Conversation


|
🦞👀 Pull request received. I will update this pull request when review starts. ClawSweeper review completeClawSweeper finished reviewing this revision. The review result is being finalized. |

|
@clawsweeper please review. |
|
🦞👀 Command router queued. I will update this comment with the next step. |
 clawsweeper
Bot
added
P2
|
Codex review: needs real behavior proof before merge. Reviewed October 4, 2026, 11:45 AM ET / 15:45 UTC (Revision 20). ClawSweeper reviewWhat this changesUpdates Windows Local AI to llama.cpp b11320 and the revised RTX Spark 48GB model recipe while preserving older installations through receipt-aware onboarding and Repair. Merge readiness⛔ Blocked before merge - 3 items remain This PR remains useful: current main still offers the older Spark recipe. No blocking code defect was found, but the previously identified Repair proof gap remains unresolved. Priority: P2 Review scores
Verification
How this fits togetherWindows Local AI uses detected GPU capabilities and installation receipts to select and manage a local inference runtime. Setup and onboarding expose installation, launch, and repair actions, and the resulting endpoint serves the user's agent. flowchart TD
A[Detected GPU capabilities] --> C[Model and runtime selection]
B[Existing installation receipt] --> C
C --> D[Onboarding actions]
D --> E[Install or repair pipeline]
E --> F[Local inference endpoint]
B --> F
F --> G[Agent responses]
Before merge
Agent review detailsSecurityNone. Review metrics
Merge-risk optionsMaintainer options:
Technical reviewBest possible solution: Offer the revised Spark recipe while keeping retained installations launchable and safely repairable, with demonstrated recovery that preserves existing model files. Do we have a high-confidence way to reproduce the issue? Not applicable as a bug reproduction: this updates an offered hardware recipe. Real hardware output establishes fresh selection and inference plus retained-install launch, but does not establish Repair completion. Is this the best way to solve the issue? Yes, separating fresh selection from receipt-aware eligibility is a focused way to preserve existing installations without reoffering retired models; the remaining uncertainty is runtime proof of Repair. AGENTS.md: found and applied where relevant. Codex review notes: model internal, reasoning medium; reviewed against 7127c16d537c. LabelsLabel changes: No label changes. Label justifications:
EvidenceWhat I checked:
Likely related people:
Rank-up movesOptional improvements that raise the rating; they are not merge blockers.
Rating scale
Overall follows the weaker of proof and patch quality. Workflow
HistoryReview history (19 earlier review cycles; latest 8 shown)
|

fcaf024 to
0525726
Compare
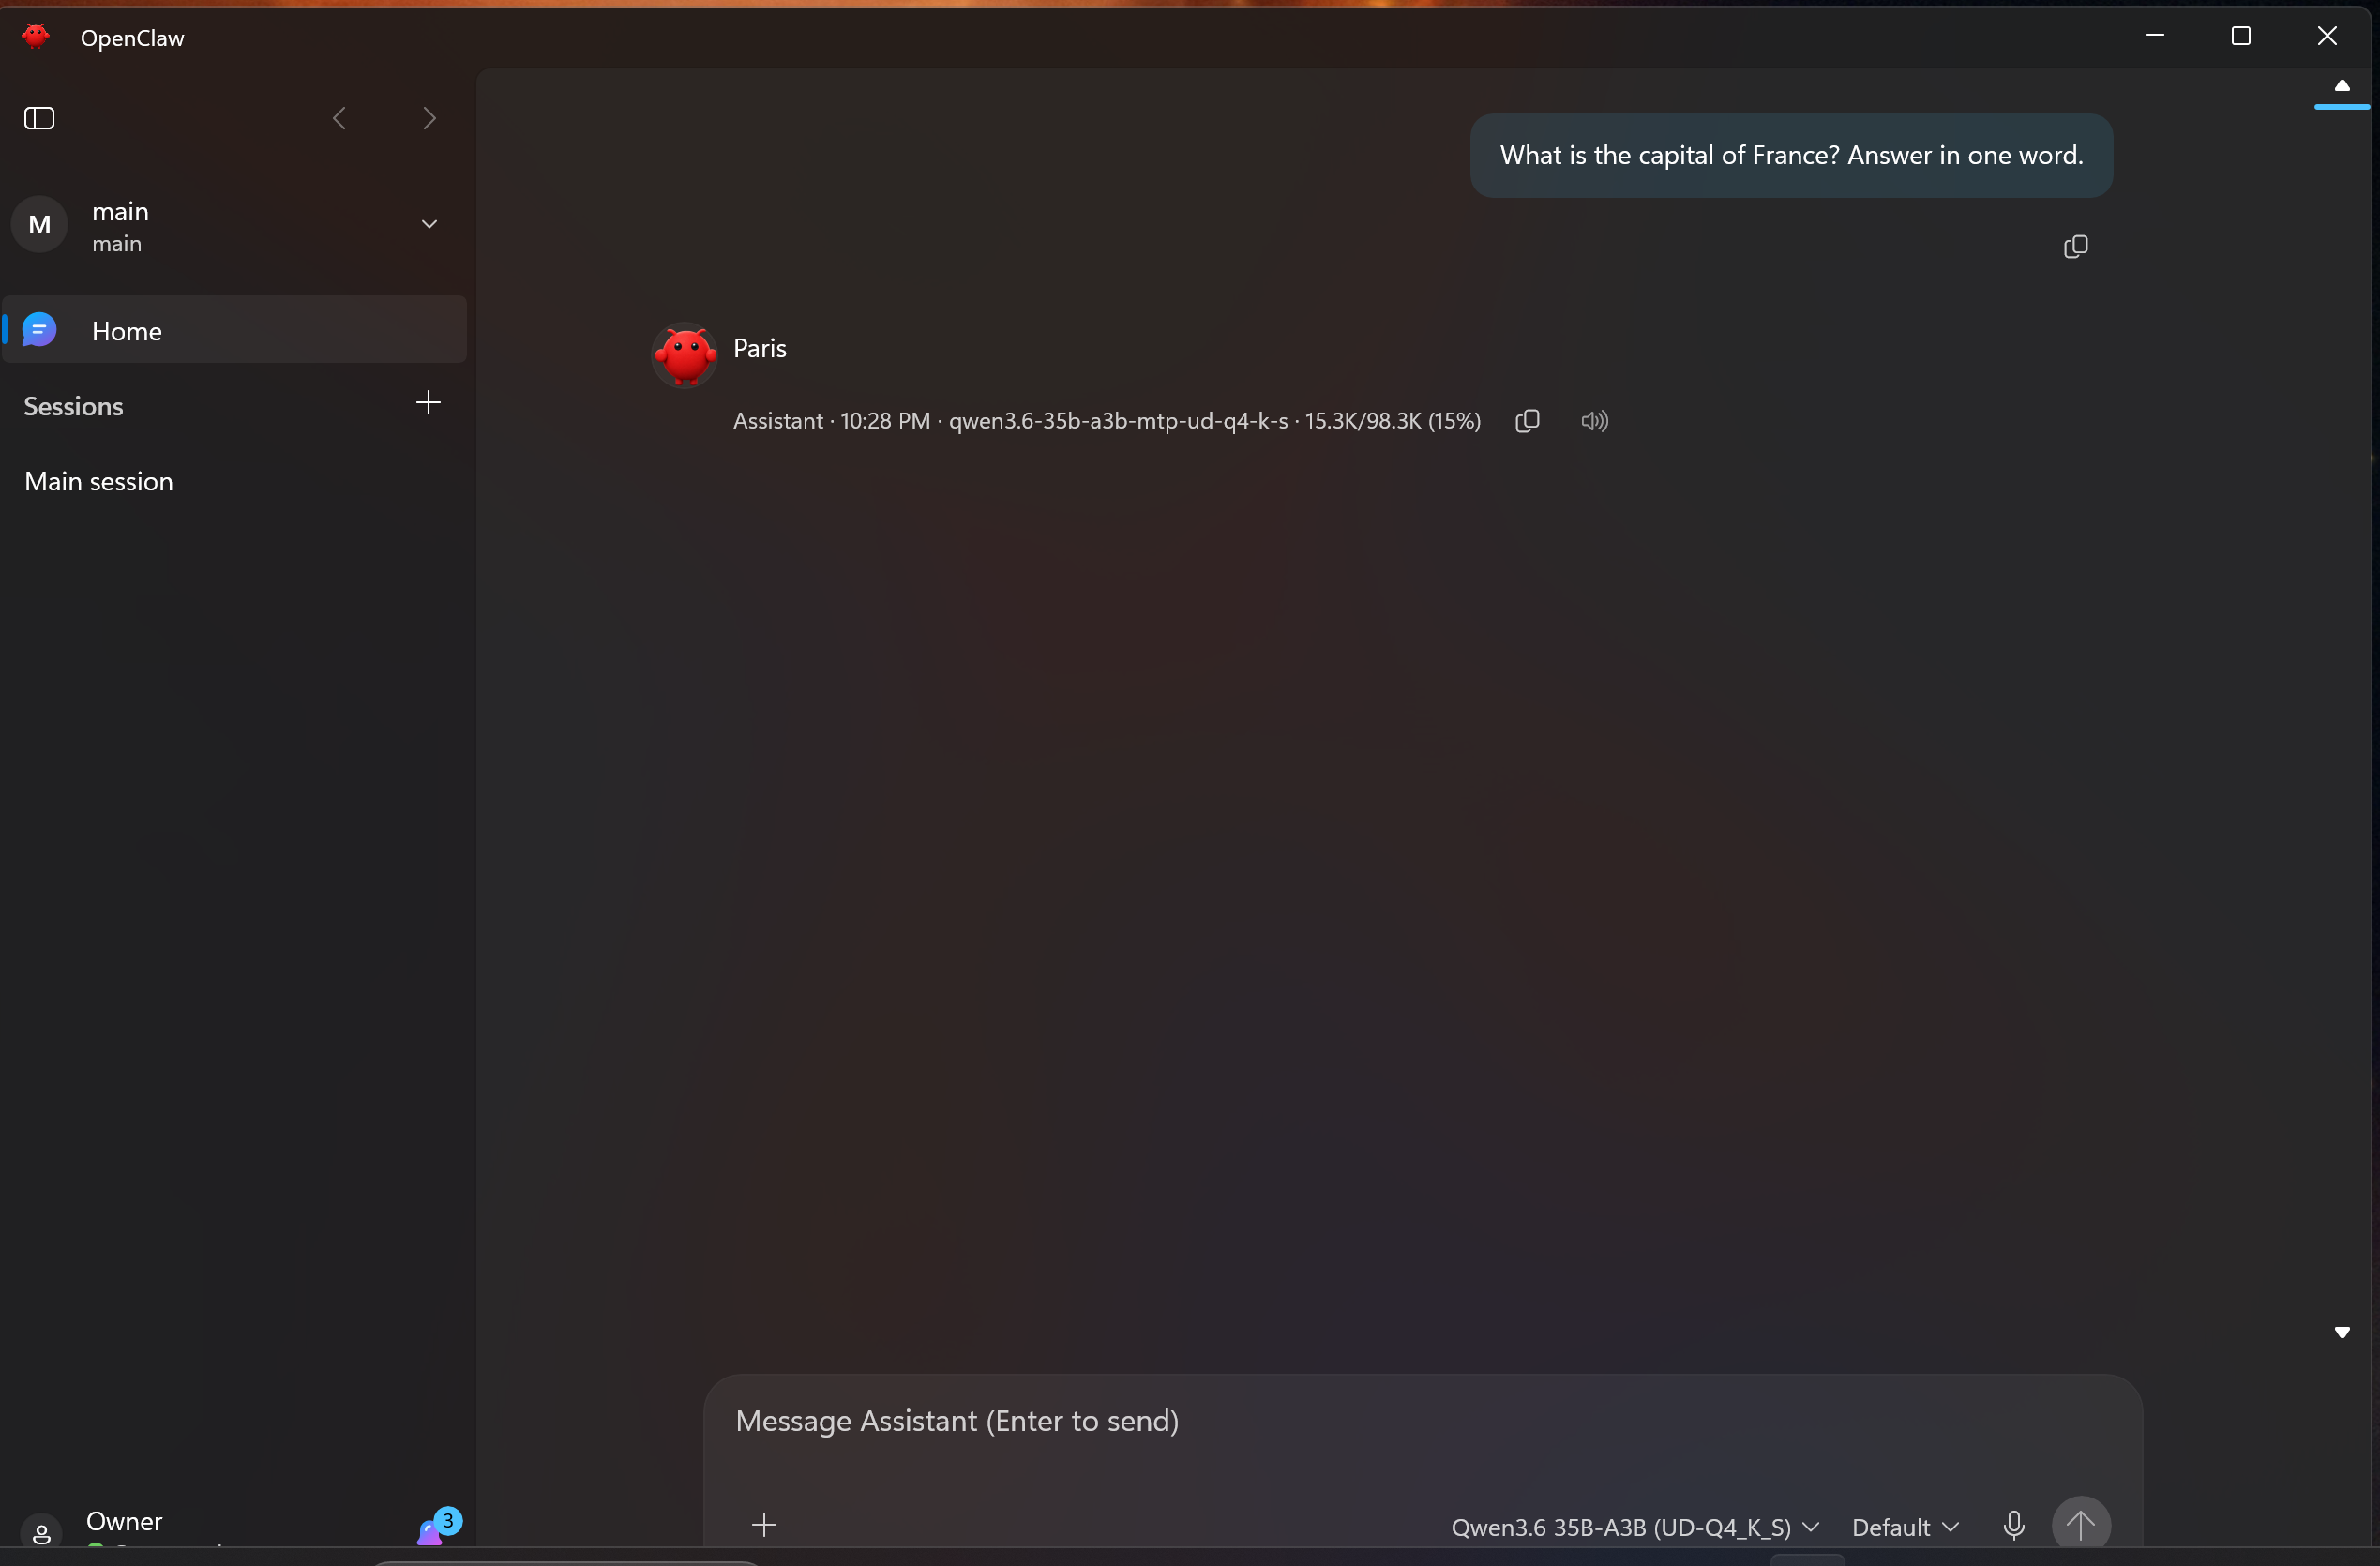
Hardware validationBoth runs are a clean flow on a wiped machine — uninstall, purge RTX Spark N1X, 48GB SKU (arm64) — the recipe this series changes
The response line carries the proof: Live worker argv on that host: RTX 5090 (x64) — generic dGPU path, unchanged by this series
|
 clawsweeper
Bot
added
the
proof: 📸 screenshot
0525726 to
32e839b
Compare
|
Thanks — the published-install finding is correct and I had the premise wrong. Addressed at P1 / P1 — retain The commit that removed them has been dropped from the series. Both the P2 — repository root discovery. Fixed, and the finding is right about the mechanism: in a linked worktree On the VCLibs minimum. The floor comes from openclaw-windows-packaging#145 rather than from this series, but it is checkable: scanning the import strings of the pinned b11320 binaries on real hardware, On the earlier "no installed base" rationale. That was my error. I reasoned from "unlaunched product" without checking the releases list, and the published alpha contradicts it. The compatibility surface is real and the entries stay. |
|
Dropped the VCLibs commit from the series, which removes one of the merge-risk items rather than arguing it. It should not have been here. It came from openclaw-windows-packaging#145, which I applied on the understanding that it fixed the The commit also carried a rationale I never reproduced ("llama-server.exe then fails to start inside the packaged session" on a high floor). That was inherited from the upstream PR and stated as established; it was not. Lowering the minimum is a real compatibility widening, but it belongs to the packaging repo and wants its own on-device proof: it converts a visible install-time dependency failure into an invisible load-time one, which is the failure shape this series exists to remove. The manifest is back at Series is now six commits: three recipe changes and three install-reliability fixes, all demonstrated on hardware. |
32e839b to
9e643be
Compare
clawsweeper
Bot
added
status: 👀 ready for maintainer look
9e643be to
f0862eb
Compare
clawsweeper
Bot
added
status: 📣 needs proof
f0862eb to
a0a2be7
Compare
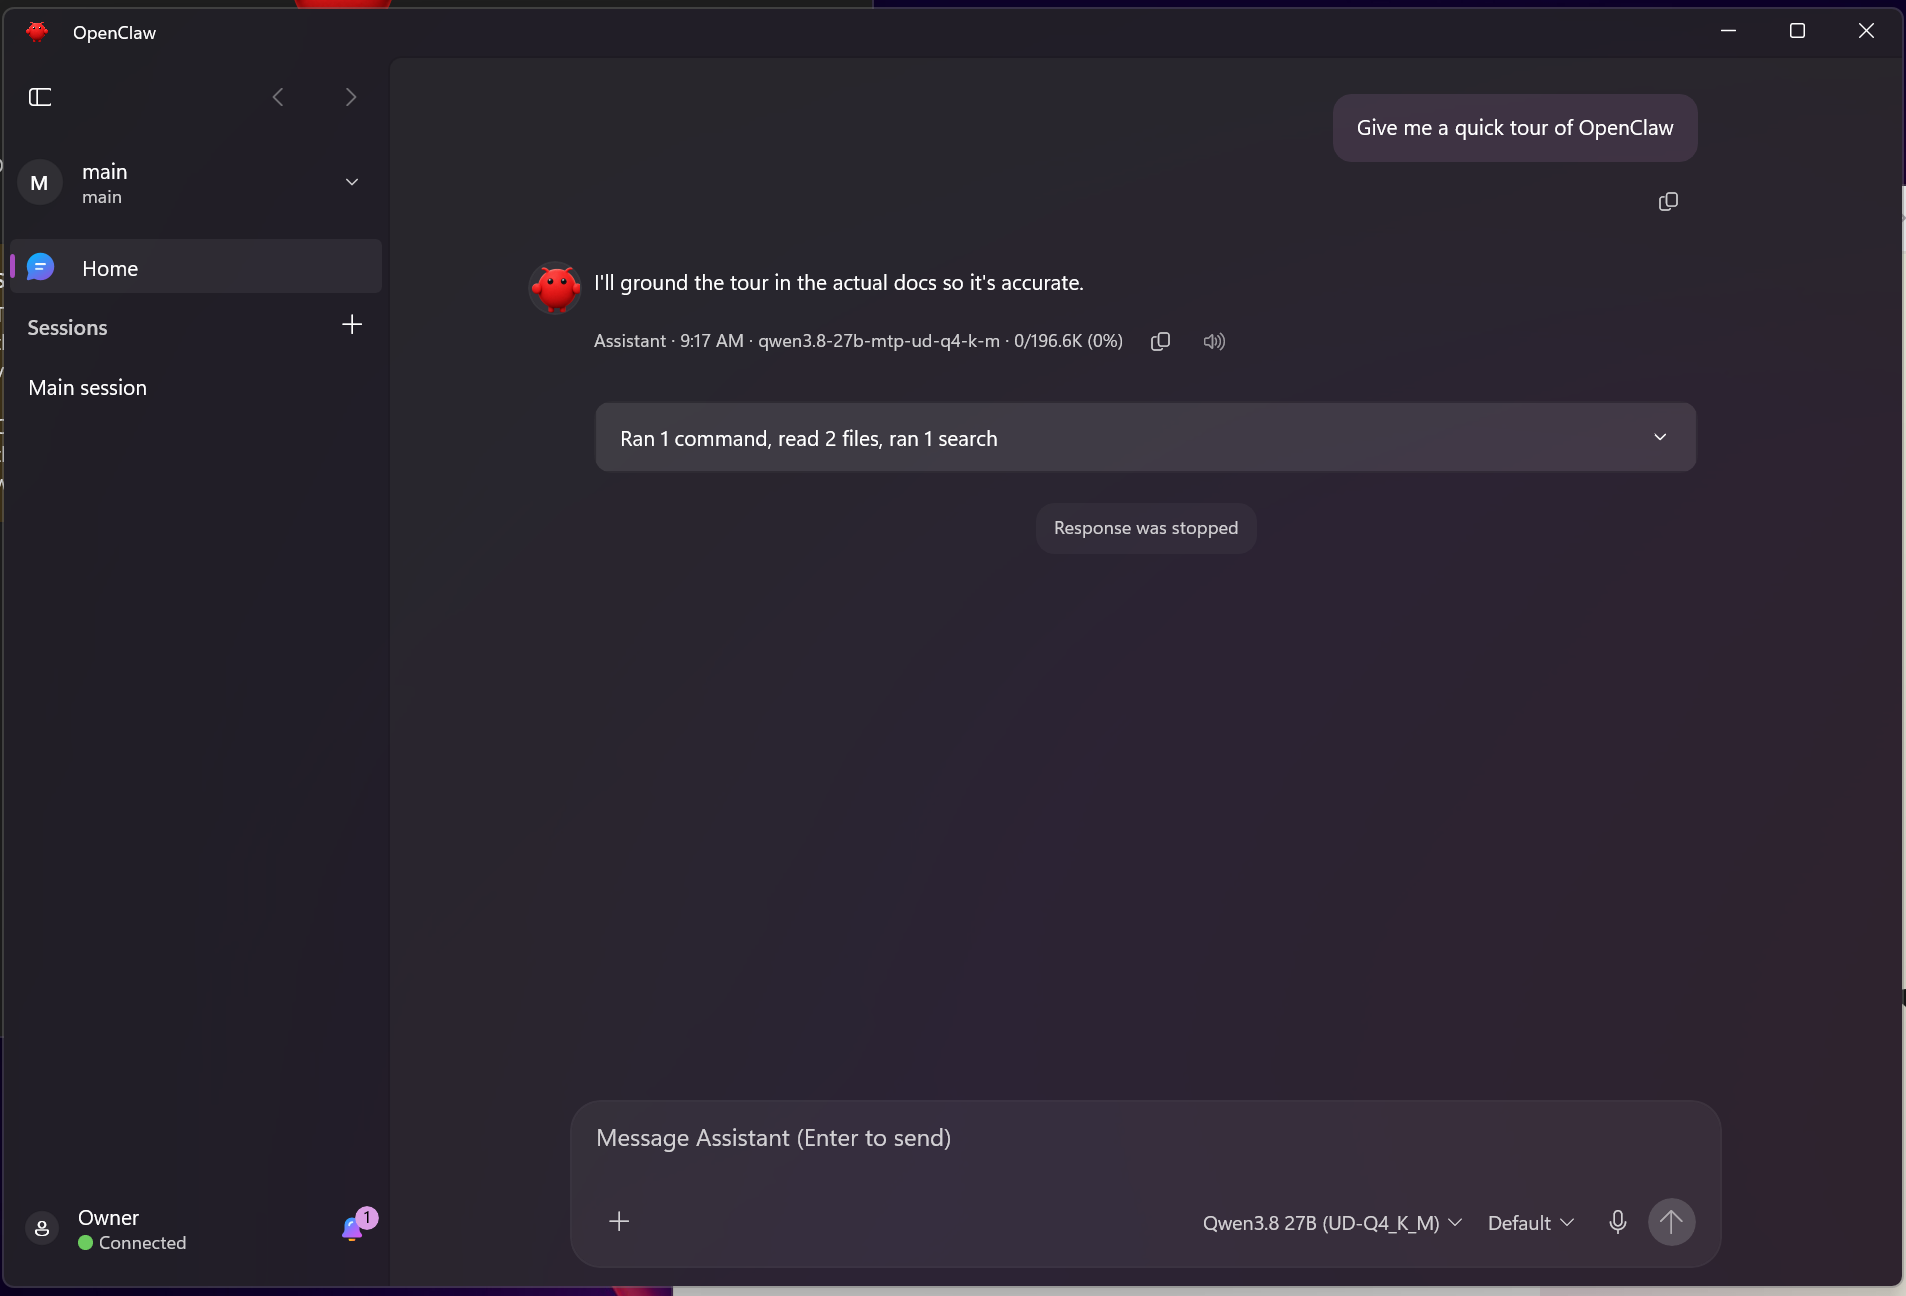
Published-install compatibility: launch path verified on hardware
This closes the P1 raised in the last review. Rather than synthesise a manifest, "runtimeId": "b11026-cuda13-x64",
"engineVersion": "b11026",
"modelCatalogId": "qwen3.8-27b-mtp-ud-q4-k-m",
"contextLength": 196608with the model on disk at I then built this branch as
The strongest single piece of evidence is that the branch build served real
The non-Spark path is unchanged on the same box: "Your NVIDIA GeForce RTX 5090 New regression test
What I did not verifyOnboarding's observation path for a retained install — this is the defect noted The in-product runtime transition b11026 → b11320 was not observed Test counts at
|
| Suite | Failed | Passed | Skipped | Total |
|---|---|---|---|---|
OpenClaw.Shared.Tests |
0 | 4231 | 33 | 4264 |
OpenClaw.Connection.Tests |
3 | 1496 | 1 | 1500 |
OpenClaw.SetupEngine.Tests |
3 | 2206 | 1 | 2210 |
OpenClaw.Tray.Tests |
0 | 3862 | 0 | 3862 |
.\build.ps1 -Msix Dev exited 0. The 6 failures are pre-existing and live in
files this series never touches, confirmed with git diff --name-only.
The PR description has been rewritten to the repository template with proof pool
declarations and the full validation detail.
ba9b5e0 to
00d3e73
Compare
00d3e73 to
b57027f
Compare
Scope reduced to the recipe set, and rebased onto current
|
| Commit | |
|---|---|
13294415 |
build(local-ai): bump the managed runtime pin to b11320 |
ff90ee78 |
feat(local-ai): move the RTX Spark 48GB recipe to UD-Q4_K_S |
b57027f6 |
feat(local-ai): align the offered Qwen3.6-35B recipe with MTP n=2 |
The three Local AI reliability fixes that were previously here have been
dropped. Rebasing onto current main showed that area has been reworked
upstream, and keeping them would have put this PR in the middle of that work:
- Inspection no longer launches
llama-server --versionat all, so the probe
budget those commits added is dead code on top ofmain. ServerImplementationLibraryNameand the per-file digest manifests landed
upstream, which supersedes the missing-implementation-library check.
Rebase conflicts are resolved. One consequence worth calling out: the new
inspection fails closed when a variant has no file manifest, so moving the pin to
b11320 required generating a manifest for it — 27 x64 and 14 arm64 entries,
produced from the release archives themselves using the same file selection the
repository already applies to b11026. The retired b11026 variants now carry their
own manifest too, so an installation recorded against the previous pin still
inspects cleanly instead of being reported as unverifiable.
The CUDA runtime archives are byte-identical to those already pinned at b11026
(same sizes, same digests), which is an independent check that the generation
procedure matches the existing entries.
On the two findings from the last review
"Validate installed runtimes against their recorded pin" — resolved, though
not by me. ValidateVersionOutput no longer exists on main; inspection now
takes the LlamaRuntimeVariant as a parameter, which is exactly the receipt-aware
shape the finding asked for. What remained was that retired variants carried no
file manifest, so they would fail the new inspection — that is fixed here.
"Keep the installed Spark model eligible for onboarding" — not changed, and I
would like a maintainer's view before touching it. The suggested fix is for
LocalInferenceSelector to fall back to FindInstalled when an explicitly
requested model id is no longer offered. I implemented that, and it breaks
Evaluate_Removed16GiBModelIdIsUnknown, which asserts the opposite: that a
retired id passed as an explicit request reports UnknownModel. That test
predates this PR and encodes the same treatment for the already-retired
qwen3.5-9b-mtp-q4-k-m, which sits in the installed-only catalog exactly as
...-iq4-xs now does.
So the behaviour the finding describes is the repository's existing, deliberate
treatment of retired models rather than something this PR introduces. Changing it
would be a product decision affecting every retired model, which seems out of
scope here. I have reverted my attempt and left the invariant intact.
|
@clawsweeper re-review |
|
🦞👀 Re-review progress:
|
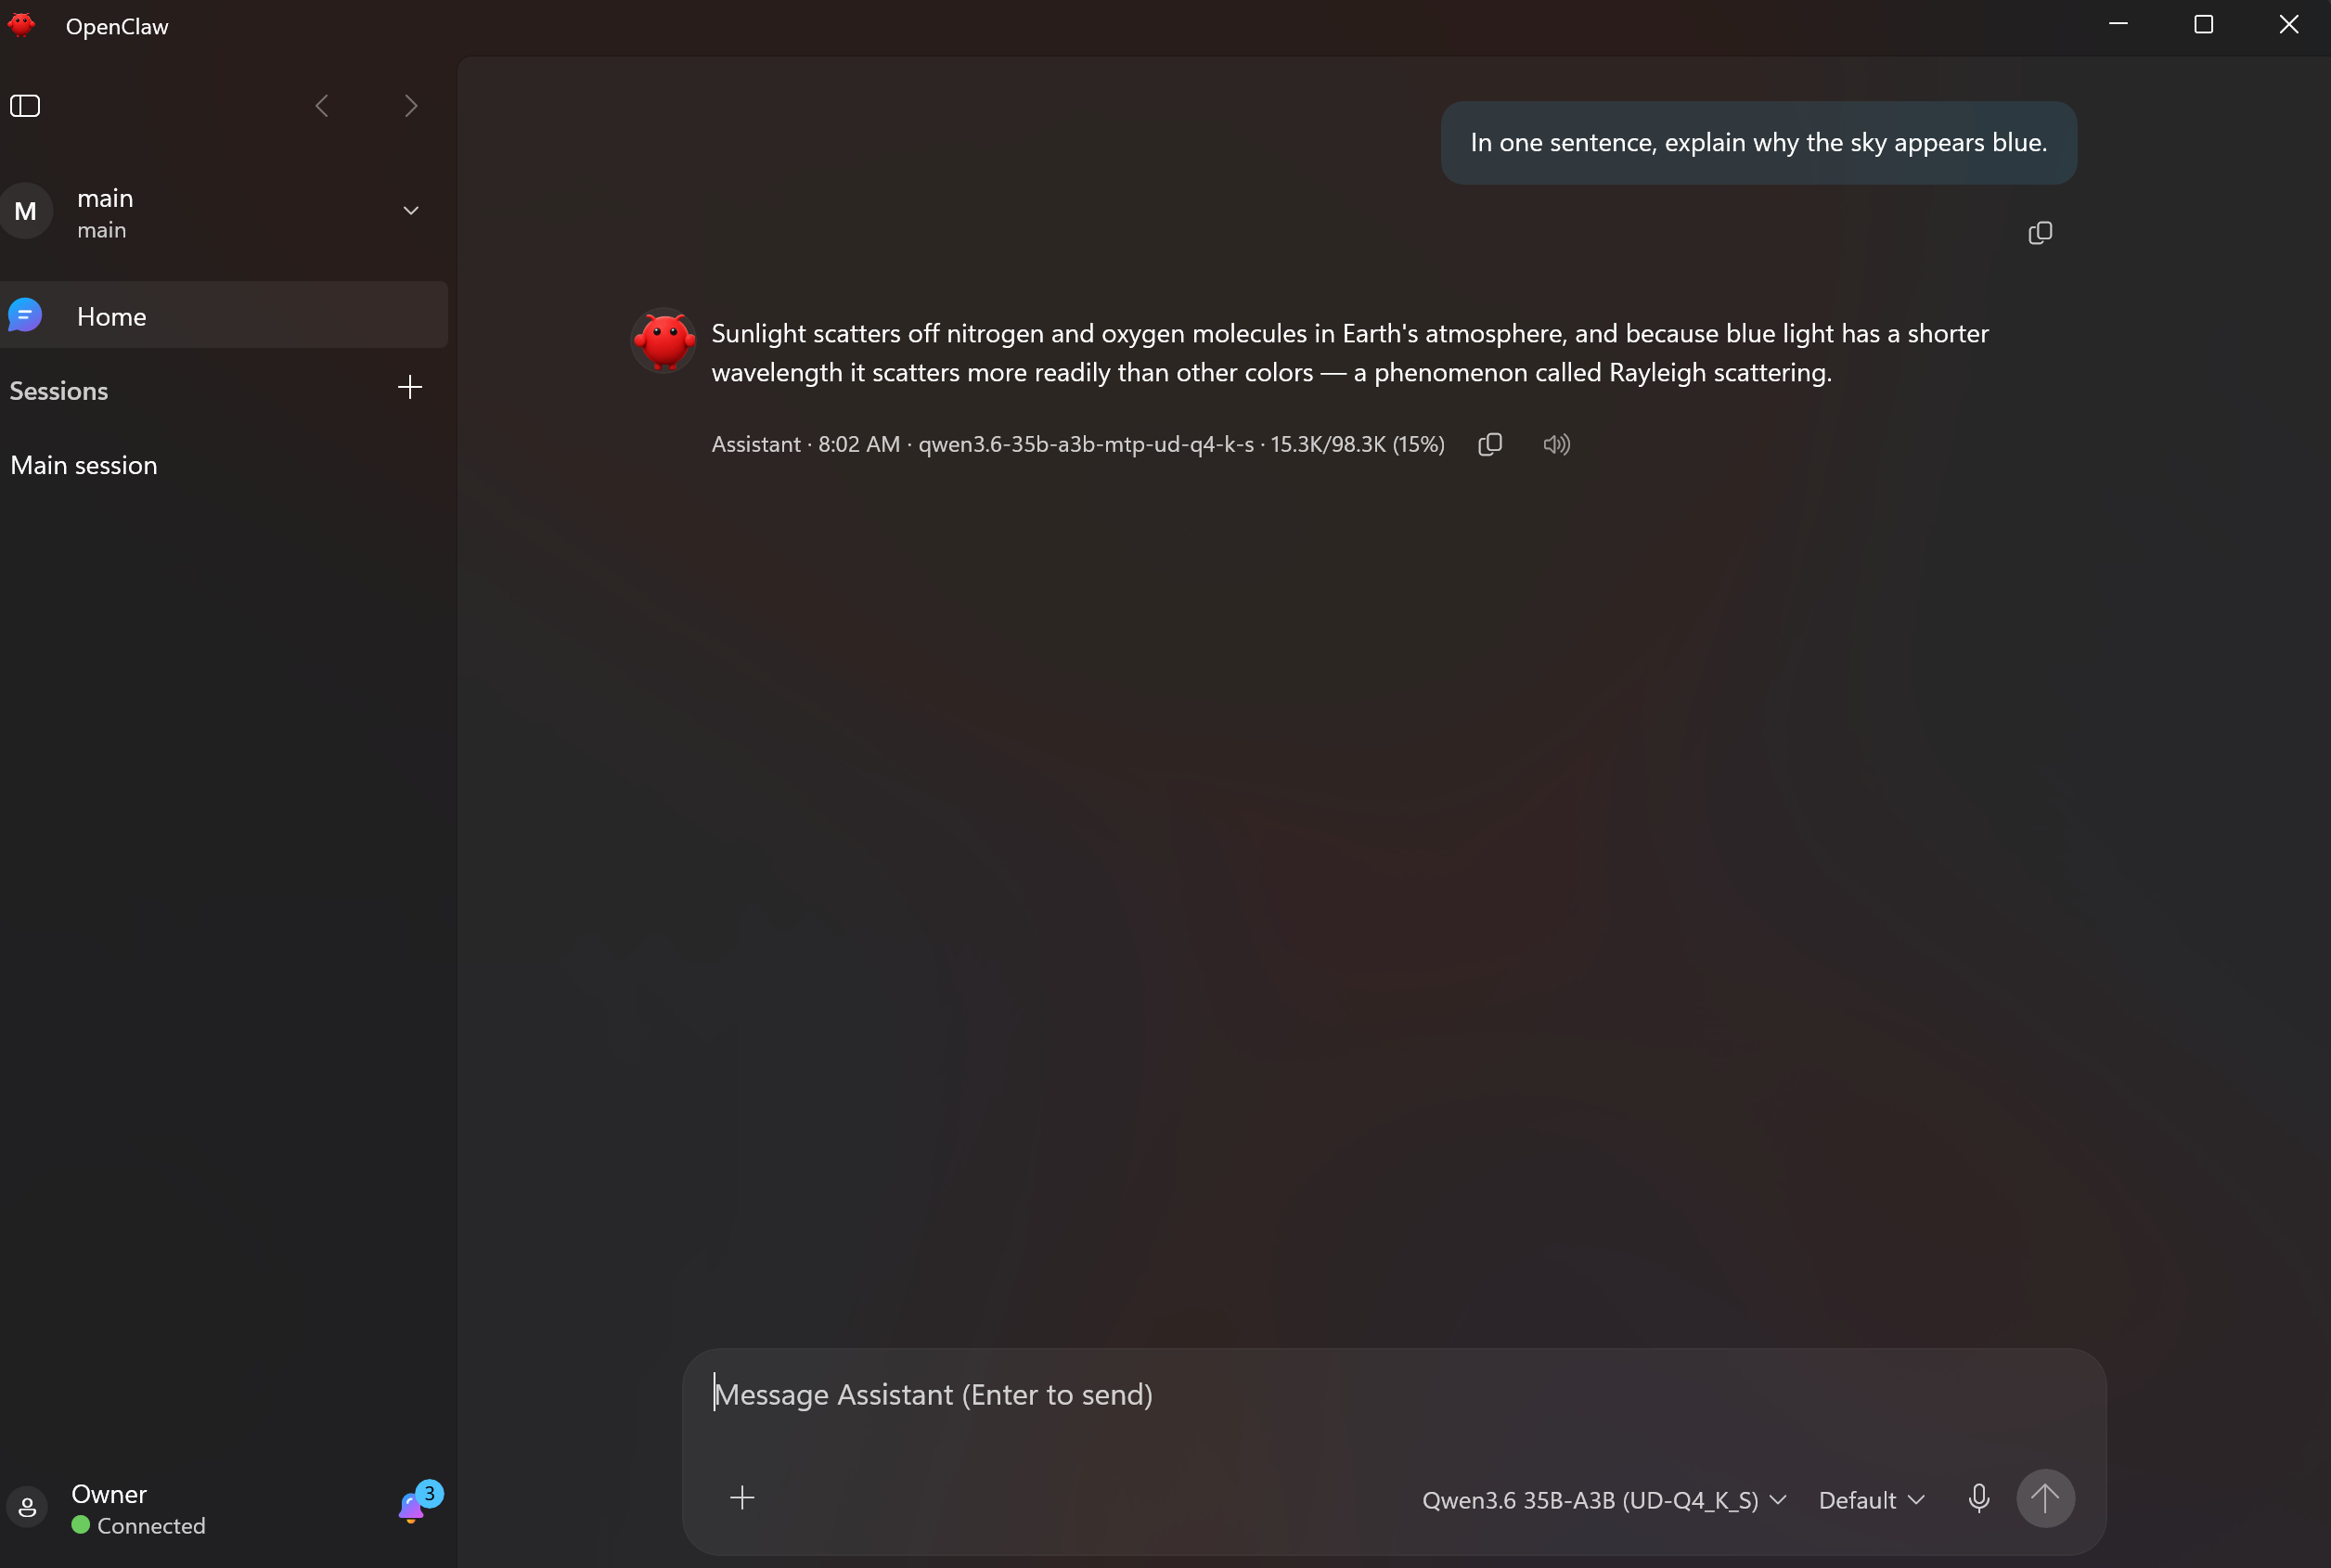
Current-head proof: 48GB Spark recipe on b11320, end to endRe-validated on RTX Spark 48GB hardware (arm64) against the rebased head The managed runtime directory was purged before installing, which forces Receipt written by the install: Setup routed the SKU to the new recipe before installing anything:
and sized it as Prompt and responsePrompt: "In one sentence, explain why the sky appears blue."
The assistant line names the model that actually served it — CIAll checks green on this head, including Core and CLI tests, Tray/setup/ |
 RomneyDa
added
the
status: 🚢 actively landing
RomneyDa
changed the title

|
Addressed the actionable ClawSweeper finding in
@clawsweeper re-review |
|
🦞👀 Re-review progress:
|
|
Addressed the Repair-handoff finding in
@clawsweeper re-review |
|
🦞👀 Re-review progress:
|


The RTX Spark recipe set published on 2026-09-30 raises its minimum
llama.cpp build: the Qwen3.6-35B-A3B recipes require b11236, the
Qwen3.8-27B DFlash recipes require b11229, and Qwen3.8 Flash-Next
requires b11256. A single managed runtime is pinned for every recipe,
so the pin moves to b11320, the newest build carrying all four Windows
CUDA 13.4 artifacts, which clears every one of those minimums.

Artifact sizes and digests are taken from the release and verified by
downloading each llama-server archive and recomputing SHA-256. The
CUDA runtime archives are byte-identical to the ones already pinned at
b11026, so their digests are unchanged.

b11026 moves into the retired set alongside b10655. It is a shipped
runtime once this release goes out, so an installation recorded
against it has to keep resolving its own receipt and stay launchable
until setup upgrades it.
…tion

The 2026-09-30 recipe set replaces the 48GB-SKU Qwen3.6-35B-A3B
quantization: UD-IQ4_XS becomes UD-Q4_K_S. Both files already exist at
the Hugging Face revision this catalog pins, so only the artifact
changes; the revision, run recipe, and 98,304-token context tier are
untouched.

The previous quantization is retired rather than rewritten in place.
It ships as the 48GB default, so an existing receipt has to keep
resolving its own pinned artifact and profile until setup upgrades it.
Retired entries normally expose only the pre-profile native/F16
profile, which this model was never installed under, so the retired
entry keeps the 48GB SKU's fixed tier instead. A regression covers
that and fails without it.
The 2026-09-30 recipe set runs every Qwen3.6-35B-A3B configuration with
MTP n=2, including the 28GB and 30GB tiers the 64GB and 128GB SKUs
offer. The already-offered UD-Q4_K_M entry inherited the catalog-wide
default of 3 instead, so it launched with a draft depth no published
recipe uses.

Its pinned artifact already matches the new recipes byte for byte --
same revision, same file, same digest -- so only the draft depth
changes, and the model stays reachable exactly as before through the
existing explicit-alternative path.

The sampling block published alongside these recipes is not adopted:
every recipe in the set carries an identical string, including
"speculative draft backend sampling: ON" on MTP-only entries that have
no draft model, so it reads as shared boilerplate rather than per-model
tuning. The 35B entries keep the temperature they ship with today.
f828948 to
5f2eee4
Compare
|
Rebased onto current Cleanup review narrowed the installed-receipt selector and transient recovery marker from public to internal visibility; no behavior or serialized contract changed. Focused retained-receipt tests remain green. The prior Setup/connect E2E cancellation was isolated to the stale pre-rebase run; current @clawsweeper re-review |
|
🦞👀 Re-review progress:
|
RomneyDa
removed
the
status: 🚢 actively landing
|
@clawsweeper re-review |
|
🦞👀 Re-review progress:
|
|
Retained-receipt proof on current head ( Baseline was a main-based build (
The worker process kept the recorded recipe, unchanged by the newer pin: The b11320 arm64 runtime is covered separately by the Spark 48GB install that served |
clawsweeper
Bot
removed
the
proof: 📸 screenshot
|
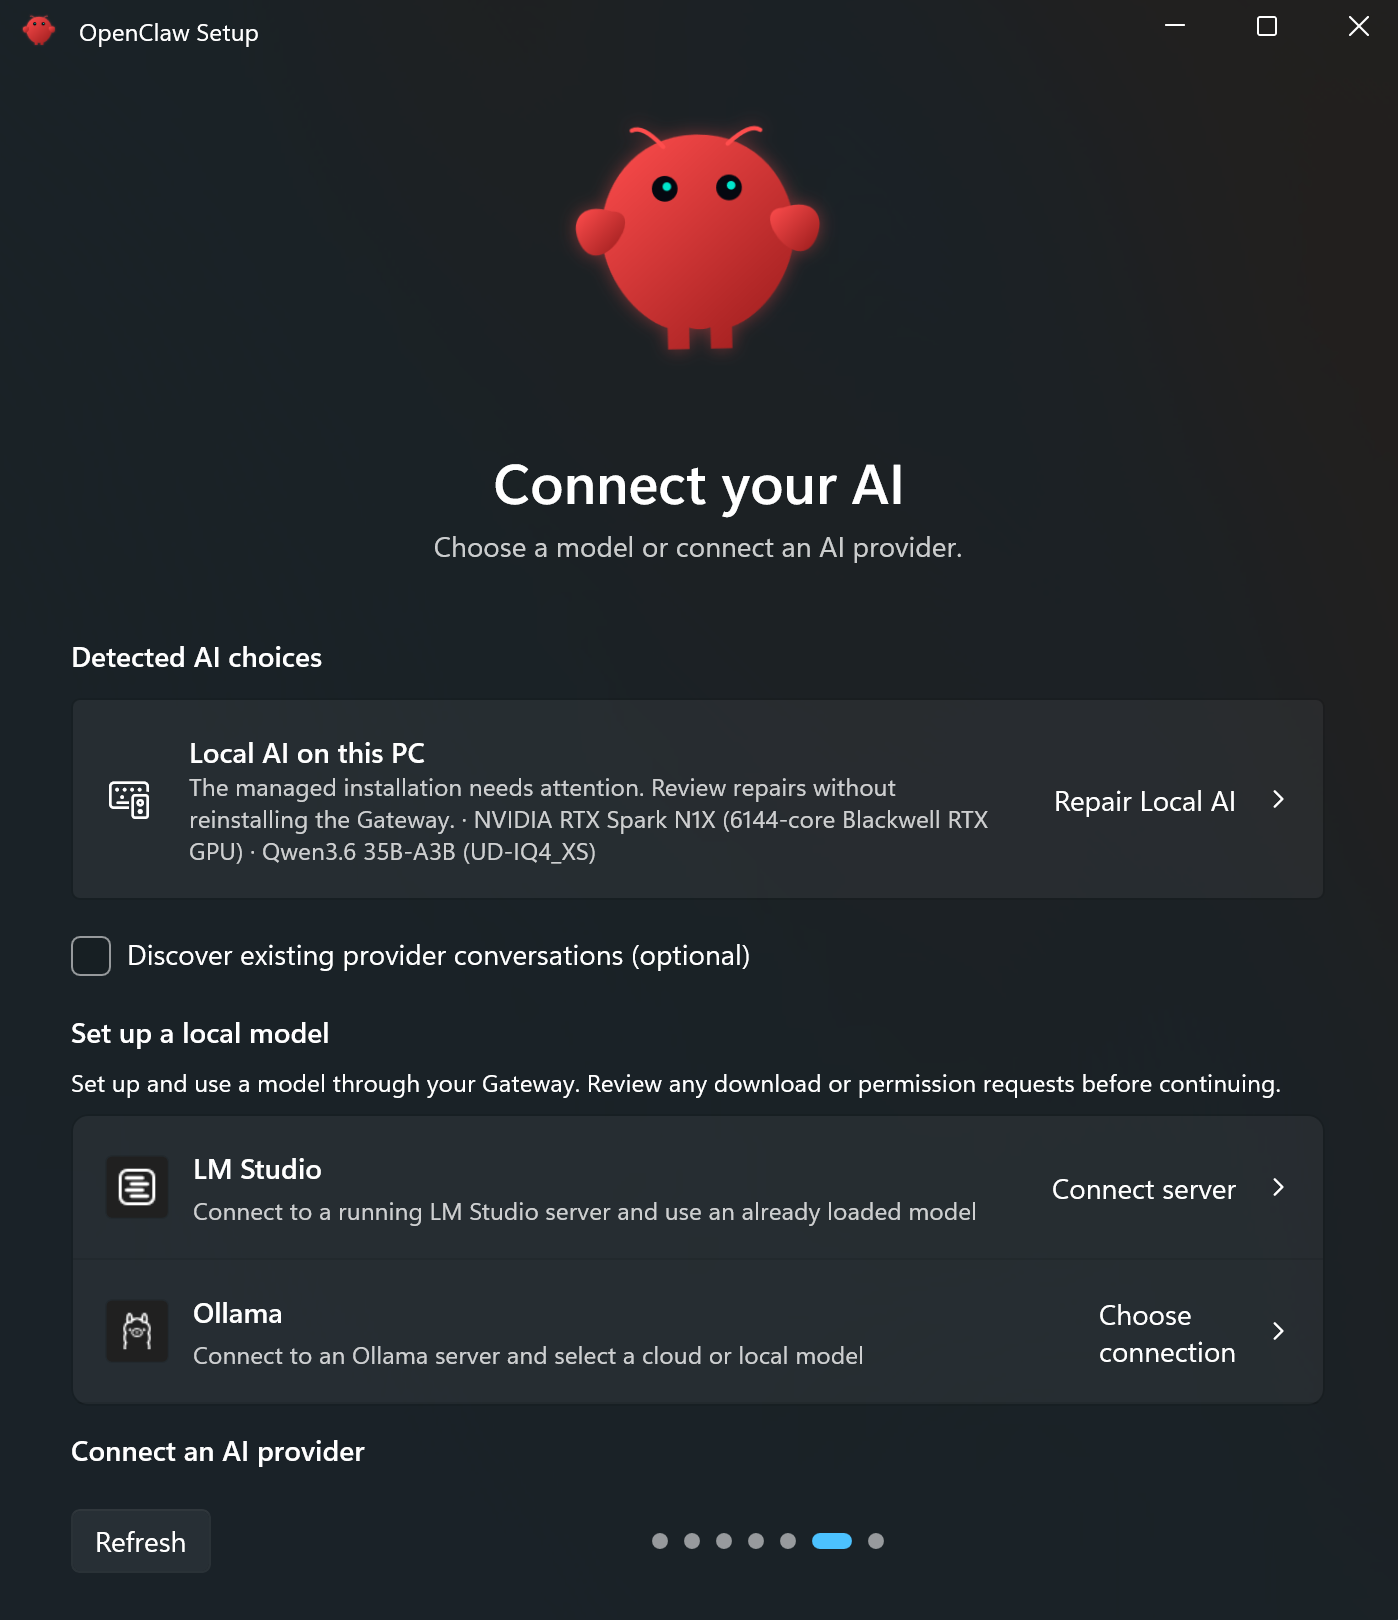
Retained IQ4_XS onboarding on current head ( This run completed a real WSL Gateway setup on the host (app-owned
Exact UI automation values read from the live window: The retired model is resolved and named by the current-head onboarding surface. Under the previous fresh-selection path that ID returns The receipt was untouched throughout: |
|
Recipe selection measured directly on RTX Spark 48GB hardware at current head ( This runs the shipped Points worth noting against this PR's intent:
Headroom is 28.97 GB required against 48.72 GB visible. |
|
@clawsweeper re-review |
|
🦞👀 Re-review progress:
|
|
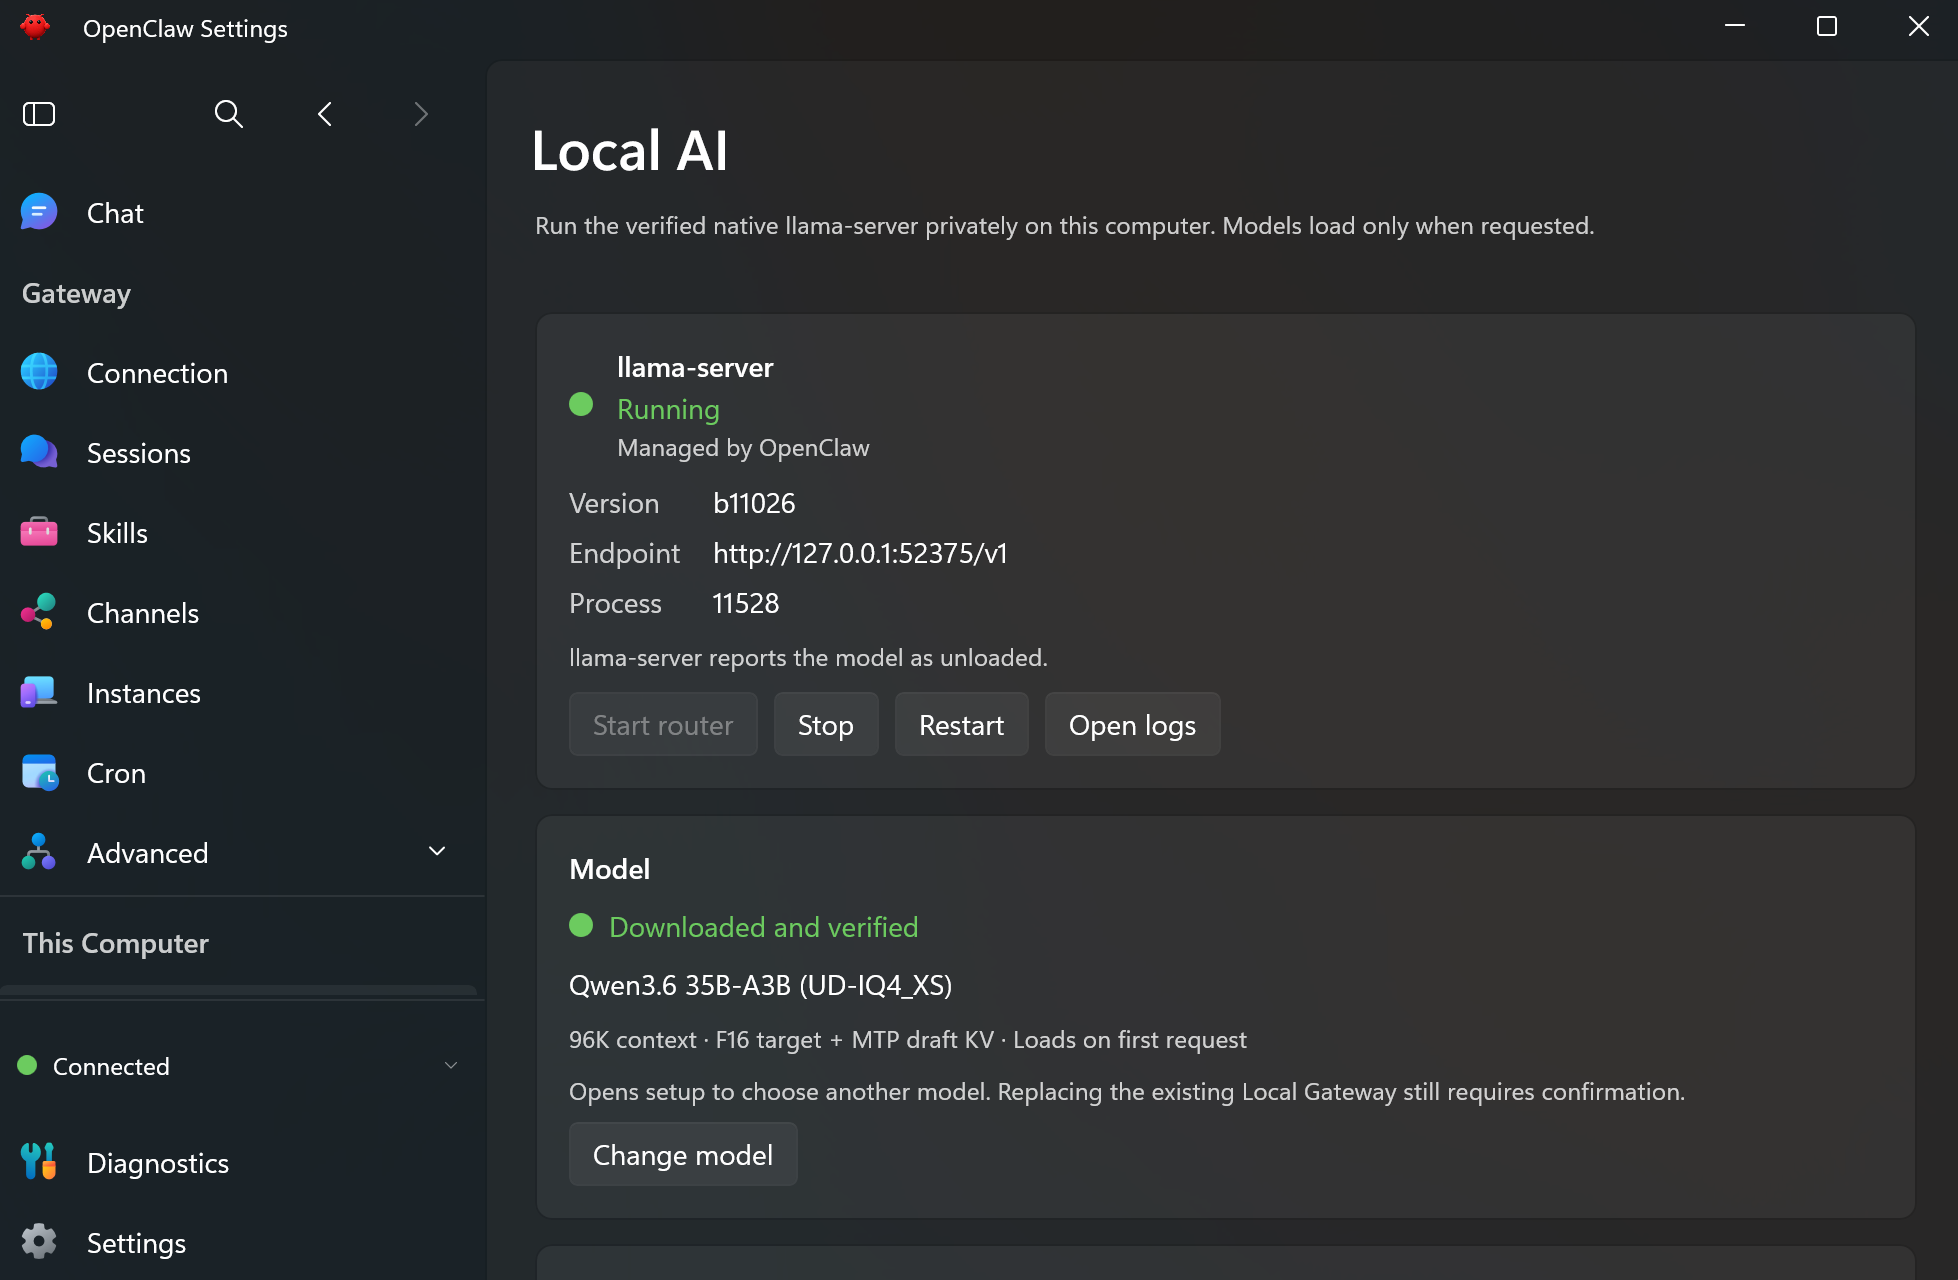
Retained IQ4_XS install observed through the tray's Local AI surface on current head ( This is after the real WSL Gateway setup completed on the host, so the Hub reaches
Automation values read from the live page:
Startup for this session recorded the same, with the session resolving to the retained model: Receipt was unchanged across the run: model |
This branch has not been deployed
2 participants


Related: #1571
What Problem This Solves
NVIDIA published a revised RTX Spark recipe set on 2026-09-30. The 48GB SKU recipe changed quantization and speculative-decoding depth, and the new set requires a newer llama.cpp build than the one currently pinned.
User Impact
RTX Spark 48GB users are offered the recipe NVIDIA validated for that SKU: Qwen3.6-35B-A3B
UD-Q4_K_Swith MTP n=2 on llama.cpp b11320.No user action is required. Non-Spark machines are unaffected. Existing installations keep their recorded runtime and model without re-downloading either artifact, and retained
UD-IQ4_XSreceipts continue to offer Start and use, Use, or Repair during onboarding.Implementation
UD-IQ4_XStoUD-Q4_K_S, retaining the previous model as a retired entry for existing receipts.The previously shipped b11026 runtime remains in the retired catalog with its own file manifest so existing receipts continue to inspect and launch correctly.
Evidence
Artifact sizes and digests were verified by downloading each archive and recomputing SHA-256. The CUDA runtime archives are byte-identical to those already pinned at b11026, so their entries are unchanged.
The b11320 per-file manifests were generated from the release archives: 27 x64 files and 14 arm64 files, matching the file-selection policy already used for b11026.
Change Type
Scope
winnodeRequired proof pools
windows-wsl-dgx-blackwell: the recipe is selected from NVIDIA GPU detection and ends in fixed-prompt inference.windows-clean-installer-upgrade: the runtime pin moves, so installations recorded against b11026 must remain usable.windows-11-arm64: the pin ships x64 and arm64 artifacts and manifests.Validation
5f2eee47:XamlCompiler.exe.5f2eee47: fast validation, Core and CLI, Tray/setup/integration, UI/functional/accessibility, Proof-pool contracts, Setup/connect E2E, Revocation recovery E2E, Network recovery E2E, and CI Gate.Real Behavior Proof
f7d17c12,19e0f9a3, anda3eb7425.Observation_RetainedSparkReceiptPreservesOnboardingActionsconstructs an installed IQ4_XS receipt and verifies the productionSetupLocalAiHost.ObserveAsyncpath returns Start and use, Use, and Repair for stopped, healthy, and failed runtimes.InstalledRetiredSpark48GbModel_RemainsEligibleWithoutRestoringFreshSelectionverifies the retired receipt is eligible while the same ID remainsUnknownModelfor fresh selection.Preflight_RetainedSparkReceiptUsesInstalledModelCatalogDuringRepaircarries the exact receipt-proven model through Repair preflight, while the paired no-receipt test keeps the retired ID unavailable for fresh setup.76ab8399on the Dell and completed Local AI setup to create a real b11026 receipt.Add-AppxPackage -ForceApplicationShutdown, restarted cold, and sent a chat message.f879af8a), then installed this head over it withAdd-AppxPackage -ForceApplicationShutdownand without purging Local AI state.OpenClawGateway-Dev, loopback only, Tailscale off), leaving the retained b11026 plus IQ4_XS installation in place, then opened onboarding.CudaHostHardwareProbeandLocalInferenceSelectorfromOpenClaw.Shareddirectly against the RTX Spark 48GB adapter at this head, so SKU routing is observed rather than inferred from catalog tests.qwen3.6-35b-a3b-mtp-ud-q4-k-s, displayed asQwen3.6 35B-A3B (UD-Q4_K_S).2026.9.5.11):state.jsonSHA-256 unchanged, model file unchanged at 18,209,036,576 bytes with mtime2026-10-02T17:32:52,installedAtUtcunchanged, andb11026still the only runtime on disk. The app resolved that retained receipt and launched the router from it:/v1/modelsreportedqwen3.6-35b-a3b-mtp-ud-iq4-xs, and a fixed prompt returned a complete answer (finish_reason: stop, 135 tokens in 2s). The running worker kept the recorded recipe,--spec-type draft-mtp --spec-draft-n-max 2 --ctx-size 98304onengines\llama-server\b11026\win-arm64\llama-server.exe.LocalAiDescriptionread... NVIDIA RTX Spark N1X (6144-core Blackwell RTX GPU) - Qwen3.6 35B-A3B (UD-IQ4_XS)withLocalAiActionText=Repair Local AI. Screenshot and exact automation values are in the follow-up comment. The receipt was unchanged throughout the run.IsRtxSpark=True,HasCompleteFacts=True,GpuVisibleMemoryBytes=48719466496,CudaMajorVersion=13.Select()returnedqwen3.6-35b-a3b-mtp-ud-q4-k-son profilectx-98304-f16withorigin=Defaultand the plan bound to that adapter's stable ID, andEvaluate()reportedCanInstall=Trueat 28,971,620,640 bytes required against 48,719,466,496 detected. The reading sits below the 48-to-64 geometric midpoint (55.43e9), so the unit classifies as the 48GB SKU and takes the pinned recipe rather than a largest-that-fits profile. Full output is in the follow-up comment.qwen3.6-35b-a3b-mtp-ud-q4-k-s. Catalog and digest tests cover the pin itself.Security Impact
NoNoYesNoNoCompatibility and Migration
YesNoNoReview Conversations
🤖 Generated with Claude Code