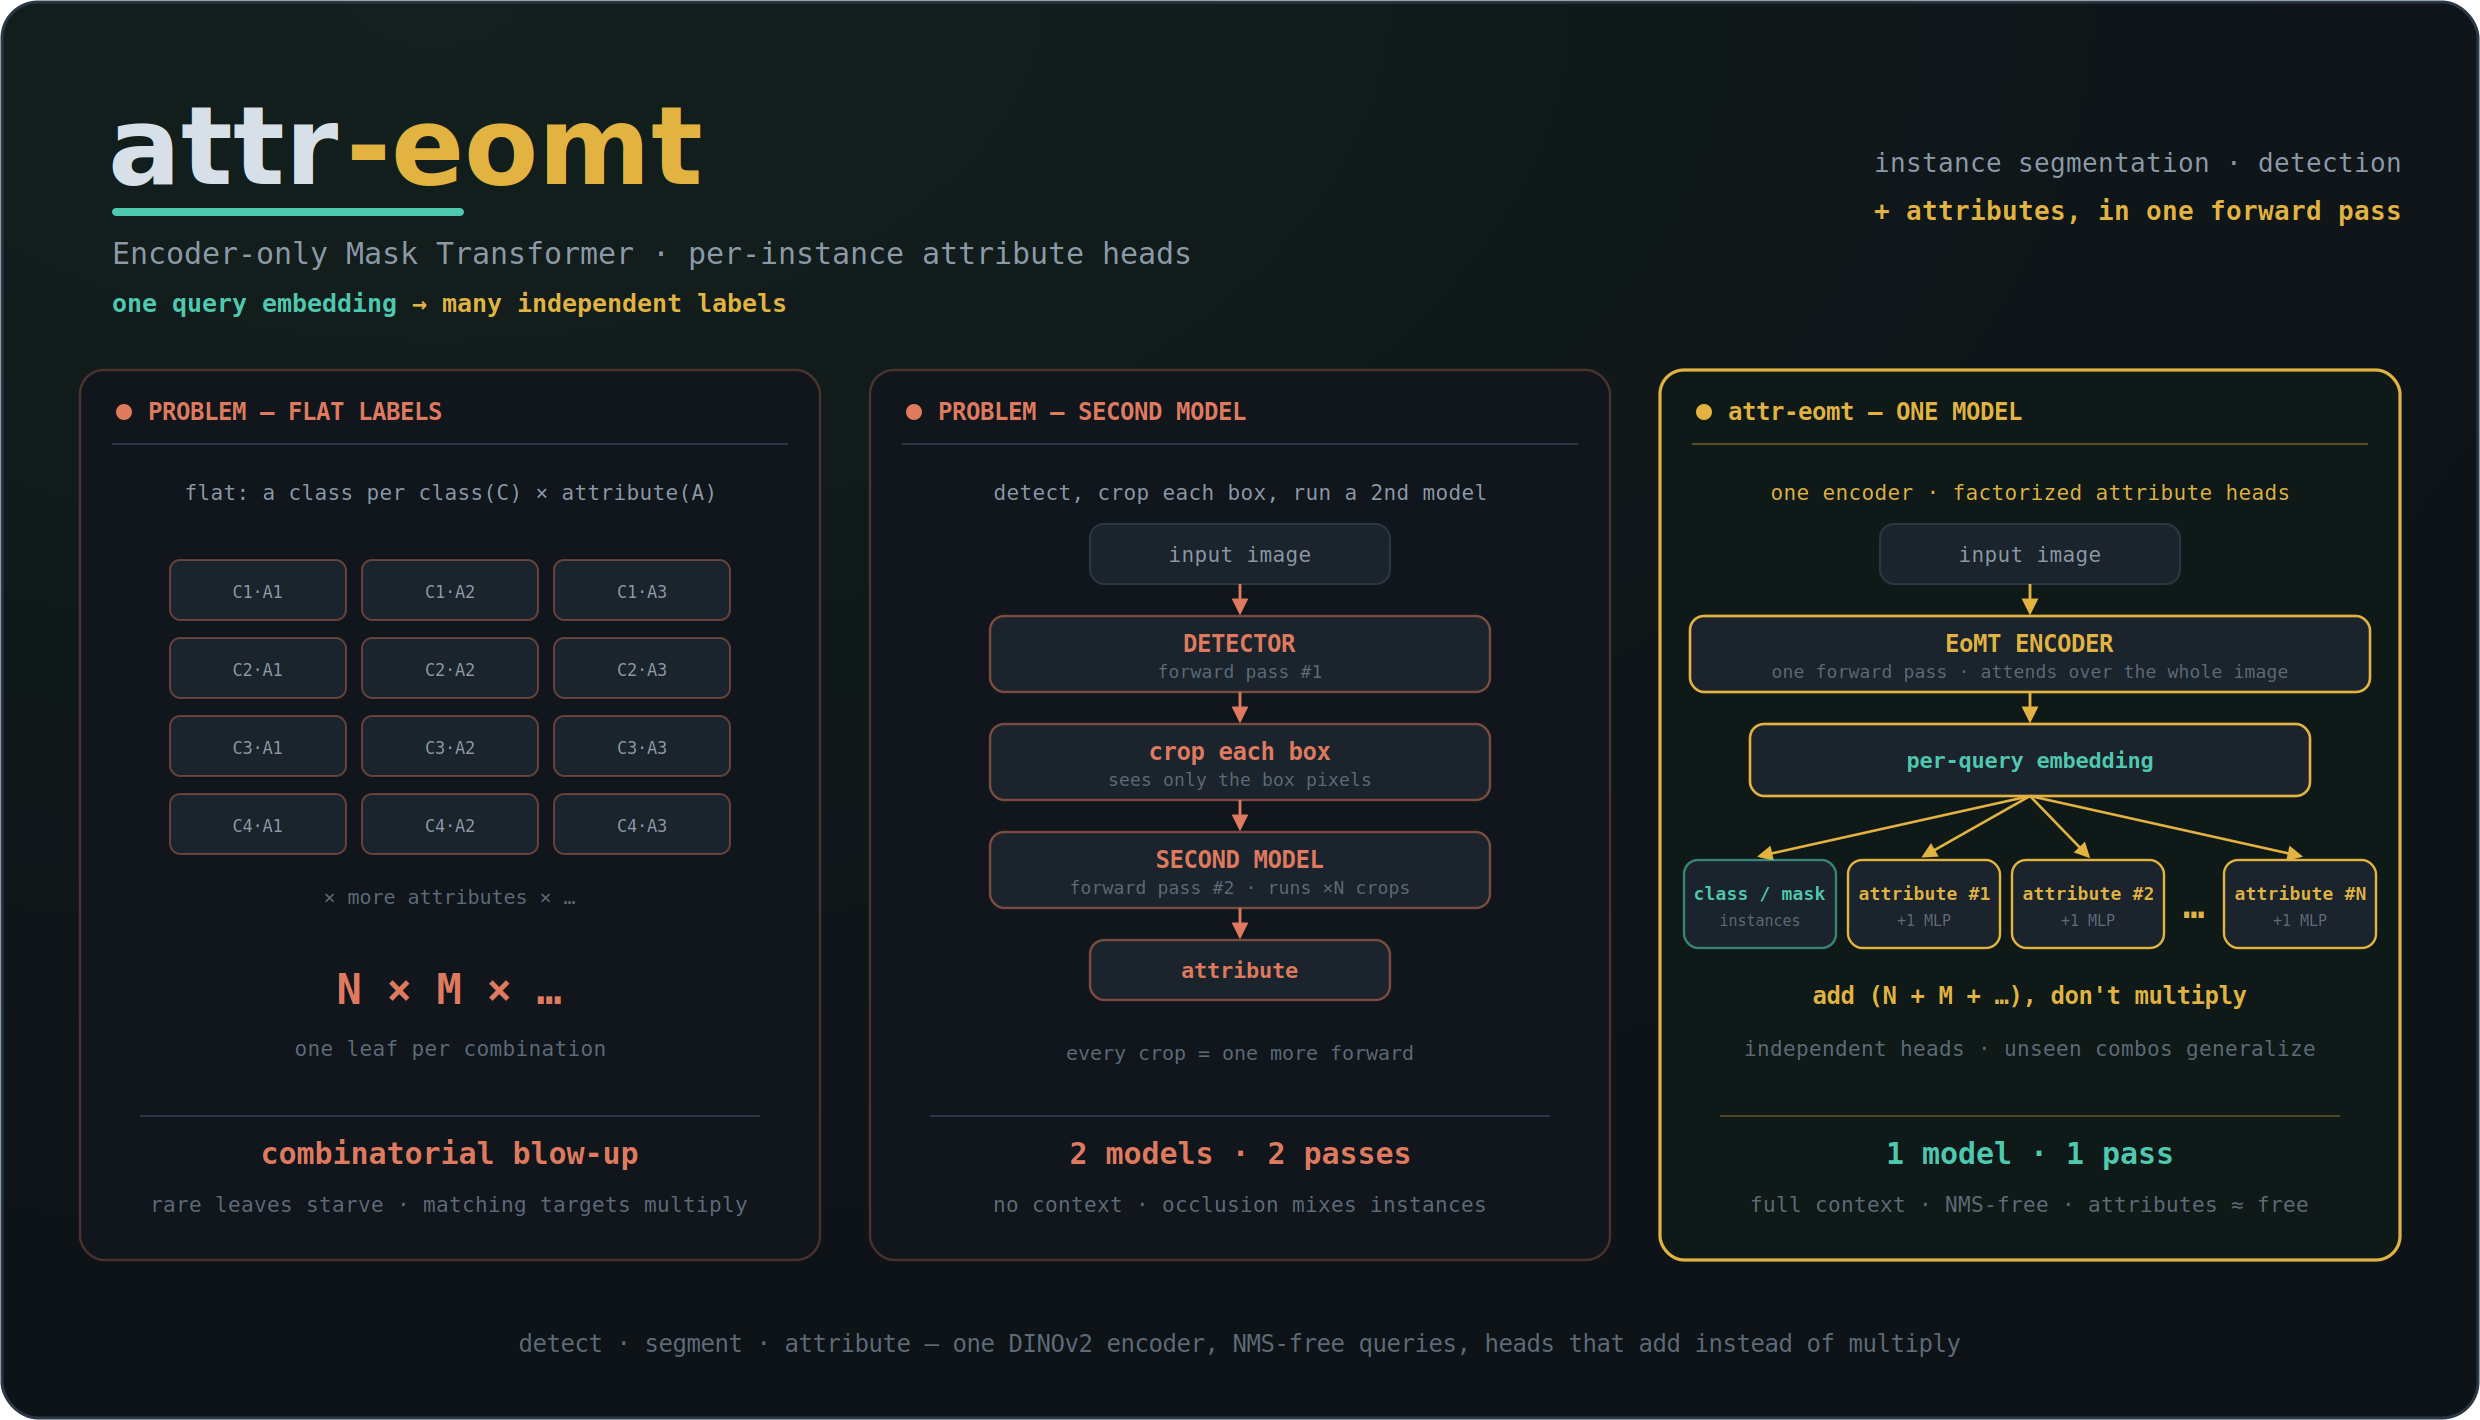


attr-eomt is a standalone EoMT (Encoder-only Mask Transformer) for instance segmentation and object detection, with one feature that sets it apart: independent per-instance attribute heads. Alongside the mask/box + class output, it predicts one or several orthogonal attributes for every detected instance — read straight off the same per-query embedding the detector already computes. No second model, no second pass, and the primary detection metric is untouched (the figure above tells the whole story).
It's a clean-room, Apache-2.0 reimplementation: the weights you train are yours to release.
from eomt import EoMT

model = EoMT("l")                            # fresh large model (DINOv2 backbone)
model.train(data="coco", epochs=50)          # COCO 2017 auto-downloads if missing

model = EoMT("runs/train/eomt-l")            # reload a run — size/classes/heads auto-detected
model.predict("images/", plot=True) # render masks/boxes + per-instance attributesEoMT is a DINOv2-with-registers ViT whose last few transformer blocks are augmented
with a fixed set of learnable queries (the Mask2Former idea) — each query is one
"slot" that latches onto one object instance. After the encoder runs, every query emits
a single vector, the per-query embedding of shape [B, Q, hidden]. The whole model
is then just "turn that embedding into predictions": a class head for the primary
label and a mask/box head for geometry. It is NMS-free, so two overlapping
garments stay two distinct queries instead of being merged — the property that lets
attributes stay attached to the right instance.
The attribute heads add nothing to this picture except themselves: they tap the exact same embedding (captured non-invasively with a forward hook), each a small classifier on top.
This collapses what is classically a two-stage pipeline — detect, crop each box, run a second classifier per crop — into a single pass. Attributes therefore cost only a thin head each, see full-image context (not just a cropped box), and never inherit a second model's cropping errors — the modern, single-stage formulation of the DETR / Mask2Former lineage (see the figure at the top).
Both families share the same DINOv2 encoder, query mechanism, NMS-free matching and auxiliary heads — they differ only in the head on top and what they output:
| family | --task |
output | metric driving best.pt |
|---|---|---|---|
| instance (default) | instance |
per-instance masks + boxes + class | segm/mAP |
| detect | detect |
per-instance boxes + class (DETR-style box head, no masks) | bbox/mAP |
EoMT("l").train(data="coco", family="instance")   # masks (default)
EoMT("l").train(data="coco", family="detect")     # boxes only
The family is recorded in the checkpoint, so val / predict pick the right
post-processing automatically. Everything below applies identically to both.
| size | backbone | hidden | layers | heads | queries |
|---|---|---|---|---|---|
s |
DINOv2-small | 384 | 12 | 6 | 100 |
b |
DINOv2-base | 768 | 12 | 12 | 200 |
l |
DINOv2-large | 1024 | 24 | 16 | 200 |
Default input is a patch-14-aligned square (644 = 14 × 46) so DINOv2 weights load 1:1.
Measured on a single NVIDIA GeForce RTX 5090, 644 × 644 input, batch size 1.
GFLOPs are multiply-accumulates at that resolution (attention included); latency /
throughput are the median over 50 runs after warm-up, under torch.amp.autocast
(fp16) — the package's own inference path.
instance family (masks + boxes + class):
| size | params | GFLOPs | latency (fp16) | throughput (fp16) | throughput (fp32) |
|---|---|---|---|---|---|
s |
24.0 M | 128 | 8.4 ms | 119 img/s | 70 img/s |
b |
93.9 M | 430 | 17.4 ms | 58 img/s | 32 img/s |
l |
317 M | 1144 | 30.2 ms | 33 img/s | 15 img/s |
detect family (boxes + class, no mask head):
| size | params | GFLOPs | latency (fp16) | throughput (fp16) | throughput (fp32) |
|---|---|---|---|---|---|
s |
22.7 M | 89 | 2.9 ms | 348 img/s | 120 img/s |
b |
88.6 M | 276 | 5.3 ms | 190 img/s | 60 img/s |
l |
308 M | 881 | 13.6 ms | 74 img/s | 21 img/s |
Dropping the mask-upsampling head makes detect substantially lighter and ~1.3–3×
faster. Figures are for the detector itself (backbone + queries + heads); the
attribute heads add a thin linear/MLP per head and are negligible by design.
This is the contribution. Conventional detectors fold every distinction into one flat
label space: an object's type × viewpoint × occlusion × … becomes a Cartesian product of
leaf classes that explodes combinatorially, starves each leaf of examples, and multiplies
the Hungarian matcher's targets. attr-eomt factorizes instead — a small, general primary
head plus independent attribute heads that add, not multiply.
Because the heads are independent, the primary taxonomy stays compact and every class keeps
its full sample count; attributes ride along for near-zero compute; and the model composes
attribute × class combinations that never appear in the training data — combinations a
flat label space cannot even represent.
One model segments each garment (primary classes like vest_dress / short_sleeve_top
/ long_sleeve_dress / skirt / trousers …) and, for every detection, reads off
four independent attribute heads — scale (small / modest / large),
occlusion (no / slight / medium), zoom_in (no / medium / large) and
viewpoint (frontal / side / back). The renderer prints the primary class + score
on the first row and each attribute + its confidence on the rows beneath it.
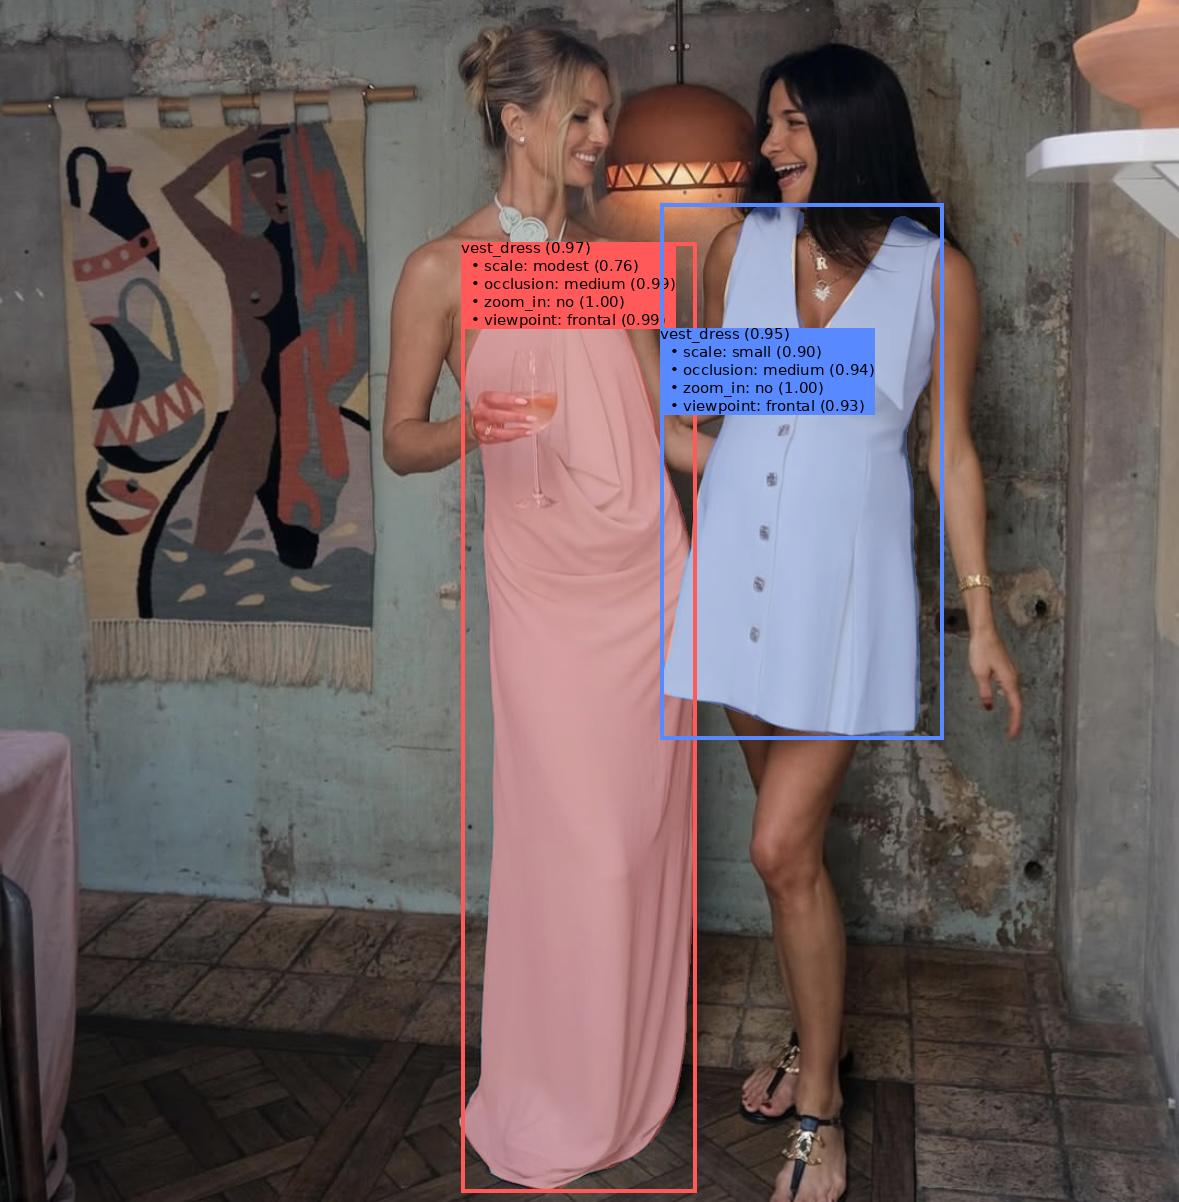
The four attributes are orthogonal to the garment class — they vary independently — which is exactly the case that's awkward to fold into the primary class space. The same pattern fits any "class plus per-instance sub-labels" task: retail shelves → product + facing, documents → element + role, cells → type + health.
Trained on the public DeepFashion2 dataset (13 garment classes + 4 attribute heads) and rendered with the package's own renderer (
eomt.visualize.draw_instances).
Attributes never run their own matcher. Detection already solves "which query is responsible for which ground-truth object" via the Hungarian matcher; attributes simply reuse that same query→GT assignment and read the answer off the matched queries.
- Embedding source. Each head reads the per-query embedding — the input to EoMT's
class_predictor, captured with a forward hook ([B, Q, hidden]). - Matching. Supervision reuses EoMT's own Hungarian matcher
(
model.eomt.criterion.matcher), so every attribute is trained on the same query→GT assignment the detection loss used; the attribute is read after matching. - Gate. An optional IoU gate drops barely-overlapping matched pairs (common early in training) so attributes only learn from queries that actually localize the object.
- Loss. Cross-entropy per head over matched queries, summed across heads and scaled
by
aux_w(default1.0), added to the detector loss. Empty-match batches contribute a graph-preserving zero, and missing labels useignore_indexand contribute nothing. - Checkpoint selection is unchanged. The attribute "rides along": its per-head
matched-query accuracy is shown live and written to
metrics.csv, but never drivesbest.pt(stillsegm/mAPorbbox/mAP). - Inference. Each result attaches
aux = {head: {"ids", "probs"}}for the kept detections, andpredict(plot=True)renders each attribute next to the class label using names stored in the checkpoint.
Attributes live inside the COCO annotations — each annotation is already a
per-instance object, so alignment is automatic and pycocotools still parses it. Just
two additions to a standard COCO file; no YAML changes — heads (count, classes,
names) are discovered from the JSON, the same as nc.
1. A top-level attributes list — one entry per head, defining its vocabulary:
2. A per-annotation attributes map — {head: raw_id} on each instance:
{
  "id": 1, "image_id": 42, "category_id": 1,
  "segmentation": [...], "bbox": [...], "area": 1234, "iscrowd": 0,
  "attributes": {"scale": 3, "viewpoint": 0}
}
Notes:
- Raw ids are remapped to a contiguous
0..n-1per head (soscale's1/2/3become0/1/2);categoriesmay be omitted, in which case the id set is inferred. - A missing or out-of-vocab per-annotation value is ignored (
-100), not trained as class0— so a partially tagged dataset is valid: each head learns only from the instances that actually carry its value. A JSON with noattributes⇒ detection-only, exactly as before.
Class-conditional heads. Give an attribute definition an optional applies_to list of
primary-class names or ids, and that head is only trained on — and only emitted for —
instances of those classes (hard routing on the primary class). Omit it and the head applies
to every class. So different attributes can attach to different classes, each with its own
label set, in one model:
"attributes": [
  {"name": "posture", "categories": [...], "applies_to": ["cat", "dog"]}
]
At inference a scoped head reports ids = -1 ("not applicable") for detections whose class it
does not cover. The scope is stored in the checkpoint, so it survives reload.
Sidecar format (optional). You can keep the COCO JSON as plain, standard COCO and put the
attributes beside it instead of inside it: an attributes.yaml schema in the dataset root plus
attributes/<split>.json values keyed by annotation id ({ann_id: {head: value}}). If present
(and the JSON has no embedded attributes), it is merged in memory at load — so a plain COCO
dataset always works and the sidecar is picked up automatically when you add it. Embedded
attributes in the JSON take precedence.
A tiny, self-contained example (two heads, including a non-contiguous id set) lives in sample_data/.
Several photos of the same scene from different viewpoints, and some instance appears
in three of them — is that one instance seen three times, or three separate ones?
infer_match() answers that at inference time, with no second model and nothing
retrained: every detected instance already carries a fingerprint, the per-query
embedding that feeds the class head, and two detections are the same physical instance
when those embeddings agree.
from eomt import EoMT

model = EoMT("runs/train/eomt-l/weights/best.pt")
result = model.infer_match("photos/subject_42/", group_by=("class",))

for rec in result["identities"]:
    print(rec["identity_id"], rec["class_name"], rec["attributes"], rec["num_photos"])
One call handles one folder = one subject. Each detection is stamped with an
identity_ids entry, identities summarizes each identity (dominant class, smoothed
attributes, how many photos it appears in), and matches records every candidate pair
— accepted or not, with the reason — so a threshold can be retuned from the JSON
without re-running inference. With plot you get a grid image: every photo, instances
colored by identity, plain lines linking the matched pairs (thickness = similarity, on
an absolute scale that does not vary with panel size), and a legend.
python scripts/match.py weights/best.pt photos/subject_42/
python scripts/match.py weights/best.pt photos/ --each-subdir # a folder per subjectIt is the DeepSORT recipe — detect, describe, associate — applied between photos
instead of between video frames, which is also what track()
does for video. Three EoMT properties make the fingerprint free:
- the model is NMS-free, so two overlapping instances stay two distinct queries;
- each query owns one instance, so its embedding describes that instance alone;
- the embedding is already computed on the way to the class head.
Matching runs the Hungarian matcher per pair of photos, then links the accepted pairs into identities with union-find. Two constraints keep that honest: one physical instance appears at most once per photo (union-find would otherwise chain two instances of the same photo together through a third), and a merge guard rejects a merge whose cross-cut similarity falls below the threshold — without it, A↔B and B↔C chain into one identity even when A and C are nothing alike.
group_by decides which pairs may match at all. The default ("class",) means only
same-class instances compete. Adding attribute heads tightens it, which matters
whenever the primary class is coarser than the distinction you care about: if one class
covers instances that sit at different places on the subject, an attribute head that
separates them — ("class", "position"), say — stops an instance in one location from
ever matching one in another, however alike they look. Any head in the checkpoint can
be named; unknown names raise before the first forward pass. group_by=None disables
gating entirely and needs a much higher sim_thres, since far more pairs then compete
with no structural prior ruling any of them out.
sim_thres (default 0.7) is the cosine floor for "same instance". Hungarian always
returns a full assignment, so the threshold is what turns best available partner into
no partner — this is a new instance. Measured on one checkpoint across four real
photo sets, with the gate on:
| non-candidate pairs | true-match pairs | |
|---|---|---|
| mean | 0.11 – 0.16 | 0.85 – 0.98 (the true-match mode) |
| p99 / max | 0.40 – 0.67 / 0.49 – 0.79 | — |
The default was raised from 0.6 to 0.7 after a 30-case run showed non-candidate
pairs reaching 0.73 and the two distributions overlapping in over half the cases —
0.6 was admitting matches with no margin at all. Every run
writes its own diagnostics (within-identity vs across-identity percentiles) into
<subject>_identities.json; if those two distributions overlap, no threshold will
save the run.
- A gate group with one instance per photo gets no benefit from the embedding.
Hungarian has no choice to make, and only
sim_threscan veto the pairing. The fingerprint earns its keep where several instances of one group compete in the same photo. - Small-instance recall caps what can be matched. An instance that is never detected in a view cannot be linked to it.
- One folder must be one subject. A folder holding photos of more than one subject will happily link generic-looking instances across them; that is a data problem, not a matching one.
- Letterboxing shifts scale with orientation, so a landscape and a portrait shot of the same subject are not on quite equal footing.
pip install attr-eomt                  # from PyPI
pip install "attr-eomt[logging]"       # + tensorboard/wandb
pip install -e ".[dev]" # from source (editable; [dev] adds pytest/build/twine)Everything goes through one class. Initialize from a size (fresh model, pretrained
DINOv2 backbone) or from a checkpoint / run folder (family, size, classes, image
size, normalization and any auxiliary heads are auto-detected from the .pt):
from eomt import EoMT

# Train on COCO 2017 (auto-downloaded on first run):
EoMT("l").train(data="coco", epochs=50, batch=4)

# ...or any COCO-format dataset (point at its data.yaml):
EoMT("s").train(data="sample_data/data.yaml", epochs=1, batch=1)

# Validate and predict from a trained run:
EoMT("runs/train/eomt-l").val(data="coco")
EoMT("runs/train/eomt-l").predict("images/", plot=True)   # writes annotated images
For the full training recipe, every train() knob, and int8 compression, see the
annotated explainer → — it's the deep dive.
- Model export. ONNX / TensorRT (and friends) for deployment — currently out of scope; the inference path is being kept export-friendly.
- Keypoints. A keypoint/pose head family alongside
instanceanddetect(the code already carries afamilyparameter so new heads slot in without API churn). - Pretrained COCO checkpoints. None are published yet. COCO-trained
s/b/lweights will be released on the Hugging Face Hub (thefrom_pretrained/hf://loading plumbing is already in place and waiting for them). - Contrastive re-ID training. Cross-photo re-identification already works at
inference time (see above) on the embedding the
detector computes anyway. What remains is training that embedding for the job: a
contrastive objective on the matched queries would make each one a purpose-built
re-identification vector rather than a by-product of the class head, which should
widen the margin between matches and non-matches and make
sim_threstransferable across datasets. Feeding those embeddings into the video tracker to re-associate objects across occlusions is the same lever.