
An async Textual TUI for website reconnaissance — DNS, WHOIS, TLS, security, tech-stack and SEO, with no paid APIs.
Point it at a domain and it concurrently gathers DNS, WHOIS, TLS, security, tech-stack and SEO intelligence, then lays it out across tabs — with a live activity log, a country map and a server-status panel that stay pinned in place.
No paid APIs. Everything runs off free, public endpoints and the standard library:
ip-api.com for geolocation, Cloudflare/Google DoH and dig against public filtering
resolvers for blocklist checks, the system whois, and stdlib ssl/socket. Country
borders are embedded (Natural Earth), so even the map needs no tile service.
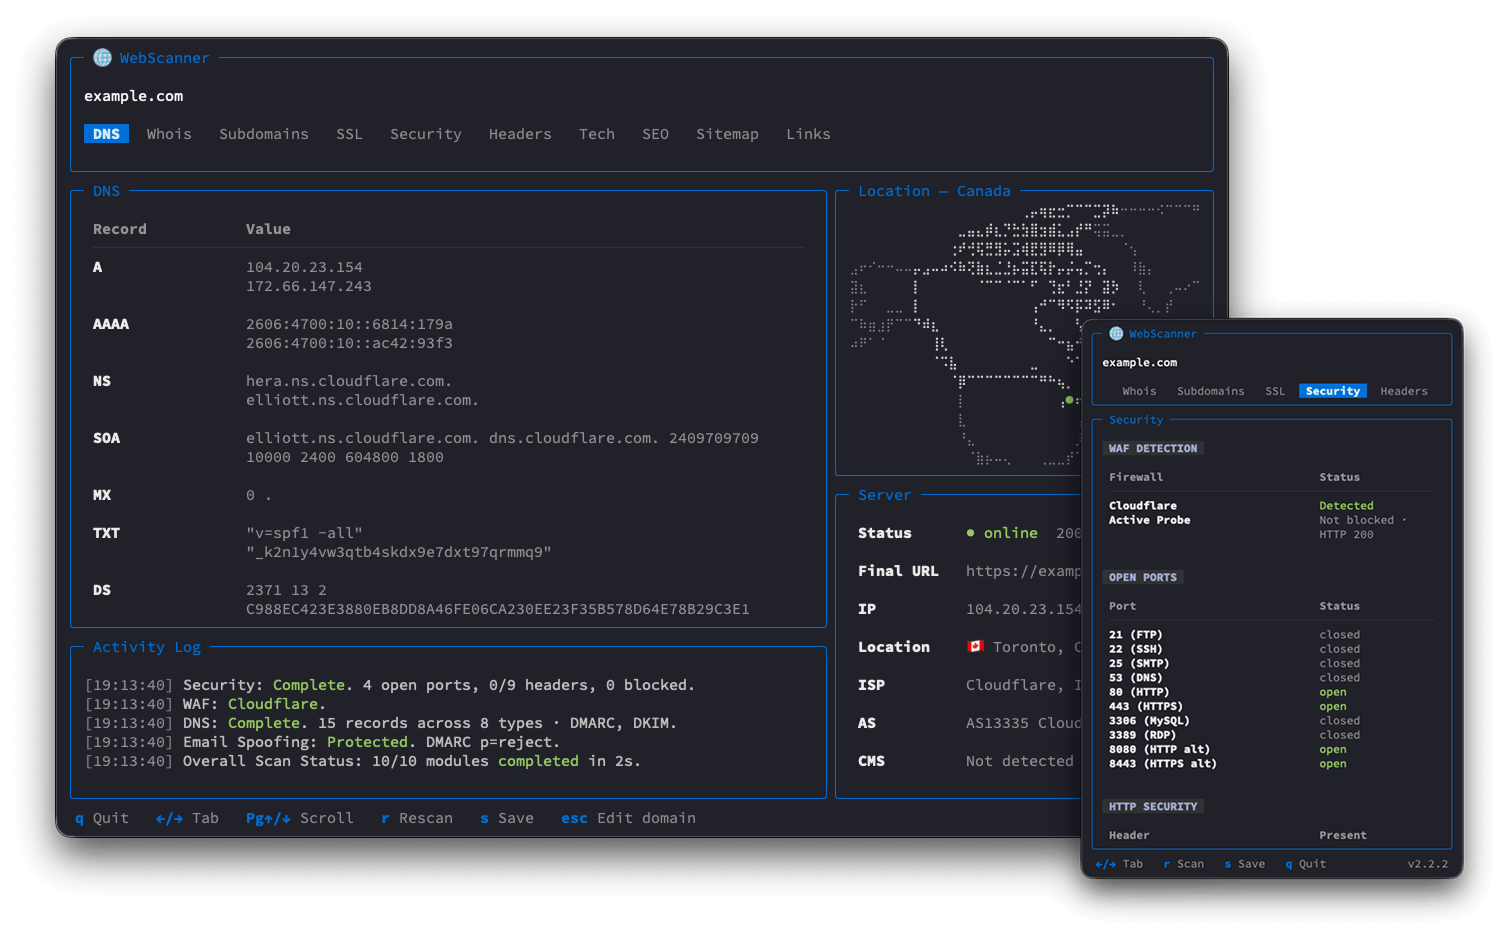
Ten tabs, scanned concurrently and rendered live as each module finishes:
- DNS — records plus email authentication, folded into one tab.
- A / AAAA / NS / CNAME / SOA / MX / TXT / CAA / DS / DNSKEY records
- DMARC (
_dmarc) and DKIM (probes ~40 selectors, each labelled with its email provider) - SPF
allqualifier, and an Email Spoofing verdict (Protected / Weak / Vulnerable) computed from DMARC enforcement, not SPF alone
- Whois — parsed system
whois, with rich gTLD and ccTLD field support.- Registrar, registration / expiry dates, nameservers
- Per-contact details where published
- Subdomains — discovered natively, no third-party enumeration services.
- TLS certificate SANs
socketprobes of common subdomains
- SSL — the live TLS certificate, parsed from the handshake.
- Issuer, subject, SANs
- Validity window, trust and expiry
- Security — four checks, each a sub-table.
- WAF detection — passive header/cookie fingerprinting plus an active probe that sends obvious attack payloads to see if it gets blocked (names Cloudflare, Sucuri, Akamai, ModSecurity, …)
- Open ports — TCP connect scan of common ports
- HTTP security headers — CSP, HSTS, X-Frame-Options, … present or not
- Blocklists — status across public filtering resolvers (AdGuard, CleanBrowsing, Cloudflare, Google, OpenDNS, Quad9)
- Headers — the full set of HTTP response headers.
- Tech — technology-stack detection via Wappalyzer.
- Each technology with its category, confidence, groups and version
- SEO — everything on-page that search engines read.
- Title / description with length hints, H1–H3, social links
- Top keyword n-grams (1 / 2 / 3-word)
robots.txtand declared sitemaps- JSON-LD structured data
- Sitemap — the site's URLs as a clickable path tree, no crawling.
- Discovered from
sitemap.xml, recursing into nested sitemap indexes - Rebuilt into a folder tree keyed by URL path
- Discovered from
- Links — links found on the page, with their anchor text.
- Internal and external, split into sub-tables
Alongside the tabs, three fixed panels:
- Activity Log — a running narration of the scan: what each module found, what came back empty and what broke, so every headline result is visible without switching tabs.
- Country map — real country outlines auto-framed around the server's location, drawn
with braille characters (
+/-to zoom). - Server — online status and response time, the final URL after redirects, IP, geolocation, ISP, AS, hosting provider and detected CMS (name and version). When many sites share the server's IP, it flags the address as shared and counts how many distinct domains resolve to it (via a free reverse-IP lookup, hackertarget, rate-limited to 50 requests/day).
The layout is responsive: on a narrow terminal it collapses to a single full-width column and the map, Server and Activity panels fold into their own tabs.
Requests to the site being scanned wear a coherent desktop-Chrome identity — a real
User-Agent plus the headers Chrome actually sends beside it — picked once per scan and
reused for every request, and reported in the Activity Log. This is about getting the real
page back rather than a WAF block page, and it only defeats naive User-Agent filtering: the
TLS and HTTP/2 fingerprints are still those of requests, so enterprise bot management sees
straight through it. Third-party lookups (ip-api, DoH) keep an honest scanner User-Agent.
Requires Python 3.11+.
The easiest way is with pipx (or uv),
which installs webscan into its own isolated environment:
pipx install web-scanner
# or
uv tool install web-scanner
To install the latest unreleased code, point either tool at the repo instead:
pipx install git+https://github.com/iamramizk/web-scanner.
git clone https://github.com/iamramizk/web-scanner.git
cd web-scanner
python3 -m venv .venv
source .venv/bin/activate     # Unix/macOS  (.venv\Scripts\activate on Windows)
pip install -e .webscan example.comYou can also run it as a module (python -m webscanner example.com), or from a source
checkout without installing (python app.py example.com).
Once a scan finishes you can stay in the app: press r to rescan the same domain, or esc
to edit the domain and scan a different one — no need to restart.
Press s to save every tab to CSV (plus a server.csv for the fixed Server panel, which
has no tab of its own). Files go into a <domain>_<timestamp>/ folder — under output/
when running from a source checkout, or straight in your current directory when installed.
The app checks PyPI in the background once a day and, when a newer release is out, marks the version in the footer with an orange dot and adds a line to the Activity Log — so you'll know when it's worth upgrading.
pipx upgrade web-scannerIf you installed from Git, pipx upgrade won't see new commits (the version is unchanged),
so reinstall from source instead:
pipx install --force git+https://github.com/iamramizk/web-scanner| Key | Action |
|---|---|
← / → Tab |
Switch tabs |
1–9 0 |
Jump straight to the Nth tab (0 = 10th) |
PgUp / PgDn |
Scroll the main panel up / down |
+ / - |
Zoom the country map in / out |
↑ / ↓ enter |
Navigate the Sitemap tree (space expands/collapses all) |
r |
Rescan |
s |
Save — export every tab to CSV under <domain>_<timestamp>/ |
esc |
Edit the domain and scan a new one |
q |
Quit |