
Ontology-guided extraction of RDF knowledge graphs from documents.


OntoCast reads documents and writes an RDF knowledge graph: an ontology that describes the domain, and the facts the documents state in its terms. Give it your ontologies and it extracts facts against them; give it none and it builds one as it reads. Run it as an HTTP service, as a batch command, or inside your own LangChain or LangGraph agent.
Documentation: growgraph.github.io/ontocast
- Ontology and facts together. Each part of a document goes through a language model in a render-and-critique loop, in parallel; ontology changes are merged, versioned and checked before facts are extracted against them.
- Patches, not rewrites. The model emits insert/delete updates to a graph rather than regenerating it.
- Entity disambiguation. Mentions of the same entity across a document are merged into one.
- Validation. Deterministic checks, SHACL shapes, and repairs that need no extra model call.
- Provenance. Facts carry RDF 1.2 provenance back to the text, which you can strip on output.
- Ontology context. Each part of a document is shown the ontology it needs: chosen from your catalog, retrieved from a vector store (LanceDB or Qdrant), or fixed.
- Storage. In memory by default, Apache Jena Fuseki for persistence, partitioned by tenant and project.
- A light core. The base install embeds without a document-processing stack or an ML runtime; those are extras.
pip install "ontocast[server,openai,doc-processing]"server provides the ontocast command and HTTP API, openai the model
provider (anthropic, google and ollama also exist), and doc-processing
the document converter (PDF, Office, HTML, Markdown, images). All extras:
Installation.
OntoCast reads its settings from environment variables:
export LLM_API_KEY=sk-...
ontocast serve
curl -X POST http://127.0.0.1:8999/process -F "file=@document.pdf" -o result.json
The response holds the facts and the ontology as Turtle. To process files without a server:
ontocast process --input-path ./papers --output-dir ./outTo keep settings in a file, copy .env.example.minimal,
edit it, and pass it with ontocast --env-file my.env serve (repeatable; later
files win). Step by step:
Quick start.
Put Turtle files in a directory and pass it at startup, or upload them to a running server:
ontocast serve --ontology-dir ./my-ontologies
curl -X POST http://127.0.0.1:8999/ontologies -F "file=@my-ontology.ttl"from langchain.agents import create_agent
from ontocast import Config, ToolBox, ontocast_tools
tools = await ToolBox.acreate(Config.in_memory())
await tools.initialize()
agent = create_agent(
model,
tools=[*ontocast_tools(tools)],
prompt="Edit the ontology from the user's text.",
)run_unit_pipeline processes a single passage, and make_ontocast_node adds
OntoCast to your own LangGraph. See Embedding
OntoCast.
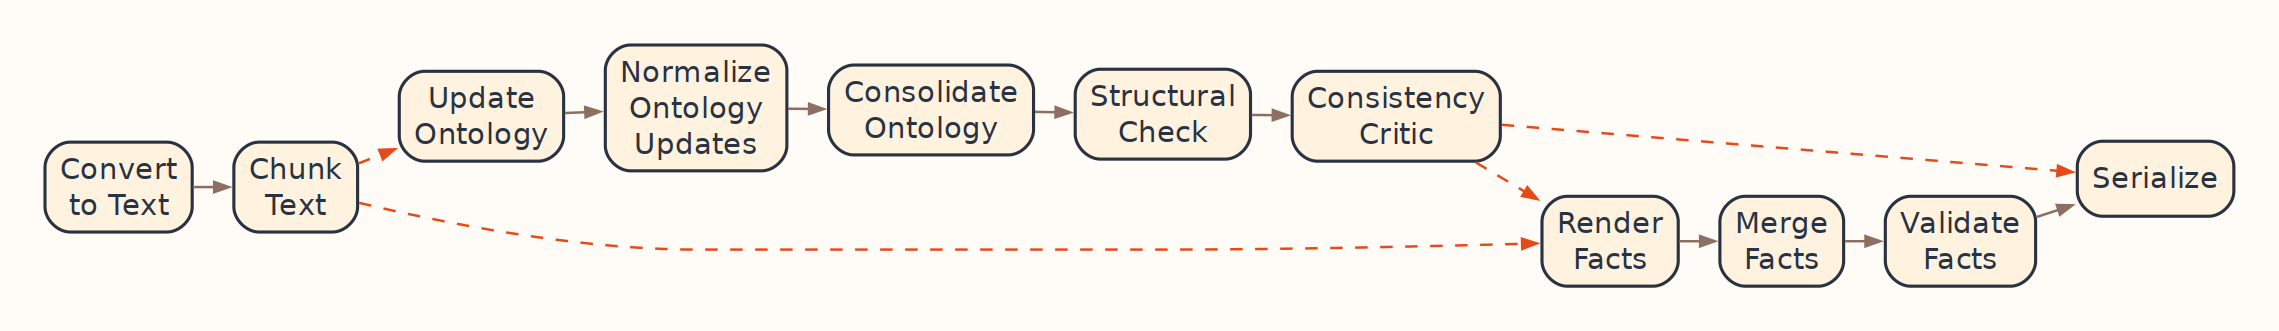
A document is converted to text and cut into parts. Each part updates the ontology; the updates are normalized, consolidated and checked. Each part then yields facts in the ontology's terms; the facts are merged, disambiguated and validated, and the result is written to the triple store. How OntoCast works.
| Getting started | Installation · Quick start |
| Concepts | How OntoCast works · Ontologies and facts |
| Guides | Configuring OntoCast · Recipes · Validation and SHACL · Triple stores |
| Reference | Configuration · HTTP API · Python API |
Release notes: CHANGELOG.md
See Contributing. Issues and discussion: GitHub. Contributors accept the Contributor License Agreement once, by commenting on their first pull request.
Apache License 2.0; see LICENSE.