In this project I will use VGG16 model to detect faces in images. I will use architecture of VGG16 model and will remove the last layer of the model and will add a new layer which will be used to detect faces in images.
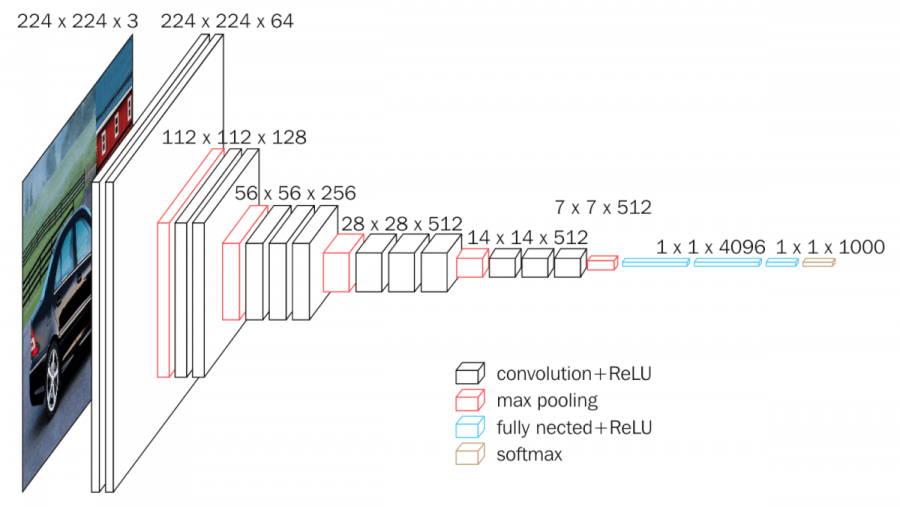
VGG16 is a convolutional neural network model proposed by K. Simonyan and A. Zisserman from the University of Oxford in the paper “Very Deep Convolutional Networks for Large-Scale Image Recognition”. The model achieves 92.7% top-5 test accuracy in ImageNet, which is a dataset of over 14 million images belonging to 1000 classes. It was one of the famous model submitted to ILSVRC-2014. It makes the improvement over AlexNet by replacing large kernel-sized filters (11 and 5 in the first and second convolutional layer, respectively) with multiple 3×3 kernel-sized filters one after another. VGG16 was trained for weeks and was using NVIDIA Titan Black GPU’s.
The model architecture is shown below:
I created a dataset of images using my camera and then augmented the images to increase the size of the dataset. Then I label that dataset using labelme tool. The dataset contains images of face and non-face.
I will use the VGG16 model architecture and will remove the last layer of the model and will add a new layer which will be used to detect faces in images. I only train the model fro 40 epochs as the dataset is small and the model is already trained on large dataset.
For model evaluation I use my test data as I already divided my dataset into training,validation and test.
The model is able to detect faces in images with an accuracy of 95% on test data.
In future I will use more complex model to detect faces in images and will use more complex dataset to train the model and will use more complex data augmentation techniques to increase the size of the dataset.
As this project is solely based on learning and implementing the VGG16 model, I have used the Youtube channel of Nicholas Renotte, to learn and implement the model.