{"fetchedAt": "2026-09-20T00:12:14.647861Z", "models": [{"id": "prism-ml/Ternary-Bonsai-2-27B-gguf", "pipeline_tag": "text-generation", "downloads": 1516960, "likes": 1200, "last_modified": "2026-09-17T18:44:01.000Z", "tags": ["llama.cpp", "gguf", "ternary", "2-bit", "llama-cpp", "cuda", "metal", "on-device", "hybrid-attention", "prismml"], "readme": "---\nlicense: apache-2.0\nlibrary_name: llama.cpp\npipeline_tag: text-generation\ntags:\n- ternary\n- 2-bit\n- gguf\n- llama-cpp\n- cuda\n- metal\n- on-device\n- hybrid-attention\n- prismml\n- bonsai\nbase_model:\n- Qwen/Qwen3.8-27B\n---\n\n<p align="center">\n <img src="./assets/bonsai-logo.svg" width="280" alt="Bonsai">\n
\n\n<p align="center">\n <a href="https://prismml.com">
Prism ML Website | \n <a href="https://github.com/PrismML-Eng/Bonsai-demo/blob/main/bonsai-2-27b-whitepaper.pdf">
Whitepaper | \n <a href="https://github.com/PrismML-Eng/Bonsai-demo">
Demo & Examples | \n <a href="https://discord.gg/prismml">
Discord\n
\n\n# Bonsai 2 27B — GGUF\n\nFull 27B-class reasoning in ternary transformer weights, for llama.cpp (CUDA, Metal, CPU)\n\n>
\~9.3x smaller than FP16 (ideal) |
98.2% of FP16 intelligence retained |
\~47 tok/s on an Apple M5 Max laptop\n\n## Highlights\n\n-
\~5.9 GB language model (down from \~54 GB FP16) — full 27B-class reasoning on a standard laptop or a single GPU\n-
98.2% of FP16 intelligence retained: 84.78 average across 14 thinking-mode benchmarks — far above the conventional IQ2_XXS build (72.59) at less than two-thirds of its footprint, and within 0.4 points of UD-Q4_K_XL at three times the footprint\n-
Retains thinking, reasoning, and agentic behavior deep in the sub-4-bit regime, where conventional low-bit representations collapse: math within half a point of full precision (96.57), coding level with the baseline (89.42), agentic tool calling at 74.92\n-
End-to-end ternary language weights across embeddings, attention projections, MLP projections, and LM head, at a
true 1.72 bits per weight — no high-precision escape hatches behind a low-bit label; the vision tower ships as a separate Q8_0 mmproj pack\n-
262K-token context on-device, kept practical by the Qwen3.8-27B hybrid-attention backbone (\~75% linear attention)\n-
Two GGUF packings with custom te", "params_total": null}, {"id": "deepseek-ai/DeepSeek-V4.1-Flash", "pipeline_tag": "image-text-to-text", "downloads": 482270, "likes": 3299, "last_modified": "2026-09-10T08:18:10.000Z", "tags": ["transformers", "safetensors", "deepseek_v41", "text-generation", "image-text-to-text", "license:mit", "eval-results", "endpoints_compatible", "8-bit", "fp8"], "readme": "---\nlicense: mit\nlibrary_name: transformers\npipeline_tag: image-text-to-text\n---\n\n# DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression\n\n\n\n\n\n<div align="center">\n <img src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/logo.svg?raw=true" width="60%" alt="DeepSeek-V4.1" />\n\n
\n<div align="center" style="line-height: 1;">\n <a href="https://www.deepseek.com/" target="_blank" style="margin: 2px;">\n <img alt="Homepage" src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/badge.svg?raw=true" style="display: inline-block; vertical-align: middle;"/>\n \n <a href="https://chat.deepseek.com/" target="_blank" style="margin: 2px;">\n <img alt="Chat" src="https://img.shields.io/badge/🤖%20Chat-DeepSeek%20V4.1-536af5?color=536af5&logoColor=white" style="display: inline-block; vertical-align: middle;"/>\n \n\n<div align="center" style="line-height: 1;">\n <a href="https://huggingface.co/deepseek-ai" target="_blank" style="margin: 2px;">\n <img alt="Hugging Face" src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-DeepSeek%20AI-ffc107?color=ffc107&logoColor=white" style="display: inline-block; vertical-align: middle;"/>\n \n <a href="https://twitter.com/deepseek_ai" target="_blank" style="margin: 2px;">\n <img alt="Twitter Follow" src="https://img.shields.io/badge/Twitter-deepseek_ai-white?logo=x&logoColor=white" style="display: inline-block; vertical-align: middle;"/>\n \n\n<div align="center" style="line-height: 1;">\n <a href="LICENSE" style="margin: 2px;">\n <img alt="License" src="https://img.shields.io/badge/License-MIT-f5de53?&color=f5de53" style="display: inline-block; vertical-align: middle;"/>\n \n\n\n<p align="center">\n <a href="https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf">
Technical Report", "params_total": null}, {"id": "Qwen/Qwen3.8-27B", "pipeline_tag": "image-text-to-text", "downloads": 7365368, "likes": 15759, "last_modified": "2026-08-14T15:00:01.000Z", "tags": ["transformers", "safetensors", "qwen3_5", "image-text-to-text", "conversational", "license:apache-2.0", "eval-results", "endpoints_compatible", "deploy:azure", "deploy:sagemaker"], "readme": "---\r\nlibrary_name: transformers\r\nlicense: apache-2.0\r\npipeline_tag: image-text-to-text\r\n---\r\n\r\n# Qwen3.8-27B\r\n\r\n> [!Note]\r\n> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. \r\n>\r\n> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.\r\n\r\n> [!Tip]\r\n> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by
Qwen Cloud.\r\n> In particular,
Qwen3.8-27B will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the
Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates.\r\n\r\nFollowing the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date.\r\n\r\nBuilt on the architectural foundation of Qwen3.5, Qwen3.8 delivers substantial gains across coding, professional work, research, and long-horizon agentic tasks. Qwen3.8-27B brings these advances to a compact, deployment-friendly dense model: a native vision-language model that understands images and videos, with flexible thinking control, designed to carry complex, multi-step tasks through to completion with greater reliability.\r\n\r\n## Qwen3.8 Highlights\r\n\r\nQwen3.8-27B features the following enhancements:\r\n-
Core Capabilities: Comprehensive improvements across coding, professional work, research, and long-horizon agentic tasks.\r\n-
Agent Execution: Stronger autonomous planning and better handling of environment feedback, leading to more reliable end-to-end task completion.\r\n-
Downstream Compatibility: Broader support for popular harnesses and development tools, making it easier to integrate into your existing stack.\r\n- ", "params_total": null}, {"id": "XingChen-AGI/Xing4.0-29B-A4B", "pipeline_tag": "text-generation", "downloads": 7278, "likes": 628, "last_modified": "2026-09-18T09:49:55.000Z", "tags": ["transformers", "safetensors", "xing4_0", "text-generation", "conversational", "custom_code", "arxiv:2512.24157", "arxiv:2507.18013", "license:apache-2.0", "region:us"], "readme": "---\nlibrary_name: transformers\nlicense: apache-2.0\npipeline_tag: text-generation\n---\n\n# Xing4.0-29B-A4B\n\n> [!Note]\n> This repository provides the model weights and configuration files for Xing4.0-29B-A4B in Hugging Face Transformers format, compatible with Transformers, vLLM, SGLang, KTransformers, and other mainstream inference frameworks.\n\n
Xing4.0-29B-A4B is a next-generation large language model in the Xing series (formerly
TeleChat), developed by China Telecom Artificial Intelligence Technology Co., Ltd. With 29B total parameters and only 4B activated per token, it natively supports a 256K context length, extensible to 512K. It is the first model of this scale trained entirely on the Ascend NPU platform with the MindSpore framework, and deeply optimized for complex engineering tasks.\n\nFor more information, please refer to our
GitHub repository.\n\n\n## Highlights\n\n-
Agent-Oriented Architecture: Built on the mHC + MLA + MTP architecture, supporting multi-step planning, tool calling, and complex reasoning chain execution, ensuring task coherence and execution stability under long contexts.\n-
Deep Co-optimization with Ascend NPU: Adapted for Ascend 910C clusters using MindSpore/MindFormers, including feature adaptation for mHC and fused operator development, enabling stable and efficient training on the Ascend platform.\n-
Significant Training Efficiency Gains: Through multi-level co-optimization — including fine-grained MoE communication optimization, selective recomputation, DVM automatic graph-operator fusion, and Ascend C mHC fused operators — overall training throughput was improved by approximately
96% over out-of-the-box performance.\n-
Full Open-Source Ecosystem Compatibility: Supports LLaMA-Factory and MindFormers for fine-tuning; SGLang, vLLM, and KTransformers for inference and deployment; with targeted adaptation and format alignment for agent f", "params_total": null}, {"id": "m-a-p/YuE2-3B", "pipeline_tag": "text-to-audio", "downloads": 15446, "likes": 871, "last_modified": "2026-09-16T08:38:56.000Z", "tags": ["safetensors", "yue2", "music-generation", "symbolic-planning", "agentic-editing", "custom_code", "text-to-audio", "zh", "en", "arxiv:2503.08638"], "readme": "---\nlicense: cc-by-nc-4.0\nlanguage:\n- zh\n- en\npipeline_tag: text-to-audio\ntags:\n- music-generation\n- symbolic-planning\n- agentic-editing\n- custom_code\n---\n<p align="center">\n <img src="assets/logo.png" alt="YuE logo" width="144" />\n
\n<h1 align="center">🤗 YuE2-3B\n<p align="center">
Frontier music generation with editable scores\n\n<p align="center">\n <a href="https://github.com/multimodal-art-projection/YuE"><img alt="GitHub" src="https://img.shields.io/badge/GitHub-YuE-181717?logo=github&logoColor=white" height="20" />\n \n <a href="https://discord.gg/ssAyWMnMzu"><img alt="Join Discord" src="https://img.shields.io/discord/842440537755353128?label=Discord&color=5865F2&logo=discord&logoColor=white" height="20" />\n
\n<p align="center">\n <a href="https://map-yue2.github.io/">🎧 Demo\n ·\n <a href="https://arena.3-148-255-99.sslip.io:8080">🗳️ Music Arena\n ·\n <a href="#quick-start">🚀 Quick start\n ·\n <a href="#cover-an-existing-song">🎙️ Cover\n ·\n <a href="#export-a-plan-edit-it-and-generate">🤖 Edit\n ·\n <a href="#speed-and-resources" title="Speed and resources">⚡ Speed\n ·\n <a href="#benchmarks">📊 Benchmarks\n ·\n <a href="#citation">📚 Citation\n
\n<p align="center">\n <a href="https://huggingface.co/m-a-p/YuE2-3B"><img alt="🤗 YuE2-3B" src="https://img.shields.io/badge/YuE2--3B-374151?logo=huggingface&logoColor=FFD21E" height="20" />\n \n <a href="https://huggingface.co/m-a-p/YuE2-Vae"><img alt="🤗 YuE2-Vae" src="https://img.shields.io/badge/YuE2--Vae-374151?logo=huggingface&logoColor=FFD21E" height="20" />\n \n <a href="https://huggingface.co/m-a-p/YuE2-Vae-legacy"><img alt="🤗 YuE2-Vae-legacy" src="https://img.shields.io/badge/YuE2--Vae--legacy-374151?logo=huggingface&logoColor=FFD21E" height="20" />\n \n <a href="https://huggingface.co/m-a-p/MERT-v2-30s"><img alt="🤗 MERT-v2-30s" src", "params_total": null}, {"id": "convaiinnovations/laya", "pipeline_tag": "text-classification", "downloads": 0, "likes": 520, "last_modified": "2026-09-19T09:53:44.000Z", "tags": ["transformers", "safetensors", "laya", "system-one", "calibrated-decisions", "rlcd", "classification", "routing", "scoring", "guardrails"], "readme": "---\nlicense: apache-2.0\nlibrary_name: transformers\npipeline_tag: text-classification\ntags:\n- laya\n- system-one\n- calibrated-decisions\n- rlcd\n- classification\n- routing\n- scoring\n- guardrails\n- moderation\n- reinforcement-learning\n- commercial-use\n---\n\n<p align="center">\n <img src="assets/logo-lockup.png" alt="Laya" width="330" />\n
\n\n
Multilingual, non-autoregressive System 1 decision model. Give it a
state (text, email,\nticket, or JSON) and
typed questions; it returns typed answers with probabilities in a\nsingle forward pass — 33 ms — across 100+ languages. Trained with reinforcement learning against\nstrictly proper scoring rules (
RLCD), so reporting honest probabilities is the only way to\nmaximise reward. It never generates text, so there is nothing to parse and nothing to\nhallucinate.\n\n<p align="center">\n <img src="assets/laya_vs_jev_full.png" alt="Laya versus TypeSafe Jev: accuracy, every application workflow, all 51 languages, speed, calibration and routing cost" width="100%" />\n
\n\n
This repo holds all three checkpoints and is the hub for the family. The English checkpoint\nis at the repo root; the other two are subfolders, and only the one you ask for is downloaded:\n\n
python\nimport laya\n\nlaya.load(\"convaiinnovations/laya\") # English\nlaya.load(\"convaiinnovations/laya\", subfolder=\"multilingual\") # 100+ languages\nlaya.load(\"convaiinnovations/laya\", subfolder=\"typed-decisions\")\n\n\n| checkpoint | encoder | params | context | use it for |\n|---|---|---|---|---|\n|
convaiinnovations/laya (this repo) | ModernBERT-large | 421M | 512 | English |\n|
convaiinnovations/laya-multilingual | mmBERT-base | 322M | 1024 | 100+ languages,
2x faster |\n| convaiinnovations/laya-typed-decisions | ModernBERT-large | 421M | 1024 | the typed-decisions workflows |\n\n| question type | returns |\n|---|---", "params_total": null}, {"id": "ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 1154265, "likes": 1417, "last_modified": "2026-09-02T09:11:34.000Z", "tags": ["gguf", "gsq", "rco", "quantization", "mixed-precision", "ist-daslab", "multimodal", "vision", "image-text-to-text", "arxiv:2604.18556"], "readme": "---\nbase_model: Qwen/Qwen3.8-27B\nbase_model_relation: quantized\npipeline_tag: image-text-to-text\nlibrary_name: gguf\nlicense: apache-2.0\ntags:\n- gguf\n- gsq\n- rco\n- quantization\n- mixed-precision\n- ist-daslab\n- multimodal\n- vision\n---\n\n\n\n<div align="center">\n\n<a href="https://github.com/IST-DASLab"><img src="https://huggingface.co/ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF/resolve/main/assets/banner.png" alt="GGUF, GSQ-RCO dynamic non-uniform quantization" width="100%"/>\n\n
\n\n# Qwen3.8-27B · GSQ-RCO GGUFs\n\nNon-uniform GGUF quantizations produced with GSQ and RCO, with a vision projector for multimodal use.\n\n \n
 \n
 \n
 \n
 \n
 \n\n\n\n and as a result getting a x1.95 speed-up on several tasks.\n\n<video controls autoplay muted loop playsinline style="width:100%;max-width:100%;height:auto;display:block;border-radius:12px;margin:0.8em 0 1.4em;" src="https://huggingface.co/ukisai/Swift-Qwen3.8-27b/resolve/main/swift-speed-demo.mp4">\n<p align="center" style="font-size:13px;color:#8C94A8;margin:-0.6em 0 1.4em;">The prompt is a sample from LiveCodeBench v6\n\n## Training approach\n\nWe built Swift by identifying reasoning-marker tokens that, in our analysis, trigger overthinking in Qwen’s\nreasoning rollouts. We then fine-tuned Qwen by penalizing usage of those tokens while it reasons.\n\nSwift produces shorter reasoning traces. In our testing, we also observe fewer overthinking errors.\n\nFor maximum gains, Swift also includes ", "params_total": null}, {"id": "harshatheg/Qwen-2.5-1B-RLCD", "pipeline_tag": "text-generation", "downloads": 0, "likes": 425, "last_modified": "2026-09-16T06:23:02.000Z", "tags": ["mlx", "structured-generation", "parallel-decoding", "constrained-decoding", "apple-silicon", "classification", "json", "text-generation", "en", "base_model:Qwen/Qwen2.5-1.5B-Instruct"], "readme": "---\nlanguage:\n- en\nlicense: apache-2.0\nlibrary_name: mlx\ntags:\n- structured-generation\n- parallel-decoding\n- constrained-decoding\n- apple-silicon\n- mlx\n- classification\n- json\npipeline_tag: text-generation\nbase_model: Qwen/Qwen2.5-1.5B-Instruct\nspaces:\n- drinkmoonshine/parallel-constrained-decoding\n---\n\n# Parallel Constrained Decoding for Apple Silicon\n\n
 \n\n> Live Demo: Try the side-by-side comparison live on Hugging Face Spaces: drinkmoonshine/parallel-constrained-decoding.\n\nA high-throughput inference engine for structured information extraction, decision routing, and categorical classification on Apple Silicon using MLX.\n\nParallel Constrained Decoding evaluates multi-field JSON schemas simultaneously rather than generating tokens sequentially. On an Apple Silicon M4 Max, it delivers 5.6x to 7.0x latency reductions compared to standard autoregressive decoding with 100% schema validity and calibrated field-level confidence scores.\n\n---\n\n## Performance Benchmarks (Apple Silicon M4 Max)\n\nEvaluated with
mlx-community/Qwen2.5-1.5B-Instruct-4bit on macOS Sequoia:\n\n| Scenario | Fields | Autoregressive Baseline | Parallel Constrained | Latency Speedup | Syntax Validity |\n| :--- | :--- | :--- | :--- | :--- | :--- |\n| Fintech Fraud Routing | 4 fields | 420 ms (120 tok/s) | 75 ms | 5.6x | 100% guaranteed |\n| Code Security Audit | 4 fields | 380 ms (125 tok/s) | 68 ms | 5.6x | 100% guaranteed |\n| High-Cardinality Tariff | 1 field (255 choices) | 500 ms (118 tok/s) | 89 ms | 5.6x | 100% guaranteed |\n| Enterprise Support Triage | 28 fields | 1,900 ms (130 tok/s) | 270 ms | 7.0x | 100% guaranteed |\n\n---\n\n## Why Parallel Constrained Decoding?\n\n### The Problem", "params_total": null}, {"id": "DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 1256962, "likes": 958, "last_modified": "2026-09-16T23:56:33.000Z", "tags": ["gguf", "unsloth", "fine tune", "heretic", "uncensored", "abliterated", "ara", "MTP GGUF Quants", "Regular GGUF Quants", "qwen3_8"], "readme": "---\nlanguage:\n- en\n- zh\nlicense: apache-2.0\ntags:\n- unsloth\n- fine tune\n- heretic\n- uncensored\n- abliterated\n- ara\n- MTP GGUF Quants\n- Regular GGUF Quants\n- qwen3_8\n- qwen3_6\n- qwen3_5\n- multi-stage tuned\n- thinking\n- reasoning\n- all use cases\n- coder\n- creative\n- creative writing\n- all genres\n- story\n- writing\n- fiction\n- roleplaying\n- bfloat16\n- multi-stage-tune\n- multi-state-merge\ndatasets:\n- DavidAU/Polar-STRICT-Datasets\n- DavidAU/F451-STRICT-Datasets\npipeline_tag: image-text-to-text\nbase_model:\n- DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU\n---\n\n<font color="red">Important: This is the first fine tune to exceed 730 "arc-c" ("735": 144 pts higher than Qwen 3.8 27B) AND 880 ARC-E (The OpenAI, Claude and Gemini "zone of intelligence") \nin 8 bit and over 718 arc-c in 4 bit. This version is called TURBO because it drastically reduces thinking tokens (by 1/2 to as high as 1/10), yet maintains output detail and quality. \nIn otherwords while "reg" Qwen3.8 27B is thinking about "formatting" for a few 1000 tokens, this model is already done and waiting for more.\nThis repo contains both "regular" and "MTP" Neo-CODER MAX DI-MATRIX (duel imatrix) GGUF quants. \n\nNOTE: Please see the "community" tab for user experiences, additional third party benchmarks (including strongest tool calling performance ever recorded), \nand other quant versions (also see "Quantized" in the right "model tree" too).\n\nQwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
\n\n<img src="star-wars-hans-solo.gif" style="float:right; padding:10px;">\n\nThe strongest, smartest open source multi-stage model fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth.\n\nThe first model of this size/type to breach "730" ARC-C in 8 bit (735) and 4 bit (719); hench the "735" in the name.\n\nThis model has 1/5 (as low as 1/10 in some cases) to 1/2 the thinking tokens (vs reg Qwen 3.8) across all 3 ", "params_total": null}, {"id": "unsloth/Qwen3.8-27B-GGUF", "pipeline_tag": null, "downloads": 7118363, "likes": 4373, "last_modified": "2026-08-20T12:04:25.000Z", "tags": ["gguf", "qwen3_5", "unsloth", "base_model:Qwen/Qwen3.8-27B", "base_model:quantized:Qwen/Qwen3.8-27B", "license:apache-2.0", "endpoints_compatible", "region:us", "imatrix", "conversational"], "readme": "---\nbase_model:\n- Qwen/Qwen3.8-27B\nlicense: apache-2.0\ntags:\n- unsloth\n---\n\n# Read our How to Run Qwen3.8-27B Guide!\n\n <p style="margin: 0 0 0px 0; margin-top: 0px;">\n
<a href="https://unsloth.ai/docs/basics/dynamic-3.0-ggufs">Unsloth Dynamic 3.0 achieves superior accuracy & outperforms other leading quants.\n
\n <div style="display: flex; gap: 5px; align-items: center; margin-bottom: 0px;">\n <a href="https://github.com/unslothai/unsloth/">\n <img src="https://github.com/unslothai/unsloth/raw/main/images/unsloth%20new%20logo.png" width="133">\n \n <a href="https://discord.gg/unsloth">\n <img src="https://github.com/unslothai/unsloth/raw/main/images/Discord%20button.png" width="173">\n \n <a href="https://unsloth.ai/docs/models/qwen3.8">\n <img src="https://raw.githubusercontent.com/unslothai/unsloth/refs/heads/main/images/documentation%20green%20button.png" width="143">\n \n
/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FSqxs6NjShWrLfRKhDy1m%2Fvolcano%202.gif?alt=media&token=395274a0-b437-403a-8a01-8e8502f9d", "params_total": null}, {"id": "openbmb/MiniCPM5-2B", "pipeline_tag": "text-generation", "downloads": 389555, "likes": 1589, "last_modified": "2026-09-12T07:20:14.000Z", "tags": ["transformers", "safetensors", "llama", "text-generation", "minicpm", "minicpm5", "long-context", "tool-calling", "on-device", "edge-ai"], "readme": "---\nlicense: apache-2.0\nlanguage:\n- en\n- zh\nlibrary_name: transformers\npipeline_tag: text-generation\ntags:\n- minicpm\n- minicpm5\n- llama\n- text-generation\n- long-context\n- tool-calling\n- on-device\n- edge-ai\ndatasets:\n- openbmb/Ultra-FineWeb\n- openbmb/UltraX-Preview\n- openbmb/Ultra-FineWeb-L3\n- openbmb/UltraData-Math\n- openbmb/UltraData-Code\n- openbmb/UltraData-SFT-2605\n- openbmb/UltraData-SFT-Agent-2609\n- openbmb/UltraData-RL-2609\n---\n\n<div align="center">\n<img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM/main/assets/minicpm_logo.png" width="500em" />\n\n\n<p align="center">\n<a href="https://arxiv.org/pdf/2506.07900" target="_blank">MiniCPM Tech Report |\n<a href="https://modelbest.feishu.cn/wiki/UtWxwcERfiRIpIkBOjuc3h9tn1D" target="_blank">MiniCPM Wiki(Chinese) |\n<a href="https://github.com/OpenBMB/MiniCPM" target="_blank">GitHub Repo |\n<a href="https://ultradata.openbmb.cn/" target="_blank">UltraData |\n<a href="https://huggingface.co/spaces/openbmb/MiniCPM5-2B-Demo" target="_blank">Online Demo\n
\n\n<p align="center">\nEnglish |\n<a href="https://huggingface.co/openbmb/MiniCPM5-2B/blob/main/README-cn.md" target="_blank">中文\n
\n\n## Highlights\n\nWe are releasing
MiniCPM5-2B, the second model in the
MiniCPM5 series, following
MiniCPM5-1B. It is a dense 2B Transformer that scales up the same training recipe, built for on-device, local deployment, and resource-constrained scenarios, reaching 2B-class open-source SOTA.\n\n🏆
2B-class open-source SOTA: compared with strong open-source models of similar size, MiniCPM5-2B achieves SOTA performance within this comparison set. It remains competitive with 4B-class models overall, while showing its advantages over models of comparable size in coding, mathematics, long-context understanding, tool use, and agentic tasks.\n\n<div id="capability-comparison-radar" class="radar-visual" role="img" aria-label="Capability radar chart comparing MiniCPM", "params_total": null}, {"id": "ukisai/Swift-Qwen3.8-27B-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 120740, "likes": 306, "last_modified": "2026-09-16T15:17:31.000Z", "tags": ["gguf", "llama.cpp", "qwen3_8", "qwen3_5", "efficient-thinking", "reasoning", "token-efficient", "image-text-to-text", "base_model:ukisai/Swift-Qwen3.8-27b", "base_model:quantized:ukisai/Swift-Qwen3.8-27b"], "readme": "---\nlicense: other\nlicense_name: swift-open-license-1.0\nlicense_link: https://huggingface.co/ukisai/Swift-Qwen3.8-27b#license-and-access\nbase_model: ukisai/Swift-Qwen3.8-27b\nbase_model_relation: quantized\npipeline_tag: image-text-to-text\nlibrary_name: gguf\ntags:\n- gguf\n- llama.cpp\n- qwen3_8\n- qwen3_5\n- efficient-thinking\n- reasoning\n- token-efficient\n---\n\n<div align="center">\n <a href="https://ukisai.com"><img src="ukisai-banner.png" alt="UkisAI" style="width:100%;max-width:100%;height:auto;display:block;margin-bottom:0.6em;" />\n <div style="display:flex;justify-content:center;gap:0.6em;margin-bottom:1em;">\n <a href="https://ukisai.com">
Website • \n <a href="https://ukisai.com/products/swift">
Learn more • \n <a href="https://huggingface.co/ukisai/Swift-Qwen3.8-27b">
BF16 model • \n <a href="#license-and-access">
Enterprise licensing\n \n\n\n# Swift-Qwen3.8-27B GGUF\n\nSwift-Qwen3.8-27B is UkisAI's reasoning-efficient derivative of Qwen3.8-27B,\nusing
58.3% fewer thinking tokens while maintaining near-identical performance\n(
<1% loss) and as a result getting a
x1.95 speed-up on several tasks.\n\n<video controls autoplay muted loop playsinline style="width:100%;max-width:100%;height:auto;display:block;border-radius:12px;margin:0.8em 0 1.4em;" src="https://huggingface.co/ukisai/Swift-Qwen3.8-27B-GGUF/resolve/main/swift-speed-demo.mp4">\n<p align="center" style="font-size:13px;color:#8C94A8;margin:-0.6em 0 1.4em;">The prompt is a sample from LiveCodeBench v6
\n\n<style>\n.swift-table { width:100%; table-layout:fixed; border-collapse:separate; border-spacing:0; overflow:hidden; border:1px solid #27344A; border-radius:20px; background:#0D111B; font-family:-apple-system,BlinkMacSystemFont,"Segoe UI",Roboto,sans-serif; font-size:14px; color:#BFBDBD; }\n.swift-table th { padding:13px 8px; text-align:center; f", "params_total": null}, {"id": "Qwen/Qwen3.8-Flash-Next", "pipeline_tag": "image-text-to-text", "downloads": 742586, "likes": 5446, "last_modified": "2026-08-27T05:03:36.000Z", "tags": ["transformers", "safetensors", "qwen4_exp", "image-text-to-text", "conversational", "license:other", "eval-results", "endpoints_compatible", "region:us"], "readme": "---\nlibrary_name: transformers\nlicense: other\nlicense_name: qwen-community-1.0\nlicense_link: LICENSE\npipeline_tag: image-text-to-text\n---\n\n# Qwen3.8-Flash-Next\n\n> [!Note]\n> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. \n>\n> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.\n\n> [!Tip]\n> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by
Qwen Cloud.\n>\n> In particular,
Qwen3.8-Flash is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the
Qwen3.8-Flash Overview.\n\n\nAs the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. \n\n
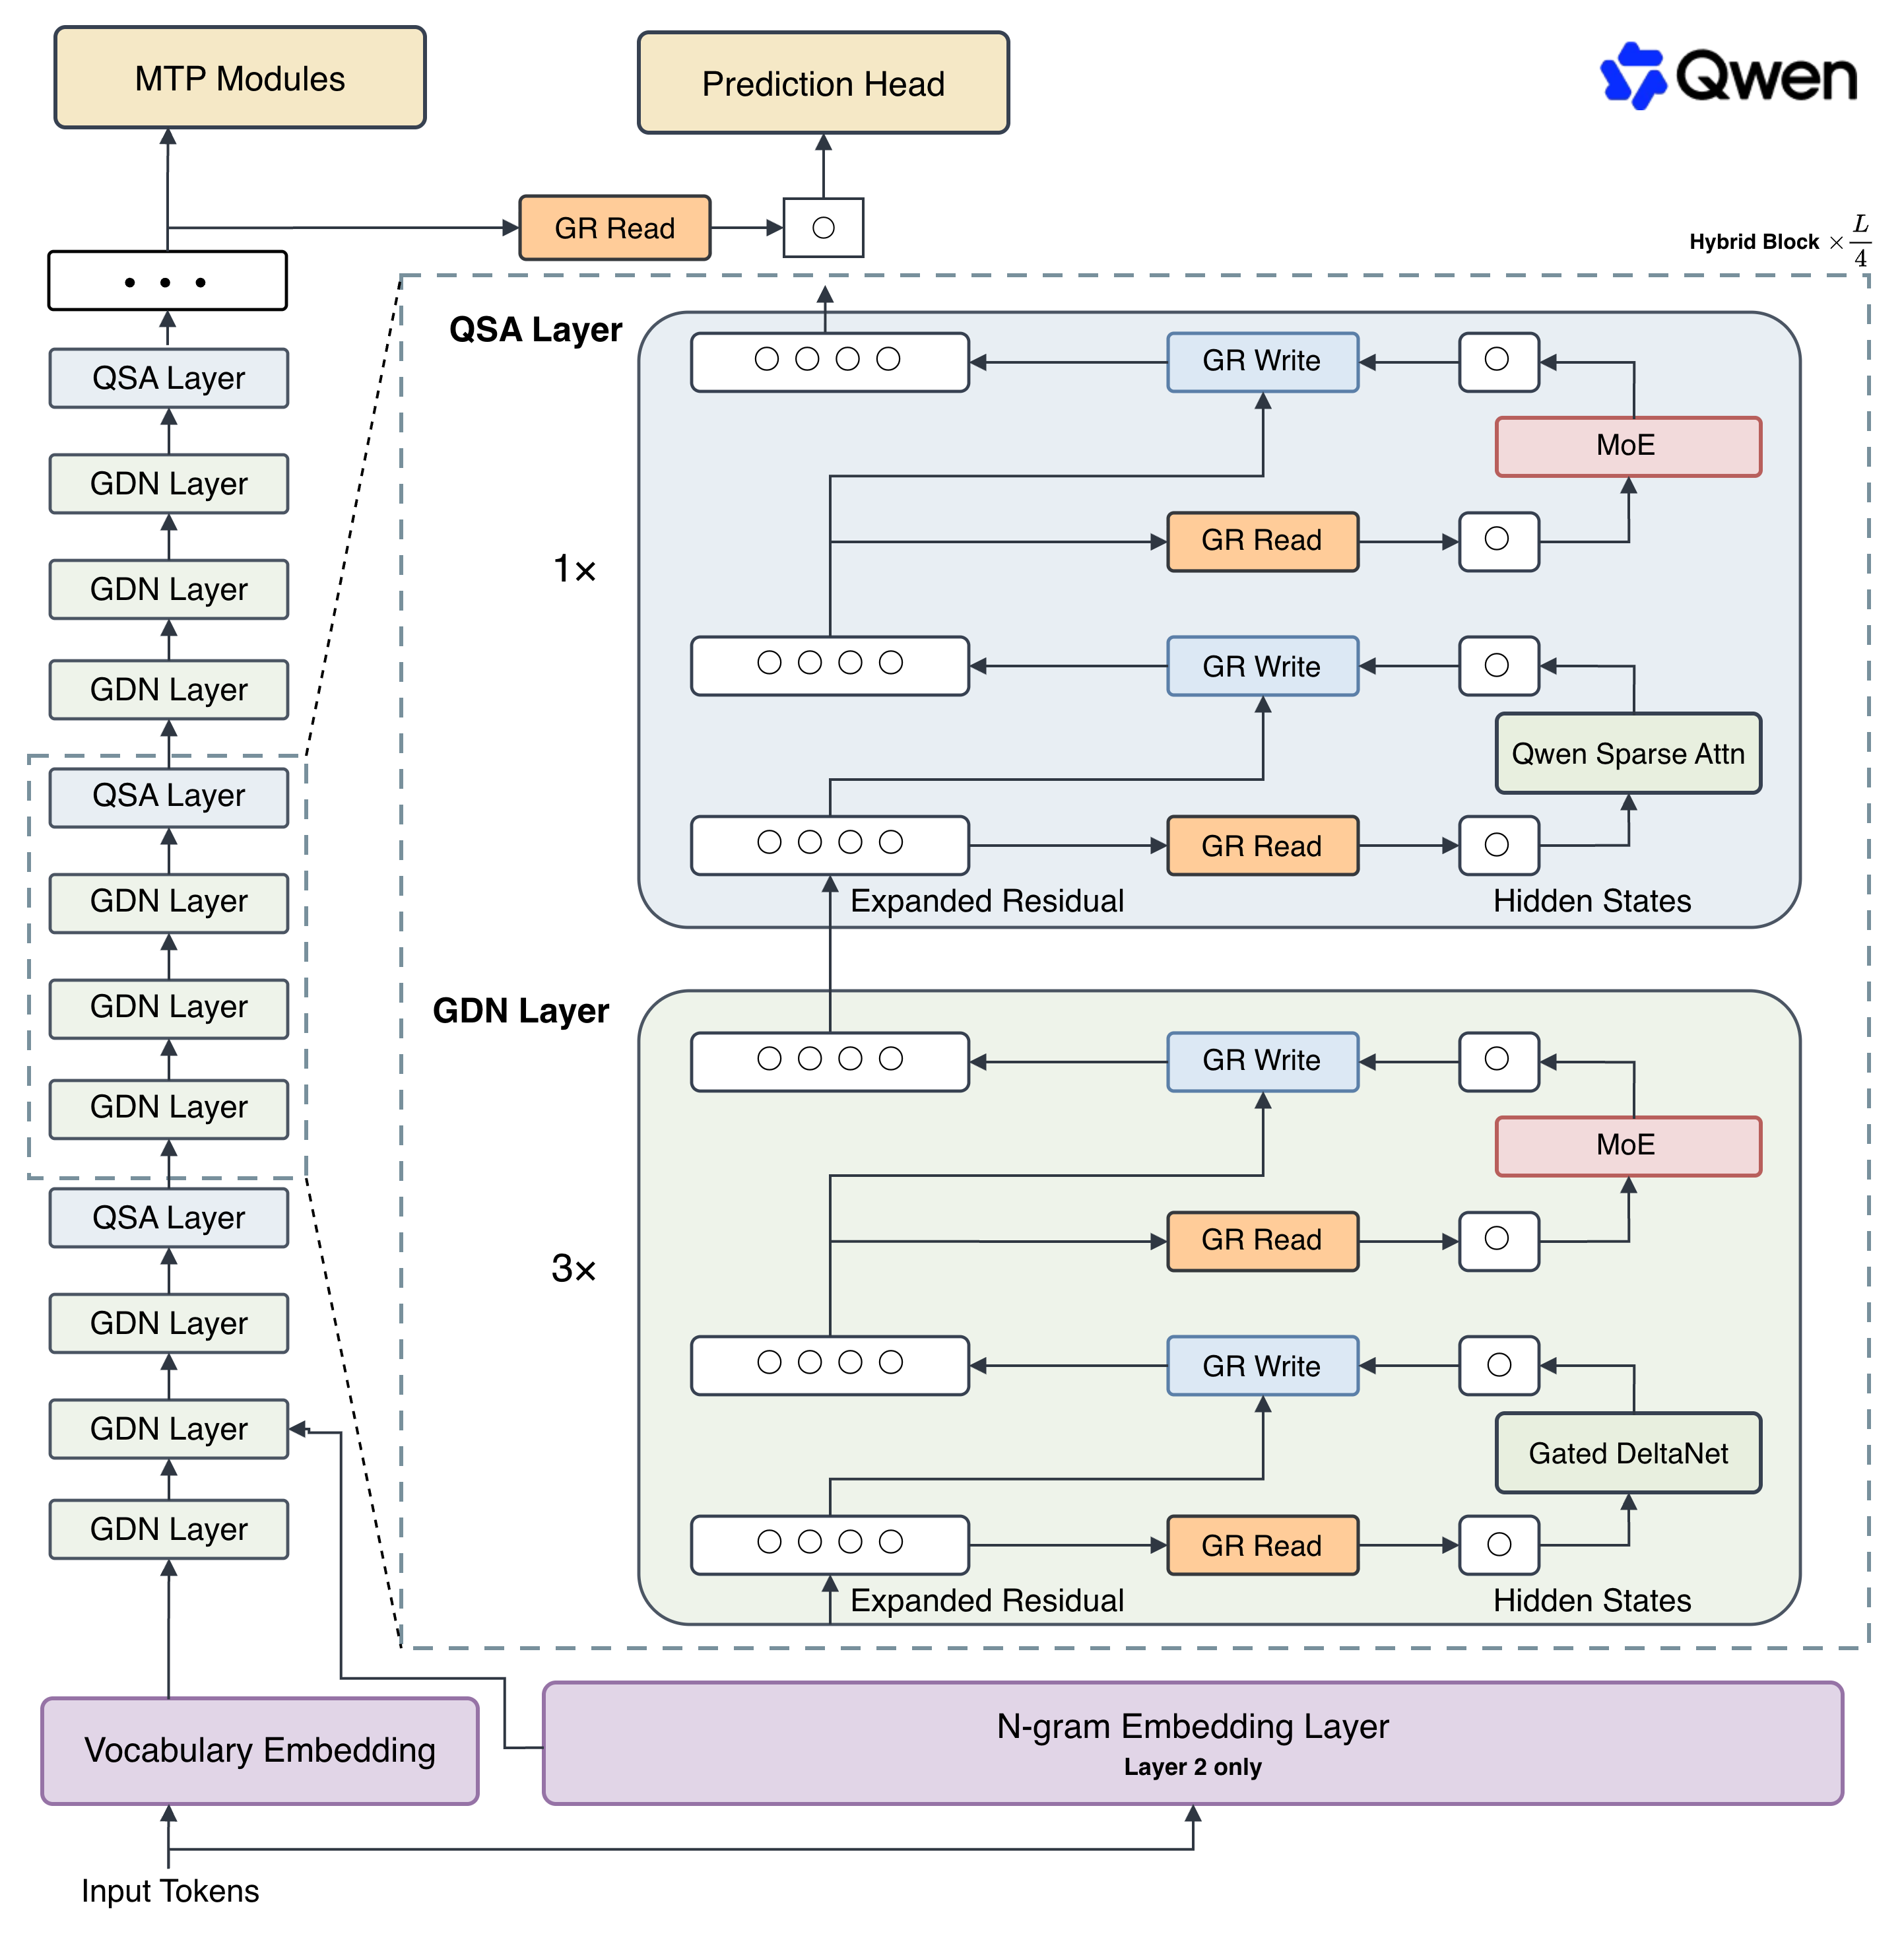
\n\nThis experimental preview of the architecture that will underpin Qwen4 is built around a fundamental rethinking of how the core components of modern large language models (LLMs) interact at scale.\n \n## Highlights\n\nThe first open-weight release under this architecture is Qwen3.8-Flash-Next, which introduces:\n\n-
Hybrid Attention with QSA: The Gated DeltaNet and Gated Attention pairing has been reworked into Gated DeltaNet and Qwen Sparse Attention (QSA). Rather than selecting individual tokens for processing, QSA operates at the micro-block level. This cuts long-context latency signifi", "params_total": null}]}
{"fetchedAt": "2026-09-20T00:12:14.647861Z", "models": [{"id": "prism-ml/Ternary-Bonsai-2-27B-gguf", "pipeline_tag": "text-generation", "downloads": 1516960, "likes": 1200, "last_modified": "2026-09-17T18:44:01.000Z", "tags": ["llama.cpp", "gguf", "ternary", "2-bit", "llama-cpp", "cuda", "metal", "on-device", "hybrid-attention", "prismml"], "readme": "---\nlicense: apache-2.0\nlibrary_name: llama.cpp\npipeline_tag: text-generation\ntags:\n- ternary\n- 2-bit\n- gguf\n- llama-cpp\n- cuda\n- metal\n- on-device\n- hybrid-attention\n- prismml\n- bonsai\nbase_model:\n- Qwen/Qwen3.8-27B\n---\n\n<p align="center">\n <img src="./assets/bonsai-logo.svg" width="280" alt="Bonsai">\n
\n\n<p align="center">\n <a href="https://prismml.com">Prism ML Website | \n <a href="https://github.com/PrismML-Eng/Bonsai-demo/blob/main/bonsai-2-27b-whitepaper.pdf">Whitepaper | \n <a href="https://github.com/PrismML-Eng/Bonsai-demo">Demo & Examples | \n <a href="https://discord.gg/prismml">Discord\n\n\n# Bonsai 2 27B — GGUF\n\nFull 27B-class reasoning in ternary transformer weights, for llama.cpp (CUDA, Metal, CPU)\n\n> \~9.3x smaller than FP16 (ideal) | 98.2% of FP16 intelligence retained | \~47 tok/s on an Apple M5 Max laptop\n\n## Highlights\n\n- \~5.9 GB language model (down from \~54 GB FP16) — full 27B-class reasoning on a standard laptop or a single GPU\n- 98.2% of FP16 intelligence retained: 84.78 average across 14 thinking-mode benchmarks — far above the conventional IQ2_XXS build (72.59) at less than two-thirds of its footprint, and within 0.4 points of UD-Q4_K_XL at three times the footprint\n- Retains thinking, reasoning, and agentic behavior deep in the sub-4-bit regime, where conventional low-bit representations collapse: math within half a point of full precision (96.57), coding level with the baseline (89.42), agentic tool calling at 74.92\n- End-to-end ternary language weights across embeddings, attention projections, MLP projections, and LM head, at a true 1.72 bits per weight — no high-precision escape hatches behind a low-bit label; the vision tower ships as a separate Q8_0 mmproj pack\n- 262K-token context on-device, kept practical by the Qwen3.8-27B hybrid-attention backbone (\~75% linear attention)\n- Two GGUF packings with custom te", "params_total": null}, {"id": "deepseek-ai/DeepSeek-V4.1-Flash", "pipeline_tag": "image-text-to-text", "downloads": 482270, "likes": 3299, "last_modified": "2026-09-10T08:18:10.000Z", "tags": ["transformers", "safetensors", "deepseek_v41", "text-generation", "image-text-to-text", "license:mit", "eval-results", "endpoints_compatible", "8-bit", "fp8"], "readme": "---\nlicense: mit\nlibrary_name: transformers\npipeline_tag: image-text-to-text\n---\n\n# DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression\n\n\n\n\n\n<div align="center">\n <img src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/logo.svg?raw=true" width="60%" alt="DeepSeek-V4.1" />\n\n\n<div align="center" style="line-height: 1;">\n <a href="https://www.deepseek.com/" target="_blank" style="margin: 2px;">\n <img alt="Homepage" src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/badge.svg?raw=true" style="display: inline-block; vertical-align: middle;"/>\n \n <a href="https://chat.deepseek.com/" target="_blank" style="margin: 2px;">\n <img alt="Chat" src="https://img.shields.io/badge/🤖%20Chat-DeepSeek%20V4.1-536af5?color=536af5&logoColor=white" style="display: inline-block; vertical-align: middle;"/>\n \n\n<div align="center" style="line-height: 1;">\n <a href="https://huggingface.co/deepseek-ai" target="_blank" style="margin: 2px;">\n <img alt="Hugging Face" src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-DeepSeek%20AI-ffc107?color=ffc107&logoColor=white" style="display: inline-block; vertical-align: middle;"/>\n \n <a href="https://twitter.com/deepseek_ai" target="_blank" style="margin: 2px;">\n <img alt="Twitter Follow" src="https://img.shields.io/badge/Twitter-deepseek_ai-white?logo=x&logoColor=white" style="display: inline-block; vertical-align: middle;"/>\n \n\n<div align="center" style="line-height: 1;">\n <a href="LICENSE" style="margin: 2px;">\n <img alt="License" src="https://img.shields.io/badge/License-MIT-f5de53?&color=f5de53" style="display: inline-block; vertical-align: middle;"/>\n \n\n\n<p align="center">\n <a href="https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf">Technical Report", "params_total": null}, {"id": "Qwen/Qwen3.8-27B", "pipeline_tag": "image-text-to-text", "downloads": 7365368, "likes": 15759, "last_modified": "2026-08-14T15:00:01.000Z", "tags": ["transformers", "safetensors", "qwen3_5", "image-text-to-text", "conversational", "license:apache-2.0", "eval-results", "endpoints_compatible", "deploy:azure", "deploy:sagemaker"], "readme": "---\r\nlibrary_name: transformers\r\nlicense: apache-2.0\r\npipeline_tag: image-text-to-text\r\n---\r\n\r\n# Qwen3.8-27B\r\n\r\n> [!Note]\r\n> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. \r\n>\r\n> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.\r\n\r\n> [!Tip]\r\n> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud.\r\n> In particular, Qwen3.8-27B will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates.\r\n\r\nFollowing the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date.\r\n\r\nBuilt on the architectural foundation of Qwen3.5, Qwen3.8 delivers substantial gains across coding, professional work, research, and long-horizon agentic tasks. Qwen3.8-27B brings these advances to a compact, deployment-friendly dense model: a native vision-language model that understands images and videos, with flexible thinking control, designed to carry complex, multi-step tasks through to completion with greater reliability.\r\n\r\n## Qwen3.8 Highlights\r\n\r\nQwen3.8-27B features the following enhancements:\r\n- Core Capabilities: Comprehensive improvements across coding, professional work, research, and long-horizon agentic tasks.\r\n- Agent Execution: Stronger autonomous planning and better handling of environment feedback, leading to more reliable end-to-end task completion.\r\n- Downstream Compatibility: Broader support for popular harnesses and development tools, making it easier to integrate into your existing stack.\r\n- ", "params_total": null}, {"id": "XingChen-AGI/Xing4.0-29B-A4B", "pipeline_tag": "text-generation", "downloads": 7278, "likes": 628, "last_modified": "2026-09-18T09:49:55.000Z", "tags": ["transformers", "safetensors", "xing4_0", "text-generation", "conversational", "custom_code", "arxiv:2512.24157", "arxiv:2507.18013", "license:apache-2.0", "region:us"], "readme": "---\nlibrary_name: transformers\nlicense: apache-2.0\npipeline_tag: text-generation\n---\n\n# Xing4.0-29B-A4B\n\n> [!Note]\n> This repository provides the model weights and configuration files for Xing4.0-29B-A4B in Hugging Face Transformers format, compatible with Transformers, vLLM, SGLang, KTransformers, and other mainstream inference frameworks.\n\nXing4.0-29B-A4B is a next-generation large language model in the Xing series (formerly TeleChat), developed by China Telecom Artificial Intelligence Technology Co., Ltd. With 29B total parameters and only 4B activated per token, it natively supports a 256K context length, extensible to 512K. It is the first model of this scale trained entirely on the Ascend NPU platform with the MindSpore framework, and deeply optimized for complex engineering tasks.\n\nFor more information, please refer to our GitHub repository.\n\n\n## Highlights\n\n- Agent-Oriented Architecture: Built on the mHC + MLA + MTP architecture, supporting multi-step planning, tool calling, and complex reasoning chain execution, ensuring task coherence and execution stability under long contexts.\n- Deep Co-optimization with Ascend NPU: Adapted for Ascend 910C clusters using MindSpore/MindFormers, including feature adaptation for mHC and fused operator development, enabling stable and efficient training on the Ascend platform.\n- Significant Training Efficiency Gains: Through multi-level co-optimization — including fine-grained MoE communication optimization, selective recomputation, DVM automatic graph-operator fusion, and Ascend C mHC fused operators — overall training throughput was improved by approximately 96% over out-of-the-box performance.\n- Full Open-Source Ecosystem Compatibility: Supports LLaMA-Factory and MindFormers for fine-tuning; SGLang, vLLM, and KTransformers for inference and deployment; with targeted adaptation and format alignment for agent f", "params_total": null}, {"id": "m-a-p/YuE2-3B", "pipeline_tag": "text-to-audio", "downloads": 15446, "likes": 871, "last_modified": "2026-09-16T08:38:56.000Z", "tags": ["safetensors", "yue2", "music-generation", "symbolic-planning", "agentic-editing", "custom_code", "text-to-audio", "zh", "en", "arxiv:2503.08638"], "readme": "---\nlicense: cc-by-nc-4.0\nlanguage:\n- zh\n- en\npipeline_tag: text-to-audio\ntags:\n- music-generation\n- symbolic-planning\n- agentic-editing\n- custom_code\n---\n<p align="center">\n <img src="assets/logo.png" alt="YuE logo" width="144" />\n\n<h1 align="center">🤗 YuE2-3B\n<p align="center">Frontier music generation with editable scores\n\n<p align="center">\n <a href="https://github.com/multimodal-art-projection/YuE"><img alt="GitHub" src="https://img.shields.io/badge/GitHub-YuE-181717?logo=github&logoColor=white" height="20" />\n \n <a href="https://discord.gg/ssAyWMnMzu"><img alt="Join Discord" src="https://img.shields.io/discord/842440537755353128?label=Discord&color=5865F2&logo=discord&logoColor=white" height="20" />\n\n<p align="center">\n <a href="https://map-yue2.github.io/">🎧 Demo\n ·\n <a href="https://arena.3-148-255-99.sslip.io:8080">🗳️ Music Arena\n ·\n <a href="#quick-start">🚀 Quick start\n ·\n <a href="#cover-an-existing-song">🎙️ Cover\n ·\n <a href="#export-a-plan-edit-it-and-generate">🤖 Edit\n ·\n <a href="#speed-and-resources" title="Speed and resources">⚡ Speed\n ·\n <a href="#benchmarks">📊 Benchmarks\n ·\n <a href="#citation">📚 Citation\n\n<p align="center">\n <a href="https://huggingface.co/m-a-p/YuE2-3B"><img alt="🤗 YuE2-3B" src="https://img.shields.io/badge/YuE2--3B-374151?logo=huggingface&logoColor=FFD21E" height="20" />\n \n <a href="https://huggingface.co/m-a-p/YuE2-Vae"><img alt="🤗 YuE2-Vae" src="https://img.shields.io/badge/YuE2--Vae-374151?logo=huggingface&logoColor=FFD21E" height="20" />\n \n <a href="https://huggingface.co/m-a-p/YuE2-Vae-legacy"><img alt="🤗 YuE2-Vae-legacy" src="https://img.shields.io/badge/YuE2--Vae--legacy-374151?logo=huggingface&logoColor=FFD21E" height="20" />\n \n <a href="https://huggingface.co/m-a-p/MERT-v2-30s"><img alt="🤗 MERT-v2-30s" src", "params_total": null}, {"id": "convaiinnovations/laya", "pipeline_tag": "text-classification", "downloads": 0, "likes": 520, "last_modified": "2026-09-19T09:53:44.000Z", "tags": ["transformers", "safetensors", "laya", "system-one", "calibrated-decisions", "rlcd", "classification", "routing", "scoring", "guardrails"], "readme": "---\nlicense: apache-2.0\nlibrary_name: transformers\npipeline_tag: text-classification\ntags:\n- laya\n- system-one\n- calibrated-decisions\n- rlcd\n- classification\n- routing\n- scoring\n- guardrails\n- moderation\n- reinforcement-learning\n- commercial-use\n---\n\n<p align="center">\n <img src="assets/logo-lockup.png" alt="Laya" width="330" />\n\n\nMultilingual, non-autoregressive System 1 decision model. Give it a state (text, email,\nticket, or JSON) and typed questions; it returns typed answers with probabilities in a\nsingle forward pass — 33 ms — across 100+ languages. Trained with reinforcement learning against\nstrictly proper scoring rules (RLCD), so reporting honest probabilities is the only way to\nmaximise reward. It never generates text, so there is nothing to parse and nothing to\nhallucinate.\n\n<p align="center">\n <img src="assets/laya_vs_jev_full.png" alt="Laya versus TypeSafe Jev: accuracy, every application workflow, all 51 languages, speed, calibration and routing cost" width="100%" />\n\n\nThis repo holds all three checkpoints and is the hub for the family. The English checkpoint\nis at the repo root; the other two are subfolders, and only the one you ask for is downloaded:\n\n
python\nimport laya\n\nlaya.load(\"convaiinnovations/laya\") # English\nlaya.load(\"convaiinnovations/laya\", subfolder=\"multilingual\") # 100+ languages\nlaya.load(\"convaiinnovations/laya\", subfolder=\"typed-decisions\")\n\n\n| checkpoint | encoder | params | context | use it for |\n|---|---|---|---|---|\n|convaiinnovations/laya(this repo) | ModernBERT-large | 421M | 512 | English |\n|convaiinnovations/laya-multilingual| mmBERT-base | 322M | 1024 | 100+ languages,2x faster |\n| \n
 \n
 \n
 \n
 \n
 \n\n\n\n and as a result getting a x1.95 speed-up on several tasks.\n\n<video controls autoplay muted loop playsinline style="width:100%;max-width:100%;height:auto;display:block;border-radius:12px;margin:0.8em 0 1.4em;" src="https://huggingface.co/ukisai/Swift-Qwen3.8-27b/resolve/main/swift-speed-demo.mp4">\n<p align="center" style="font-size:13px;color:#8C94A8;margin:-0.6em 0 1.4em;">The prompt is a sample from LiveCodeBench v6\n\n## Training approach\n\nWe built Swift by identifying reasoning-marker tokens that, in our analysis, trigger overthinking in Qwen’s\nreasoning rollouts. We then fine-tuned Qwen by penalizing usage of those tokens while it reasons.\n\nSwift produces shorter reasoning traces. In our testing, we also observe fewer overthinking errors.\n\nFor maximum gains, Swift also includes ", "params_total": null}, {"id": "harshatheg/Qwen-2.5-1B-RLCD", "pipeline_tag": "text-generation", "downloads": 0, "likes": 425, "last_modified": "2026-09-16T06:23:02.000Z", "tags": ["mlx", "structured-generation", "parallel-decoding", "constrained-decoding", "apple-silicon", "classification", "json", "text-generation", "en", "base_model:Qwen/Qwen2.5-1.5B-Instruct"], "readme": "---\nlanguage:\n- en\nlicense: apache-2.0\nlibrary_name: mlx\ntags:\n- structured-generation\n- parallel-decoding\n- constrained-decoding\n- apple-silicon\n- mlx\n- classification\n- json\npipeline_tag: text-generation\nbase_model: Qwen/Qwen2.5-1.5B-Instruct\nspaces:\n- drinkmoonshine/parallel-constrained-decoding\n---\n\n# Parallel Constrained Decoding for Apple Silicon\n\n
 \n\n> Live Demo: Try the side-by-side comparison live on Hugging Face Spaces: drinkmoonshine/parallel-constrained-decoding.\n\nA high-throughput inference engine for structured information extraction, decision routing, and categorical classification on Apple Silicon using MLX.\n\nParallel Constrained Decoding evaluates multi-field JSON schemas simultaneously rather than generating tokens sequentially. On an Apple Silicon M4 Max, it delivers 5.6x to 7.0x latency reductions compared to standard autoregressive decoding with 100% schema validity and calibrated field-level confidence scores.\n\n---\n\n## Performance Benchmarks (Apple Silicon M4 Max)\n\nEvaluated with
\n <p style="margin: 0 0 0px 0; margin-top: 0px;">\n <a href="https://unsloth.ai/docs/basics/dynamic-3.0-ggufs">Unsloth Dynamic 3.0 achieves superior accuracy & outperforms other leading quants.\n \n <div style="display: flex; gap: 5px; align-items: center; margin-bottom: 0px;">\n <a href="https://github.com/unslothai/unsloth/">\n <img src="https://github.com/unslothai/unsloth/raw/main/images/unsloth%20new%20logo.png" width="133">\n \n <a href="https://discord.gg/unsloth">\n <img src="https://github.com/unslothai/unsloth/raw/main/images/Discord%20button.png" width="173">\n \n <a href="https://unsloth.ai/docs/models/qwen3.8">\n <img src="https://raw.githubusercontent.com/unslothai/unsloth/refs/heads/main/images/documentation%20green%20button.png" width="143">\n \n \n <ul style="margin: 0;">\n Introducing <a href="https://unsloth.ai/docs/basics/dynamic-3.0-ggufs">Dynamic V3.0 GGUFs for SOTA accuracy and quantization performance \n Run and fine-tune Qwen3.8 in <a href="https://unsloth.ai/docs/new/desktop">Unsloth Desktop with Thinking toggles. <a href="https://unsloth.ai">Download for Mac, Windows and Linux. <a href="github.com/unslothai/unsloth">GitHub repo \n Developer Role Support so Qwen3.8 can work in agentic tools like Codex and more! \n Tool calling improvements: Makes parsing nested objects to make tool calling succeed more. \n See below for 4-bit Qwen3.8-27B run inside of Unsloth Desktop: \n\n\n<img width="600" alt="qwen3.8 unsloth desktop" src="https://3215535692-files.gitbook.io//files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FSqxs6NjShWrLfRKhDy1m%2Fvolcano%202.gif?alt=media&token=395274a0-b437-403a-8a01-8e8502f9d", "params_total": null}, {"id": "openbmb/MiniCPM5-2B", "pipeline_tag": "text-generation", "downloads": 389555, "likes": 1589, "last_modified": "2026-09-12T07:20:14.000Z", "tags": ["transformers", "safetensors", "llama", "text-generation", "minicpm", "minicpm5", "long-context", "tool-calling", "on-device", "edge-ai"], "readme": "---\nlicense: apache-2.0\nlanguage:\n- en\n- zh\nlibrary_name: transformers\npipeline_tag: text-generation\ntags:\n- minicpm\n- minicpm5\n- llama\n- text-generation\n- long-context\n- tool-calling\n- on-device\n- edge-ai\ndatasets:\n- openbmb/Ultra-FineWeb\n- openbmb/UltraX-Preview\n- openbmb/Ultra-FineWeb-L3\n- openbmb/UltraData-Math\n- openbmb/UltraData-Code\n- openbmb/UltraData-SFT-2605\n- openbmb/UltraData-SFT-Agent-2609\n- openbmb/UltraData-RL-2609\n---\n\n<div align="center">\n<img src="https://raw.githubusercontent.com/OpenBMB/MiniCPM/main/assets/minicpm_logo.png" width="500em" />\n\n\n<p align="center">\n<a href="https://arxiv.org/pdf/2506.07900" target="_blank">MiniCPM Tech Report |\n<a href="https://modelbest.feishu.cn/wiki/UtWxwcERfiRIpIkBOjuc3h9tn1D" target="_blank">MiniCPM Wiki(Chinese) |\n<a href="https://github.com/OpenBMB/MiniCPM" target="_blank">GitHub Repo |\n<a href="https://ultradata.openbmb.cn/" target="_blank">UltraData |\n<a href="https://huggingface.co/spaces/openbmb/MiniCPM5-2B-Demo" target="_blank">Online Demo\n\n\n<p align="center">\nEnglish |\n<a href="https://huggingface.co/openbmb/MiniCPM5-2B/blob/main/README-cn.md" target="_blank">中文\n\n\n## Highlights\n\nWe are releasing MiniCPM5-2B, the second model in the MiniCPM5 series, following MiniCPM5-1B. It is a dense 2B Transformer that scales up the same training recipe, built for on-device, local deployment, and resource-constrained scenarios, reaching 2B-class open-source SOTA.\n\n🏆 2B-class open-source SOTA: compared with strong open-source models of similar size, MiniCPM5-2B achieves SOTA performance within this comparison set. It remains competitive with 4B-class models overall, while showing its advantages over models of comparable size in coding, mathematics, long-context understanding, tool use, and agentic tasks.\n\n<div id="capability-comparison-radar" class="radar-visual" role="img" aria-label="Capability radar chart comparing MiniCPM", "params_total": null}, {"id": "ukisai/Swift-Qwen3.8-27B-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 120740, "likes": 306, "last_modified": "2026-09-16T15:17:31.000Z", "tags": ["gguf", "llama.cpp", "qwen3_8", "qwen3_5", "efficient-thinking", "reasoning", "token-efficient", "image-text-to-text", "base_model:ukisai/Swift-Qwen3.8-27b", "base_model:quantized:ukisai/Swift-Qwen3.8-27b"], "readme": "---\nlicense: other\nlicense_name: swift-open-license-1.0\nlicense_link: https://huggingface.co/ukisai/Swift-Qwen3.8-27b#license-and-access\nbase_model: ukisai/Swift-Qwen3.8-27b\nbase_model_relation: quantized\npipeline_tag: image-text-to-text\nlibrary_name: gguf\ntags:\n- gguf\n- llama.cpp\n- qwen3_8\n- qwen3_5\n- efficient-thinking\n- reasoning\n- token-efficient\n---\n\n<div align="center">\n <a href="https://ukisai.com"><img src="ukisai-banner.png" alt="UkisAI" style="width:100%;max-width:100%;height:auto;display:block;margin-bottom:0.6em;" />\n <div style="display:flex;justify-content:center;gap:0.6em;margin-bottom:1em;">\n <a href="https://ukisai.com">Website • \n <a href="https://ukisai.com/products/swift">Learn more • \n <a href="https://huggingface.co/ukisai/Swift-Qwen3.8-27b">BF16 model • \n <a href="#license-and-access">Enterprise licensing\n \n\n\n# Swift-Qwen3.8-27B GGUF\n\nSwift-Qwen3.8-27B is UkisAI's reasoning-efficient derivative of Qwen3.8-27B,\nusing 58.3% fewer thinking tokens while maintaining near-identical performance\n(<1% loss) and as a result getting a x1.95 speed-up on several tasks.\n\n<video controls autoplay muted loop playsinline style="width:100%;max-width:100%;height:auto;display:block;border-radius:12px;margin:0.8em 0 1.4em;" src="https://huggingface.co/ukisai/Swift-Qwen3.8-27B-GGUF/resolve/main/swift-speed-demo.mp4">\n<p align="center" style="font-size:13px;color:#8C94A8;margin:-0.6em 0 1.4em;">The prompt is a sample from LiveCodeBench v6\n\n<style>\n.swift-table { width:100%; table-layout:fixed; border-collapse:separate; border-spacing:0; overflow:hidden; border:1px solid #27344A; border-radius:20px; background:#0D111B; font-family:-apple-system,BlinkMacSystemFont,"Segoe UI",Roboto,sans-serif; font-size:14px; color:#BFBDBD; }\n.swift-table th { padding:13px 8px; text-align:center; f", "params_total": null}, {"id": "Qwen/Qwen3.8-Flash-Next", "pipeline_tag": "image-text-to-text", "downloads": 742586, "likes": 5446, "last_modified": "2026-08-27T05:03:36.000Z", "tags": ["transformers", "safetensors", "qwen4_exp", "image-text-to-text", "conversational", "license:other", "eval-results", "endpoints_compatible", "region:us"], "readme": "---\nlibrary_name: transformers\nlicense: other\nlicense_name: qwen-community-1.0\nlicense_link: LICENSE\npipeline_tag: image-text-to-text\n---\n\n# Qwen3.8-Flash-Next\n\n> [!Note]\n> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. \n>\n> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.\n\n> [!Tip]\n> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud.\n>\n> In particular, Qwen3.8-Flash is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview.\n\n\nAs the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. \n\nconvaiinnovations/laya-typed-decisions| ModernBERT-large | 421M | 1024 | the typed-decisions workflows |\n\n| question type | returns |\n|---|---", "params_total": null}, {"id": "ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 1154265, "likes": 1417, "last_modified": "2026-09-02T09:11:34.000Z", "tags": ["gguf", "gsq", "rco", "quantization", "mixed-precision", "ist-daslab", "multimodal", "vision", "image-text-to-text", "arxiv:2604.18556"], "readme": "---\nbase_model: Qwen/Qwen3.8-27B\nbase_model_relation: quantized\npipeline_tag: image-text-to-text\nlibrary_name: gguf\nlicense: apache-2.0\ntags:\n- gguf\n- gsq\n- rco\n- quantization\n- mixed-precision\n- ist-daslab\n- multimodal\n- vision\n---\n\n\n\n<div align="center">\n\n<a href="https://github.com/IST-DASLab"><img src="https://huggingface.co/ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF/resolve/main/assets/banner.png" alt="GGUF, GSQ-RCO dynamic non-uniform quantization" width="100%"/>\n\n\n\n# Qwen3.8-27B · GSQ-RCO GGUFs\n\nNon-uniform GGUF quantizations produced with GSQ and RCO, with a vision projector for multimodal use.\n\n
mlx-community/Qwen2.5-1.5B-Instruct-4biton macOS Sequoia:\n\n| Scenario | Fields | Autoregressive Baseline | Parallel Constrained | Latency Speedup | Syntax Validity |\n| :--- | :--- | :--- | :--- | :--- | :--- |\n| Fintech Fraud Routing | 4 fields | 420 ms (120 tok/s) | 75 ms | 5.6x | 100% guaranteed |\n| Code Security Audit | 4 fields | 380 ms (125 tok/s) | 68 ms | 5.6x | 100% guaranteed |\n| High-Cardinality Tariff | 1 field (255 choices) | 500 ms (118 tok/s) | 89 ms | 5.6x | 100% guaranteed |\n| Enterprise Support Triage | 28 fields | 1,900 ms (130 tok/s) | 270 ms | 7.0x | 100% guaranteed |\n\n---\n\n## Why Parallel Constrained Decoding?\n\n### The Problem", "params_total": null}, {"id": "DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 1256962, "likes": 958, "last_modified": "2026-09-16T23:56:33.000Z", "tags": ["gguf", "unsloth", "fine tune", "heretic", "uncensored", "abliterated", "ara", "MTP GGUF Quants", "Regular GGUF Quants", "qwen3_8"], "readme": "---\nlanguage:\n- en\n- zh\nlicense: apache-2.0\ntags:\n- unsloth\n- fine tune\n- heretic\n- uncensored\n- abliterated\n- ara\n- MTP GGUF Quants\n- Regular GGUF Quants\n- qwen3_8\n- qwen3_6\n- qwen3_5\n- multi-stage tuned\n- thinking\n- reasoning\n- all use cases\n- coder\n- creative\n- creative writing\n- all genres\n- story\n- writing\n- fiction\n- roleplaying\n- bfloat16\n- multi-stage-tune\n- multi-state-merge\ndatasets:\n- DavidAU/Polar-STRICT-Datasets\n- DavidAU/F451-STRICT-Datasets\npipeline_tag: image-text-to-text\nbase_model:\n- DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU\n---\n\n<font color="red">Important: This is the first fine tune to exceed 730 "arc-c" ("735": 144 pts higher than Qwen 3.8 27B) AND 880 ARC-E (The OpenAI, Claude and Gemini "zone of intelligence") \nin 8 bit and over 718 arc-c in 4 bit. This version is called TURBO because it drastically reduces thinking tokens (by 1/2 to as high as 1/10), yet maintains output detail and quality. \nIn otherwords while "reg" Qwen3.8 27B is thinking about "formatting" for a few 1000 tokens, this model is already done and waiting for more.\nThis repo contains both "regular" and "MTP" Neo-CODER MAX DI-MATRIX (duel imatrix) GGUF quants. \n\nNOTE: Please see the "community" tab for user experiences, additional third party benchmarks (including strongest tool calling performance ever recorded), \nand other quant versions (also see "Quantized" in the right "model tree" too).\n\nQwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF
\n\n<img src="star-wars-hans-solo.gif" style="float:right; padding:10px;">\n\nThe strongest, smartest open source multi-stage model fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth.\n\nThe first model of this size/type to breach "730" ARC-C in 8 bit (735) and 4 bit (719); hench the "735" in the name.\n\nThis model has 1/5 (as low as 1/10 in some cases) to 1/2 the thinking tokens (vs reg Qwen 3.8) across all 3 ", "params_total": null}, {"id": "unsloth/Qwen3.8-27B-GGUF", "pipeline_tag": null, "downloads": 7118363, "likes": 4373, "last_modified": "2026-08-20T12:04:25.000Z", "tags": ["gguf", "qwen3_5", "unsloth", "base_model:Qwen/Qwen3.8-27B", "base_model:quantized:Qwen/Qwen3.8-27B", "license:apache-2.0", "endpoints_compatible", "region:us", "imatrix", "conversational"], "readme": "---\nbase_model:\n- Qwen/Qwen3.8-27B\nlicense: apache-2.0\ntags:\n- unsloth\n---\n\n# Read our How to Run Qwen3.8-27B Guide!\n
\n\nThis experimental preview of the architecture that will underpin Qwen4 is built around a fundamental rethinking of how the core components of modern large language models (LLMs) interact at scale.\n \n## Highlights\n\nThe first open-weight release under this architecture is Qwen3.8-Flash-Next, which introduces:\n\n- Hybrid Attention with QSA: The Gated DeltaNet and Gated Attention pairing has been reworked into Gated DeltaNet and Qwen Sparse Attention (QSA). Rather than selecting individual tokens for processing, QSA operates at the micro-block level. This cuts long-context latency signifi", "params_total": null}]}