From 6ccdd1f9fc40efba92a031728d1c37a8f92b571e Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Fri, 29 May 2026 03:33:57 +0600 Subject: [PATCH 01/33] Update README.md --- README.md | 4 ++-- 1 file changed, 2 insertions(+), 2 deletions(-) diff --git a/README.md b/README.md index 4da2903..44ef7eb 100644 --- a/README.md +++ b/README.md @@ -10,9 +10,9 @@

- Build Status + Build Status PyPI Version - License + License

From afec3b8b45f2b543a13a44c0f74443a6d7f11abd Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Fri, 29 May 2026 03:47:19 +0600 Subject: [PATCH 02/33] cleanup --- DEVELOPER_TESTING.md | 664 ------------------------------------------- graph_build_audit.md | 71 ----- next_move.md | 103 ------- project_identity.md | 1 - 4 files changed, 839 deletions(-) delete mode 100644 DEVELOPER_TESTING.md delete mode 100644 graph_build_audit.md delete mode 100644 next_move.md delete mode 100644 project_identity.md diff --git a/DEVELOPER_TESTING.md b/DEVELOPER_TESTING.md deleted file mode 100644 index f2be1d4..0000000 --- a/DEVELOPER_TESTING.md +++ /dev/null @@ -1,664 +0,0 @@ -# Codegenome Developer Testing Guide - -This guide provides comprehensive instructions for testing **Codegenome** (Watcher CLI) in development mode. - -**Project Overview:** Codegenome is an open-source CLI tool for building and querying local codebase knowledge graphs. It uses tree-sitter for code parsing, stores metadata in SQLite, and exposes graph data through an MCP (Model Context Protocol) server. - ---- - -## Table of Contents - -1. [Environment Setup](#environment-setup) -2. [Installation for Development](#installation-for-development) -3. [Running Tests](#running-tests) -4. [Manual Testing Workflows](#manual-testing-workflows) -5. [Testing MCP Server](#testing-mcp-server) -6. [Debugging Tips](#debugging-tips) -7. [Common Issues](#common-issues) - ---- - -## Environment Setup - -### Prerequisites - -- **Python 3.11+** (3.11, 3.12, or 3.13 supported) -- **Git** for version control -- **pip** for package management - -### Verify Python Installation - -```bash -python --version -# Output should be Python 3.11.x, 3.12.x, or 3.13.x -``` - ---- - -## Installation for Development - -### 1. Clone the Repository - -```bash -git clone https://github.com/Ogro-Projukti/codegenome.git -cd codegenome -``` - -### 2. Create and Activate Virtual Environment - -**Windows:** -```bash -python -m venv .venv -.venv\Scripts\activate -``` - -**macOS/Linux:** -```bash -python -m venv .venv -source .venv/bin/activate -``` - -### 3. Install in Editable Mode with Dev Dependencies - -```bash -pip install -e ".[dev]" -``` - -This installs: -- **Core dependencies:** tree-sitter, networkx, watchdog, fastmcp, radon -- **Dev dependencies:** pytest, pytest-cov, ruff, pyinstaller - -### 4. Verify Installation - -```bash -# Check CLI availability -codegenome --help - -# Or run as module -python -m codegenome --help -``` - -Expected output shows all available commands and flags. - ---- - -## Running Tests - -### Run All Tests - -```bash -pytest -``` - -### Run Tests with Coverage Report - -```bash -pytest --cov=src/codegenome --cov-report=html -``` - -Coverage report is generated in `htmlcov/index.html`. - -### Run Specific Test File - -```bash -pytest tests/test_parser.py -v -pytest tests/test_builder.py -v -pytest tests/test_mcp_server.py -v -``` - -### Run Tests Matching a Pattern - -```bash -# Tests for scanner functionality -pytest -k "scanner" -v - -# Tests for timeline features -pytest -k "timeline" -v -``` - -### Run with Verbose Output - -```bash -pytest -v # Show each test name -pytest -vv # Very verbose with full test output -pytest -v --tb=short # Shorter traceback format -pytest -v --tb=long # Full traceback on failures -``` - -### Run Tests in Parallel (faster) - -```bash -pip install pytest-xdist -pytest -n auto # Uses all available CPU cores -``` - ---- - -## Manual Testing Workflows - -### Workflow 1: Build a Graph from a Repository - -Test the core graph building functionality. - -#### Step 1: Navigate to a Target Repository - -```bash -cd /path/to/test/repository -``` - -Use an existing Python, JavaScript, or Go project (or test on codegenome itself). - -#### Step 2: Build a Full Graph - -```bash -codegenome --workspace . --build --full -``` - -Expected output: -- `.genome/` directory created with: - - `graph.json` — the extracted code graph - - `watcher.db` — SQLite database with metadata - - `build_log.txt` — build summary - -#### Step 3: Verify Output - -```bash -# Check .genome directory was created -ls -la .genome/ - -# View build log -cat .genome/build_log.txt - -# Check graph file size (should be > 100 bytes for non-empty repos) -ls -lh .genome/graph.json -``` - -#### Step 4: Inspect Graph Content (Optional) - -```bash -python ->>> import json ->>> with open('.genome/graph.json') as f: -... graph = json.load(f) ->>> print(f"Nodes: {len(graph.get('nodes', []))}") ->>> print(f"Edges: {len(graph.get('edges', []))}") ->>> exit() -``` - ---- - -### Workflow 2: Export in Multiple Formats - -Test the export functionality. - -#### Step 1: Build and Export - -```bash -# From your test repository directory -codegenome --workspace . --build --export json markdown graphml cypher -``` - -#### Step 2: Verify Exports - -```bash -# Check all export files exist -ls -la .genome/ - -# Should see: -# - graph.json -# - graph.md -# - graph.graphml -# - graph.cypher -# - graph_html/ (directory with interactive viewer) -``` - -#### Step 3: View Markdown Export - -```bash -cat .genome/graph.md | head -50 -``` - -#### Step 4: Test HTML Viewer - -```bash -# Open in browser (path depends on OS) -# Windows: -start .genome/graph_html/index.html - -# macOS: -open .genome/graph_html/index.html - -# Linux: -xdg-open .genome/graph_html/index.html -``` - ---- - -### Workflow 3: Watch Mode (Live Updates) - -Test the file watcher and incremental rebuild. - -#### Step 1: Start Watch Mode - -```bash -# From your test repository -codegenome --workspace . --build --watch -``` - -Expected output: -``` -[...] Starting watch mode... -[...] Watching for changes in: /path/to/repo -``` - -The process should stay running. - -#### Step 2: Make File Changes (In Another Terminal) - -```bash -# Open another terminal, navigate to the same repo -cd /path/to/test/repository - -# Create or modify a file -echo "new_function = lambda x: x + 1" >> test_file.py -``` - -#### Step 3: Verify Incremental Update - -Back in the original terminal, you should see: -``` -[...] Detecting changes... -[...] Incremental rebuild: 1 files changed -[...] Graph updated -``` - -#### Step 4: Stop Watch Mode - -```bash -# Press Ctrl+C in the watch mode terminal -``` - ---- - -### Workflow 4: Timeline Queries - -Test timeline and change history functionality. - -#### Step 1: Build with Timeline - -```bash -# From your test repository -codegenome --workspace . --build --full -``` - -#### Step 2: Dump Timeline - -```bash -codegenome --workspace . --dump-timeline -``` - -Expected output: JSON with timeline metadata, change events, and file churn statistics. - -#### Step 3: Query Timeline Programmatically (Optional) - -```bash -python ->>> from codegenome.timeline import TimelineDB ->>> db = TimelineDB('.genome/watcher.db') ->>> timeline = db.get_timeline() ->>> print(f"Timeline snapshots: {len(timeline.get('snapshots', []))}") ->>> exit() -``` - ---- - -## Testing MCP Server - -The MCP (Model Context Protocol) server allows integration with AI clients like Cursor and Claude. - -### Workflow 1: Start MCP Server in HTTP Mode - -#### Step 1: Build Graph First - -```bash -# From your test repository -codegenome --workspace . --build -``` - -#### Step 2: Start MCP Server - -```bash -# HTTP mode (default) -codegenome --workspace . --mcp -``` - -Expected output: -``` -[...] Starting MCP server on http://127.0.0.1:8000 -[...] Health check: /health -[...] Resources available at /resources -``` - -The server stays running. - -#### Step 3: Test Health Endpoint (In Another Terminal) - -```bash -curl http://127.0.0.1:8000/health -``` - -Expected response: -```json -{"status": "healthy"} -``` - -#### Step 4: Query Resources - -```bash -curl http://127.0.0.1:8000/resources -``` - -Returns available MCP resources (code symbols, relationships, etc.). - -#### Step 5: Stop Server - -```bash -# Press Ctrl+C in the MCP server terminal -``` - ---- - -### Workflow 2: MCP Server with Watch + Live Graph - -Test real-time updates with MCP. - -```bash -# Build with watch and MCP enabled -codegenome --workspace . --build --mcp --watch -``` - -Make file changes in another terminal (as in Workflow 3). The MCP server updates resources in real-time. - ---- - -### Workflow 3: MCP Server with Stdio Transport (For Agents) - -Test stdio mode for direct agent integration. - -```bash -codegenome --workspace . --mcp --transport stdio -``` - -In this mode: -- Server reads JSON-RPC requests from stdin -- Server writes JSON-RPC responses to stdout -- Suitable for direct process integration with Cursor, Claude, etc. - ---- - -## Code Quality Checks - -### Linting with Ruff - -```bash -# Check for linting issues -ruff check src tests - -# Auto-fix issues -ruff check --fix src tests - -# Format code -ruff format src tests -``` - -### Run Linting + Tests Together - -```bash -ruff check src tests && pytest -``` - ---- - -## Debugging Tips - -### Enable Debug Logging - -Most modules support debug output via environment variables: - -```bash -# Verbose debug output -CODEGENOME_DEBUG=1 codegenome --workspace . --build - -# Or with Python module -CODEGENOME_DEBUG=1 python -m codegenome --workspace . --build -``` - -### Debug in Python REPL - -```python -import sys -sys.path.insert(0, 'src') - -from codegenome.builder import GraphBuilder -from pathlib import Path - -# Build a graph programmatically -builder = GraphBuilder(workspace_dir=Path('.')) -result = builder.build_full() - -# Inspect result -print(result) -``` - -### Inspect SQLite Database - -```bash -# With sqlite3 CLI (if installed) -sqlite3 .genome/watcher.db - -# View tables -.tables - -# Query symbols -SELECT * FROM symbols LIMIT 10; - -# Query relationships -SELECT * FROM relationships LIMIT 10; - -# Exit -.quit -``` - -Or in Python: - -```python -import sqlite3 - -conn = sqlite3.connect('.genome/watcher.db') -cursor = conn.cursor() - -# Get all tables -cursor.execute("SELECT name FROM sqlite_master WHERE type='table';") -tables = cursor.fetchall() -print("Tables:", [t[0] for t in tables]) - -# Query symbols -cursor.execute("SELECT * FROM symbols LIMIT 5;") -for row in cursor.fetchall(): - print(row) - -conn.close() -``` - ---- - -## Common Issues - -### Issue 1: Virtual Environment Not Activated - -**Symptom:** `codegenome: command not found` or `ModuleNotFoundError` - -**Solution:** -```bash -# Make sure venv is activated -# Windows: -.venv\Scripts\activate - -# macOS/Linux: -source .venv/bin/activate - -# Verify prompt shows (.venv) -``` - ---- - -### Issue 2: "tree-sitter Not Found" or Language Binding Errors - -**Symptom:** `ModuleNotFoundError: No module named 'tree_sitter_python'` - -**Solution:** -```bash -# Reinstall dependencies -pip install --upgrade --force-reinstall tree-sitter tree-sitter-python tree-sitter-javascript tree-sitter-typescript tree-sitter-go tree-sitter-rust -``` - ---- - -### Issue 3: ".genome Directory Not Created" - -**Symptom:** Build completes but no `.genome/` directory - -**Causes:** -- **Empty repository:** Ensure the target repo has source files in supported languages -- **Invalid workspace path:** Use absolute or relative paths, e.g., `.` or `/full/path/to/repo` - -**Solution:** -```bash -# Test on codegenome itself -cd /path/to/codegenome -codegenome --workspace . --build --full - -# Or test on a known repo -git clone https://github.com/torvalds/linux.git linux-test -cd linux-test -codegenome --workspace . --build # May take time for large repo -``` - ---- - -### Issue 4: MCP Server Port Already in Use - -**Symptom:** `Address already in use` on port 8000 - -**Solution:** -```bash -# Kill the existing process -# Windows: -netstat -ano | findstr :8000 -taskkill /PID /F - -# macOS/Linux: -lsof -i :8000 -kill -9 - -# Or use a different port (if supported) -codegenome --workspace . --mcp --port 8001 -``` - ---- - -### Issue 5: Tests Fail Due to Missing Language Grammars - -**Symptom:** `ParseError: No grammar found for language` - -**Solution:** -```bash -# Tree-sitter needs language grammars; reinstall from scratch -pip uninstall tree-sitter tree-sitter-{python,javascript,typescript,go,rust} -y -pip install -e ".[dev]" -pytest # Try again -``` - ---- - -### Issue 6: Slow Build on Large Repositories - -**Symptom:** Build takes > 5 minutes - -**Workaround:** -```bash -# Use incremental builds instead of full -codegenome --workspace . --build # Incremental (faster) - -# Exclude large directories -# (Feature may be added in future; currently n/a) -``` - ---- - -## Quick Reference: Common Commands - -```bash -# Development setup -python -m venv .venv -source .venv/bin/activate # or .venv\Scripts\activate on Windows -pip install -e ".[dev]" - -# Run tests -pytest # All tests -pytest -v # Verbose -pytest --cov=src/codegenome # With coverage -pytest -k "parser" # Specific pattern - -# Code quality -ruff check src tests # Lint -ruff format src tests # Format - -# Graph building -codegenome --workspace . --build # Incremental -codegenome --workspace . --build --full # Full rebuild -codegenome --workspace . --build --watch # Live mode - -# Exports -codegenome --workspace . --build --export json markdown graphml cypher - -# Timeline -codegenome --workspace . --dump-timeline - -# MCP server -codegenome --workspace . --mcp # HTTP mode -codegenome --workspace . --mcp --watch # With live updates -codegenome --workspace . --mcp --transport stdio # Stdio for agents - -# Help -codegenome --help -python -m codegenome --help -``` - ---- - -## Resources - -- **CLI Reference:** See [docs/cli-reference.md](docs/cli-reference.md) for full command documentation -- **Installation Guide:** See [docs/installation.md](docs/installation.md) -- **MCP Integration:** See [docs/mcp-integration.md](docs/mcp-integration.md) -- **Main README:** See [README.md](README.md) - ---- - -## Contributing Tips - -When making changes to the codebase: - -1. **Write tests first:** Use TDD approach where applicable -2. **Run full test suite:** `pytest -v` before committing -3. **Lint your code:** `ruff check --fix src tests` -4. **Test on multiple Python versions:** If possible, test on 3.11, 3.12, 3.13 -5. **Document changes:** Update docstrings and relevant docs -6. **Test MCP integration:** If modifying MCP server, test with actual agents - ---- - -**Happy testing!** 🚀 - -For issues or questions, refer to the project's GitHub issues or documentation. diff --git a/graph_build_audit.md b/graph_build_audit.md deleted file mode 100644 index 51c3cf5..0000000 --- a/graph_build_audit.md +++ /dev/null @@ -1,71 +0,0 @@ -# CodeGenome — Graph Build Audit & Cleanup Plan - -Date: 2026-05-28 - -Purpose -- Produce a focused audit for graph-building, auto-evolve, and graph-driven analysis. Align cleanup tasks with project_identity.md and next_move.md so the package can prioritize a python-igraph-based, incremental, event-driven graph engine. - -High-level findings -- Core, required components: - - src/codegenome/parser.py — tree-sitter parsers: REQUIRED (primary source extraction). - - src/codegenome/builder.py — graph construction: REQUIRED, currently NetworkX-centric; must migrate to igraph or wrap behind an abstraction. - - src/codegenome/clusterer.py — clustering (leidenalg + igraph conversion): REQUIRED; consolidate to igraph-native (remove networkx intermediary). - - src/codegenome/graph_store.py — persistence/timeline: REQUIRED; ensure store supports incremental snapshots and igraph-compatible serialization. - - src/codegenome/timeline.py — timeline/churn analysis: REQUIRED; currently assumes networkx in places — migrate. - - src/codegenome/watcher.py & live_graph_monitor.py — event-driven/watchdog pipeline: REQUIRED (real-time incremental builds). - - src/codegenome/mcp_server.py & installer.py & mcp_activity.py — MCP integration: REQUIRED for agent integration, but can be optional in packaging via extras. - - src/codegenome/exporter.py — export formats: REQUIRED surface, but should work from igraph or via an adapter. - - tests/ — many tests assume NetworkX; REQUIRED to update to igraph or adapter tests. - -- Risk/technical debt - - NetworkX is used widely (builder, exporter, timeline, intelligence, graph_store). Next_move mandates removal to avoid memory blowups; current codebase mixes networkx and igraph with conversion helpers — risky and expensive. - - python-igraph + leidenalg are native C-backed and preferred for large graphs, but platform packaging and wheel availability must be verified. - - Export and tests currently depend on NetworkX APIs; blind removal will break behavior and CI. - -- Candidates to postpone or make optional - - Packaging helpers for PyInstaller/build.py — postpone until core migration completes. - - Non-essential export formats or heavy optional integrations (GraphML/Cypher plugins) can be moved to optional extras. - -Recommended migration strategy (staged) -1. Introduce a thin Graph API abstraction (src/codegenome/graph_api.py): - - Provide the minimal API surface currently consumed across codebase (add_node, add_edge, nodes, edges, attributes, SCC, degree, neighbors, to_serializable()). - - Implement an igraph-backed implementation and a NetworkX compatibility adapter for parity tests. - -2. Add unit/integration tests that assert parity between current NetworkX output and igraph adapter on small graphs (SCCs, degree, export shapes). - -3. Migrate builder.py to use Graph API (backed by igraph) while keeping behavior identical (graph.json output unchanged for same inputs). - -4. Migrate clusterer.py to igraph-native calls; remove networkx_to_igraph conversion helper; use leidenalg directly on igraph objects. - -5. Update exporter.py, timeline.py, graph_store.py, and intelligence.py to consume Graph API objects (or igraph directly once parity verified). - -6. Run full test suite and fix regressions. Keep networkx available in dev extras only (e.g., [compat]) until tests and consumers fully migrated. - -7. Remove networkx from core dependencies and pyproject; update README and docs describing installation extras for legacy exports. - -8. Profile memory and performance on medium and large sample repos; iterate on lazy-loading and subgraph contraction strategies described in next_move.md. - -Concrete checklist (files to change) -- High priority: src/codegenome/builder.py, src/codegenome/clusterer.py, src/codegenome/graph_store.py, src/codegenome/timeline.py, src/codegenome/exporter.py -- Medium: src/codegenome/intelligence.py, src/codegenome/watcher.py (ensure watcher integrates with new Graph API), tests/* -- Low/postpone: build.py, packaging scripts, optional exporters, docs updates - -Dependency & packaging notes -- Keep: tree-sitter family (parsers), watchdog, fastmcp (MCP), python-igraph, leidenalg -- Move to optional extras: networkx (compat/export), pyinstaller, heavy export plugins -- Ensure python-igraph binary wheels are available or document build steps for platforms where they are not. - -Testing & validation -- Add smoke tests that build a small repo graph and verify parity with existing outputs. -- Add memory/regression tests for larger repos to ensure igraph migration reduces peak memory usage. - -Immediate next moves (recommended order) -1. Add src/codegenome/graph_api.py and tests asserting parity for core graph ops. -2. Refactor builder.py to use Graph API. -3. Run tests and fix breaking changes. -4. Migrate clusterer and exporter; remove networkx from core deps. - -Notes -- next_move.md and project_identity.md already prescribe igraph-first and event-driven incremental pipelines — the above plan operationalizes those mandates while keeping a safe compatibility path. - -If this looks good, next action can be: implement graph_api.py skeleton and convert builder.py to use it (I can perform those edits and run tests). \ No newline at end of file diff --git a/next_move.md b/next_move.md deleted file mode 100644 index 82ca8e7..0000000 --- a/next_move.md +++ /dev/null @@ -1,103 +0,0 @@ -# Architectural Design Document: Scalable Codebase Graph Analyzer -## Executive Summary & System Decisions Log - -This document compiles the architectural decisions, structural paradigms, and technical strategies agreed upon for scaling a codebase graph analysis tool. The primary objective is to transition from a monolithic, high-memory graph structure to a distributed, incremental, and language-agnostic architecture capable of handling enterprise-scale codebases efficiently. - ---- - -## 1. Core Architecture & Technology Stack Upgrades - -### The Problem -The initial implementation used `NetworkX` alongside `python-igraph` and `leidenalg`. For large codebases, `NetworkX` incurred a catastrophic memory footprint due to its internal storage design (nested Python dictionaries) and massive CPU overhead during serialization/deserialization between libraries. - -### Decisions Made -1. **Complete Removal of NetworkX:** Standardize 100% of graph computation on `python-igraph`. - * **Reasoning:** `python-igraph` executes core graph operations (Strongly Connected Components, Cycle Detection, Degree Analysis, and Reachability) natively in C, providing a 10x–100x performance boost and severe memory reductions. -2. **Algorithmic Specialization:** - * **Leiden Community Detection:** Runs on high-level macro-graphs or clean subgraphs to map logical architectures. - * **Cycle Detection:** Avoid global execution of heavy algorithms (e.g., Tarjan's/Johnson's) across the entire codebase. Instead, calculate **Strongly Connected Components (SCCs)** first, treat them as single mega-nodes, and isolate deep cycle queries exclusively *within* problematic SCC clusters. - * **Reachability Analysis:** Shift away from complete transitive closure computation to localized checks or landmark-based routing approximations where appropriate. - ---- - -## 2. Structural Paradigm: Hierarchical Graph Decomposition - -### The Problem -For a worst-case modular codebase containing layers of nesting: -$$\text{Modules (m)} \rightarrow \text{Submodules (sm)} \rightarrow \text{Files (f)} \rightarrow \text{Classes (c)} \rightarrow \text{Nested Classes (nc)} \rightarrow \text{Functions (fn)} \rightarrow \text{Local Functions (lfn)}$$ -Loading a single flat graph representing line-by-line syntax relationships stalls UI rendering pipelines and breaches memory safety limits. - -### Decisions Made -1. **Divide-and-Conquer Clustered Graphs:** Deconstruct the system into a tree of isolated graphs. -2. **Bottom-Up Graph Synthesis:** * **Leaf-Level (Micro-Graphs):** Create tiny, micro-graphs for independent submodules containing local files, classes, and execution flows. - * **Macro-Level (Parent Graph):** Collapse entire submodule subgraphs into single "Meta-Nodes" using structural aggregation techniques (e.g., igraph's `contract_vertices()`). Edges between these meta-nodes represent cross-boundary imports, weighted by the cumulative frequency of interactions. -3. **Lazy-Loading Top-Down UI Pipeline:** - * The user interface initially renders only the highest level Parent Graph (representing primary modules). - * Detailed child graphs are **lazy-loaded via dedicated API endpoints** (`GET /graph/module_A`) only when a developer explicitly selects a module to explore, eliminating WebGL/Canvas rendering lags. - -- - -## 3. Incremental Rebuild & Event-Driven Parsing - -### The Problem -Re-parsing thousands of unmodified files whenever a single line of code changes is highly inefficient. However, traditional polling methods using standard directory iterations (`os.walk`) thrash disk I/O, spike CPU consumption, and fall behind when processing vast numbers of files. - -### Decisions Made -1. **Event-Driven Codebase Observer:** Replace time-interval folder-polling with an asynchronous background thread powered by the **`watchdog`** library. - * **Reasoning:** Hooks directly into native OS kernel event sub-systems (`inotify` on Linux, `FSEvents` on macOS, `ReadDirectoryChangesW` on Windows) to capture instant, lightweight file-save notifications (e.g., `FileModifiedEvent`). -2. **Surgical Patching Pipeline:** - * Upon notification, locate the explicit submodule boundary containing the altered file. - * Clear old internal nodes and attributes associated with that single file path. - * Re-parse *only* the modified file and merge the updated nodes/edges directly back into the cached submodule subgraph. - * Re-run analytics suites (SCC, Cycles, Degree) locally within the altered module scope. - - - -## 4. Cross-Submodule Dependency Management - -### The Problem -When a file is modified locally, calculating how outside modules are affected (incoming dependencies) typically requires scanning the entire system, breaking the isolated submodule paradigm. - -### Decisions Made -1. **Global Dependency Registry:** Implement a centralized, lightweight lookup schema (in-memory or SQLite-backed) tracing the usage of all exported definitions. -2. **Interface Contract Mapping:** Track structural definitions ("Provides") alongside external requirements ("Consumes"). -3. **Proxy Node System:** - * Submodules retain self-containment by using **Proxy/Stub Nodes** to represent points of contact with external targets. - * If a critical symbol (e.g., `login_user()`) is deleted or renamed inside `Submodule_A`, the graph system queries the Registry, locates all dependent Proxy Nodes across foreign graphs, and marks their internal state as `is_broken = True`. - * **Orphan and Reachability algorithms** catch these flags instantly to flag architectural breaking-changes in the UI without re-evaluating external AST structures. - -```python -# System Design Pattern: Centralized Lookups -DEPENDENCY_REGISTRY = { - "FQN_IDENTIFIER": { - "defined_in": "origin/file_path.py", - "consumed_by": ["dependent/file_path_1.py", "dependent/file_path_2.py"] - } -} - -``` - - -## 5. Language-Agnostic Normalization Engine - -### The Problem - -Hardcoding unique semantic behaviors for every programming language's Abstract Syntax Tree (AST) causes engineering bloat and scales poorly. - -### Decisions Made - -1. **Standardized Parser Backend via Tree-sitter:** Deploy **Tree-sitter** for code parsing. It parses source files into structural concrete trees using fast C-grammars and offers lightning-fast incremental updates. -2. **Declarative Pattern Queries:** Utilize Tree-sitter S-expression queries to isolate syntax targets (Classes, Functions, Imports) uniformly across files. -3. **Universal Normalization Layer (Adapter Interface):** Create an adapter system to translate concrete syntax patterns into a standardized **Universal Schema / Common Intermediate Representation (IR)** before handing elements over to the graph engine. -4. **Fully Qualified Name (FQN) Resolution:** The adapter translates varying path behaviors (relative imports, package-level structures, text inclusions) into a uniform project namespace format (`PROJECT//root/submodule/file/symbol`) to align cleanly with the Global Dependency Registry. - - -## 6. MVP Implementation Strategy - -1. **Target Environment:** Focus initial development on **Python** and structurally similar targets (e.g., Mojo, GDScript). -2. **Python Normalizer Focus:** Use Python's explicit import nuances (`import X`, `from Y import Z`, `from . import local`, and package definitions via `__init__.py`) as a rigorous testing suite to validate path resolution engines. -3. **Pipeline Construction Ordering:** -* **Milestone 1:** Build the backend storage topology using `python-igraph` supporting nested graph hierarchies. -* **Milestone 2:** Implement the centralized memory-based Global Dependency Registry. -* **Milestone 3:** Develop the Tree-sitter query extractor for Python to emit the Universal Schema. -* **Milestone 4:** Tie components together via the `watchdog` kernel event listener to realize automated, real-time graph patching. \ No newline at end of file diff --git a/project_identity.md b/project_identity.md deleted file mode 100644 index 6ddd274..0000000 --- a/project_identity.md +++ /dev/null @@ -1 +0,0 @@ -CodeGenome: Project Identity🚀 VisionTo render the invisible complexity of software architecture visible, manageable, and intuitive. We envision a world where every developer, regardless of the codebase's size or age, can instantly visualize their system’s structure, identify architectural bottlenecks, and navigate their code with total clarity.🎯 MissionTo provide an open-source, high-performance, and language-agnostic platform that treats code as a "living genome." Through real-time hierarchical graph decomposition, we empower developers to evolve their systems with confidence, turning static code into an interactive, self-documenting architectural atlas.🏆 GoalsEliminate Architectural Debt: Provide immediate, automated feedback on circular dependencies, bridge-node fragmentation, and god-object bloat.Ensure Zero-Friction Observability: Achieve a "living" graph representation that updates in milliseconds via event-driven kernel hooks, ensuring the documentation is never out of date.Democratize Architecture: Lower the cognitive barrier for new developers joining large projects by providing a "zoomable" interface that organizes chaos into logical sub-systems ($m \rightarrow sm \rightarrow f \rightarrow c$).Scale Through Community: Foster an ecosystem where any language (Python, TypeScript, Go, etc.) can be integrated into the CodeGenome engine via universal, schema-driven adapters.Enable Data-Driven Refactoring: Give engineers the tools to make refactoring decisions based on empirical graph data (centrality, reachability, and coupling) rather than guesswork.Why this structure matters for your PyPI release:The Vision attracts people who want to solve a "big" problem.The Mission tells them how you intend to do it (the "genome" / "interactive atlas" approach).The Goals provide a roadmap for contributors—they know exactly what success looks like for CodeGenome. \ No newline at end of file From f75ce856c5ead817878b3da4bb370d06447842a9 Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Fri, 29 May 2026 04:20:39 +0600 Subject: [PATCH 03/33] Update README.md --- README.md | 7 ++++--- 1 file changed, 4 insertions(+), 3 deletions(-) diff --git a/README.md b/README.md index 44ef7eb..031df82 100644 --- a/README.md +++ b/README.md @@ -6,13 +6,14 @@

Codegenome

- Open-source CLI for building, exporting, and querying local codebase knowledge graphs. + Open-source CLI for building, exporting, and querying local codebase knowledge graphs.
+ 🌍 Website: codegenome.pages.dev

- Build Status + Build Status PyPI Version - License + License

From 04230fea88d670a194228d1bef4eab1c349237c9 Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Fri, 29 May 2026 04:26:46 +0600 Subject: [PATCH 04/33] remove unused dependecy --- build.py | 1 - pyproject.toml | 1 - requirements.txt | 2 -- tests/test_imports.py | 1 - 4 files changed, 5 deletions(-) diff --git a/build.py b/build.py index 1829557..dd99e63 100644 --- a/build.py +++ b/build.py @@ -41,7 +41,6 @@ "fastmcp", "starlette", "uvicorn", - "radon", ] COLLECT_ALL = [ diff --git a/pyproject.toml b/pyproject.toml index ab2e5e4..00be4ea 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -33,7 +33,6 @@ dependencies = [ "tree-sitter-rust==0.21.2", "watchdog", "fastmcp", - "radon", "leidenalg", "python-igraph", "click", diff --git a/requirements.txt b/requirements.txt index fa77127..f82a4ee 100644 --- a/requirements.txt +++ b/requirements.txt @@ -7,10 +7,8 @@ tree-sitter-rust==0.21.2 networkx>=3.2,<4 watchdog>=4.0,<5 fastmcp>=2.0,<3 -radon>=6.0,<7 leidenalg>=0.10,<1 python-igraph>=0.11,<1 -litellm>=1.40,<2 jinja2>=3.1,<4 pytest>=8.0,<9 pytest-cov>=5.0,<6 diff --git a/tests/test_imports.py b/tests/test_imports.py index 874b7ee..652493e 100644 --- a/tests/test_imports.py +++ b/tests/test_imports.py @@ -6,7 +6,6 @@ "tree_sitter", "watchdog", "fastmcp", - "radon", "leidenalg", "igraph", "jinja2", From 1710e6ff5e41d4d9037450a038a294e9e8bb5e03 Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Fri, 29 May 2026 04:38:53 +0600 Subject: [PATCH 05/33] readme bug fix --- README.md | 22 +++++++++++----------- pyproject.toml | 5 ++--- src/codegenome/version.py | 2 +- 3 files changed, 14 insertions(+), 15 deletions(-) diff --git a/README.md b/README.md index 031df82..bc12aee 100644 --- a/README.md +++ b/README.md @@ -1,5 +1,5 @@
- Codegenome Header + Codegenome Header
@@ -13,7 +13,7 @@

Build Status PyPI Version - License + License

@@ -30,8 +30,8 @@ Codegenome deeply understands your code. It parses your source files, incrementa Keep your codebase intelligence fresh in real-time. As you write code, Codegenome watches your workspace and automatically updates the graph, so your agents and queries are never out of sync.
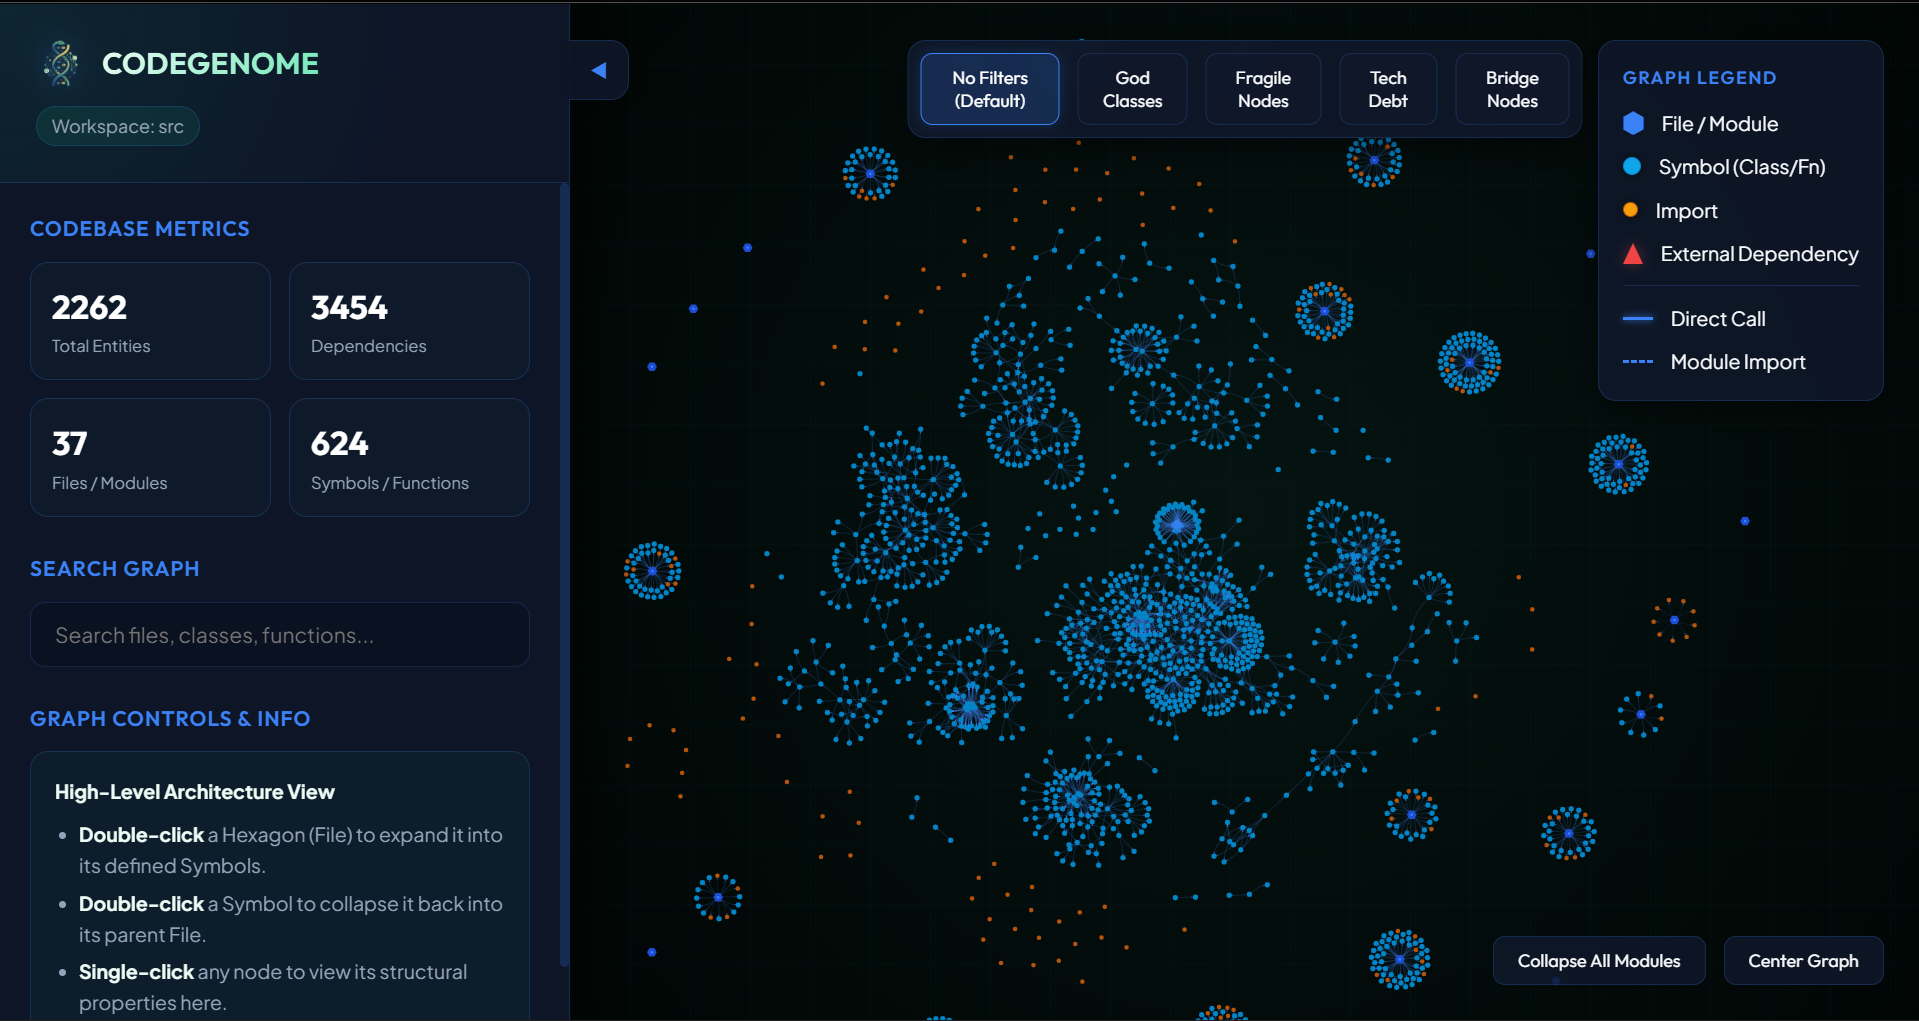
- Live Graph Visualization - Live Graph Detail + Live Graph Visualization + Live Graph Detail
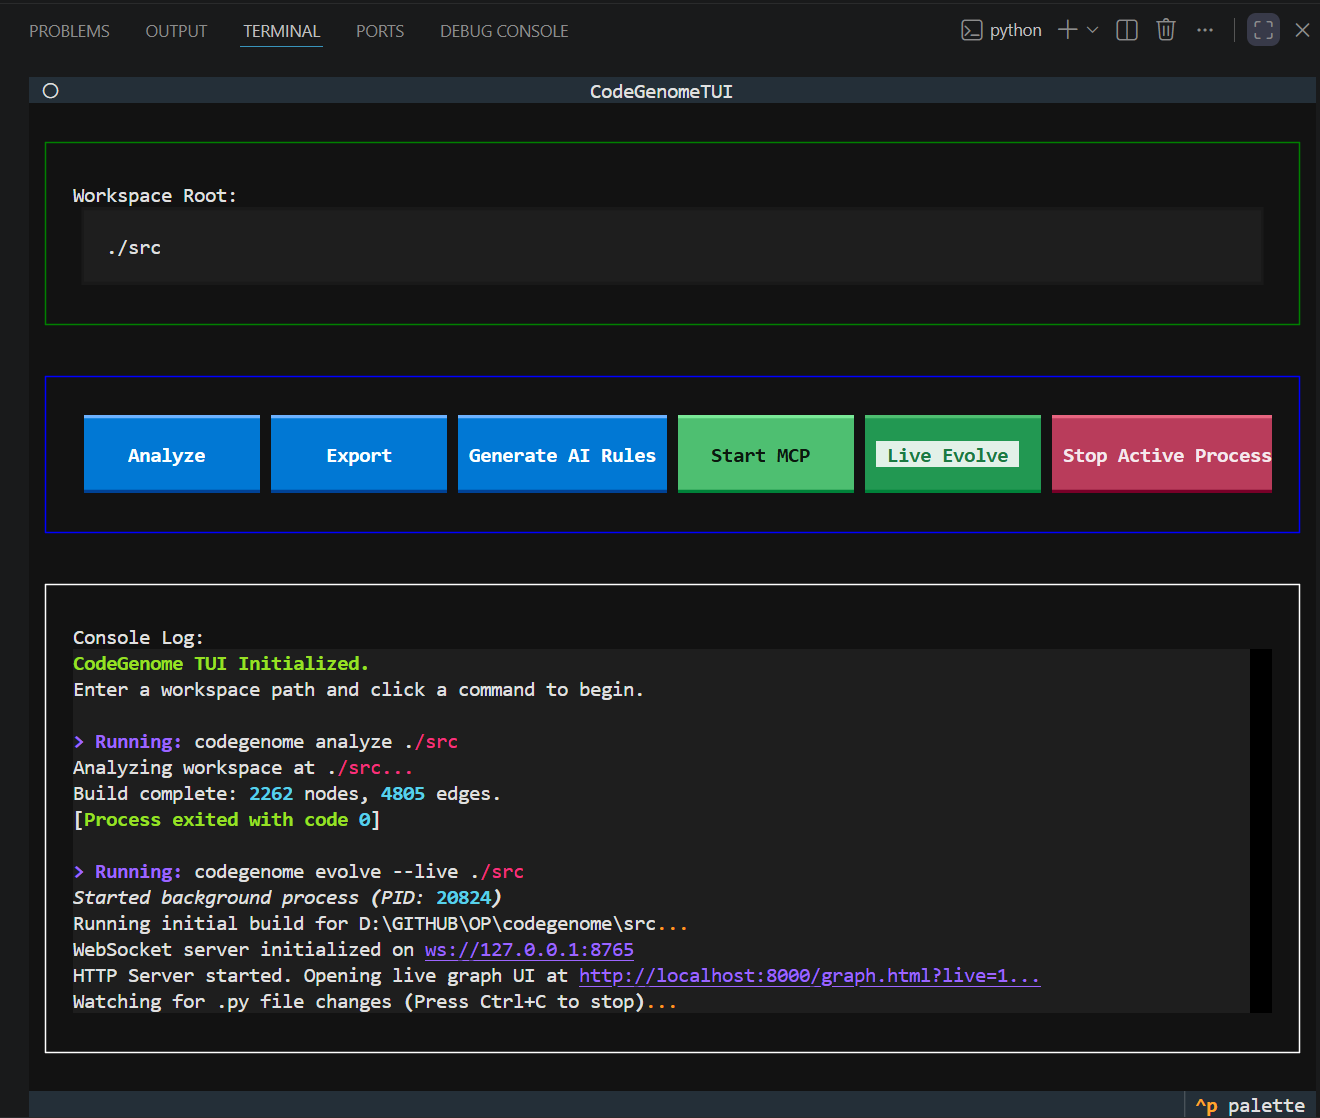
### 🖥️ Rich Terminal User Interface (TUI) @@ -43,7 +43,7 @@ codegenome tui ```
- Codegenome TUI + Codegenome TUI
### 🤖 Seamless AI Agent Integration via MCP @@ -92,16 +92,16 @@ codegenome evolve --live . | Doc | Description | |-----|-------------| -| 📖 [CLI reference](docs/cli-reference.md) | Flags, workflows, troubleshooting | -| ⚙️ [Installation](docs/installation.md) | pip, venv, MCP setup | -| 🔌 [MCP integration](docs/mcp-integration.md) | Server modes and client installer | -| 🧩 [Extensions](extensions/README.md) | Cursor rules and Copilot templates | +| 📖 [CLI reference](https://github.com/Ogro-Projukti/codegenome/blob/main/docs/cli-reference.md) | Flags, workflows, troubleshooting | +| ⚙️ [Installation](https://github.com/Ogro-Projukti/codegenome/blob/main/docs/installation.md) | pip, venv, MCP setup | +| 🔌 [MCP integration](https://github.com/Ogro-Projukti/codegenome/blob/main/docs/mcp-integration.md) | Server modes and client installer | +| 🧩 [Extensions](https://github.com/Ogro-Projukti/codegenome/blob/main/extensions/README.md) | Cursor rules and Copilot templates | ## ⚖️ License -Codegenome is open-source software licensed under the **[MIT License](LICENSE)**. +Codegenome is open-source software licensed under the **[MIT License](https://github.com/Ogro-Projukti/codegenome/blob/main/LICENSE)**.

- Codegenome Logo + Codegenome Logo
diff --git a/pyproject.toml b/pyproject.toml index 00be4ea..a25e17f 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -4,10 +4,10 @@ build-backend = "setuptools.build_meta" [project] name = "codegenome" -version = "0.1.0" +version = "0.1.1" description = "Open-source CLI for building and querying local codebase knowledge graphs" readme = "README.md" -license = { text = "MIT" } +license = "MIT" requires-python = ">=3.11" authors = [{ name = "Watcher Contributors" }] keywords = ["code-analysis", "knowledge-graph", "mcp", "cli", "tree-sitter"] @@ -15,7 +15,6 @@ classifiers = [ "Development Status :: 3 - Alpha", "Environment :: Console", "Intended Audience :: Developers", - "License :: OSI Approved :: MIT License", "Operating System :: OS Independent", "Programming Language :: Python :: 3", "Programming Language :: Python :: 3.11", diff --git a/src/codegenome/version.py b/src/codegenome/version.py index 831c8ac..a39cb3a 100644 --- a/src/codegenome/version.py +++ b/src/codegenome/version.py @@ -1,3 +1,3 @@ """Version information for the CodeGenome package.""" -__version__ = "0.1.0" +__version__ = "0.1.1" From d822499651be66313f0810f216424003206a691b Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Fri, 29 May 2026 11:41:31 +0600 Subject: [PATCH 06/33] fix + update - dependency issue - added new filter - update the UI - fix mcp server name - refine for v.0.1.3 release --- MANIFEST.in | 4 +++ build.py => build_cli.py | 0 pyproject.toml | 4 +-- src/codegenome/installer.py | 2 +- src/codegenome/templates/graph.html.j2 | 36 +++++++++++++++++++------- src/codegenome/version.py | 2 +- tests/test_imports.py | 2 +- 7 files changed, 35 insertions(+), 15 deletions(-) create mode 100644 MANIFEST.in rename build.py => build_cli.py (100%) diff --git a/MANIFEST.in b/MANIFEST.in new file mode 100644 index 0000000..351b8c6 --- /dev/null +++ b/MANIFEST.in @@ -0,0 +1,4 @@ +include LICENSE +include README.md +recursive-include src/codegenome/assets * +recursive-include src/codegenome/templates * diff --git a/build.py b/build_cli.py similarity index 100% rename from build.py rename to build_cli.py diff --git a/pyproject.toml b/pyproject.toml index a25e17f..bab0103 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -4,7 +4,7 @@ build-backend = "setuptools.build_meta" [project] name = "codegenome" -version = "0.1.1" +version = "0.1.3" description = "Open-source CLI for building and querying local codebase knowledge graphs" readme = "README.md" license = "MIT" @@ -38,11 +38,11 @@ dependencies = [ "jinja2", "websockets", "textual", + "networkx>=3.2,<4", ] [project.optional-dependencies] dev = ["pytest", "pytest-cov", "ruff", "pyinstaller>=6.0,<7"] -compat = ["networkx"] [project.urls] Homepage = "https://github.com/watcher-dev/codegenome" diff --git a/src/codegenome/installer.py b/src/codegenome/installer.py index 5cfddd9..57466d5 100644 --- a/src/codegenome/installer.py +++ b/src/codegenome/installer.py @@ -10,7 +10,7 @@ from pathlib import Path from typing import Any, Literal -SERVER_NAME = "watcher" +SERVER_NAME = "genome" TransportMode = Literal["stdio", "http"] diff --git a/src/codegenome/templates/graph.html.j2 b/src/codegenome/templates/graph.html.j2 index bb59314..4c908b7 100644 --- a/src/codegenome/templates/graph.html.j2 +++ b/src/codegenome/templates/graph.html.j2 @@ -8,6 +8,7 @@ + @@ -528,10 +801,12 @@ ◀ @@ -587,19 +862,24 @@
-
+
+
+
-
-
Graph Legend
+
+
+
Graph Legend
+ +
File / Module
Symbol (Class/Fn)
Import
@@ -610,6 +890,12 @@
+ + @@ -617,6 +903,70 @@ Center Graph
+ + + +
+
+
+ AI Graph Chat + Ask about the current .genome connectome. +
+ +
+
+ +
+
+ + +
+
+ + +
+
+ + +
+
+ + +
+
+ + +
+
Open the panel and load models to begin.
+
+
+
+
+ + +
+
diff --git a/src/codegenome/templates/rules/cursor-rules.mdc b/src/codegenome/templates/rules/cursor-rules.mdc index 5af4731..6796262 100644 --- a/src/codegenome/templates/rules/cursor-rules.mdc +++ b/src/codegenome/templates/rules/cursor-rules.mdc @@ -9,10 +9,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use the native CodeGenome MCP tools provided in your context for all codebase, architecture, dependency, or symbol queries. Do NOT attempt to make HTTP requests to the MCP server. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -24,5 +25,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If the tools are missing or fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/src/codegenome/templates/rules/markdown-instructions.md b/src/codegenome/templates/rules/markdown-instructions.md index d1466c2..3666328 100644 --- a/src/codegenome/templates/rules/markdown-instructions.md +++ b/src/codegenome/templates/rules/markdown-instructions.md @@ -4,10 +4,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use the native CodeGenome MCP tools provided in your context for all codebase, architecture, dependency, or symbol queries. Do NOT attempt to make HTTP requests to the MCP server. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -19,5 +20,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If the tools are missing or fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/src/codegenome/tui.py b/src/codegenome/tui.py index 0f45f92..c375177 100644 --- a/src/codegenome/tui.py +++ b/src/codegenome/tui.py @@ -41,6 +41,11 @@ class ActiveProcess: class CodeGenomeTUI(App): """A Textual app for managing CodeGenome.""" + BINDINGS = [ + ("ctrl+q", "quit_app", "Quit"), + ("ctrl+c", "quit_app", "Quit"), + ] + CSS = """ Screen { layout: vertical; @@ -257,8 +262,6 @@ def compose(self) -> ComposeResult: with Horizontal(classes="command-row"): yield Button("Live Evolve (Local)", id="btn-evolve-local", variant="success") yield Button("Live Evolve (LAN)", id="btn-evolve-lan", variant="success") - yield Button("Stop Active Processes", id="btn-stop", variant="error") - yield Button("Quit", id="btn-quit-main", variant="default") with Container(id="log-container"): with TabbedContent(initial="tab-analyze"): @@ -275,10 +278,15 @@ def compose(self) -> ComposeResult: with Vertical(classes="log-pane"): yield RichLog(id="log-general", markup=True, highlight=True) + with Horizontal(classes="page-actions"): + yield Button("Stop Active Processes", id="btn-stop", variant="error") + yield Button("Quit", id="btn-quit-main", variant="default") + yield Footer() def on_mount(self) -> None: """Called when app starts. Initializes widgets and state.""" + self._workspace_poll_timer = None self.pages = self.query_one(ContentSwitcher) self.workspace_input = self.query_one("#workspace-input", Input) self.workspace_scan_status = self.query_one("#workspace-scan-status", Static) @@ -385,6 +393,25 @@ async def _load_workspace_info(self, path: str) -> None: self._pending_workspace_info = info self.update_workspace_scan_panels(info) + def background_refresh_workspace_info(self) -> None: + """Periodically refresh workspace counts in the background.""" + if getattr(self, "_workspace_path", None) and getattr(self, "pages", None) and self.pages.current == PAGE_MAIN: + self.run_worker( + self._do_background_refresh(self._workspace_path), + exclusive=True, + group="workspace-info-bg", + ) + + async def _do_background_refresh(self, path: str) -> None: + """Fetch updated info without blocking or changing UI state heavily.""" + worker = get_current_worker() + info = await asyncio.to_thread(collect_workspace_info, Path(path)) + if worker.is_cancelled: + return + + # Only update the summary bar to avoid flashing the UI + self.workspace_summary.update(format_workspace_summary(info)) + def on_worker_state_changed(self, event: Worker.StateChanged) -> None: """Re-enable controls and surface workspace scan failures.""" if event.worker.group != "workspace-info": @@ -414,6 +441,9 @@ def enter_main_dashboard(self) -> None: self.workspace_summary.update(format_workspace_summary(info)) self.show_page(PAGE_MAIN) + if getattr(self, "_workspace_poll_timer", None) is None: + self._workspace_poll_timer = self.set_interval(5.0, self.background_refresh_workspace_info) + if not self._main_initialized: self._main_initialized = True self.write_log("general", "[bold green]CodeGenome TUI initialized.[/bold green]") @@ -682,6 +712,10 @@ async def _cleanup_subprocesses(self) -> None: self._subprocesses.clear() self.active_processes.clear() + def action_quit_app(self) -> None: + """Handle quit action from bindings.""" + self.quit_app() + def quit_app(self) -> None: """Stop running subprocesses and exit the TUI.""" self.run_worker( diff --git a/src/codegenome/workspace_info.py b/src/codegenome/workspace_info.py index 524ffda..a848e1e 100644 --- a/src/codegenome/workspace_info.py +++ b/src/codegenome/workspace_info.py @@ -217,7 +217,7 @@ def format_workspace_summary(info: WorkspaceInfo) -> str: return ( f"[bold]Workspace:[/bold] {info.root} " f"[dim]|[/dim] " - f"{file_count} file{'s' if file_count != 1 else ''} in " + f"⏳ [bold cyan]Live Tracking:[/bold cyan] {file_count} file{'s' if file_count != 1 else ''} in " f"{dir_count} director{'ies' if dir_count != 1 else 'y'}" ) diff --git a/tests/test_ai_chat.py b/tests/test_ai_chat.py new file mode 100644 index 0000000..ae39437 --- /dev/null +++ b/tests/test_ai_chat.py @@ -0,0 +1,269 @@ +import json +from pathlib import Path + +from codegenome import ai_chat +from codegenome.ai_chat import build_graph_context, save_provider_key, settings_payload + + +def test_settings_payload_reports_saved_keys_without_exposing_values(tmp_path: Path) -> None: + genome_dir = tmp_path / ".genome" + save_provider_key(genome_dir, "openai", "sk-test") + + payload = settings_payload(genome_dir) + + assert payload["saved"]["openai"] is True + assert "sk-test" not in json.dumps(payload) + + +def test_settings_payload_includes_new_chat_providers(tmp_path: Path) -> None: + payload = settings_payload(tmp_path / ".genome") + + providers = {provider["id"]: provider for provider in payload["providers"]} + + assert list(providers) == ["openai", "google", "groq", "ollama"] + assert providers["openai"]["requires_api_key"] is True + assert providers["google"]["requires_api_key"] is True + assert providers["groq"]["requires_api_key"] is True + assert providers["ollama"]["requires_api_key"] is False + assert "default_base_url" not in providers["ollama"] + + +def test_build_graph_context_includes_selected_node_neighborhood(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "metadata": {"statistics": {"node_count": 2, "edge_count": 1}}, + "nodes": [ + {"id": "a.py", "node_type": "file", "name": "a.py", "is_bridge": True}, + {"id": "b.py", "node_type": "file", "name": "b.py"}, + ], + "edges": [{"source": "a.py", "target": "b.py", "edge_type": "imports"}], + } + ), + encoding="utf-8", + ) + + context = build_graph_context(graph_path, selected_node_id="a.py") + + assert "Selected node:" in context + assert '"id": "a.py"' in context + assert '"direction": "outgoing"' in context + + +def test_build_graph_context_caps_large_payloads(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "nodes": [ + { + "id": f"file_{index}.py", + "node_type": "file", + "name": f"file_{index}.py", + "file_path": "src/" + ("very_long_path/" * 40) + f"file_{index}.py", + "qualified_name": "module." + ("very_long_symbol." * 40) + str(index), + "source": "x" * 5000, + } + for index in range(200) + ], + "edges": [ + { + "source": f"file_{index}.py", + "target": f"file_{index + 1}.py", + "edge_type": "imports", + } + for index in range(199) + ], + } + ), + encoding="utf-8", + ) + + context = build_graph_context(graph_path, selected_node_id="file_0.py") + + assert len(context) <= ai_chat.MAX_CONTEXT_CHARS + 80 + assert "source" not in context + assert "...[truncated]" in context + + +def test_build_graph_context_profiles_change_budget(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "nodes": [ + { + "id": f"file_{index}.py", + "node_type": "file", + "name": f"file_{index}.py", + "file_path": f"src/package/file_{index}.py", + } + for index in range(50) + ], + "edges": [ + { + "source": f"file_{index}.py", + "target": f"file_{index + 1}.py", + "edge_type": "imports", + } + for index in range(49) + ], + } + ), + encoding="utf-8", + ) + + minimal = build_graph_context(graph_path, context_size="minimal") + full = build_graph_context(graph_path, context_size="full") + + assert "- context profile: minimal" in minimal + assert "- context profile: full" in full + assert len(full) > len(minimal) + + +def test_load_models_supports_keyless_ollama(monkeypatch, tmp_path: Path) -> None: + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"models": [{"name": "llama3.2:latest"}, {"model": "codellama:latest"}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + models = ai_chat.load_models(tmp_path / ".genome", "ollama") + + assert calls[0][0] == "http://127.0.0.1:11434/api/tags" + assert models == [ + {"id": "codellama:latest", "label": "codellama:latest"}, + {"id": "llama3.2:latest", "label": "llama3.2:latest"}, + ] + + +def test_load_models_supports_groq(monkeypatch, tmp_path: Path) -> None: + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"data": [{"id": "llama-3.3-70b-versatile"}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + models = ai_chat.load_models(tmp_path / ".genome", "groq", "gsk-test") + + assert calls[0][0] == "https://api.groq.com/openai/v1/models" + assert calls[0][1]["headers"]["Authorization"] == "Bearer gsk-test" + assert models == [ + {"id": "llama-3.3-70b-versatile", "label": "llama-3.3-70b-versatile"} + ] + + +def test_request_json_adds_provider_friendly_headers(monkeypatch) -> None: + captured = {} + + class FakeResponse: + def __enter__(self): + return self + + def __exit__(self, exc_type, exc, traceback): + return False + + def read(self): + return b"{}" + + def fake_urlopen(request, timeout): + captured["headers"] = dict(request.header_items()) + captured["timeout"] = timeout + return FakeResponse() + + monkeypatch.setattr(ai_chat.urllib.request, "urlopen", fake_urlopen) + + ai_chat._request_json( + "https://api.groq.com/openai/v1/models", + headers={"Authorization": "Bearer gsk-test"}, + ) + + assert captured["headers"]["User-agent"].startswith("CodeGenome/") + assert captured["headers"]["Accept"] == "application/json" + assert captured["headers"]["Authorization"] == "Bearer gsk-test" + + +def test_chat_completion_supports_ollama_payload(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"message": {"content": "Local answer"}} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + answer = ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "ollama", + "llama3.2:latest", + [{"role": "user", "content": "What changed?"}], + ) + + assert answer == "Local answer" + assert calls[0][0] == "http://127.0.0.1:11434/api/chat" + assert calls[0][1]["payload"]["stream"] is False + assert calls[0][1]["payload"]["options"]["num_predict"] == ai_chat.MAX_RESPONSE_TOKENS + + +def test_chat_completion_caps_openai_compatible_output(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"choices": [{"message": {"content": "Answer"}}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + answer = ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "groq", + "llama-3.3-70b-versatile", + [{"role": "user", "content": "Which files should split?"}], + "gsk-test", + ) + + assert answer == "Answer" + assert calls[0][1]["payload"]["max_tokens"] == ai_chat.MAX_RESPONSE_TOKENS + assert "- context profile: small" in calls[0][1]["payload"]["messages"][1]["content"] + + +def test_chat_completion_uses_requested_context_profile(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"choices": [{"message": {"content": "Answer"}}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "openai", + "gpt-4o-mini", + [{"role": "user", "content": "Use more context"}], + "sk-test", + context_size="full", + ) + + context = calls[0][1]["payload"]["messages"][1]["content"] + assert "- context profile: full" in context From 32e5b69c7d0a0f9e09298dbc0ec7a31477d78b9b Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Mon, 1 Jun 2026 00:09:25 +0600 Subject: [PATCH 23/33] ai feature updated ollama cloud provider added and a new Max context catagory --- src/codegenome/ai_chat.py | 104 ++++++++++++++++++++----- src/codegenome/templates/graph.html.j2 | 48 +++++++++--- tests/test_ai_chat.py | 79 ++++++++++++++++++- 3 files changed, 201 insertions(+), 30 deletions(-) diff --git a/src/codegenome/ai_chat.py b/src/codegenome/ai_chat.py index f4a990e..e6752ca 100644 --- a/src/codegenome/ai_chat.py +++ b/src/codegenome/ai_chat.py @@ -41,6 +41,13 @@ "models_url": "http://127.0.0.1:11434/api/tags", "chat_url": "http://127.0.0.1:11434/api/chat", }, + "ollama_cloud": { + "label": "Ollama Cloud", + "api_style": "ollama", + "requires_api_key": True, + "models_url": "https://ollama.com/api/tags", + "chat_url": "https://ollama.com/api/chat", + }, } CONFIG_FILENAME = "ai-chat.json" @@ -52,10 +59,46 @@ MAX_RESPONSE_TOKENS = 900 DEFAULT_CONTEXT_SIZE = "small" CONTEXT_PROFILES = { - "full": {"nodes": 40, "edges": 96, "neighbors": 24, "chars": 16_000, "value_chars": 240}, - "medium": {"nodes": 16, "edges": 32, "neighbors": 12, "chars": 8_000, "value_chars": 180}, - "small": {"nodes": 8, "edges": 16, "neighbors": 6, "chars": 4_000, "value_chars": 140}, - "minimal": {"nodes": 4, "edges": 8, "neighbors": 3, "chars": 1_800, "value_chars": 100}, + "max": { + "nodes": 120, + "import_edges": 1_000, + "edges": 240, + "neighbors": 48, + "chars": 60_000, + "value_chars": 320, + }, + "full": { + "nodes": 40, + "import_edges": 256, + "edges": 96, + "neighbors": 24, + "chars": 16_000, + "value_chars": 240, + }, + "medium": { + "nodes": 16, + "import_edges": 96, + "edges": 32, + "neighbors": 12, + "chars": 8_000, + "value_chars": 180, + }, + "small": { + "nodes": 8, + "import_edges": 32, + "edges": 16, + "neighbors": 6, + "chars": 4_000, + "value_chars": 140, + }, + "minimal": { + "nodes": 4, + "import_edges": 12, + "edges": 8, + "neighbors": 3, + "chars": 1_800, + "value_chars": 100, + }, } DEFAULT_HTTP_HEADERS = { "Accept": "application/json", @@ -117,8 +160,13 @@ def load_models( for model in payload.get("models", []) if "generateContent" in model.get("supportedGenerationMethods", []) ] - elif request.provider == "ollama": - payload = _request_json(PROVIDERS[request.provider]["models_url"], headers={}) + elif PROVIDERS[request.provider].get("api_style") == "ollama": + headers = ( + _provider_headers(request.provider, request.api_key) + if PROVIDERS[request.provider].get("requires_api_key", True) + else {} + ) + payload = _request_json(PROVIDERS[request.provider]["models_url"], headers=headers) models = [ model.get("model") or model.get("name", "") for model in payload.get("models", []) @@ -231,7 +279,7 @@ def chat_completion( response = _request_json( PROVIDERS[request.provider]["chat_url"], method="POST", - headers={"Content-Type": "application/json"}, + headers=_ollama_headers(request), payload=payload, timeout=90, ) @@ -300,8 +348,22 @@ def build_graph_context( sort_keys=True, ), "", - "Important nodes:", ] + + import_edges = [edge for edge in edges if edge.get("edge_type") == "imports"] + if import_edges: + lines.append("Import edges:") + for edge in import_edges[: int(profile["import_edges"])]: + lines.append( + "- " + + json.dumps( + _compact_edge_context(edge, int(profile["value_chars"])), + sort_keys=True, + ) + ) + lines.append("") + + lines.append("Important nodes:") for node in ranked[: int(profile["nodes"])]: lines.append( "- " @@ -341,17 +403,7 @@ def build_graph_context( lines.append("") lines.append("Representative edges:") for edge in edges[: int(profile["edges"])]: - lines.append( - "- " - + json.dumps( - { - "source": _truncate_context_value(edge.get("source"), int(profile["value_chars"])), - "target": _truncate_context_value(edge.get("target"), int(profile["value_chars"])), - "edge_type": edge.get("edge_type"), - }, - sort_keys=True, - ) - ) + lines.append("- " + json.dumps(_compact_edge_context(edge, int(profile["value_chars"])), sort_keys=True)) context = _fit_context_lines(lines, int(profile["chars"])) if len(context) < len("\n".join(lines)): @@ -403,6 +455,12 @@ def _provider_headers(provider: str, api_key: str) -> dict[str, str]: } +def _ollama_headers(request: ProviderRequest) -> dict[str, str]: + if PROVIDERS[request.provider].get("requires_api_key", True): + return _provider_headers(request.provider, request.api_key) + return {"Content-Type": "application/json"} + + def _request_json( url: str, *, @@ -490,6 +548,14 @@ def _compact_node_context( } +def _compact_edge_context(edge: dict[str, Any], value_chars: int) -> dict[str, Any]: + return { + "source": _truncate_context_value(edge.get("source"), value_chars), + "target": _truncate_context_value(edge.get("target"), value_chars), + "edge_type": edge.get("edge_type"), + } + + def _truncate_context_value(value: Any, max_chars: int = MAX_CONTEXT_VALUE_CHARS) -> Any: if not isinstance(value, str) or len(value) <= max_chars: return value diff --git a/src/codegenome/templates/graph.html.j2 b/src/codegenome/templates/graph.html.j2 index 61f391c..ae88fbb 100644 --- a/src/codegenome/templates/graph.html.j2 +++ b/src/codegenome/templates/graph.html.j2 @@ -627,6 +627,12 @@ letter-spacing: 0.06em; } + .ai-helper-text { + color: var(--text-secondary); + font-size: 11px; + line-height: 1.4; + } + .ai-field select, .ai-field input, .ai-chat-compose textarea { @@ -936,12 +942,14 @@
- + + + + + +
@@ -998,6 +1006,13 @@ messages: [], busy: false }; + const aiContextHelp = { + minimal: 'Minimal sends up to 4 important nodes, 12 import edges, 8 representative edges, and 3 selected-node neighbors.', + small: 'Small sends up to 8 important nodes, 32 import edges, 16 representative edges, and 6 selected-node neighbors.', + medium: 'Medium sends up to 16 important nodes, 96 import edges, 32 representative edges, and 12 selected-node neighbors.', + full: 'Full sends up to 40 important nodes, 256 import edges, 96 representative edges, and 24 selected-node neighbors.', + max: 'MAX sends up to 120 important nodes, 1000 import edges, 240 representative edges, and 48 selected-node neighbors.' + }; function calculateMetrics() { graphMetrics.clear(); @@ -1465,6 +1480,8 @@ renderAiSavedHint(); resetAiModels(); }); + document.getElementById('ai-context-size').addEventListener('change', renderAiContextHelp); + renderAiContextHelp(); try { const response = await fetch('/ai/settings', { cache: 'no-store' }); @@ -1490,7 +1507,8 @@ option.textContent = provider.label; providerSelect.appendChild(option); }); - providerSelect.value = settings.default_provider || 'openai'; + const defaultProvider = settings.default_provider || 'openai'; + providerSelect.value = aiState.providersById.has(defaultProvider) ? defaultProvider : 'openai'; renderAiProviderFields(); } @@ -1502,13 +1520,16 @@ const saveRow = document.getElementById('ai-save-row'); const saveKey = document.getElementById('ai-save-key'); + keyField.style.display = 'flex'; if (provider.requires_api_key === false) { - keyField.style.display = 'none'; + keyInput.disabled = true; + keyInput.value = ''; + keyInput.placeholder = 'Not required for local Ollama'; saveRow.querySelector('label').style.display = 'none'; saveKey.checked = false; - keyInput.value = ''; } else { - keyField.style.display = 'flex'; + keyInput.disabled = false; + keyInput.placeholder = 'Use a saved key or paste one for this session'; saveRow.querySelector('label').style.display = 'inline-flex'; } } @@ -1524,6 +1545,15 @@ setAiStatus(saved ? 'Saved key available for this provider.' : 'Enter an API key, then load models.'); } + function renderAiContextHelp() { + const select = document.getElementById('ai-context-size'); + const helper = document.getElementById('ai-context-help'); + if (!select || !helper) return; + const message = aiContextHelp[select.value] || aiContextHelp.small; + helper.textContent = message; + helper.title = `${message} Data comes from the current .genome graph export.`; + } + function resetAiModels() { const modelSelect = document.getElementById('ai-model'); modelSelect.innerHTML = ''; diff --git a/tests/test_ai_chat.py b/tests/test_ai_chat.py index ae39437..ac0ff8d 100644 --- a/tests/test_ai_chat.py +++ b/tests/test_ai_chat.py @@ -20,11 +20,12 @@ def test_settings_payload_includes_new_chat_providers(tmp_path: Path) -> None: providers = {provider["id"]: provider for provider in payload["providers"]} - assert list(providers) == ["openai", "google", "groq", "ollama"] + assert list(providers) == ["openai", "google", "groq", "ollama", "ollama_cloud"] assert providers["openai"]["requires_api_key"] is True assert providers["google"]["requires_api_key"] is True assert providers["groq"]["requires_api_key"] is True assert providers["ollama"]["requires_api_key"] is False + assert providers["ollama_cloud"]["requires_api_key"] is True assert "default_base_url" not in providers["ollama"] @@ -85,7 +86,7 @@ def test_build_graph_context_caps_large_payloads(tmp_path: Path) -> None: context = build_graph_context(graph_path, selected_node_id="file_0.py") assert len(context) <= ai_chat.MAX_CONTEXT_CHARS + 80 - assert "source" not in context + assert "Import edges:" in context assert "...[truncated]" in context @@ -125,6 +126,37 @@ def test_build_graph_context_profiles_change_budget(tmp_path: Path) -> None: assert len(full) > len(minimal) +def test_build_graph_context_max_profile_includes_more_import_edges(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "nodes": [ + {"id": f"file_{index}.py", "node_type": "file", "name": f"file_{index}.py"} + for index in range(30) + ], + "edges": [ + { + "source": f"file_{index}.py", + "target": f"import:file_{index}.py:1:dep_{index}", + "edge_type": "imports", + } + for index in range(30) + ], + } + ), + encoding="utf-8", + ) + + minimal = build_graph_context(graph_path, context_size="minimal") + max_context = build_graph_context(graph_path, context_size="max") + + assert "- context profile: max" in max_context + assert "Import edges:" in max_context + assert max_context.count('"edge_type": "imports"') > minimal.count('"edge_type": "imports"') + + def test_load_models_supports_keyless_ollama(monkeypatch, tmp_path: Path) -> None: calls = [] @@ -143,6 +175,22 @@ def fake_request_json(url, **kwargs): ] +def test_load_models_supports_ollama_cloud(monkeypatch, tmp_path: Path) -> None: + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"models": [{"model": "gpt-oss:120b"}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + models = ai_chat.load_models(tmp_path / ".genome", "ollama_cloud", "ollama-key") + + assert calls[0][0] == "https://ollama.com/api/tags" + assert calls[0][1]["headers"]["Authorization"] == "Bearer ollama-key" + assert models == [{"id": "gpt-oss:120b", "label": "gpt-oss:120b"}] + + def test_load_models_supports_groq(monkeypatch, tmp_path: Path) -> None: calls = [] @@ -217,6 +265,33 @@ def fake_request_json(url, **kwargs): assert calls[0][1]["payload"]["options"]["num_predict"] == ai_chat.MAX_RESPONSE_TOKENS +def test_chat_completion_supports_ollama_cloud_auth(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"message": {"content": "Cloud answer"}} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + answer = ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "ollama_cloud", + "gpt-oss:120b", + [{"role": "user", "content": "What changed?"}], + "ollama-key", + ) + + assert answer == "Cloud answer" + assert calls[0][0] == "https://ollama.com/api/chat" + assert calls[0][1]["headers"]["Authorization"] == "Bearer ollama-key" + assert calls[0][1]["payload"]["stream"] is False + + def test_chat_completion_caps_openai_compatible_output(monkeypatch, tmp_path: Path) -> None: graph_path = tmp_path / ".genome" / "graph.json" graph_path.parent.mkdir() From 26aab05933eb20229203c5df379438e638125c1a Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Mon, 1 Jun 2026 00:26:02 +0600 Subject: [PATCH 24/33] fix mcp tools extended and fixed --- src/codegenome/graph_store.py | 76 ++++++++++++++++++++++++++--- src/codegenome/intelligence.py | 87 ++++++++++++++++++++++++++++++++-- src/codegenome/mcp_server.py | 29 +++++++++--- tests/test_intelligence.py | 61 ++++++++++++++++++++++++ tests/test_mcp_server.py | 43 +++++++++++++++++ 5 files changed, 280 insertions(+), 16 deletions(-) diff --git a/src/codegenome/graph_store.py b/src/codegenome/graph_store.py index 480ac48..cfbd9a5 100644 --- a/src/codegenome/graph_store.py +++ b/src/codegenome/graph_store.py @@ -28,10 +28,12 @@ class GraphSummary: empty (bool): Indicates whether the snapshot contains any nodes. """ snapshot_id: int | None + latest_snapshot_id: int | None node_count: int edge_count: int label: str | None empty: bool + current: bool class GraphStore: @@ -101,6 +103,40 @@ def open(self) -> None: self._snapshot_label = latest.label self._intelligence = GraphIntelligence(self._graph) + def refresh_latest(self) -> bool: + """Load the newest timeline snapshot if it changed after startup. + + Returns: + bool: True when a newer snapshot was loaded. + """ + if self._timeline is None: + raise GraphStoreError("Timeline database is not open") + + snapshots = self._timeline.list_snapshots() + if not snapshots: + changed = self._snapshot_id is not None or not self.is_empty + self._graph = create_graph("igraph") + self._snapshot_id = None + self._snapshot_label = None + self._intelligence = GraphIntelligence(self._graph) + return changed + + latest = snapshots[-1] + if latest.snapshot_id == self._snapshot_id: + return False + + try: + self._graph = self._timeline.load_snapshot(latest.snapshot_id) + except sqlite3.Error as exc: + raise GraphStoreError( + f"Failed to load snapshot {latest.snapshot_id}: {exc}" + ) from exc + + self._snapshot_id = latest.snapshot_id + self._snapshot_label = latest.label + self._intelligence = GraphIntelligence(self._graph) + return True + def close(self) -> None: """Closes the connection to the timeline database.""" if self._timeline is not None: @@ -113,12 +149,15 @@ def summary(self) -> GraphSummary: Returns: GraphSummary: High-level metrics for the current graph state. """ + latest_snapshot_id = self._latest_snapshot_id() return GraphSummary( snapshot_id=self._snapshot_id, + latest_snapshot_id=latest_snapshot_id, node_count=self._graph.number_of_nodes(), edge_count=self._graph.number_of_edges(), label=self._snapshot_label, empty=self.is_empty, + current=self._snapshot_id == latest_snapshot_id, ) def get_graph( @@ -141,6 +180,8 @@ def get_graph( summary = self.summary() payload: dict[str, Any] = { "snapshot_id": summary.snapshot_id, + "latest_snapshot_id": summary.latest_snapshot_id, + "current": summary.current, "label": summary.label, "node_count": summary.node_count, "edge_count": summary.edge_count, @@ -328,13 +369,21 @@ def get_timeline( ] return payload - def get_dead_code(self) -> list[str]: + def get_dead_code( + self, + *, + include_generated: bool = False, + include_public_api: bool = False, + ) -> list[str]: """Detects likely dead code by finding unreferenced symbols. Returns: list[str]: A list of node IDs corresponding to unreferenced symbols. """ - return self._require_intelligence().detect_dead_code() + return self._require_intelligence().detect_dead_code( + include_generated=include_generated, + include_public_api=include_public_api, + ) def get_entry_points(self) -> list[str]: """Detects entry points to the application (e.g., main scripts, public API). @@ -344,7 +393,7 @@ def get_entry_points(self) -> list[str]: """ return self._require_intelligence().detect_entry_points() - def get_god_nodes(self) -> list[dict[str, Any]]: + def get_god_nodes(self, *, include_generated: bool = False) -> list[dict[str, Any]]: """Identifies highly connected or overly complex nodes (God Nodes). Returns: @@ -352,7 +401,9 @@ def get_god_nodes(self) -> list[dict[str, Any]]: """ return [ {"node_id": node_id, "score": score} - for node_id, score in self._require_intelligence().detect_god_nodes() + for node_id, score in self._require_intelligence().detect_god_nodes( + include_generated=include_generated + ) ] def get_circular_deps(self) -> list[list[str]]: @@ -363,7 +414,12 @@ def get_circular_deps(self) -> list[list[str]]: """ return self._require_intelligence().detect_circular_dependencies() - def get_complexity(self, *, limit: int = 25) -> list[dict[str, Any]]: + def get_complexity( + self, + *, + limit: int = 25, + include_generated: bool = False, + ) -> list[dict[str, Any]]: """Ranks nodes by their computed complexity score. Args: @@ -377,7 +433,9 @@ def get_complexity(self, *, limit: int = 25) -> list[dict[str, Any]]: """ if limit <= 0: raise ValueError("limit must be a positive integer") - rankings = self._require_intelligence().complexity_rankings()[:limit] + rankings = self._require_intelligence().complexity_rankings( + include_generated=include_generated + )[:limit] return [{"node_id": node_id, "complexity": score} for node_id, score in rankings] def get_churn( @@ -486,6 +544,12 @@ def _serialize_edges(self, *, limit: int) -> list[dict[str, Any]]: break return edges + def _latest_snapshot_id(self) -> int | None: + if self._timeline is None: + return self._snapshot_id + snapshots = self._timeline.list_snapshots() + return snapshots[-1].snapshot_id if snapshots else None + @staticmethod def _snapshot_info_dict(info: SnapshotInfo) -> dict[str, Any]: return { diff --git a/src/codegenome/intelligence.py b/src/codegenome/intelligence.py index 8b27ee5..583f45a 100644 --- a/src/codegenome/intelligence.py +++ b/src/codegenome/intelligence.py @@ -50,6 +50,33 @@ class GraphIntelligence: ENTRY_FILE_NAMES = frozenset( {"__main__.py", "main.py", "app.py", "index.js", "index.ts", "index.tsx"} ) + GENERATED_PATH_PARTS = frozenset( + { + ".cache", + ".mypy_cache", + ".pytest_cache", + ".ruff_cache", + ".tox", + ".venv", + "build", + "coverage", + "dist", + "node_modules", + "site-packages", + "vendor", + "vendors", + "venv", + } + ) + GENERATED_FILE_SUFFIXES = ( + ".bundle.css", + ".bundle.js", + ".generated.css", + ".generated.js", + ".map", + ".min.css", + ".min.js", + ) def __init__( self, @@ -86,7 +113,12 @@ def analyze(self) -> IntelligenceReport: churn_rankings=self.churn_rankings(), ) - def detect_dead_code(self) -> list[str]: + def detect_dead_code( + self, + *, + include_generated: bool = False, + include_public_api: bool = False, + ) -> list[str]: """Detect functions and methods that are never called. Returns: @@ -100,8 +132,15 @@ def detect_dead_code(self) -> list[str]: for node, attrs in self.graph.iter_nodes(): if attrs.get("node_type") != "symbol": continue + if not include_generated and self._is_generated_or_vendor(attrs): + continue if attrs.get("kind") not in {"function", "method"}: continue + name = str(attrs.get("name", "")) + if self._is_dunder_name(name): + continue + if not include_public_api and self._is_public_api_method(attrs): + continue if node in entry_symbols: continue if any( @@ -142,7 +181,11 @@ def detect_circular_dependencies(self) -> list[list[str]]: cycles.sort(key=lambda cycle: (len(cycle), cycle)) return cycles - def detect_god_nodes(self) -> list[tuple[str, float]]: + def detect_god_nodes( + self, + *, + include_generated: bool = False, + ) -> list[tuple[str, float]]: """Identify nodes with excessively high degrees (god nodes). Returns: @@ -153,6 +196,8 @@ def detect_god_nodes(self) -> list[tuple[str, float]]: for node, attrs in self.graph.iter_nodes(): if attrs.get("node_type") not in {"file", "symbol"}: continue + if not include_generated and self._is_generated_or_vendor(attrs): + continue in_degree = self.graph.in_degree(node) out_degree = self.graph.out_degree(node) @@ -235,7 +280,11 @@ def detect_orphan_modules(self) -> list[str]: orphans.append(path) return sorted(orphans) - def complexity_rankings(self) -> list[tuple[str, int]]: + def complexity_rankings( + self, + *, + include_generated: bool = False, + ) -> list[tuple[str, int]]: """Rank symbols based on their cyclomatic complexity. Returns: @@ -246,6 +295,8 @@ def complexity_rankings(self) -> list[tuple[str, int]]: for node, attrs in self.graph.iter_nodes(): if attrs.get("node_type") != "symbol": continue + if not include_generated and self._is_generated_or_vendor(attrs): + continue complexity = attrs.get("complexity") if complexity is None: continue @@ -431,6 +482,36 @@ def _resolve_module_to_file( return module_index[PathLike(candidate).stem] return None + def _is_generated_or_vendor(self, attrs: dict[str, object]) -> bool: + path = str(attrs.get("file_path") or attrs.get("absolute_path") or "") + if not path: + return False + + normalized = path.replace("\\", "/").casefold() + parts = {part for part in normalized.split("/") if part} + if parts & self.GENERATED_PATH_PARTS: + return True + + name = PathLike(normalized).name + return name.endswith(self.GENERATED_FILE_SUFFIXES) + + @staticmethod + def _is_dunder_name(name: str) -> bool: + return len(name) > 4 and name.startswith("__") and name.endswith("__") + + @staticmethod + def _is_public_api_method(attrs: dict[str, object]) -> bool: + name = str(attrs.get("name", "")) + if not name or name.startswith("_"): + return False + + qname = str(attrs.get("qualified_name") or "") + if "." not in qname: + return False + + owner = qname.rsplit(".", 1)[0].rsplit(".", 1)[-1] + return bool(owner) and owner[:1].isupper() and not owner.startswith("_") + class PathLike: """Minimal path helper to avoid importing pathlib in hot loops. diff --git a/src/codegenome/mcp_server.py b/src/codegenome/mcp_server.py index dee5ae5..dfb5c9a 100644 --- a/src/codegenome/mcp_server.py +++ b/src/codegenome/mcp_server.py @@ -229,6 +229,7 @@ def shutdown(self) -> None: def _invoke(self, fn: Callable[..., Any], *args: Any, **kwargs: Any) -> Any: with self._lock: + self._store.refresh_latest() return fn(*args, **kwargs) def run(self, fn: Callable[..., Any], *args: Any, **kwargs: Any) -> Any: @@ -457,13 +458,15 @@ def wrapper(*args: Any, **kwargs: Any) -> dict[str, Any]: @mcp.custom_route("/health", methods=["GET"], include_in_schema=False) async def health(_request: Request) -> JSONResponse: - summary = service.store.summary() + summary = service.run(service.store.summary) payload = { "status": "ok", "service": "watcher-mcp", "version": __version__, "db_path": str(service.config.db_path), "snapshot_id": summary.snapshot_id, + "latest_snapshot_id": summary.latest_snapshot_id, + "current": summary.current, "node_count": summary.node_count, "edge_count": summary.edge_count, "empty": summary.empty, @@ -547,9 +550,15 @@ def get_timeline(node_id: str | None = None) -> dict[str, Any]: @mcp.tool @guarded_tool - def get_dead_code() -> dict[str, Any]: + def get_dead_code( + include_generated: bool = False, + include_public_api: bool = False, + ) -> dict[str, Any]: """Detect likely dead code symbols.""" - return service.store.get_dead_code() + return service.store.get_dead_code( + include_generated=include_generated, + include_public_api=include_public_api, + ) @mcp.tool @guarded_tool @@ -559,9 +568,9 @@ def get_entry_points() -> dict[str, Any]: @mcp.tool @guarded_tool - def get_god_nodes() -> dict[str, Any]: + def get_god_nodes(include_generated: bool = False) -> dict[str, Any]: """Return highly connected god nodes.""" - return service.store.get_god_nodes() + return service.store.get_god_nodes(include_generated=include_generated) @mcp.tool @guarded_tool @@ -571,9 +580,15 @@ def get_circular_deps() -> dict[str, Any]: @mcp.tool @guarded_tool - def get_complexity(limit: int = 25) -> dict[str, Any]: + def get_complexity( + limit: int = 25, + include_generated: bool = False, + ) -> dict[str, Any]: """Return top complexity-ranked symbols.""" - return service.store.get_complexity(limit=limit) + return service.store.get_complexity( + limit=limit, + include_generated=include_generated, + ) @mcp.tool @guarded_tool diff --git a/tests/test_intelligence.py b/tests/test_intelligence.py index bbb700f..937ff0a 100644 --- a/tests/test_intelligence.py +++ b/tests/test_intelligence.py @@ -158,6 +158,67 @@ def test_intelligence_rankings() -> None: assert churn[0] == (file_node_id("rank.py"), 3) +def test_intelligence_filters_generated_complexity_by_default() -> None: + graph = create_graph("igraph") + graph.add_node( + "symbol:src/app.py:hard", + node_type="symbol", + file_path="src/app.py", + name="hard", + qualified_name="hard", + kind="function", + complexity=5, + ) + graph.add_node( + "symbol:src/assets/vendor.min.js:a", + node_type="symbol", + file_path="src/assets/vendor.min.js", + name="a", + qualified_name="a", + kind="function", + complexity=99, + ) + + intelligence = GraphIntelligence(graph) + + assert intelligence.complexity_rankings()[0] == ("symbol:src/app.py:hard", 5) + assert intelligence.complexity_rankings(include_generated=True)[0] == ( + "symbol:src/assets/vendor.min.js:a", + 99, + ) + + +def test_intelligence_filters_public_api_methods_from_dead_code_by_default() -> None: + graph = create_graph("igraph") + graph.add_node( + "symbol:src/codegenome/graph_api.py:Graph.add_node", + node_type="symbol", + file_path="src/codegenome/graph_api.py", + name="add_node", + qualified_name="Graph.add_node", + kind="method", + complexity=1, + ) + graph.add_node( + "symbol:src/codegenome/graph_api.py:Graph._unused_helper", + node_type="symbol", + file_path="src/codegenome/graph_api.py", + name="_unused_helper", + qualified_name="Graph._unused_helper", + kind="method", + complexity=1, + ) + + intelligence = GraphIntelligence(graph) + + assert intelligence.detect_dead_code() == [ + "symbol:src/codegenome/graph_api.py:Graph._unused_helper" + ] + assert "symbol:src/codegenome/graph_api.py:Graph.add_node" in ( + intelligence.detect_dead_code(include_public_api=True) + ) + + def test_intelligence_detects_entry_points() -> None: alpha = ParseResult(path="alpha.py", language="python") alpha.symbols = [ diff --git a/tests/test_mcp_server.py b/tests/test_mcp_server.py index 467e0de..b8cb79a 100644 --- a/tests/test_mcp_server.py +++ b/tests/test_mcp_server.py @@ -137,6 +137,49 @@ def test_graph_service_get_timeline_from_worker_thread(sample_db: Path) -> None: service.shutdown() +def test_graph_service_refreshes_latest_snapshot_before_tool_reads(sample_db: Path) -> None: + config = ServerConfig( + host="127.0.0.1", + port=7331, + db_path=sample_db, + timeout_seconds=5.0, + log_level="INFO", + transport="http", + ) + service = GraphService(config) + service.startup() + try: + updated_graph = create_graph("igraph") + updated_graph.add_node( + "file:alpha.py", + node_type="file", + file_path="alpha.py", + churn=2, + complexity=1, + ) + updated_graph.add_node( + "file:beta.py", + node_type="file", + file_path="beta.py", + churn=1, + complexity=1, + ) + timeline = GraphTimeline(sample_db) + try: + latest_snapshot_id = timeline.record_snapshot(updated_graph, label="updated") + finally: + timeline.close() + + graph = service.run(service.store.get_graph) + + assert graph["snapshot_id"] == latest_snapshot_id + assert graph["latest_snapshot_id"] == latest_snapshot_id + assert graph["current"] is True + assert graph["node_count"] == 2 + finally: + service.shutdown() + + def test_create_server_registers_tools(sample_db: Path) -> None: config = ServerConfig( host="127.0.0.1", From cafa3117fa58464afc2b110646a228f8037e9739 Mon Sep 17 00:00:00 2001 From: "Md. Fatin Shadab Turja" <71595077+FatinShadab@users.noreply.github.com> Date: Mon, 1 Jun 2026 01:08:20 +0600 Subject: [PATCH 25/33] Update graph.html.j2 --- src/codegenome/templates/graph.html.j2 | 74 +++++++++++++++++++++++--- 1 file changed, 67 insertions(+), 7 deletions(-) diff --git a/src/codegenome/templates/graph.html.j2 b/src/codegenome/templates/graph.html.j2 index ae88fbb..1624aa1 100644 --- a/src/codegenome/templates/graph.html.j2 +++ b/src/codegenome/templates/graph.html.j2 @@ -501,8 +501,10 @@ right: 24px; bottom: 24px; z-index: 30; - height: 44px; - min-width: 118px; + width: 48px; + height: 48px; + min-width: 48px; + padding: 0; border-radius: 999px; background: linear-gradient(135deg, rgba(14, 165, 233, 0.95), rgba(59, 130, 246, 0.95)); border: 1px solid rgba(186, 230, 253, 0.35); @@ -510,6 +512,12 @@ box-shadow: 0 10px 30px rgba(2, 6, 23, 0.45), 0 0 20px rgba(14, 165, 233, 0.32); } + .ai-chat-launcher svg { + width: 24px; + height: 24px; + display: block; + } + .ai-chat-panel { position: absolute; right: 24px; @@ -527,6 +535,11 @@ overflow: hidden; } + .ai-chat-panel.ai-expanded { + width: min(900px, calc(100vw - 48px)); + height: min(820px, calc(100vh - 96px)); + } + .ai-hidden { display: none !important; } @@ -562,6 +575,13 @@ font-size: 11px; } + .ai-chat-actions { + display: flex; + align-items: center; + gap: 6px; + flex-shrink: 0; + } + .ai-icon-btn { width: 32px; height: 32px; @@ -569,6 +589,20 @@ border-radius: 8px; } + .ai-icon-btn svg { + width: 15px; + height: 15px; + } + + .ai-collapse-icon, + .ai-chat-panel.ai-expanded .ai-expand-icon { + display: none; + } + + .ai-chat-panel.ai-expanded .ai-collapse-icon { + display: block; + } + .ai-chat-config { border-bottom: 1px solid var(--border-glass); background: rgba(2, 6, 23, 0.34); @@ -783,6 +817,10 @@ width: calc(100vw - 24px); height: min(620px, calc(100vh - 96px)); } + .ai-chat-panel.ai-expanded { + width: calc(100vw - 24px); + height: calc(100vh - 92px); + } .ai-chat-launcher { right: 12px; bottom: 12px; @@ -910,8 +948,11 @@
-
@@ -920,9 +961,19 @@ AI Graph Chat Ask about the current .genome connectome.
- +
+ + +