diff --git a/.cursor/rules/watcher-knowledge-graph.mdc b/.cursor/rules/watcher-knowledge-graph.mdc new file mode 100644 index 0000000..42b7600 --- /dev/null +++ b/.cursor/rules/watcher-knowledge-graph.mdc @@ -0,0 +1,29 @@ +--- +description: CodeGenome knowledge graph and MCP Context +alwaysApply: true +--- + +# CodeGenome MCP Integration + +You are operating within a repository analyzed by CodeGenome, an architectural knowledge graph tool. This project contains a `.genome/` directory. + +## Core Directives + +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:7331/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. + +## Available MCP Capabilities + +- **Discovery**: `search_nodes` (find symbols) +- **Relationships**: `get_neighbors` (imports, callers, callees) +- **Architecture**: `get_entry_points`, `get_dead_code`, `get_circular_deps`, `get_god_nodes` +- **Metrics**: `get_complexity`, `get_churn`, `get_graph` (summary statistics) +- **Evolution**: `get_timeline`, `get_changes` (architectural diffs) + +## Constraints & Behaviors + +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/.github/copilot-instructions.md b/.github/copilot-instructions.md new file mode 100644 index 0000000..b512202 --- /dev/null +++ b/.github/copilot-instructions.md @@ -0,0 +1,24 @@ +# CodeGenome Knowledge Graph (MCP) + +You are operating within a repository analyzed by CodeGenome, an architectural knowledge graph tool. This project contains a `.genome/` directory. + +## Core Directives + +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:7331/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. + +## Available MCP Capabilities + +- **Discovery**: `search_nodes` (find symbols) +- **Relationships**: `get_neighbors` (imports, callers, callees) +- **Architecture**: `get_entry_points`, `get_dead_code`, `get_circular_deps`, `get_god_nodes` +- **Metrics**: `get_complexity`, `get_churn`, `get_graph` (summary statistics) +- **Evolution**: `get_timeline`, `get_changes` (architectural diffs) + +## Constraints & Behaviors + +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/.github/workflows/compatibility.yml b/.github/workflows/compatibility.yml new file mode 100644 index 0000000..f2ca8b0 --- /dev/null +++ b/.github/workflows/compatibility.yml @@ -0,0 +1,41 @@ +name: Compatibility + +on: + push: + branches: ["main"] + pull_request: + +jobs: + install-and-parser-smoke: + name: "${{ matrix.os }} / py${{ matrix.python-version }}" + runs-on: ${{ matrix.os }} + strategy: + fail-fast: false + matrix: + os: [ubuntu-latest, macos-14] + python-version: ["3.11", "3.12", "3.13"] + + steps: + - name: Checkout + uses: actions/checkout@v4 + + - name: Set up Python + uses: actions/setup-python@v5 + with: + python-version: ${{ matrix.python-version }} + + - name: Upgrade build tooling + run: python -m pip install --upgrade pip setuptools wheel + + - name: Install package and test dependencies + run: | + python -m pip install . + python -m pip install pytest + + - name: Parser test suite + run: python -m pytest tests/test_parser.py -q + + - name: CLI smoke test + run: | + codegenome --help + python -c "import codegenome; print(codegenome.__version__)" diff --git a/.gitignore b/.gitignore index f8bde31..f924f6f 100644 --- a/.gitignore +++ b/.gitignore @@ -22,3 +22,5 @@ Thumbs.db .env .env.* *.log + +*.tex diff --git a/.idea/.gitignore b/.idea/.gitignore new file mode 100644 index 0000000..7bc07ec --- /dev/null +++ b/.idea/.gitignore @@ -0,0 +1,10 @@ +# Default ignored files +/shelf/ +/workspace.xml +# Editor-based HTTP Client requests +/httpRequests/ +# Environment-dependent path to Maven home directory +/mavenHomeManager.xml +# Datasource local storage ignored files +/dataSources/ +/dataSources.local.xml diff --git a/.idea/codegenome.iml b/.idea/codegenome.iml new file mode 100644 index 0000000..d6ebd48 --- /dev/null +++ b/.idea/codegenome.iml @@ -0,0 +1,9 @@ + + + + + + + + + \ No newline at end of file diff --git a/.idea/compiler.xml b/.idea/compiler.xml new file mode 100644 index 0000000..a1757ae --- /dev/null +++ b/.idea/compiler.xml @@ -0,0 +1,8 @@ + + + + + + + + \ No newline at end of file diff --git a/.idea/misc.xml b/.idea/misc.xml new file mode 100644 index 0000000..628afae --- /dev/null +++ b/.idea/misc.xml @@ -0,0 +1,6 @@ + + + + + + \ No newline at end of file diff --git a/.idea/modules.xml b/.idea/modules.xml new file mode 100644 index 0000000..f338140 --- /dev/null +++ b/.idea/modules.xml @@ -0,0 +1,8 @@ + + + + + + + + \ No newline at end of file diff --git a/.idea/vcs.xml b/.idea/vcs.xml new file mode 100644 index 0000000..35eb1dd --- /dev/null +++ b/.idea/vcs.xml @@ -0,0 +1,6 @@ + + + + + + \ No newline at end of file diff --git a/.windsurfrules b/.windsurfrules new file mode 100644 index 0000000..b512202 --- /dev/null +++ b/.windsurfrules @@ -0,0 +1,24 @@ +# CodeGenome Knowledge Graph (MCP) + +You are operating within a repository analyzed by CodeGenome, an architectural knowledge graph tool. This project contains a `.genome/` directory. + +## Core Directives + +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:7331/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. + +## Available MCP Capabilities + +- **Discovery**: `search_nodes` (find symbols) +- **Relationships**: `get_neighbors` (imports, callers, callees) +- **Architecture**: `get_entry_points`, `get_dead_code`, `get_circular_deps`, `get_god_nodes` +- **Metrics**: `get_complexity`, `get_churn`, `get_graph` (summary statistics) +- **Evolution**: `get_timeline`, `get_changes` (architectural diffs) + +## Constraints & Behaviors + +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/AGENTS.md b/AGENTS.md new file mode 100644 index 0000000..b512202 --- /dev/null +++ b/AGENTS.md @@ -0,0 +1,24 @@ +# CodeGenome Knowledge Graph (MCP) + +You are operating within a repository analyzed by CodeGenome, an architectural knowledge graph tool. This project contains a `.genome/` directory. + +## Core Directives + +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:7331/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. + +## Available MCP Capabilities + +- **Discovery**: `search_nodes` (find symbols) +- **Relationships**: `get_neighbors` (imports, callers, callees) +- **Architecture**: `get_entry_points`, `get_dead_code`, `get_circular_deps`, `get_god_nodes` +- **Metrics**: `get_complexity`, `get_churn`, `get_graph` (summary statistics) +- **Evolution**: `get_timeline`, `get_changes` (architectural diffs) + +## Constraints & Behaviors + +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/CHANGELOG.md b/CHANGELOG.md new file mode 100644 index 0000000..df3988d --- /dev/null +++ b/CHANGELOG.md @@ -0,0 +1,46 @@ +# Changelog + +All notable changes to Codegenome are documented in this file. + +The format is based on [Keep a Changelog](https://keepachangelog.com/en/1.1.0/), +and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html). + +## [0.1.4] - 2026-06-01 + +### Added + +- **Copyable TUI console outputs** — users can now select text in the log panes and press `Ctrl+C` to copy it to the clipboard. +- **LAN live graph sharing** — `codegenome evolve --live --lan` binds HTTP and WebSocket to `0.0.0.0` so other devices on the same network can open the live graph. The CLI prints a shareable LAN URL (for example `http://192.168.1.42:8000/graph.html?live=1`). +- **TUI MCP HTTP mode controls** — the dashboard now includes separate **Start MCP HTTP (Local)** and **Start MCP HTTP (LAN)** buttons so users can intentionally choose localhost-only or LAN exposure. +- **Git-aware file filtering** — the scanner respects workspace `.gitignore` and `.genomeignore` files, including nested ignore files in subdirectories, negation rules (`!pattern`), and anchored patterns. +- **TUI workspace info page** — after setting a workspace, the TUI shows tracked folders, file extensions, and discovered `.gitignore` files before you run analyze or evolve. +- **TUI live-evolve controls** — buttons for **Live Evolve (Local)**, **Live Evolve (LAN)**, and **Quit** to start or stop background processes from the dashboard. +- **Live graph AI chat** — the HTML graph UI includes an in-browser chat panel backed by OpenAI, Google Gemini, Groq, Ollama (local), and Ollama Cloud. API keys are stored under `.genome/ai-chat.json` and never echoed back to the browser. +- **Graph context profiles for AI chat** — selectable context sizes (`minimal`, `small`, `medium`, `full`, `max`) control how much neighborhood data is sent with each prompt. +- **MCP `query_graph` tool** — filter graph nodes by type, file path prefix, or symbol kind. +- **`codegenome mcp-start --transport` and `--port`** — start the MCP server over stdio (default) or HTTP from the modern CLI and TUI. +- **`pathspec` dependency** — powers gitignore-compatible pattern matching. + +### Changed + +- Default ignore list always excludes `.git/`, `.venv/`, `node_modules/`, `__pycache__/`, `*.pyc`, `.genome/`, and `.genomeignore` in addition to workspace ignore files. +- MCP server refreshes the latest timeline snapshot before tool reads so agents always see current graph data after `analyze` or live evolve. +- `codegenome mcp-start` adds `--lan` for intentional HTTP LAN binding from CLI/TUI workflows. +- Agent instruction templates (`codegenome rules`) now direct agents to use native MCP tools instead of raw HTTP/curl calls. + +### Fixed + +- MCP tool handlers return richer graph intelligence data (dead code, entry points, complexity, churn) with improved filtering for generated assets and public API symbols. +- Agent rules no longer reference misleading HTTP endpoints that caused agents to `curl` the server instead of using MCP transport. +- MCP server keeps localhost-only behavior by default and now requires an explicit remote HTTP opt-in (`--allow-remote-http`) for non-loopback hosts. +- Release lint blockers (unused imports and test lint violations) were resolved so full lint/test/build gates pass before upload. +- Tree-sitter dependency constraints now support Python 3.12+ installations (including macOS Apple Silicon) while preserving legacy pins for Python 3.11 compatibility (fixes [#1](https://github.com/Ogro-Projukti/codegenome/issues/1)). +- Updated tree-sitter `Parser` initialization to support both legacy and modern (`>=0.23`) API signatures without breaking runtime. + +### Documentation + +- CLI reference covers `--lan`, TUI live modes, ignore-rule behavior, and MCP transport options. +- README quick start includes the LAN evolve example. +- Release notes and upgrade instructions in `docs/release-0.1.4.md`. + +[0.1.4]: https://github.com/Ogro-Projukti/codegenome/releases/tag/v0.1.4 diff --git a/CITATION.cff b/CITATION.cff new file mode 100644 index 0000000..86bc87a --- /dev/null +++ b/CITATION.cff @@ -0,0 +1,39 @@ +cff-version: 1.2.0 +message: "If you use this software, please cite it as below." +authors: + - family-names: "Turja" + given-names: "Md. Fatin Shadab" + orcid: "https://orcid.org/0009-0008-0026-2947" + affiliation: "United International University" +title: "CodeGenome" +version: "0.1.4" +date-released: "2026-05-30" +license: "MIT" +repository-code: "https://github.com/Ogro-Projukti/codegenome" +url: "https://codegenome.pages.dev/" +abstract: >- + CodeGenome is an open-source codebase analyzer that treats software architecture + as a connectome—a map of connections between functions, classes, files, and imports. + It builds a project-level dependency graph, provides a higher-level community view + using Leiden community detection, and features real-time updates via a filesystem observer. + An integrated Model Context Protocol (MCP) server lets AI agents query structural + architectural context directly instead of consuming raw source files. +keywords: + - "software-architecture" + - "code-analysis" + - "dependency-graphs" + - "community-detection" + - "model-context-protocol" + - "ai-assisted-development" +preferred-citation: + type: generic + authors: + - family-names: "Turja" + given-names: "Md. Fatin Shadab" + orcid: "https://orcid.org/0009-0008-0026-2947" + affiliation: "United International University" + title: "CodeGenome: A Real-Time Hierarchical Codebase Connectome Engine for AI-Assisted Development" + year: 2026 + medium: "Technical Report" + publisher: "Ogro-Projukti" + url: "https://github.com/Ogro-Projukti/codegenome" diff --git a/CONTRIBUTING.md b/CONTRIBUTING.md new file mode 100644 index 0000000..7a1a6eb --- /dev/null +++ b/CONTRIBUTING.md @@ -0,0 +1,256 @@ +# Contributing to Codegenome + +Thank you for your interest in contributing to [Codegenome](https://github.com/Ogro-Projukti/codegenome). This guide explains how to set up a development environment, run checks locally, and submit changes. + +Codegenome is an open-source Python CLI that builds local codebase knowledge graphs and exposes them to AI agents via MCP. Contributions of all sizes are welcome—bug fixes, tests, documentation, new export formats, parser improvements, and MCP tooling. + +## Table of contents + +- [Ways to help](#ways-to-help) +- [Development setup](#development-setup) +- [Project layout](#project-layout) +- [Running tests](#running-tests) +- [Linting and formatting](#linting-and-formatting) +- [Manual verification](#manual-verification) +- [Making changes](#making-changes) +- [Submitting a pull request](#submitting-a-pull-request) +- [Reporting bugs and requesting features](#reporting-bugs-and-requesting-features) +- [Documentation](#documentation) +- [License](#license) + +## Ways to help + +You do not need to write code to contribute. Useful contributions include: + +- **Bug reports** with clear reproduction steps and environment details +- **Documentation** fixes in `README.md`, `docs/`, or this file +- **Tests** for existing behavior or regressions +- **Parser and graph logic** in `src/codegenome/` +- **CLI and TUI** improvements +- **MCP server and installer** changes +- **Export formats** and graph visualization updates + +Before starting large features, open a [GitHub issue](https://github.com/Ogro-Projukti/codegenome/issues) to discuss the approach and avoid duplicate work. + +## Development setup + +### Requirements + +- **Python 3.11+** (see `requires-python` in `pyproject.toml`) +- **Git** +- A C compiler may be required on some platforms to build `python-igraph` / `leidenalg` + +### Clone and install + +From the repository root: + +```bash +git clone https://github.com/Ogro-Projukti/codegenome.git +cd codegenome + +python -m venv .venv +``` + +Activate the virtual environment: + +```bash +# Windows (PowerShell) +.venv\Scripts\Activate.ps1 + +# macOS / Linux +source .venv/bin/activate +``` + +Install the package in editable mode with development dependencies: + +```bash +pip install -e ".[dev]" +``` + +Verify the install: + +```bash +codegenome --help +python -c "import codegenome; print(codegenome.__version__)" +``` + +For more installation context (PyPI, MCP setup, troubleshooting), see [docs/installation.md](docs/installation.md). + +## Project layout + +```text +codegenome/ +├── src/codegenome/ # Main Python package +│ ├── cli.py # Modern Click CLI (`codegenome analyze`, `export`, `tui`, …) +│ ├── __main__.py # Legacy flag-based CLI (`python -m codegenome --build`) +│ ├── parser.py # tree-sitter parsing +│ ├── builder.py # Graph construction +│ ├── mcp_server.py # MCP server +│ └── … +├── tests/ # pytest test suite +├── docs/ # User-facing documentation +├── extensions/ # Cursor rules and Copilot templates +├── pyproject.toml # Package metadata and tool config +└── build_cli.py # Optional PyInstaller binary build +``` + +Codegenome exposes two CLI surfaces: + +| Entry point | Example | Notes | +|-------------|---------|-------| +| `codegenome` | `codegenome analyze .` | Preferred for new work; subcommand-based | +| `python -m codegenome` | `python -m codegenome --workspace . --build` | Legacy flag-based interface; still supported | + +When adding or changing CLI behavior, prefer extending the Click CLI in `cli.py` unless you are maintaining legacy compatibility in `__main__.py`. + +## Running tests + +All tests live under `tests/` and are configured in `pyproject.toml`. + +Run the full suite: + +```bash +pytest +``` + +Run a single file or test: + +```bash +pytest tests/test_parser.py +pytest tests/test_parser.py::test_some_specific_case -v +``` + +Run with coverage: + +```bash +pytest --cov=codegenome --cov-report=term-missing +``` + +Please add or update tests when you change behavior. The suite should pass before you open a pull request. + +## Linting and formatting + +This project uses [Ruff](https://docs.astral.sh/ruff/) (line length **100**, Python **3.11** target). + +Check for issues: + +```bash +ruff check src tests +``` + +Auto-fix safe issues: + +```bash +ruff check src tests --fix +``` + +Keep new code consistent with surrounding modules. Avoid drive-by refactors in unrelated files. + +## Manual verification + +After functional changes, smoke-test the CLI against a small project directory: + +```bash +# Build a graph +codegenome analyze . + +# Export (requires a prior analyze) +codegenome export --format json --path . + +# Optional: TUI or MCP (see docs/) +codegenome tui +``` + +Graph artifacts are written under `.genome/` in the analyzed workspace. See [docs/cli-reference.md](docs/cli-reference.md) for the full command reference. + +### Optional: standalone binary + +To build a PyInstaller binary (named `watcher` in `dist/`): + +```bash +python build_cli.py +``` + +This requires the `dev` extra (`pyinstaller`). + +## Making changes + +1. **Fork** the repository on GitHub (or create a branch if you have write access). +2. **Create a feature branch** from `main`: + + ```bash + git checkout -b your-topic-branch + ``` + +3. **Make focused changes**—one logical change per pull request when possible. +4. **Update tests and docs** if behavior or public APIs change. +5. **Run checks locally**: + + ```bash + pytest + ruff check src tests + ``` + +6. **Commit** with a clear message describing *why* the change was made. + +If you change the package version, update `src/codegenome/version.py` and any version assertions in tests (for example `tests/test_imports.py`). + +## Submitting a pull request + +1. Push your branch to your fork: + + ```bash + git push -u origin your-topic-branch + ``` + +2. Open a pull request against **`main`** on [Ogro-Projukti/codegenome](https://github.com/Ogro-Projukti/codegenome). + +3. Fill in the PR description with: + - **Summary** — what changed and why + - **Test plan** — commands you ran (e.g. `pytest`, manual CLI steps) + - **Related issues** — link with `Fixes #123` when applicable + +4. Ensure CI checks pass (when available) and respond to review feedback. + +We aim to review pull requests in a timely manner. Smaller, well-tested changes are easier to merge. + +### Pull request checklist + +- [ ] Tests pass locally (`pytest`) +- [ ] Ruff passes on touched code (`ruff check src tests`) +- [ ] New behavior has tests where practical +- [ ] User-facing changes are reflected in `README.md` or `docs/` if needed +- [ ] Commit messages and PR description explain the motivation + +## Reporting bugs and requesting features + +Use [GitHub Issues](https://github.com/Ogro-Projukti/codegenome/issues) and include as much detail as possible: + +- **Environment** — OS, Python version, install method (`pip`, editable, PyPI) +- **Steps to reproduce** — exact commands and a minimal workspace if relevant +- **Expected vs actual behavior** +- **Logs or stack traces** — redact secrets and private paths + +For MCP or client integration problems, also note which client (Cursor, Claude Desktop, etc.) and transport (`stdio` / HTTP). + +## Documentation + +When updating user-facing docs, use **`codegenome`** as the primary CLI name. Document legacy flag-based usage as `python -m codegenome --…`. The on-disk database file remains `.genome/watcher.db`. + +| Document | Purpose | +|----------|---------| +| [README.md](README.md) | Overview and quick start | +| [docs/installation.md](docs/installation.md) | Install and MCP setup | +| [docs/cli-reference.md](docs/cli-reference.md) | Subcommands, legacy flags, workflows | +| [docs/mcp-integration.md](docs/mcp-integration.md) | MCP server and installer | +| [extensions/README.md](extensions/README.md) | Editor rules and templates | + +Improvements to documentation are always appreciated and often the fastest way to help new users. + +## License + +By contributing to Codegenome, you agree that your contributions will be licensed under the [MIT License](LICENSE), the same license that covers the project. + +--- + +Questions? Open an issue or start a discussion on the repository. We appreciate your help making Codegenome better for everyone building with AI-assisted development tools. diff --git a/DEVELOPER_TESTING.md b/DEVELOPER_TESTING.md index f2be1d4..e69de29 100644 --- a/DEVELOPER_TESTING.md +++ b/DEVELOPER_TESTING.md @@ -1,664 +0,0 @@ -# Codegenome Developer Testing Guide - -This guide provides comprehensive instructions for testing **Codegenome** (Watcher CLI) in development mode. - -**Project Overview:** Codegenome is an open-source CLI tool for building and querying local codebase knowledge graphs. It uses tree-sitter for code parsing, stores metadata in SQLite, and exposes graph data through an MCP (Model Context Protocol) server. - ---- - -## Table of Contents - -1. [Environment Setup](#environment-setup) -2. [Installation for Development](#installation-for-development) -3. [Running Tests](#running-tests) -4. [Manual Testing Workflows](#manual-testing-workflows) -5. [Testing MCP Server](#testing-mcp-server) -6. [Debugging Tips](#debugging-tips) -7. [Common Issues](#common-issues) - ---- - -## Environment Setup - -### Prerequisites - -- **Python 3.11+** (3.11, 3.12, or 3.13 supported) -- **Git** for version control -- **pip** for package management - -### Verify Python Installation - -```bash -python --version -# Output should be Python 3.11.x, 3.12.x, or 3.13.x -``` - ---- - -## Installation for Development - -### 1. Clone the Repository - -```bash -git clone https://github.com/Ogro-Projukti/codegenome.git -cd codegenome -``` - -### 2. Create and Activate Virtual Environment - -**Windows:** -```bash -python -m venv .venv -.venv\Scripts\activate -``` - -**macOS/Linux:** -```bash -python -m venv .venv -source .venv/bin/activate -``` - -### 3. Install in Editable Mode with Dev Dependencies - -```bash -pip install -e ".[dev]" -``` - -This installs: -- **Core dependencies:** tree-sitter, networkx, watchdog, fastmcp, radon -- **Dev dependencies:** pytest, pytest-cov, ruff, pyinstaller - -### 4. Verify Installation - -```bash -# Check CLI availability -codegenome --help - -# Or run as module -python -m codegenome --help -``` - -Expected output shows all available commands and flags. - ---- - -## Running Tests - -### Run All Tests - -```bash -pytest -``` - -### Run Tests with Coverage Report - -```bash -pytest --cov=src/codegenome --cov-report=html -``` - -Coverage report is generated in `htmlcov/index.html`. - -### Run Specific Test File - -```bash -pytest tests/test_parser.py -v -pytest tests/test_builder.py -v -pytest tests/test_mcp_server.py -v -``` - -### Run Tests Matching a Pattern - -```bash -# Tests for scanner functionality -pytest -k "scanner" -v - -# Tests for timeline features -pytest -k "timeline" -v -``` - -### Run with Verbose Output - -```bash -pytest -v # Show each test name -pytest -vv # Very verbose with full test output -pytest -v --tb=short # Shorter traceback format -pytest -v --tb=long # Full traceback on failures -``` - -### Run Tests in Parallel (faster) - -```bash -pip install pytest-xdist -pytest -n auto # Uses all available CPU cores -``` - ---- - -## Manual Testing Workflows - -### Workflow 1: Build a Graph from a Repository - -Test the core graph building functionality. - -#### Step 1: Navigate to a Target Repository - -```bash -cd /path/to/test/repository -``` - -Use an existing Python, JavaScript, or Go project (or test on codegenome itself). - -#### Step 2: Build a Full Graph - -```bash -codegenome --workspace . --build --full -``` - -Expected output: -- `.genome/` directory created with: - - `graph.json` — the extracted code graph - - `watcher.db` — SQLite database with metadata - - `build_log.txt` — build summary - -#### Step 3: Verify Output - -```bash -# Check .genome directory was created -ls -la .genome/ - -# View build log -cat .genome/build_log.txt - -# Check graph file size (should be > 100 bytes for non-empty repos) -ls -lh .genome/graph.json -``` - -#### Step 4: Inspect Graph Content (Optional) - -```bash -python ->>> import json ->>> with open('.genome/graph.json') as f: -... graph = json.load(f) ->>> print(f"Nodes: {len(graph.get('nodes', []))}") ->>> print(f"Edges: {len(graph.get('edges', []))}") ->>> exit() -``` - ---- - -### Workflow 2: Export in Multiple Formats - -Test the export functionality. - -#### Step 1: Build and Export - -```bash -# From your test repository directory -codegenome --workspace . --build --export json markdown graphml cypher -``` - -#### Step 2: Verify Exports - -```bash -# Check all export files exist -ls -la .genome/ - -# Should see: -# - graph.json -# - graph.md -# - graph.graphml -# - graph.cypher -# - graph_html/ (directory with interactive viewer) -``` - -#### Step 3: View Markdown Export - -```bash -cat .genome/graph.md | head -50 -``` - -#### Step 4: Test HTML Viewer - -```bash -# Open in browser (path depends on OS) -# Windows: -start .genome/graph_html/index.html - -# macOS: -open .genome/graph_html/index.html - -# Linux: -xdg-open .genome/graph_html/index.html -``` - ---- - -### Workflow 3: Watch Mode (Live Updates) - -Test the file watcher and incremental rebuild. - -#### Step 1: Start Watch Mode - -```bash -# From your test repository -codegenome --workspace . --build --watch -``` - -Expected output: -``` -[...] Starting watch mode... -[...] Watching for changes in: /path/to/repo -``` - -The process should stay running. - -#### Step 2: Make File Changes (In Another Terminal) - -```bash -# Open another terminal, navigate to the same repo -cd /path/to/test/repository - -# Create or modify a file -echo "new_function = lambda x: x + 1" >> test_file.py -``` - -#### Step 3: Verify Incremental Update - -Back in the original terminal, you should see: -``` -[...] Detecting changes... -[...] Incremental rebuild: 1 files changed -[...] Graph updated -``` - -#### Step 4: Stop Watch Mode - -```bash -# Press Ctrl+C in the watch mode terminal -``` - ---- - -### Workflow 4: Timeline Queries - -Test timeline and change history functionality. - -#### Step 1: Build with Timeline - -```bash -# From your test repository -codegenome --workspace . --build --full -``` - -#### Step 2: Dump Timeline - -```bash -codegenome --workspace . --dump-timeline -``` - -Expected output: JSON with timeline metadata, change events, and file churn statistics. - -#### Step 3: Query Timeline Programmatically (Optional) - -```bash -python ->>> from codegenome.timeline import TimelineDB ->>> db = TimelineDB('.genome/watcher.db') ->>> timeline = db.get_timeline() ->>> print(f"Timeline snapshots: {len(timeline.get('snapshots', []))}") ->>> exit() -``` - ---- - -## Testing MCP Server - -The MCP (Model Context Protocol) server allows integration with AI clients like Cursor and Claude. - -### Workflow 1: Start MCP Server in HTTP Mode - -#### Step 1: Build Graph First - -```bash -# From your test repository -codegenome --workspace . --build -``` - -#### Step 2: Start MCP Server - -```bash -# HTTP mode (default) -codegenome --workspace . --mcp -``` - -Expected output: -``` -[...] Starting MCP server on http://127.0.0.1:8000 -[...] Health check: /health -[...] Resources available at /resources -``` - -The server stays running. - -#### Step 3: Test Health Endpoint (In Another Terminal) - -```bash -curl http://127.0.0.1:8000/health -``` - -Expected response: -```json -{"status": "healthy"} -``` - -#### Step 4: Query Resources - -```bash -curl http://127.0.0.1:8000/resources -``` - -Returns available MCP resources (code symbols, relationships, etc.). - -#### Step 5: Stop Server - -```bash -# Press Ctrl+C in the MCP server terminal -``` - ---- - -### Workflow 2: MCP Server with Watch + Live Graph - -Test real-time updates with MCP. - -```bash -# Build with watch and MCP enabled -codegenome --workspace . --build --mcp --watch -``` - -Make file changes in another terminal (as in Workflow 3). The MCP server updates resources in real-time. - ---- - -### Workflow 3: MCP Server with Stdio Transport (For Agents) - -Test stdio mode for direct agent integration. - -```bash -codegenome --workspace . --mcp --transport stdio -``` - -In this mode: -- Server reads JSON-RPC requests from stdin -- Server writes JSON-RPC responses to stdout -- Suitable for direct process integration with Cursor, Claude, etc. - ---- - -## Code Quality Checks - -### Linting with Ruff - -```bash -# Check for linting issues -ruff check src tests - -# Auto-fix issues -ruff check --fix src tests - -# Format code -ruff format src tests -``` - -### Run Linting + Tests Together - -```bash -ruff check src tests && pytest -``` - ---- - -## Debugging Tips - -### Enable Debug Logging - -Most modules support debug output via environment variables: - -```bash -# Verbose debug output -CODEGENOME_DEBUG=1 codegenome --workspace . --build - -# Or with Python module -CODEGENOME_DEBUG=1 python -m codegenome --workspace . --build -``` - -### Debug in Python REPL - -```python -import sys -sys.path.insert(0, 'src') - -from codegenome.builder import GraphBuilder -from pathlib import Path - -# Build a graph programmatically -builder = GraphBuilder(workspace_dir=Path('.')) -result = builder.build_full() - -# Inspect result -print(result) -``` - -### Inspect SQLite Database - -```bash -# With sqlite3 CLI (if installed) -sqlite3 .genome/watcher.db - -# View tables -.tables - -# Query symbols -SELECT * FROM symbols LIMIT 10; - -# Query relationships -SELECT * FROM relationships LIMIT 10; - -# Exit -.quit -``` - -Or in Python: - -```python -import sqlite3 - -conn = sqlite3.connect('.genome/watcher.db') -cursor = conn.cursor() - -# Get all tables -cursor.execute("SELECT name FROM sqlite_master WHERE type='table';") -tables = cursor.fetchall() -print("Tables:", [t[0] for t in tables]) - -# Query symbols -cursor.execute("SELECT * FROM symbols LIMIT 5;") -for row in cursor.fetchall(): - print(row) - -conn.close() -``` - ---- - -## Common Issues - -### Issue 1: Virtual Environment Not Activated - -**Symptom:** `codegenome: command not found` or `ModuleNotFoundError` - -**Solution:** -```bash -# Make sure venv is activated -# Windows: -.venv\Scripts\activate - -# macOS/Linux: -source .venv/bin/activate - -# Verify prompt shows (.venv) -``` - ---- - -### Issue 2: "tree-sitter Not Found" or Language Binding Errors - -**Symptom:** `ModuleNotFoundError: No module named 'tree_sitter_python'` - -**Solution:** -```bash -# Reinstall dependencies -pip install --upgrade --force-reinstall tree-sitter tree-sitter-python tree-sitter-javascript tree-sitter-typescript tree-sitter-go tree-sitter-rust -``` - ---- - -### Issue 3: ".genome Directory Not Created" - -**Symptom:** Build completes but no `.genome/` directory - -**Causes:** -- **Empty repository:** Ensure the target repo has source files in supported languages -- **Invalid workspace path:** Use absolute or relative paths, e.g., `.` or `/full/path/to/repo` - -**Solution:** -```bash -# Test on codegenome itself -cd /path/to/codegenome -codegenome --workspace . --build --full - -# Or test on a known repo -git clone https://github.com/torvalds/linux.git linux-test -cd linux-test -codegenome --workspace . --build # May take time for large repo -``` - ---- - -### Issue 4: MCP Server Port Already in Use - -**Symptom:** `Address already in use` on port 8000 - -**Solution:** -```bash -# Kill the existing process -# Windows: -netstat -ano | findstr :8000 -taskkill /PID /F - -# macOS/Linux: -lsof -i :8000 -kill -9 - -# Or use a different port (if supported) -codegenome --workspace . --mcp --port 8001 -``` - ---- - -### Issue 5: Tests Fail Due to Missing Language Grammars - -**Symptom:** `ParseError: No grammar found for language` - -**Solution:** -```bash -# Tree-sitter needs language grammars; reinstall from scratch -pip uninstall tree-sitter tree-sitter-{python,javascript,typescript,go,rust} -y -pip install -e ".[dev]" -pytest # Try again -``` - ---- - -### Issue 6: Slow Build on Large Repositories - -**Symptom:** Build takes > 5 minutes - -**Workaround:** -```bash -# Use incremental builds instead of full -codegenome --workspace . --build # Incremental (faster) - -# Exclude large directories -# (Feature may be added in future; currently n/a) -``` - ---- - -## Quick Reference: Common Commands - -```bash -# Development setup -python -m venv .venv -source .venv/bin/activate # or .venv\Scripts\activate on Windows -pip install -e ".[dev]" - -# Run tests -pytest # All tests -pytest -v # Verbose -pytest --cov=src/codegenome # With coverage -pytest -k "parser" # Specific pattern - -# Code quality -ruff check src tests # Lint -ruff format src tests # Format - -# Graph building -codegenome --workspace . --build # Incremental -codegenome --workspace . --build --full # Full rebuild -codegenome --workspace . --build --watch # Live mode - -# Exports -codegenome --workspace . --build --export json markdown graphml cypher - -# Timeline -codegenome --workspace . --dump-timeline - -# MCP server -codegenome --workspace . --mcp # HTTP mode -codegenome --workspace . --mcp --watch # With live updates -codegenome --workspace . --mcp --transport stdio # Stdio for agents - -# Help -codegenome --help -python -m codegenome --help -``` - ---- - -## Resources - -- **CLI Reference:** See [docs/cli-reference.md](docs/cli-reference.md) for full command documentation -- **Installation Guide:** See [docs/installation.md](docs/installation.md) -- **MCP Integration:** See [docs/mcp-integration.md](docs/mcp-integration.md) -- **Main README:** See [README.md](README.md) - ---- - -## Contributing Tips - -When making changes to the codebase: - -1. **Write tests first:** Use TDD approach where applicable -2. **Run full test suite:** `pytest -v` before committing -3. **Lint your code:** `ruff check --fix src tests` -4. **Test on multiple Python versions:** If possible, test on 3.11, 3.12, 3.13 -5. **Document changes:** Update docstrings and relevant docs -6. **Test MCP integration:** If modifying MCP server, test with actual agents - ---- - -**Happy testing!** 🚀 - -For issues or questions, refer to the project's GitHub issues or documentation. diff --git a/MANIFEST.in b/MANIFEST.in new file mode 100644 index 0000000..351b8c6 --- /dev/null +++ b/MANIFEST.in @@ -0,0 +1,4 @@ +include LICENSE +include README.md +recursive-include src/codegenome/assets * +recursive-include src/codegenome/templates * diff --git a/README.md b/README.md index 4da2903..e562be8 100644 --- a/README.md +++ b/README.md @@ -1,24 +1,31 @@
- Codegenome Header + Codegenome Header

Codegenome

- Open-source CLI for building, exporting, and querying local codebase knowledge graphs. + Turn your codebase into a living knowledge graph. An MCP server using tree-sitter to stream high-fidelity architectural context to Cursor and Claude.

- Build Status - PyPI Version - License + Documentation + PyPI + MIT License
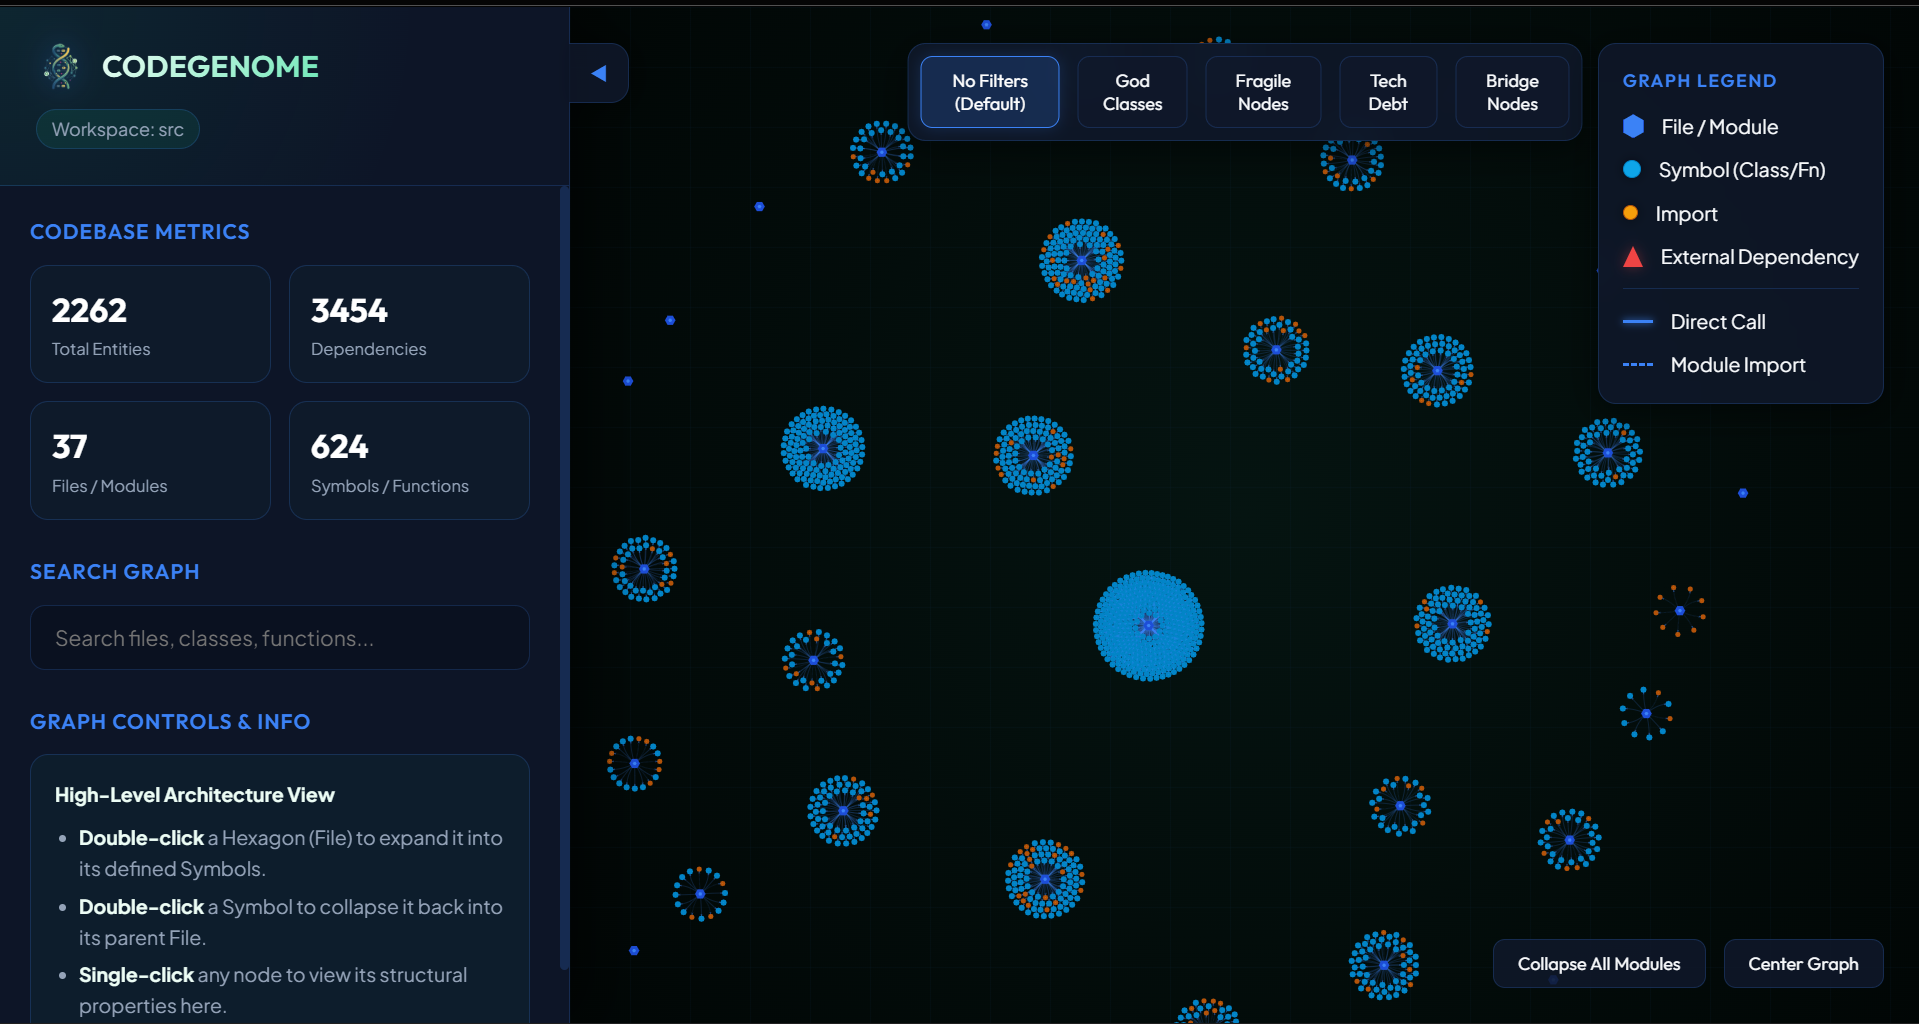
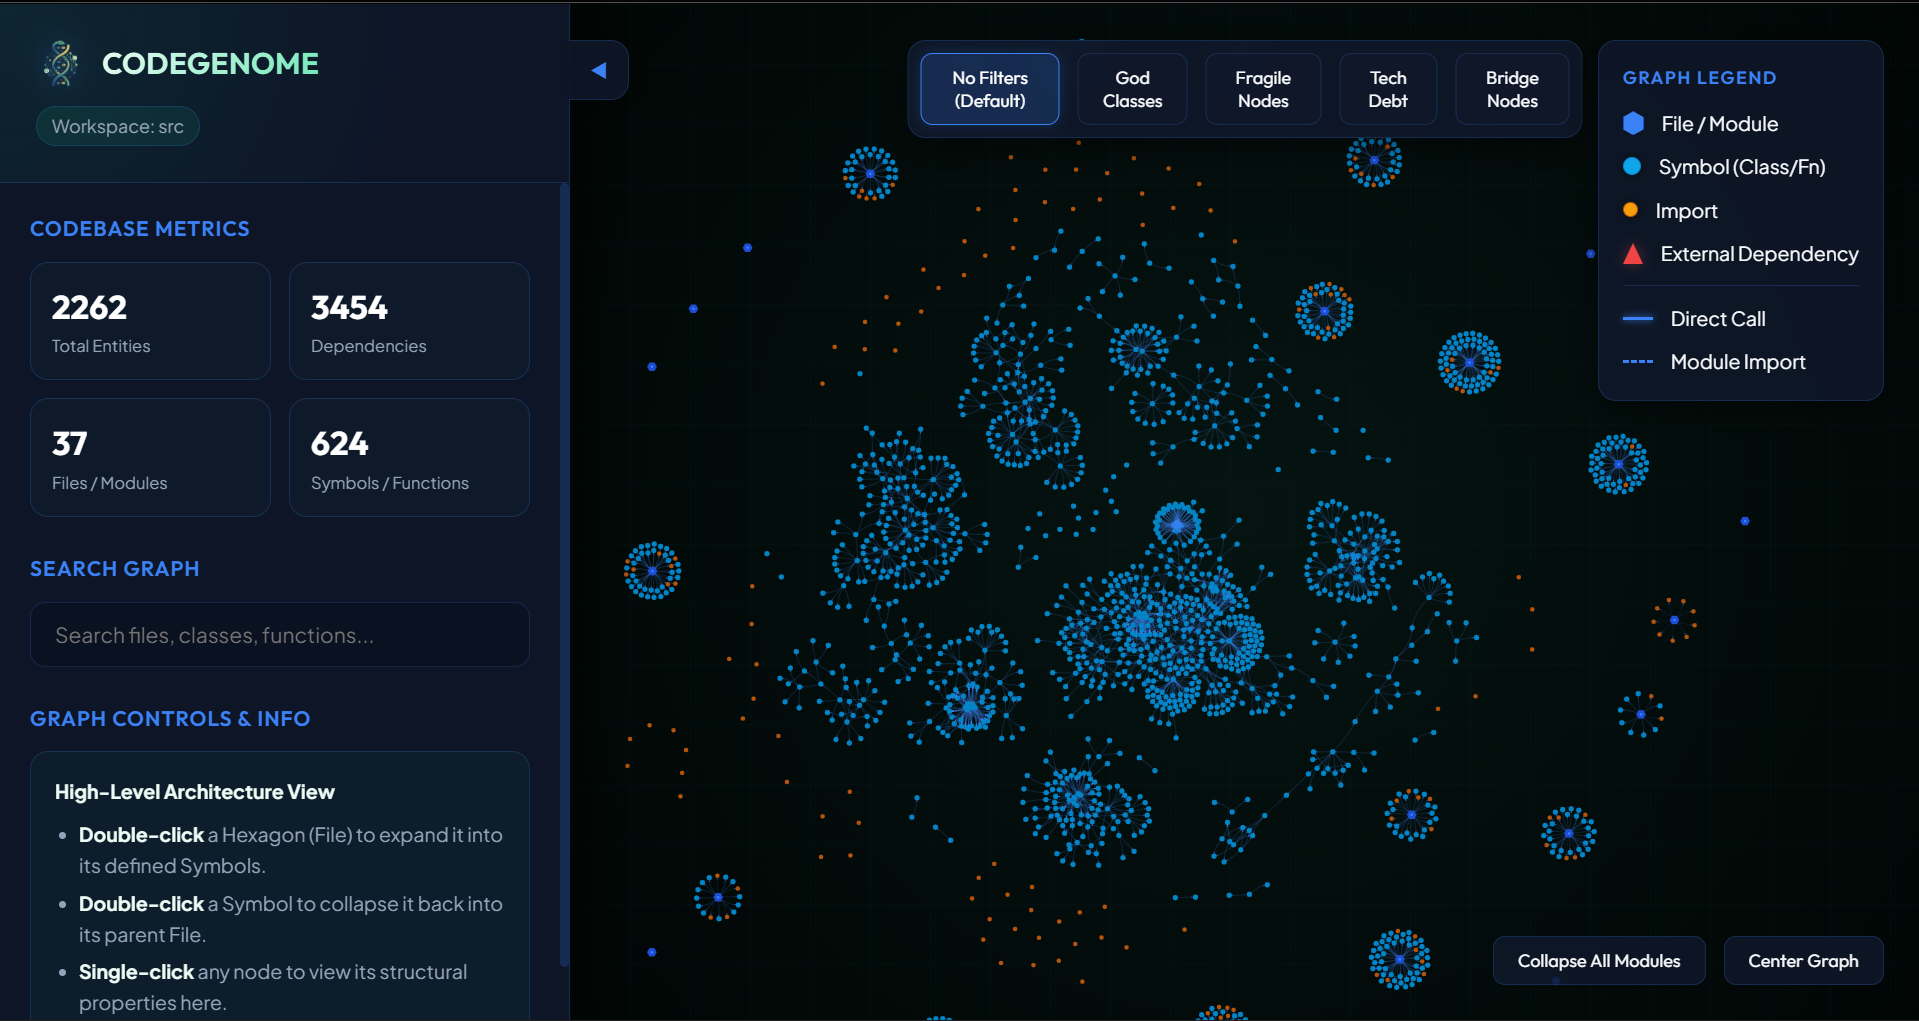
---- -**Codegenome** scans your repository, extracts symbols and relationships using `tree-sitter`, stores timeline snapshots in SQLite, and exposes this powerful intelligence to AI agents through MCP (Model Context Protocol). Use it headless in CI, on servers, or alongside any editor—no VS Code required! +## 🌐 The Connectome of Code: Mapping the Digital Brain + +Your codebase isn't a static document—it's an evolving digital brain. Standard context tools dump flat, truncated text files into your LLM window, causing massive token bloat and architectural hallucinations. + +**Codegenome treats code like a living connectome.** By running localized, incremental `tree-sitter` passes and tracking changes in SQLite, it monitors your repository's structural neuroplasticity in real time—without dragging down system performance. + +### ⚡ Watch your connectome grow as your agent codes +As your AI agent (**Cursor, Claude Desktop, or custom MCP clients**) generates new modules, refactors functions, or shifts dependencies, Codegenome maps out those structural relationships instantly. It exposes high-fidelity intelligence directly to your editor via the **Model Context Protocol (MCP)**, allowing AI agents to reason about your entire system architecture with surgical precision. Use it headless in CI, on servers, or locally—no complex IDE wrappers required. + ## ✨ What Codegenome Can Do @@ -29,8 +36,8 @@ Codegenome deeply understands your code. It parses your source files, incrementa Keep your codebase intelligence fresh in real-time. As you write code, Codegenome watches your workspace and automatically updates the graph, so your agents and queries are never out of sync.
- Live Graph Visualization - Live Graph Detail + Live Graph Visualization + Live Graph Detail
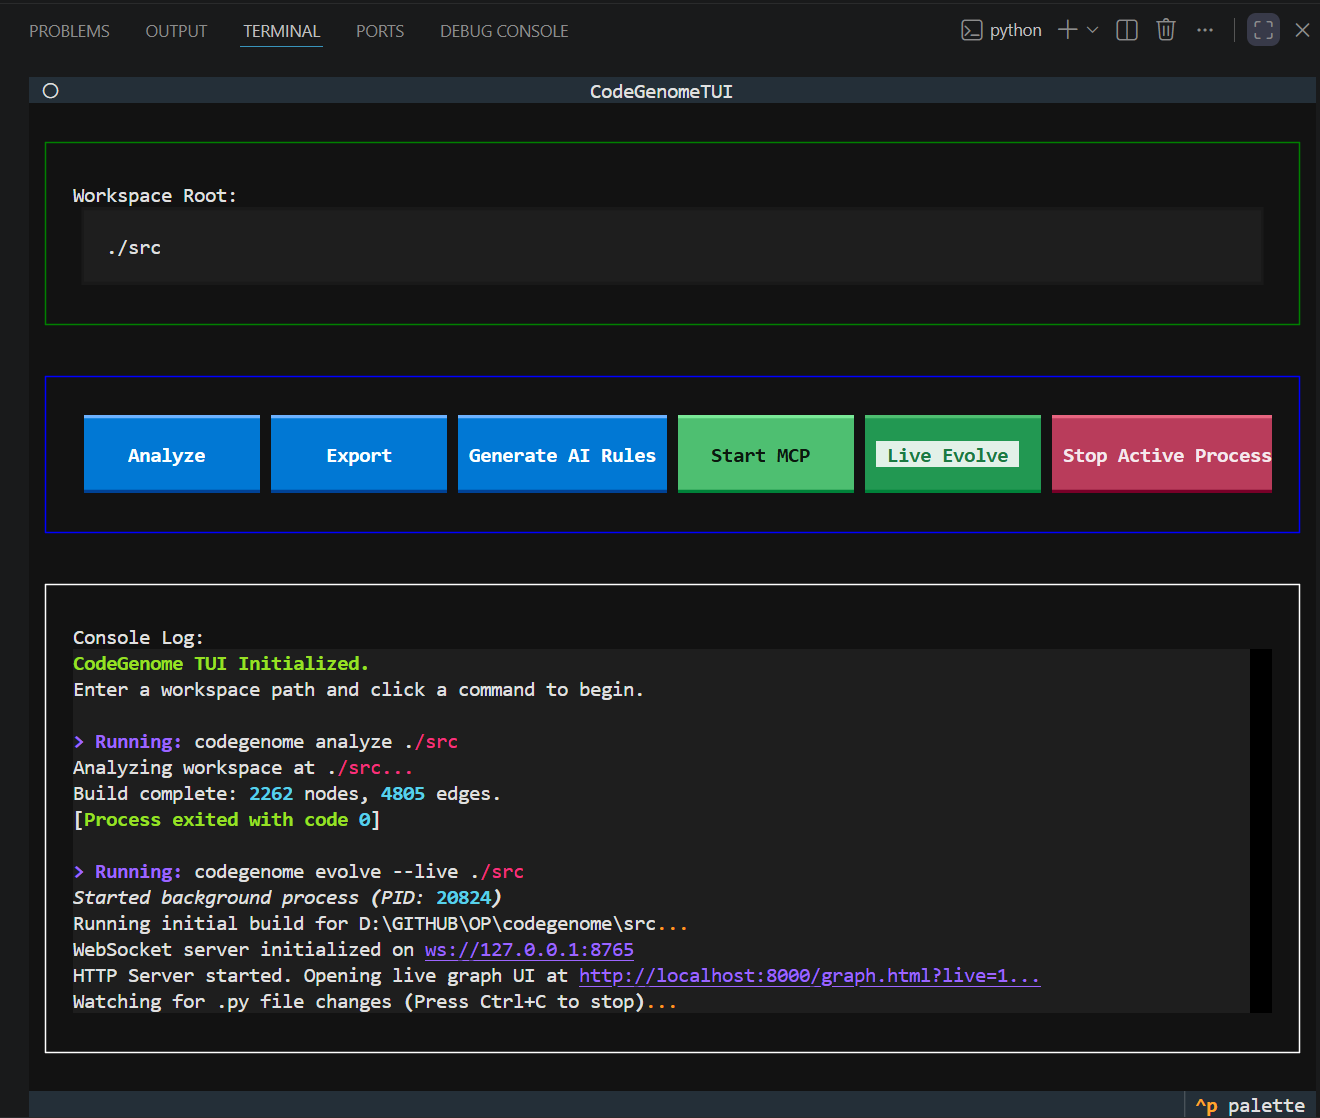
### 🖥️ Rich Terminal User Interface (TUI) @@ -42,7 +49,7 @@ codegenome tui ```
- Codegenome TUI + Codegenome TUI
### 🤖 Seamless AI Agent Integration via MCP @@ -56,6 +63,8 @@ Need your graph in a different format? Codegenome seamlessly exports to: - **Cypher** (for Neo4j) - **Obsidian** (for personal knowledge bases) +Use `codegenome export --format ` for `json`, `html`, `cypher`, and `obsidian`. Additional formats are available through the [legacy CLI](docs/cli-reference.md#legacy-cli-python--m-codegenome). + ## 🚀 Quick Start Get up and running in seconds. @@ -73,6 +82,9 @@ codegenome export --format obsidian --path . # Run in watch mode with live graph web UI codegenome evolve --live . + +# Share the live graph with other devices on your LAN (v0.1.4+) +codegenome evolve --live --lan . ``` > **Note**: For detailed CLI reference, installation guides, and MCP setup, see our comprehensive [Documentation](#-documentation). @@ -91,16 +103,17 @@ codegenome evolve --live . | Doc | Description | |-----|-------------| -| 📖 [CLI reference](docs/cli-reference.md) | Flags, workflows, troubleshooting | +| 📖 [CLI reference](docs/cli-reference.md) | Subcommands, legacy flags, workflows | | ⚙️ [Installation](docs/installation.md) | pip, venv, MCP setup | | 🔌 [MCP integration](docs/mcp-integration.md) | Server modes and client installer | | 🧩 [Extensions](extensions/README.md) | Cursor rules and Copilot templates | +| 🤝 [Contributing](CONTRIBUTING.md) | Development setup, tests, pull requests | ## ⚖️ License -Codegenome is open-source software licensed under the **[MIT License](LICENSE)**. +Codegenome is open-source software licensed under the **[MIT License](https://github.com/Ogro-Projukti/codegenome/blob/main/LICENSE)**.

- Codegenome Logo + Codegenome Logo
diff --git a/assets/new-v_014/ai-chat-live-graph.png b/assets/new-v_014/ai-chat-live-graph.png new file mode 100644 index 0000000..783ddce Binary files /dev/null and b/assets/new-v_014/ai-chat-live-graph.png differ diff --git a/assets/new-v_014/tui-config.png b/assets/new-v_014/tui-config.png new file mode 100644 index 0000000..1086f8a Binary files /dev/null and b/assets/new-v_014/tui-config.png differ diff --git a/assets/new-v_014/tui-main-panel.png b/assets/new-v_014/tui-main-panel.png new file mode 100644 index 0000000..24c8eb9 Binary files /dev/null and b/assets/new-v_014/tui-main-panel.png differ diff --git a/assets/new-v_014/tui-view-1-wp-set.png b/assets/new-v_014/tui-view-1-wp-set.png new file mode 100644 index 0000000..8c9840e Binary files /dev/null and b/assets/new-v_014/tui-view-1-wp-set.png differ diff --git a/assets/new-v_014/tui-view-2-wp-info.png b/assets/new-v_014/tui-view-2-wp-info.png new file mode 100644 index 0000000..f79abfc Binary files /dev/null and b/assets/new-v_014/tui-view-2-wp-info.png differ diff --git a/build.py b/build_cli.py similarity index 99% rename from build.py rename to build_cli.py index 1829557..dd99e63 100644 --- a/build.py +++ b/build_cli.py @@ -41,7 +41,6 @@ "fastmcp", "starlette", "uvicorn", - "radon", ] COLLECT_ALL = [ diff --git a/docs/cli-reference.md b/docs/cli-reference.md index 501a38b..56a7c9f 100644 --- a/docs/cli-reference.md +++ b/docs/cli-reference.md @@ -1,105 +1,169 @@ # CLI reference -The **Watcher CLI** (`watcher` or `python -m codegenome`) builds and exports knowledge graphs, runs watch/live modes, scaffolds projects, queries timeline data, and starts the MCP server. +Codegenome ships two CLI interfaces: -## How to invoke +| Interface | Invoke | Best for | +|-----------|--------|----------| +| **Modern CLI** | `codegenome ` | Day-to-day use, TUI, exports, stdio MCP | +| **Legacy CLI** | `python -m codegenome --flags` | Watch mode, HTTP MCP, timeline queries, all export formats | -| Method | When to use | -|--------|-------------| -| `watcher …` | After `pip install codegenome` or editable install | -| `python -m codegenome …` | Development or when the script is not on PATH | -| `python -m codegenome.mcp_server …` | Standalone MCP (stdio or custom HTTP port) | -| `python -m codegenome.installer …` | Write MCP entries into AI client configs | +Both operate on a **workspace** (project root). By default that is the current directory (`.`). Graph data is stored under `/.genome/`. + +## Workspace artifacts + +| Path | Purpose | +|------|---------| +| `.genome/watcher.db` | Timeline snapshots (SQLite) | +| `.genome/graph.json` | Latest graph | +| `.genome/exports/` | HTML, Markdown, GraphML, etc. | +| `.genome/scan_cache.db` | Incremental scan cache | + +Override the database with `--db-path` on the legacy CLI, or pass `--db-path` to `python -m codegenome.mcp_server`. + +--- + +## Modern CLI (`codegenome`) + +Install with `pip install codegenome`, then: ```bash -watcher --help +codegenome --help ``` ---- +### `analyze` + +Build or incrementally update the knowledge graph. + +```bash +codegenome analyze . +codegenome analyze /path/to/my-app +``` -## Workspace +### `export` -Almost every command needs a project root (default: `.`): +Export the current graph. Requires a prior `analyze`. ```bash -watcher --workspace /path/to/my-app --build +codegenome export --format json --path . +codegenome export --format obsidian --path . ``` -The engine writes under `/.genome/`: +Supported formats in this subcommand: `json`, `html`, `cypher`, `obsidian`. -| Path | Purpose | -|------|---------| -| `.genome/watcher.db` | Timeline snapshots (SQLite) | -| `.genome/graph.json` | Latest graph | -| `.genome/exports/` | HTML, Markdown, GraphML, etc. | -| `.genome/scan_cache.db` | Incremental scan cache | +For `markdown`, `graphml`, and multi-format exports, use the [legacy CLI](#legacy-cli-python--m-codegenome). + +### `evolve` + +Run a live observer with a browser-based graph UI. Watches `.py` file changes and rebuilds incrementally. + +```bash +codegenome evolve . +codegenome evolve --live . +codegenome evolve --live --lan . +``` + +With `--live`, a WebSocket server broadcasts graph updates. The UI is served at `http://localhost:8000/graph.html?live=1`. + +With `--lan`, HTTP and WebSocket bind to all interfaces (`0.0.0.0`) so other devices on the same network can open the graph. The CLI prints a shareable LAN URL (for example `http://192.168.1.42:8000/graph.html?live=1`). Use `--live --lan` together for real-time updates on remote viewers. + +### `mcp-start` + +Start the MCP server over **stdio** for the given workspace. + +```bash +codegenome mcp-start . +``` + +For HTTP MCP on port `7331`, use the [legacy CLI](#mcp-via-legacy-cli) or [standalone MCP server](mcp-integration.md#standalone-mcp-server). + +### `rules` -Override the database with `--db-path` for timeline queries or MCP. +Generate agent instruction files (Cursor rules, Copilot instructions, `AGENTS.md`, etc.). + +```bash +codegenome rules . +codegenome rules --client cursor --client copilot --port 7331 . +codegenome rules --dry-run . +``` + +Clients: `cursor`, `copilot`, `windsurf`, `agents`, or `all` (default when omitted). + +### `tui` + +Launch the interactive terminal dashboard. + +```bash +codegenome tui +``` + +From the TUI you can start live graph observation in two modes: + +- **Live Evolve (Local)** — graph UI and WebSocket on localhost only +- **Live Evolve (LAN)** — exposes HTTP and WebSocket on the local network so other devices can view the graph +- **Quit** — stops any background processes and exits the TUI --- -## Build & export +## Legacy CLI (`python -m codegenome`) + +The flag-based interface supports watch mode, HTTP MCP, timeline queries, metrics, and every export format. + +```bash +python -m codegenome --help +``` + +### Build and export ```bash # Incremental build -watcher --workspace . --build +python -m codegenome --workspace . --build # Full rebuild -watcher --workspace . --build --full +python -m codegenome --workspace . --build --full # Custom exports (default: json, html, markdown) -watcher --workspace . --build --export json markdown graphml cypher obsidian +python -m codegenome --workspace . --build --export json markdown graphml cypher obsidian ``` -Supported formats: `json`, `html`, `markdown`, `graphml`, `cypher`, `obsidian`. - ---- +Supported export formats: `json`, `html`, `markdown`, `graphml`, `cypher`, `obsidian`. -## Watch & live graph +### Watch and live graph ```bash # Debounced rebuild on file changes (default debounce: 30s) -watcher --workspace . --build --watch --watch-debounce 10 +python -m codegenome --workspace . --build --watch --watch-debounce 10 # Poll file/line totals and rebuild when they increase -watcher --workspace . --build --live-graph --live-graph-interval 60 +python -m codegenome --workspace . --build --live-graph --live-graph-interval 60 ``` ---- - -## Metrics +### Metrics ```bash -watcher --workspace . --print-metrics +python -m codegenome --workspace . --print-metrics # {"file_count": 142, "line_count": 18450} ``` ---- - -## MCP via main CLI +### MCP via legacy CLI ```bash -watcher --workspace . --build --mcp --watch +python -m codegenome --workspace . --build --mcp --watch ``` Starts HTTP MCP on `127.0.0.1:7331` after build. For stdio or a custom port, use `python -m codegenome.mcp_server`. ---- +### Timeline queries -## Timeline queries - -JSON to stdout; requires at least one prior build. +JSON is printed to stdout. Requires at least one prior build. ```bash -watcher --workspace . --dump-timeline -watcher --workspace . --dump-timeline --node-id "file:src/main.py" -watcher --workspace . --dump-changes --snapshot-from 1 --snapshot-to 3 -watcher --workspace . --dump-churn --churn-limit 10 +python -m codegenome --workspace . --dump-timeline +python -m codegenome --workspace . --dump-timeline --node-id "file:src/main.py" +python -m codegenome --workspace . --dump-changes --snapshot-from 1 --snapshot-to 3 +python -m codegenome --workspace . --dump-churn --churn-limit 10 ``` ---- - -## Flag reference +### Legacy flag reference | Flag | Description | |------|-------------| @@ -124,7 +188,18 @@ watcher --workspace . --dump-churn --churn-limit 10 | `--churn-file PATH` | Filter churn to one file | | `--churn-limit N` | Max churn rows (default: 25) | -**Requires at least one of:** `--build`, `--watch`, `--live-graph` (unless using query/scaffold/metrics-only flags). +**Requires at least one of:** `--build`, `--watch`, `--live-graph` (unless using query or metrics-only flags). + +--- + +## Related modules + +| Command | Purpose | +|---------|---------| +| `python -m codegenome.mcp_server …` | Standalone MCP (stdio or custom HTTP port) | +| `python -m codegenome.installer …` | Write MCP entries into AI client configs | + +See [MCP integration](mcp-integration.md) and [Installation](installation.md). --- @@ -133,30 +208,42 @@ watcher --workspace . --dump-churn --churn-limit 10 | Code | Meaning | |------|---------| | `0` | Success | -| `1` | Error (stderr) | +| `1` | Error (details on stderr) | --- ## Common workflows +### Quick local analysis + +```bash +codegenome analyze . +codegenome export --format html --path . +codegenome tui +``` + ### CI graph build ```bash -watcher --workspace . --build --export json +python -m codegenome --workspace . --build --export json ``` -### Local dev + Cursor MCP +### Local dev with Cursor (HTTP MCP) Terminal 1: ```bash -watcher --workspace . --build --mcp --watch +python -m codegenome --workspace . --build --mcp --watch ``` Terminal 2: ```bash -python -m codegenome.installer --db-path "$(pwd)/.genome/watcher.db" --client cursor +python -m codegenome.installer \ + --db-path "$(pwd)/.genome/watcher.db" \ + --client cursor \ + --transport http +codegenome rules --client cursor . ``` -See [MCP integration](mcp-integration.md) and [Installation](installation.md). +Restart Cursor after installing MCP config and rules. diff --git a/docs/installation.md b/docs/installation.md index 861e853..a697da8 100644 --- a/docs/installation.md +++ b/docs/installation.md @@ -1,72 +1,92 @@ # Installation -Install **Watcher CLI** with pip into a virtual environment (recommended). +Install **Codegenome** with pip into a virtual environment (recommended). ## Requirements - Python **3.11+** +- **Git** (for development installs) - A C compiler may be required on some platforms for `python-igraph` / `leidenalg` -## Editable install (development) - -From this repository root: +## Production install (PyPI) ```bash python -m venv .venv # Windows PowerShell .venv\Scripts\Activate.ps1 -pip install -e ".[dev]" # macOS / Linux source .venv/bin/activate -pip install -e ".[dev]" + +pip install codegenome ``` Verify: ```bash -watcher --help +codegenome --help python -c "import codegenome; print(codegenome.__version__)" ``` -## Production install (PyPI) - -Once published: +TestPyPI: ```bash -pip install codegenome +pip install --index-url https://test.pypi.org/simple/ --extra-index-url https://pypi.org/simple/ codegenome ``` -TestPyPI: +## Editable install (development) + +From this repository root: ```bash -pip install --index-url https://test.pypi.org/simple/ --extra-index-url https://pypi.org/simple/ codegenome +python -m venv .venv + +# Windows PowerShell +.venv\Scripts\Activate.ps1 +pip install -e ".[dev]" + +# macOS / Linux +source .venv/bin/activate +pip install -e ".[dev]" ``` +Verify the same way as above. For contribution workflow, tests, and linting, see [CONTRIBUTING.md](../CONTRIBUTING.md). + ## First graph build -Point Watcher at **your project directory** (the repo you want to analyze): +Point Codegenome at **your project directory** (the repo you want to analyze): ```bash cd ~/projects/my-app -watcher --workspace . --build +codegenome analyze . ``` -Artifacts: +Codegenome writes artifacts under `/.genome/`: | Path | Purpose | |------|---------| | `.genome/graph.json` | Latest graph | -| `.genome/watcher.db` | Timeline snapshots | -| `.genome/exports/` | HTML, Markdown, etc. | +| `.genome/watcher.db` | Timeline snapshots (SQLite) | +| `.genome/exports/` | HTML, Markdown, GraphML, etc. | +| `.genome/scan_cache.db` | Incremental scan cache | + +Export after building: + +```bash +codegenome export --format json --path . +``` ## MCP setup -**Terminal 1** — build + HTTP MCP: +Build the graph first (`codegenome analyze .`). Then choose a transport: + +### HTTP (Cursor and most editor clients) + +**Terminal 1** — build, watch, and start HTTP MCP on `127.0.0.1:7331`: ```bash -watcher --workspace . --build --mcp --watch +python -m codegenome --workspace . --build --mcp --watch ``` **Terminal 2** — write client config (one time): @@ -75,7 +95,9 @@ watcher --workspace . --build --mcp --watch python -m codegenome.installer \ --db-path "$(pwd)/.genome/watcher.db" \ --client cursor \ - --transport http + --transport http \ + --host 127.0.0.1 \ + --port 7331 ``` Health check: @@ -84,7 +106,16 @@ Health check: curl http://127.0.0.1:7331/health ``` -Standalone MCP server (custom port or stdio): +Restart your AI client after installing MCP config. + +### Stdio (Claude Desktop and some CLI agents) + +```bash +codegenome analyze . +codegenome mcp-start . +``` + +Or run the standalone server module: ```bash python -m codegenome.mcp_server \ @@ -92,13 +123,33 @@ python -m codegenome.mcp_server \ --transport stdio ``` -See [MCP integration](mcp-integration.md) for environment variables and client list. +See [MCP integration](mcp-integration.md) for environment variables, supported clients, and agent rules. + +## Optional: standalone binary + +To build a PyInstaller binary named `watcher` in `dist/` (requires the `dev` extra): + +```bash +python build_cli.py +``` + +This is optional. The default PyPI entry point is the `codegenome` command. ## Troubleshooting | Problem | Fix | |---------|-----| -| `watcher: command not found` | Activate venv or use `python -m codegenome` | -| `igraph` build fails | Install build tools; on Windows try `pip install python-igraph` with MSVC Build Tools | -| Empty timeline dumps | Run `watcher --workspace . --build` first | -| Port 7331 in use | Stop other Watcher instance or use `--port` on `mcp_server` | +| `codegenome: command not found` | Activate your venv or reinstall with `pip install codegenome` | +| `No graph found` on export/MCP | Run `codegenome analyze .` first | +| `igraph` build fails | Install platform build tools; on Windows, install MSVC Build Tools | +| Empty timeline dumps | Run `python -m codegenome --workspace . --build` first | +| Port 7331 in use | Stop the other MCP instance or pass `--port` to `mcp_server` | +| Mixed CLI errors | Use subcommands (`codegenome analyze`) or legacy flags (`python -m codegenome --build`), not both in one invocation | + +## Next steps + +| Doc | Description | +|-----|-------------| +| [CLI reference](cli-reference.md) | Subcommands, legacy flags, workflows | +| [MCP integration](mcp-integration.md) | Server modes, installer, tools | +| [Extensions](../extensions/README.md) | Cursor rules and Copilot templates | diff --git a/docs/mcp-integration.md b/docs/mcp-integration.md index 5592a8d..ed75076 100644 --- a/docs/mcp-integration.md +++ b/docs/mcp-integration.md @@ -1,12 +1,20 @@ # MCP integration -Watcher exposes your project's knowledge graph to AI coding assistants through a **local MCP server** on `127.0.0.1:7331` (HTTP by default). +Codegenome exposes your project's knowledge graph to AI coding assistants through a **local MCP server**. The default HTTP endpoint is `127.0.0.1:7331`. -## Quick setup +Build the graph before connecting clients: + +```bash +codegenome analyze . +``` + +## Quick setup (HTTP + watch) + +Best for Cursor, Copilot (VS Code), and other HTTP-based clients. ```bash # Terminal 1: build + MCP + watch -watcher --workspace . --build --mcp --watch +python -m codegenome --workspace . --build --mcp --watch # Terminal 2: install client config python -m codegenome.installer \ @@ -15,10 +23,32 @@ python -m codegenome.installer \ --transport http \ --host 127.0.0.1 \ --port 7331 + +# Optional: generate agent rules in the workspace +codegenome rules --client cursor --port 7331 . ``` Restart your AI client after installation. +## Stdio setup + +Best for Claude Desktop and agents that spawn an MCP subprocess. + +```bash +codegenome analyze . +codegenome mcp-start . +``` + +Or configure clients to run the module directly: + +```bash +python -m codegenome.mcp_server \ + --db-path ./.genome/watcher.db \ + --transport stdio +``` + +Use `python -m codegenome.installer --transport stdio` when writing client config for stdio mode. + ## Standalone MCP server ```bash @@ -31,7 +61,7 @@ python -m codegenome.mcp_server \ --port 7331 \ --transport http -# Stdio (Claude Desktop, some CLI agents) +# Stdio python -m codegenome.mcp_server \ --db-path ./.genome/watcher.db \ --transport stdio @@ -65,7 +95,7 @@ python -m codegenome.installer --help | Aider | `~/.aider/mcp.json` | | Windsurf | `~/.codeium/windsurf/mcp_config.json` | -Use **absolute paths** for `--db-path`. +Always use **absolute paths** for `--db-path`. ## Environment variables @@ -85,9 +115,15 @@ curl http://127.0.0.1:7331/health curl http://127.0.0.1:7331/mcp/activity ``` -## AI rules (Cursor / Copilot) +## AI rules (Cursor / Copilot / AGENTS.md) -Templates live in [`extensions/templates/`](../extensions/templates/). See [Extensions README](../extensions/README.md). +Generate rules with the CLI: + +```bash +codegenome rules --client all --port 7331 . +``` + +Templates also live in [`extensions/templates/`](../extensions/templates/). See [Extensions README](../extensions/README.md). Manual Cursor rule install: @@ -97,6 +133,8 @@ sed 's/{{MCP_PORT}}/7331/g' extensions/templates/watcher-knowledge-graph.mdc \ > .cursor/rules/watcher-knowledge-graph.mdc ``` +On Windows PowerShell, copy the template and replace `{{MCP_PORT}}` with `7331` manually or use your editor's find-and-replace. + ## MCP tools (summary) Agents can call tools such as: @@ -110,14 +148,17 @@ Agents can call tools such as: Build the graph before expecting rich tool results: ```bash -watcher --workspace . --build +codegenome analyze . ``` ## Troubleshooting | Problem | Solution | |---------|----------| -| Connection refused | Run `watcher --mcp` or `mcp_server`; ensure graph was built | -| Port 7331 in use | Stop other instance or `mcp_server --port 7332` | -| Empty tool results | Run `--build` first; check `.genome/watcher.db` exists | -| Client not using MCP | Restart client after `installer`; verify config path | +| Connection refused | Run HTTP MCP (`python -m codegenome --mcp --build --watch`) or `mcp_server`; ensure the graph was built | +| Port 7331 in use | Stop the other instance or run `mcp_server --port 7332` and update client config | +| Empty tool results | Run `codegenome analyze .` first; confirm `.genome/watcher.db` exists | +| Client not using MCP | Restart the client after `installer`; verify the config file path | +| Stdio vs HTTP mismatch | Match `--transport` in `installer` with how the server is started | + +See also [CLI reference](cli-reference.md) and [Installation](installation.md). diff --git a/docs/release-0.1.4.md b/docs/release-0.1.4.md new file mode 100644 index 0000000..235f664 --- /dev/null +++ b/docs/release-0.1.4.md @@ -0,0 +1,72 @@ +# Release 0.1.4 + +## Highlights + +- **LAN live graph** — share the evolving graph with devices on the same network +- **Ignore rules** — scans respect `.gitignore` and `.genomeignore` +- **TUI** — workspace info view and buttons for local/LAN live evolve +- **Live graph AI chat** — ask questions about your architecture from the browser UI (OpenAI, Gemini, Groq, Ollama, Ollama Cloud) +- **MCP improvements** — `query_graph` tool, live snapshot refresh, HTTP/stdio transport via `mcp-start` + +## CLI + +```bash +# LAN live graph +codegenome evolve --live --lan . + +# MCP over HTTP (for editors that connect via URL) +codegenome mcp-start . --transport http --port 7331 + +# Generate agent rules +codegenome rules --client all . + +# TUI +codegenome tui +``` + +## Upgrade + +```bash +pip install --upgrade codegenome +python -c "import codegenome; print(codegenome.__version__)" +# Expected: 0.1.4 +``` + +## Pre-release verification + +| Check | Status | +|-------|--------| +| Tests (`pytest`) | 99 passed | +| Version in `pyproject.toml` and `src/codegenome/version.py` | `0.1.4` | +| Changelog updated | Yes | + +## Publishing checklist + +- [x] Remaining features merged +- [x] Tests pass (`pytest`) +- [x] Version bumped in `pyproject.toml` and `src/codegenome/version.py` +- [x] Changelog and release notes updated +- [ ] Tag `v0.1.4` and create GitHub Release +- [ ] Publish to PyPI + +## GitHub Release body (copy/paste) + +```markdown +## What's new in 0.1.4 + +### Live graph & TUI +- Share live graph updates on your LAN with `codegenome evolve --live --lan` +- TUI workspace info page and one-click local/LAN live evolve controls +- In-browser AI chat on the live graph UI (OpenAI, Gemini, Groq, Ollama, Ollama Cloud) + +### Scanning +- Git-aware ignore rules via `.gitignore` and `.genomeignore` + +### MCP +- New `query_graph` tool for filtering nodes by type, path, or symbol kind +- `codegenome mcp-start --transport http|stdio --port 7331` +- Server auto-refreshes to the latest snapshot before serving tool calls + +### Upgrade +pip install --upgrade codegenome +``` diff --git a/extensions/README.md b/extensions/README.md index 6f7ed06..073a1a2 100644 --- a/extensions/README.md +++ b/extensions/README.md @@ -1,19 +1,34 @@ -# Extensions & editor integrations +# Extensions and editor integrations -This folder holds **editor and agent integration assets** that ship with the open-source CLI repo. They are copied from the Watcher monorepo and will grow here as CLI-side installers expand. +This folder holds **editor and agent integration assets** that ship with the Codegenome repository. ## Contents | Path | Purpose | |------|---------| -| `templates/watcher-knowledge-graph.mdc` | Cursor rule template — teaches agents to use Watcher MCP tools | +| `templates/watcher-knowledge-graph.mdc` | Cursor rule template — teaches agents to use Codegenome MCP tools | | `templates/copilot-instructions.md` | GitHub Copilot instructions template | +| `templates/claude-instructions.md` | Claude-oriented instructions template | Templates use `{{MCP_PORT}}` as a placeholder (default MCP port: `7331`). -## MCP client installer (CLI) +## Generate rules with the CLI -The Python package includes a config writer for AI clients: +Prefer the built-in generator over manual copying: + +```bash +codegenome rules --client cursor --port 7331 . +codegenome rules --client copilot --port 7331 . +codegenome rules --client all --port 7331 . +``` + +Supported `--client` values: `cursor`, `copilot`, `windsurf`, `agents`, `all`. + +Use `--dry-run` to preview output paths without writing files. + +## MCP client installer + +Write MCP server entries into AI client config files: ```bash python -m codegenome.installer \ @@ -24,13 +39,9 @@ python -m codegenome.installer \ --port 7331 ``` -Supported clients: `claude`, `cursor`, `codex`, `gemini`, `aider`, `windsurf`, `copilot`. - -## Planned moves from the monorepo +Supported installer clients: `claude`, `cursor`, `codex`, `gemini`, `aider`, `windsurf`, `copilot`. -- Cursor rule / Copilot template install command on the main `watcher` CLI (today: VS Code extension only) -- Additional agent rule formats (AGENTS.md, Windsurf rules, etc.) -- VS Code extension remains a separate package; only shared templates and installer logic live here +See [MCP integration](../docs/mcp-integration.md) for transport modes, health checks, and troubleshooting. ## Manual install (Cursor rule) @@ -41,3 +52,11 @@ sed 's/{{MCP_PORT}}/7331/g' extensions/templates/watcher-knowledge-graph.mdc \ ``` Restart Cursor after installing MCP config or rules. + +## Related documentation + +| Doc | Description | +|-----|-------------| +| [MCP integration](../docs/mcp-integration.md) | Server setup and installer | +| [CLI reference](../docs/cli-reference.md) | `codegenome rules` and other commands | +| [Installation](../docs/installation.md) | pip install and first graph build | diff --git a/extensions/templates/claude-instructions.md b/extensions/templates/claude-instructions.md index 07c4397..3666328 100644 --- a/extensions/templates/claude-instructions.md +++ b/extensions/templates/claude-instructions.md @@ -4,10 +4,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists and the MCP server is healthy, you MUST use the CodeGenome MCP server (`watcher` on `http://127.0.0.1:{{MCP_PORT}}/mcp`) for all codebase, architecture, dependency, or symbol queries. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -19,5 +20,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If a tool fails due to connection issues, politely ask the user to start the MCP server: `codegenome mcp-start`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/extensions/templates/copilot-instructions.md b/extensions/templates/copilot-instructions.md index 07c4397..3666328 100644 --- a/extensions/templates/copilot-instructions.md +++ b/extensions/templates/copilot-instructions.md @@ -4,10 +4,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists and the MCP server is healthy, you MUST use the CodeGenome MCP server (`watcher` on `http://127.0.0.1:{{MCP_PORT}}/mcp`) for all codebase, architecture, dependency, or symbol queries. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -19,5 +20,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If a tool fails due to connection issues, politely ask the user to start the MCP server: `codegenome mcp-start`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/extensions/templates/watcher-knowledge-graph.mdc b/extensions/templates/watcher-knowledge-graph.mdc index 89198e1..6796262 100644 --- a/extensions/templates/watcher-knowledge-graph.mdc +++ b/extensions/templates/watcher-knowledge-graph.mdc @@ -9,10 +9,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists and the MCP server is healthy, you MUST use the CodeGenome MCP server (`watcher` on `http://127.0.0.1:{{MCP_PORT}}/mcp`) for all codebase, architecture, dependency, or symbol queries. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -24,5 +25,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If a tool fails due to connection issues, politely ask the user to start the MCP server: `codegenome mcp-start`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/graph_build_audit.md b/graph_build_audit.md deleted file mode 100644 index 51c3cf5..0000000 --- a/graph_build_audit.md +++ /dev/null @@ -1,71 +0,0 @@ -# CodeGenome — Graph Build Audit & Cleanup Plan - -Date: 2026-05-28 - -Purpose -- Produce a focused audit for graph-building, auto-evolve, and graph-driven analysis. Align cleanup tasks with project_identity.md and next_move.md so the package can prioritize a python-igraph-based, incremental, event-driven graph engine. - -High-level findings -- Core, required components: - - src/codegenome/parser.py — tree-sitter parsers: REQUIRED (primary source extraction). - - src/codegenome/builder.py — graph construction: REQUIRED, currently NetworkX-centric; must migrate to igraph or wrap behind an abstraction. - - src/codegenome/clusterer.py — clustering (leidenalg + igraph conversion): REQUIRED; consolidate to igraph-native (remove networkx intermediary). - - src/codegenome/graph_store.py — persistence/timeline: REQUIRED; ensure store supports incremental snapshots and igraph-compatible serialization. - - src/codegenome/timeline.py — timeline/churn analysis: REQUIRED; currently assumes networkx in places — migrate. - - src/codegenome/watcher.py & live_graph_monitor.py — event-driven/watchdog pipeline: REQUIRED (real-time incremental builds). - - src/codegenome/mcp_server.py & installer.py & mcp_activity.py — MCP integration: REQUIRED for agent integration, but can be optional in packaging via extras. - - src/codegenome/exporter.py — export formats: REQUIRED surface, but should work from igraph or via an adapter. - - tests/ — many tests assume NetworkX; REQUIRED to update to igraph or adapter tests. - -- Risk/technical debt - - NetworkX is used widely (builder, exporter, timeline, intelligence, graph_store). Next_move mandates removal to avoid memory blowups; current codebase mixes networkx and igraph with conversion helpers — risky and expensive. - - python-igraph + leidenalg are native C-backed and preferred for large graphs, but platform packaging and wheel availability must be verified. - - Export and tests currently depend on NetworkX APIs; blind removal will break behavior and CI. - -- Candidates to postpone or make optional - - Packaging helpers for PyInstaller/build.py — postpone until core migration completes. - - Non-essential export formats or heavy optional integrations (GraphML/Cypher plugins) can be moved to optional extras. - -Recommended migration strategy (staged) -1. Introduce a thin Graph API abstraction (src/codegenome/graph_api.py): - - Provide the minimal API surface currently consumed across codebase (add_node, add_edge, nodes, edges, attributes, SCC, degree, neighbors, to_serializable()). - - Implement an igraph-backed implementation and a NetworkX compatibility adapter for parity tests. - -2. Add unit/integration tests that assert parity between current NetworkX output and igraph adapter on small graphs (SCCs, degree, export shapes). - -3. Migrate builder.py to use Graph API (backed by igraph) while keeping behavior identical (graph.json output unchanged for same inputs). - -4. Migrate clusterer.py to igraph-native calls; remove networkx_to_igraph conversion helper; use leidenalg directly on igraph objects. - -5. Update exporter.py, timeline.py, graph_store.py, and intelligence.py to consume Graph API objects (or igraph directly once parity verified). - -6. Run full test suite and fix regressions. Keep networkx available in dev extras only (e.g., [compat]) until tests and consumers fully migrated. - -7. Remove networkx from core dependencies and pyproject; update README and docs describing installation extras for legacy exports. - -8. Profile memory and performance on medium and large sample repos; iterate on lazy-loading and subgraph contraction strategies described in next_move.md. - -Concrete checklist (files to change) -- High priority: src/codegenome/builder.py, src/codegenome/clusterer.py, src/codegenome/graph_store.py, src/codegenome/timeline.py, src/codegenome/exporter.py -- Medium: src/codegenome/intelligence.py, src/codegenome/watcher.py (ensure watcher integrates with new Graph API), tests/* -- Low/postpone: build.py, packaging scripts, optional exporters, docs updates - -Dependency & packaging notes -- Keep: tree-sitter family (parsers), watchdog, fastmcp (MCP), python-igraph, leidenalg -- Move to optional extras: networkx (compat/export), pyinstaller, heavy export plugins -- Ensure python-igraph binary wheels are available or document build steps for platforms where they are not. - -Testing & validation -- Add smoke tests that build a small repo graph and verify parity with existing outputs. -- Add memory/regression tests for larger repos to ensure igraph migration reduces peak memory usage. - -Immediate next moves (recommended order) -1. Add src/codegenome/graph_api.py and tests asserting parity for core graph ops. -2. Refactor builder.py to use Graph API. -3. Run tests and fix breaking changes. -4. Migrate clusterer and exporter; remove networkx from core deps. - -Notes -- next_move.md and project_identity.md already prescribe igraph-first and event-driven incremental pipelines — the above plan operationalizes those mandates while keeping a safe compatibility path. - -If this looks good, next action can be: implement graph_api.py skeleton and convert builder.py to use it (I can perform those edits and run tests). \ No newline at end of file diff --git a/next_move.md b/next_move.md deleted file mode 100644 index 82ca8e7..0000000 --- a/next_move.md +++ /dev/null @@ -1,103 +0,0 @@ -# Architectural Design Document: Scalable Codebase Graph Analyzer -## Executive Summary & System Decisions Log - -This document compiles the architectural decisions, structural paradigms, and technical strategies agreed upon for scaling a codebase graph analysis tool. The primary objective is to transition from a monolithic, high-memory graph structure to a distributed, incremental, and language-agnostic architecture capable of handling enterprise-scale codebases efficiently. - ---- - -## 1. Core Architecture & Technology Stack Upgrades - -### The Problem -The initial implementation used `NetworkX` alongside `python-igraph` and `leidenalg`. For large codebases, `NetworkX` incurred a catastrophic memory footprint due to its internal storage design (nested Python dictionaries) and massive CPU overhead during serialization/deserialization between libraries. - -### Decisions Made -1. **Complete Removal of NetworkX:** Standardize 100% of graph computation on `python-igraph`. - * **Reasoning:** `python-igraph` executes core graph operations (Strongly Connected Components, Cycle Detection, Degree Analysis, and Reachability) natively in C, providing a 10x–100x performance boost and severe memory reductions. -2. **Algorithmic Specialization:** - * **Leiden Community Detection:** Runs on high-level macro-graphs or clean subgraphs to map logical architectures. - * **Cycle Detection:** Avoid global execution of heavy algorithms (e.g., Tarjan's/Johnson's) across the entire codebase. Instead, calculate **Strongly Connected Components (SCCs)** first, treat them as single mega-nodes, and isolate deep cycle queries exclusively *within* problematic SCC clusters. - * **Reachability Analysis:** Shift away from complete transitive closure computation to localized checks or landmark-based routing approximations where appropriate. - ---- - -## 2. Structural Paradigm: Hierarchical Graph Decomposition - -### The Problem -For a worst-case modular codebase containing layers of nesting: -$$\text{Modules (m)} \rightarrow \text{Submodules (sm)} \rightarrow \text{Files (f)} \rightarrow \text{Classes (c)} \rightarrow \text{Nested Classes (nc)} \rightarrow \text{Functions (fn)} \rightarrow \text{Local Functions (lfn)}$$ -Loading a single flat graph representing line-by-line syntax relationships stalls UI rendering pipelines and breaches memory safety limits. - -### Decisions Made -1. **Divide-and-Conquer Clustered Graphs:** Deconstruct the system into a tree of isolated graphs. -2. **Bottom-Up Graph Synthesis:** * **Leaf-Level (Micro-Graphs):** Create tiny, micro-graphs for independent submodules containing local files, classes, and execution flows. - * **Macro-Level (Parent Graph):** Collapse entire submodule subgraphs into single "Meta-Nodes" using structural aggregation techniques (e.g., igraph's `contract_vertices()`). Edges between these meta-nodes represent cross-boundary imports, weighted by the cumulative frequency of interactions. -3. **Lazy-Loading Top-Down UI Pipeline:** - * The user interface initially renders only the highest level Parent Graph (representing primary modules). - * Detailed child graphs are **lazy-loaded via dedicated API endpoints** (`GET /graph/module_A`) only when a developer explicitly selects a module to explore, eliminating WebGL/Canvas rendering lags. - -- - -## 3. Incremental Rebuild & Event-Driven Parsing - -### The Problem -Re-parsing thousands of unmodified files whenever a single line of code changes is highly inefficient. However, traditional polling methods using standard directory iterations (`os.walk`) thrash disk I/O, spike CPU consumption, and fall behind when processing vast numbers of files. - -### Decisions Made -1. **Event-Driven Codebase Observer:** Replace time-interval folder-polling with an asynchronous background thread powered by the **`watchdog`** library. - * **Reasoning:** Hooks directly into native OS kernel event sub-systems (`inotify` on Linux, `FSEvents` on macOS, `ReadDirectoryChangesW` on Windows) to capture instant, lightweight file-save notifications (e.g., `FileModifiedEvent`). -2. **Surgical Patching Pipeline:** - * Upon notification, locate the explicit submodule boundary containing the altered file. - * Clear old internal nodes and attributes associated with that single file path. - * Re-parse *only* the modified file and merge the updated nodes/edges directly back into the cached submodule subgraph. - * Re-run analytics suites (SCC, Cycles, Degree) locally within the altered module scope. - - - -## 4. Cross-Submodule Dependency Management - -### The Problem -When a file is modified locally, calculating how outside modules are affected (incoming dependencies) typically requires scanning the entire system, breaking the isolated submodule paradigm. - -### Decisions Made -1. **Global Dependency Registry:** Implement a centralized, lightweight lookup schema (in-memory or SQLite-backed) tracing the usage of all exported definitions. -2. **Interface Contract Mapping:** Track structural definitions ("Provides") alongside external requirements ("Consumes"). -3. **Proxy Node System:** - * Submodules retain self-containment by using **Proxy/Stub Nodes** to represent points of contact with external targets. - * If a critical symbol (e.g., `login_user()`) is deleted or renamed inside `Submodule_A`, the graph system queries the Registry, locates all dependent Proxy Nodes across foreign graphs, and marks their internal state as `is_broken = True`. - * **Orphan and Reachability algorithms** catch these flags instantly to flag architectural breaking-changes in the UI without re-evaluating external AST structures. - -```python -# System Design Pattern: Centralized Lookups -DEPENDENCY_REGISTRY = { - "FQN_IDENTIFIER": { - "defined_in": "origin/file_path.py", - "consumed_by": ["dependent/file_path_1.py", "dependent/file_path_2.py"] - } -} - -``` - - -## 5. Language-Agnostic Normalization Engine - -### The Problem - -Hardcoding unique semantic behaviors for every programming language's Abstract Syntax Tree (AST) causes engineering bloat and scales poorly. - -### Decisions Made - -1. **Standardized Parser Backend via Tree-sitter:** Deploy **Tree-sitter** for code parsing. It parses source files into structural concrete trees using fast C-grammars and offers lightning-fast incremental updates. -2. **Declarative Pattern Queries:** Utilize Tree-sitter S-expression queries to isolate syntax targets (Classes, Functions, Imports) uniformly across files. -3. **Universal Normalization Layer (Adapter Interface):** Create an adapter system to translate concrete syntax patterns into a standardized **Universal Schema / Common Intermediate Representation (IR)** before handing elements over to the graph engine. -4. **Fully Qualified Name (FQN) Resolution:** The adapter translates varying path behaviors (relative imports, package-level structures, text inclusions) into a uniform project namespace format (`PROJECT//root/submodule/file/symbol`) to align cleanly with the Global Dependency Registry. - - -## 6. MVP Implementation Strategy - -1. **Target Environment:** Focus initial development on **Python** and structurally similar targets (e.g., Mojo, GDScript). -2. **Python Normalizer Focus:** Use Python's explicit import nuances (`import X`, `from Y import Z`, `from . import local`, and package definitions via `__init__.py`) as a rigorous testing suite to validate path resolution engines. -3. **Pipeline Construction Ordering:** -* **Milestone 1:** Build the backend storage topology using `python-igraph` supporting nested graph hierarchies. -* **Milestone 2:** Implement the centralized memory-based Global Dependency Registry. -* **Milestone 3:** Develop the Tree-sitter query extractor for Python to emit the Universal Schema. -* **Milestone 4:** Tie components together via the `watchdog` kernel event listener to realize automated, real-time graph patching. \ No newline at end of file diff --git a/package-lock.json b/package-lock.json new file mode 100644 index 0000000..5f6e7b9 --- /dev/null +++ b/package-lock.json @@ -0,0 +1,6 @@ +{ + "name": "codegenome", + "lockfileVersion": 3, + "requires": true, + "packages": {} +} diff --git a/project_identity.md b/project_identity.md deleted file mode 100644 index 6ddd274..0000000 --- a/project_identity.md +++ /dev/null @@ -1 +0,0 @@ -CodeGenome: Project Identity🚀 VisionTo render the invisible complexity of software architecture visible, manageable, and intuitive. We envision a world where every developer, regardless of the codebase's size or age, can instantly visualize their system’s structure, identify architectural bottlenecks, and navigate their code with total clarity.🎯 MissionTo provide an open-source, high-performance, and language-agnostic platform that treats code as a "living genome." Through real-time hierarchical graph decomposition, we empower developers to evolve their systems with confidence, turning static code into an interactive, self-documenting architectural atlas.🏆 GoalsEliminate Architectural Debt: Provide immediate, automated feedback on circular dependencies, bridge-node fragmentation, and god-object bloat.Ensure Zero-Friction Observability: Achieve a "living" graph representation that updates in milliseconds via event-driven kernel hooks, ensuring the documentation is never out of date.Democratize Architecture: Lower the cognitive barrier for new developers joining large projects by providing a "zoomable" interface that organizes chaos into logical sub-systems ($m \rightarrow sm \rightarrow f \rightarrow c$).Scale Through Community: Foster an ecosystem where any language (Python, TypeScript, Go, etc.) can be integrated into the CodeGenome engine via universal, schema-driven adapters.Enable Data-Driven Refactoring: Give engineers the tools to make refactoring decisions based on empirical graph data (centrality, reachability, and coupling) rather than guesswork.Why this structure matters for your PyPI release:The Vision attracts people who want to solve a "big" problem.The Mission tells them how you intend to do it (the "genome" / "interactive atlas" approach).The Goals provide a roadmap for contributors—they know exactly what success looks like for CodeGenome. \ No newline at end of file diff --git a/pyproject.toml b/pyproject.toml index ab2e5e4..dc9c188 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -4,10 +4,10 @@ build-backend = "setuptools.build_meta" [project] name = "codegenome" -version = "0.1.0" +version = "0.1.4" description = "Open-source CLI for building and querying local codebase knowledge graphs" readme = "README.md" -license = { text = "MIT" } +license = "MIT" requires-python = ">=3.11" authors = [{ name = "Watcher Contributors" }] keywords = ["code-analysis", "knowledge-graph", "mcp", "cli", "tree-sitter"] @@ -15,7 +15,6 @@ classifiers = [ "Development Status :: 3 - Alpha", "Environment :: Console", "Intended Audience :: Developers", - "License :: OSI Approved :: MIT License", "Operating System :: OS Independent", "Programming Language :: Python :: 3", "Programming Language :: Python :: 3.11", @@ -25,26 +24,32 @@ classifiers = [ "Topic :: Software Development :: Quality Assurance", ] dependencies = [ - "tree-sitter==0.21.3", - "tree-sitter-python==0.21.0", - "tree-sitter-javascript==0.21.0", - "tree-sitter-typescript==0.21.0", - "tree-sitter-go==0.21.0", - "tree-sitter-rust==0.21.2", + "tree-sitter==0.21.3; python_version < '3.12'", + "tree-sitter>=0.23,<0.26; python_version >= '3.12'", + "tree-sitter-python==0.21.0; python_version < '3.12'", + "tree-sitter-python>=0.23,<0.26; python_version >= '3.12'", + "tree-sitter-javascript==0.21.0; python_version < '3.12'", + "tree-sitter-javascript>=0.23,<0.26; python_version >= '3.12'", + "tree-sitter-typescript==0.21.0; python_version < '3.12'", + "tree-sitter-typescript>=0.23,<0.26; python_version >= '3.12'", + "tree-sitter-go==0.21.0; python_version < '3.12'", + "tree-sitter-go>=0.23,<0.26; python_version >= '3.12'", + "tree-sitter-rust==0.21.2; python_version < '3.12'", + "tree-sitter-rust>=0.23,<0.26; python_version >= '3.12'", "watchdog", "fastmcp", - "radon", "leidenalg", "python-igraph", "click", "jinja2", "websockets", "textual", + "networkx>=3.2,<4", + "pathspec>=0.12,<2", ] [project.optional-dependencies] dev = ["pytest", "pytest-cov", "ruff", "pyinstaller>=6.0,<7"] -compat = ["networkx"] [project.urls] Homepage = "https://github.com/watcher-dev/codegenome" diff --git a/requirements.txt b/requirements.txt index fa77127..cdb7500 100644 --- a/requirements.txt +++ b/requirements.txt @@ -1,19 +1,24 @@ -tree-sitter==0.21.3 -tree-sitter-python==0.21.0 -tree-sitter-javascript==0.21.0 -tree-sitter-typescript==0.21.0 -tree-sitter-go==0.21.0 -tree-sitter-rust==0.21.2 +tree-sitter==0.21.3; python_version < "3.12" +tree-sitter>=0.23,<0.26; python_version >= "3.12" +tree-sitter-python==0.21.0; python_version < "3.12" +tree-sitter-python>=0.23,<0.26; python_version >= "3.12" +tree-sitter-javascript==0.21.0; python_version < "3.12" +tree-sitter-javascript>=0.23,<0.26; python_version >= "3.12" +tree-sitter-typescript==0.21.0; python_version < "3.12" +tree-sitter-typescript>=0.23,<0.26; python_version >= "3.12" +tree-sitter-go==0.21.0; python_version < "3.12" +tree-sitter-go>=0.23,<0.26; python_version >= "3.12" +tree-sitter-rust==0.21.2; python_version < "3.12" +tree-sitter-rust>=0.23,<0.26; python_version >= "3.12" networkx>=3.2,<4 watchdog>=4.0,<5 fastmcp>=2.0,<3 -radon>=6.0,<7 leidenalg>=0.10,<1 python-igraph>=0.11,<1 -litellm>=1.40,<2 jinja2>=3.1,<4 pytest>=8.0,<9 pytest-cov>=5.0,<6 ruff>=0.4,<1 websockets>=12.0,<15 textual>=0.50,<1 +pathspec>=0.12,<2 diff --git a/src/codegenome/ai_chat.py b/src/codegenome/ai_chat.py new file mode 100644 index 0000000..e6752ca --- /dev/null +++ b/src/codegenome/ai_chat.py @@ -0,0 +1,628 @@ +"""Local AI chat helpers for the live graph UI.""" + +from __future__ import annotations + +import json +import os +import urllib.error +import urllib.parse +import urllib.request +from dataclasses import dataclass +from pathlib import Path +from typing import Any + + +PROVIDERS = { + "openai": { + "label": "OpenAI", + "api_style": "openai", + "requires_api_key": True, + "models_url": "https://api.openai.com/v1/models", + "chat_url": "https://api.openai.com/v1/chat/completions", + }, + "google": { + "label": "Google Gemini", + "api_style": "google", + "requires_api_key": True, + "models_url": "https://generativelanguage.googleapis.com/v1beta/models", + "chat_url": "https://generativelanguage.googleapis.com/v1beta/models/{model}:generateContent", + }, + "groq": { + "label": "Groq", + "api_style": "openai", + "requires_api_key": True, + "models_url": "https://api.groq.com/openai/v1/models", + "chat_url": "https://api.groq.com/openai/v1/chat/completions", + }, + "ollama": { + "label": "Ollama", + "api_style": "ollama", + "requires_api_key": False, + "models_url": "http://127.0.0.1:11434/api/tags", + "chat_url": "http://127.0.0.1:11434/api/chat", + }, + "ollama_cloud": { + "label": "Ollama Cloud", + "api_style": "ollama", + "requires_api_key": True, + "models_url": "https://ollama.com/api/tags", + "chat_url": "https://ollama.com/api/chat", + }, +} + +CONFIG_FILENAME = "ai-chat.json" +MAX_CONTEXT_NODES = 16 +MAX_CONTEXT_EDGES = 32 +MAX_NEIGHBORS = 12 +MAX_CONTEXT_CHARS = 8_000 +MAX_CONTEXT_VALUE_CHARS = 180 +MAX_RESPONSE_TOKENS = 900 +DEFAULT_CONTEXT_SIZE = "small" +CONTEXT_PROFILES = { + "max": { + "nodes": 120, + "import_edges": 1_000, + "edges": 240, + "neighbors": 48, + "chars": 60_000, + "value_chars": 320, + }, + "full": { + "nodes": 40, + "import_edges": 256, + "edges": 96, + "neighbors": 24, + "chars": 16_000, + "value_chars": 240, + }, + "medium": { + "nodes": 16, + "import_edges": 96, + "edges": 32, + "neighbors": 12, + "chars": 8_000, + "value_chars": 180, + }, + "small": { + "nodes": 8, + "import_edges": 32, + "edges": 16, + "neighbors": 6, + "chars": 4_000, + "value_chars": 140, + }, + "minimal": { + "nodes": 4, + "import_edges": 12, + "edges": 8, + "neighbors": 3, + "chars": 1_800, + "value_chars": 100, + }, +} +DEFAULT_HTTP_HEADERS = { + "Accept": "application/json", + "User-Agent": "CodeGenome/0.1 (+https://github.com/watcher-dev/codegenome)", +} + + +@dataclass(frozen=True) +class ProviderRequest: + """Validated provider request fields from the browser.""" + + provider: str + api_key: str = "" + + +class AIChatError(RuntimeError): + """Raised when a provider or local AI chat operation fails.""" + + +def settings_payload(genome_dir: Path) -> dict[str, Any]: + """Return public AI chat settings without exposing saved API keys.""" + config = _read_config(genome_dir) + api_keys = config.get("api_keys", {}) + if not isinstance(api_keys, dict): + api_keys = {} + + return { + "providers": [ + { + "id": provider_id, + "label": meta["label"], + "requires_api_key": bool(meta.get("requires_api_key", True)), + } + for provider_id, meta in PROVIDERS.items() + ], + "saved": { + provider_id: bool(api_keys.get(provider_id)) + for provider_id in PROVIDERS + }, + "default_provider": config.get("default_provider") or "openai", + } + + +def load_models( + genome_dir: Path, + provider: str, + api_key: str | None = None, + *, + save_api_key: bool = False, +) -> list[dict[str, str]]: + """Fetch available model ids for a provider.""" + request = _provider_request(genome_dir, provider, api_key) + + if request.provider == "google": + url = f"{PROVIDERS[request.provider]['models_url']}?key={urllib.parse.quote(request.api_key)}" + payload = _request_json(url, headers={}) + models = [ + model.get("name", "").removeprefix("models/") + for model in payload.get("models", []) + if "generateContent" in model.get("supportedGenerationMethods", []) + ] + elif PROVIDERS[request.provider].get("api_style") == "ollama": + headers = ( + _provider_headers(request.provider, request.api_key) + if PROVIDERS[request.provider].get("requires_api_key", True) + else {} + ) + payload = _request_json(PROVIDERS[request.provider]["models_url"], headers=headers) + models = [ + model.get("model") or model.get("name", "") + for model in payload.get("models", []) + ] + else: + payload = _request_json( + PROVIDERS[request.provider]["models_url"], + headers=_provider_headers(request.provider, request.api_key), + ) + models = [model.get("id", "") for model in payload.get("data", [])] + + cleaned = sorted({model for model in models if model}) + if not cleaned: + raise AIChatError("No chat-capable models were returned by the provider.") + + if save_api_key and PROVIDERS[request.provider].get("requires_api_key", True): + save_provider_key(genome_dir, request.provider, request.api_key) + + return [{"id": model, "label": model} for model in cleaned] + + +def chat_completion( + genome_dir: Path, + graph_json_path: Path, + provider: str, + model: str, + messages: list[dict[str, str]], + api_key: str | None = None, + selected_node_id: str | None = None, + context_size: str | None = None, + *, + save_api_key: bool = False, +) -> str: + """Ask a provider to answer against the current CodeGenome graph.""" + request = _provider_request(genome_dir, provider, api_key) + if not isinstance(messages, list): + raise AIChatError("Chat messages must be an array.") + clean_messages = _clean_messages(messages) + if not clean_messages: + raise AIChatError("Send a question before starting chat.") + if not model: + raise AIChatError("Choose a model before starting chat.") + + graph_context = build_graph_context( + graph_json_path, + selected_node_id=selected_node_id, + context_size=context_size, + ) + system_prompt = ( + "You are CodeGenome's live graph assistant. Answer using the supplied local " + "CodeGenome connectome graph context. Prefer concrete files, symbols, dependency " + "directions, risks, and next inspection steps. If the graph context is insufficient, " + "say what is missing instead of guessing." + ) + + api_style = str(PROVIDERS[request.provider].get("api_style", request.provider)) + + if api_style == "openai": + payload = { + "model": model, + "max_tokens": MAX_RESPONSE_TOKENS, + "messages": [ + {"role": "system", "content": system_prompt}, + {"role": "user", "content": graph_context}, + *clean_messages, + ], + } + response = _request_json( + PROVIDERS[request.provider]["chat_url"], + method="POST", + headers=_provider_headers(request.provider, request.api_key), + payload=payload, + timeout=90, + ) + answer = response["choices"][0]["message"]["content"] + elif api_style == "google": + url = PROVIDERS[request.provider]["chat_url"].format( + model=urllib.parse.quote(model, safe="") + ) + url = f"{url}?key={urllib.parse.quote(request.api_key)}" + prompt = "\n\n".join( + [ + system_prompt, + graph_context, + *_format_dialog_messages(clean_messages), + ] + ) + response = _request_json( + url, + method="POST", + headers={"Content-Type": "application/json"}, + payload={ + "contents": [{"role": "user", "parts": [{"text": prompt}]}], + "generationConfig": {"maxOutputTokens": MAX_RESPONSE_TOKENS}, + }, + timeout=90, + ) + parts = response["candidates"][0]["content"].get("parts", []) + answer = "".join(part.get("text", "") for part in parts) + elif api_style == "ollama": + payload = { + "model": model, + "stream": False, + "options": {"num_predict": MAX_RESPONSE_TOKENS}, + "messages": [ + {"role": "system", "content": f"{system_prompt}\n\n{graph_context}"}, + *clean_messages, + ], + } + response = _request_json( + PROVIDERS[request.provider]["chat_url"], + method="POST", + headers=_ollama_headers(request), + payload=payload, + timeout=90, + ) + answer = response.get("message", {}).get("content", "") + else: + raise AIChatError(f"Unsupported provider: {provider}") + + if save_api_key and PROVIDERS[request.provider].get("requires_api_key", True): + save_provider_key(genome_dir, request.provider, request.api_key) + + return answer.strip() + + +def build_graph_context( + graph_json_path: Path, + selected_node_id: str | None = None, + context_size: str | None = None, +) -> str: + """Build a compact text context from `.genome/graph.json`.""" + profile = _context_profile(context_size) + try: + graph = json.loads(graph_json_path.read_text(encoding="utf-8")) + except FileNotFoundError as exc: + raise AIChatError("No .genome graph JSON exists yet. Run codegenome analyze first.") from exc + except json.JSONDecodeError as exc: + raise AIChatError("The .genome graph JSON could not be parsed.") from exc + + nodes = graph.get("nodes", []) + edges = graph.get("edges", []) + metadata = graph.get("metadata", {}) + stats = metadata.get("statistics", {}) if isinstance(metadata, dict) else {} + + node_by_id = {str(node.get("id", "")): node for node in nodes if node.get("id")} + in_counts: dict[str, int] = {} + out_counts: dict[str, int] = {} + for edge in edges: + source = str(edge.get("source", "")) + target = str(edge.get("target", "")) + out_counts[source] = out_counts.get(source, 0) + 1 + in_counts[target] = in_counts.get(target, 0) + 1 + + ranked = sorted( + node_by_id.values(), + key=lambda node: ( + bool(node.get("is_bridge")), + int(node.get("complexity") or 0), + int(node.get("churn") or 0), + in_counts.get(str(node.get("id")), 0) + out_counts.get(str(node.get("id")), 0), + ), + reverse=True, + ) + + lines = [ + "Current local CodeGenome connectome graph:", + f"- context profile: {profile['name']}", + f"- graph path: {graph_json_path.as_posix()}", + "- statistics: " + + json.dumps( + stats + or { + "node_count": len(nodes), + "edge_count": len(edges), + "file_count": sum(1 for node in nodes if node.get("node_type") == "file"), + "symbol_count": sum(1 for node in nodes if node.get("node_type") == "symbol"), + }, + sort_keys=True, + ), + "", + ] + + import_edges = [edge for edge in edges if edge.get("edge_type") == "imports"] + if import_edges: + lines.append("Import edges:") + for edge in import_edges[: int(profile["import_edges"])]: + lines.append( + "- " + + json.dumps( + _compact_edge_context(edge, int(profile["value_chars"])), + sort_keys=True, + ) + ) + lines.append("") + + lines.append("Important nodes:") + for node in ranked[: int(profile["nodes"])]: + lines.append( + "- " + + json.dumps( + _compact_node_context(node, in_counts, out_counts, int(profile["value_chars"])), + sort_keys=True, + ) + ) + + if selected_node_id and selected_node_id in node_by_id: + selected = node_by_id[selected_node_id] + neighbors = _neighbors_for_context( + edges, + node_by_id, + selected_node_id, + max_neighbors=int(profile["neighbors"]), + value_chars=int(profile["value_chars"]), + ) + lines.extend( + [ + "", + "Selected node:", + json.dumps( + _compact_node_context( + selected, + in_counts, + out_counts, + int(profile["value_chars"]), + ), + sort_keys=True, + ), + "Selected node neighborhood:", + json.dumps(neighbors, sort_keys=True), + ] + ) + + lines.append("") + lines.append("Representative edges:") + for edge in edges[: int(profile["edges"])]: + lines.append("- " + json.dumps(_compact_edge_context(edge, int(profile["value_chars"])), sort_keys=True)) + + context = _fit_context_lines(lines, int(profile["chars"])) + if len(context) < len("\n".join(lines)): + context += "\n\n[Graph context truncated to fit provider request limits.]" + return context + + +def save_provider_key(genome_dir: Path, provider: str, api_key: str) -> None: + """Persist an API key in `.genome/ai-chat.json`.""" + if provider not in PROVIDERS: + raise AIChatError(f"Unsupported provider: {provider}") + if not api_key: + raise AIChatError("API key is required before it can be saved.") + + config = _read_config(genome_dir) + api_keys = config.get("api_keys") + if not isinstance(api_keys, dict): + api_keys = {} + api_keys[provider] = api_key + config.update({"version": 1, "default_provider": provider, "api_keys": api_keys}) + _write_config(genome_dir, config) + + +def _provider_request( + genome_dir: Path, + provider: str, + api_key: str | None, +) -> ProviderRequest: + if provider not in PROVIDERS: + raise AIChatError(f"Unsupported provider: {provider}") + + requires_api_key = PROVIDERS[provider].get("requires_api_key", True) + resolved_key = (api_key or "").strip() + if requires_api_key and not resolved_key: + config = _read_config(genome_dir) + api_keys = config.get("api_keys", {}) + if isinstance(api_keys, dict): + resolved_key = str(api_keys.get(provider, "")).strip() + + if requires_api_key and not resolved_key: + raise AIChatError("Enter an API key or save one for this provider first.") + return ProviderRequest(provider=provider, api_key=resolved_key) + + +def _provider_headers(provider: str, api_key: str) -> dict[str, str]: + return { + "Authorization": f"Bearer {api_key}", + "Content-Type": "application/json", + } + + +def _ollama_headers(request: ProviderRequest) -> dict[str, str]: + if PROVIDERS[request.provider].get("requires_api_key", True): + return _provider_headers(request.provider, request.api_key) + return {"Content-Type": "application/json"} + + +def _request_json( + url: str, + *, + method: str = "GET", + headers: dict[str, str], + payload: dict[str, Any] | None = None, + timeout: int = 30, +) -> dict[str, Any]: + data = None + headers = {**DEFAULT_HTTP_HEADERS, **headers} + if payload is not None: + data = json.dumps(payload).encode("utf-8") + headers = {"Content-Type": "application/json", **headers} + + request = urllib.request.Request(url, data=data, headers=headers, method=method) + try: + with urllib.request.urlopen(request, timeout=timeout) as response: + return json.loads(response.read().decode("utf-8")) + except urllib.error.HTTPError as exc: + body = exc.read().decode("utf-8", errors="replace") + detail = _provider_error_detail(body) or exc.reason + raise AIChatError(f"Provider request failed ({exc.code}): {detail}") from exc + except urllib.error.URLError as exc: + raise AIChatError(f"Provider request failed: {exc.reason}") from exc + except json.JSONDecodeError as exc: + raise AIChatError("Provider returned a response that was not JSON.") from exc + + +def _provider_error_detail(body: str) -> str: + try: + payload = json.loads(body) + except json.JSONDecodeError: + return body[:300] + error = payload.get("error") + if isinstance(error, dict): + return str(error.get("message") or error) + if isinstance(error, str): + return error + return body[:300] + + +def _clean_messages(messages: list[dict[str, str]]) -> list[dict[str, str]]: + clean = [] + for message in messages[-12:]: + if not isinstance(message, dict): + continue + role = message.get("role") + content = str(message.get("content", "")).strip() + if role in {"user", "assistant"} and content: + clean.append({"role": role, "content": content}) + return clean + + +def _format_dialog_messages(messages: list[dict[str, str]]) -> list[str]: + return [f"{message['role'].title()}: {message['content']}" for message in messages] + + +def _context_profile(context_size: str | None) -> dict[str, str | int]: + name = str(context_size or DEFAULT_CONTEXT_SIZE).strip().lower() + if name == "media": + name = "medium" + if name not in CONTEXT_PROFILES: + name = DEFAULT_CONTEXT_SIZE + return {"name": name, **CONTEXT_PROFILES[name]} + + +def _compact_node_context( + node: dict[str, Any], + in_counts: dict[str, int], + out_counts: dict[str, int], + value_chars: int = MAX_CONTEXT_VALUE_CHARS, +) -> dict[str, Any]: + node_id = str(node.get("id", "")) + return { + "id": _truncate_context_value(node_id, value_chars), + "name": _truncate_context_value(node.get("name"), value_chars), + "type": node.get("node_type"), + "file_path": _truncate_context_value(node.get("file_path"), value_chars), + "qualified_name": _truncate_context_value(node.get("qualified_name"), value_chars), + "complexity": node.get("complexity"), + "churn": node.get("churn"), + "is_bridge": node.get("is_bridge"), + "incoming": in_counts.get(node_id, 0), + "outgoing": out_counts.get(node_id, 0), + } + + +def _compact_edge_context(edge: dict[str, Any], value_chars: int) -> dict[str, Any]: + return { + "source": _truncate_context_value(edge.get("source"), value_chars), + "target": _truncate_context_value(edge.get("target"), value_chars), + "edge_type": edge.get("edge_type"), + } + + +def _truncate_context_value(value: Any, max_chars: int = MAX_CONTEXT_VALUE_CHARS) -> Any: + if not isinstance(value, str) or len(value) <= max_chars: + return value + return value[: max_chars - 16] + "...[truncated]" + + +def _fit_context_lines(lines: list[str], max_chars: int) -> str: + kept: list[str] = [] + total = 0 + for line in lines: + line_length = len(line) + (1 if kept else 0) + if total + line_length > max_chars: + break + kept.append(line) + total += line_length + return "\n".join(kept) + + +def _neighbors_for_context( + edges: list[dict[str, Any]], + node_by_id: dict[str, dict[str, Any]], + selected_node_id: str, + *, + max_neighbors: int = MAX_NEIGHBORS, + value_chars: int = MAX_CONTEXT_VALUE_CHARS, +) -> list[dict[str, Any]]: + neighbors = [] + for edge in edges: + source = str(edge.get("source", "")) + target = str(edge.get("target", "")) + if source != selected_node_id and target != selected_node_id: + continue + neighbor_id = target if source == selected_node_id else source + neighbor = node_by_id.get(neighbor_id, {}) + neighbors.append( + { + "direction": "outgoing" if source == selected_node_id else "incoming", + "edge_type": edge.get("edge_type"), + "id": _truncate_context_value(neighbor_id, value_chars), + "name": _truncate_context_value(neighbor.get("name"), value_chars), + "type": neighbor.get("node_type"), + "file_path": _truncate_context_value(neighbor.get("file_path"), value_chars), + "qualified_name": _truncate_context_value(neighbor.get("qualified_name"), value_chars), + } + ) + if len(neighbors) >= max_neighbors: + break + return neighbors + + +def _read_config(genome_dir: Path) -> dict[str, Any]: + path = genome_dir / CONFIG_FILENAME + try: + return json.loads(path.read_text(encoding="utf-8")) + except FileNotFoundError: + return {} + except json.JSONDecodeError: + return {} + + +def _write_config(genome_dir: Path, config: dict[str, Any]) -> None: + genome_dir.mkdir(parents=True, exist_ok=True) + path = genome_dir / CONFIG_FILENAME + temp_path = path.with_suffix(".tmp") + temp_path.write_text(json.dumps(config, indent=2, sort_keys=True), encoding="utf-8") + try: + os.chmod(temp_path, 0o600) + except OSError: + pass + temp_path.replace(path) diff --git a/src/codegenome/assets/html/graph-viewer.js b/src/codegenome/assets/html/graph-viewer.js index 5fce514..c179b6d 100644 --- a/src/codegenome/assets/html/graph-viewer.js +++ b/src/codegenome/assets/html/graph-viewer.js @@ -158,7 +158,8 @@ await pollLiveGraph(true); - const ws = new WebSocket('ws://localhost:8765'); + const wsPort = config.liveWsPort || 8765; + const ws = new WebSocket(`ws://${window.location.hostname}:${wsPort}`); ws.onopen = () => { console.log('WebSocket connected for live updates'); }; diff --git a/src/codegenome/cli.py b/src/codegenome/cli.py index 4b96c0a..1b80560 100644 --- a/src/codegenome/cli.py +++ b/src/codegenome/cli.py @@ -23,9 +23,12 @@ def analyze(path: str): workspace = Path(path).resolve() config = WatcherConfig(workspace=workspace, export_formats=("json",)) engine = WatcherEngine(config) + + def on_progress(message: str) -> None: + click.echo(message) try: - result = engine.build(full=False) + result = engine.build(full=False, on_progress=on_progress) click.echo(f"Build complete: {result.graph.number_of_nodes()} nodes, {result.graph.number_of_edges()} edges.") except Exception as e: click.echo(f"Error during analysis: {e}", err=True) @@ -89,11 +92,31 @@ def export(export_format: str, path: str): type=click.Path(exists=True, file_okay=False), help="Workspace path for the MCP server." ) -def mcp_start(path: str): +@click.option( + "--transport", + type=click.Choice(["stdio", "http"], case_sensitive=False), + default="stdio", + help="Transport protocol (stdio or http)." +) +@click.option( + "--port", + type=int, + default=7331, + help="Port to bind to when using HTTP transport." +) +@click.option( + "--lan", + is_flag=True, + help="Allow HTTP transport to bind on LAN (0.0.0.0) instead of localhost.", +) +def mcp_start(path: str, transport: str, port: int, lan: bool): """Initializes and starts the MCP server so external LLMs can connect. Args: path (str): The workspace directory path for the MCP server. + transport (str): Transport protocol (stdio or http). + port (int): Port to bind to when using HTTP transport. + lan (bool): Whether to expose HTTP transport on the local network. """ workspace = Path(path).resolve() config = WatcherConfig(workspace=workspace) @@ -101,27 +124,41 @@ def mcp_start(path: str): db_path = engine.db_path engine.close() # Close the engine since the MCP server process will open its own connection - click.echo(f"Starting MCP server for workspace {workspace} (DB: {db_path})...") + click.echo(f"Starting MCP server for workspace {workspace} (DB: {db_path}) via {transport}...", err=True) from codegenome.mcp_server import main as mcp_main - sys.exit(mcp_main(["--db-path", str(db_path), "--transport", "stdio"])) + args = ["--db-path", str(db_path), "--transport", transport.lower()] + if transport.lower() == "http": + host = "0.0.0.0" if lan else "127.0.0.1" + args.extend(["--host", host]) + args.extend(["--port", str(port)]) + if lan: + args.append("--allow-remote-http") + sys.exit(mcp_main(args)) @cli.command() @click.option("--live", is_flag=True, help="Enable WebSocket real-time broadcast.") +@click.option( + "--lan", + is_flag=True, + help="Expose HTTP and WebSocket on the local network (0.0.0.0).", +) @click.argument("path", default=".", type=click.Path(exists=True, file_okay=False)) -def evolve(path: str, live: bool): +def evolve(path: str, live: bool, lan: bool): """Start real-time architectural observer and open live UI. Args: path (str): The workspace directory path to observe. live (bool): Whether to enable WebSocket real-time broadcast. + lan (bool): Whether to bind services for LAN access. """ import time import threading import webbrowser from http.server import SimpleHTTPRequestHandler - from socketserver import TCPServer + from socketserver import ThreadingTCPServer from watchdog.observers import Observer + from codegenome.ai_chat import AIChatError, chat_completion, load_models, settings_payload from codegenome.watcher import WatcherConfig, WatcherEngine, SurgicalUpdateHandler workspace = Path(path).resolve() @@ -131,29 +168,120 @@ def evolve(path: str, live: bool): click.echo(f"Running initial build for {workspace}...") engine.build(full=False) + from codegenome.network_utils import get_lan_ip + + http_port = 8000 + ws_port = 8765 + bind_host = "0.0.0.0" if lan else "127.0.0.1" + lan_ip = get_lan_ip() if lan else "127.0.0.1" + live_server = None if live: from codegenome.live_server import LiveGraphServer - live_server = LiveGraphServer(host="127.0.0.1", port=8765) + live_server = LiveGraphServer(host=bind_host, port=ws_port) live_server.start_background() - click.echo("WebSocket server initialized on ws://127.0.0.1:8765") - + if lan: + click.echo(f"WebSocket server listening on ws://0.0.0.0:{ws_port}") + click.echo(f" LAN clients connect to ws://{lan_ip}:{ws_port}") + else: + click.echo(f"WebSocket server initialized on ws://127.0.0.1:{ws_port}") + def serve_forever(): - import os - os.chdir(engine.export_dir) - # Suppress logging in SimpleHTTPRequestHandler to keep terminal clean + import json + class QuietHandler(SimpleHTTPRequestHandler): + def __init__(self, *args, **kwargs): + super().__init__(*args, directory=str(engine.export_dir), **kwargs) + def log_message(self, format, *args): pass - with TCPServer(("", 8000), QuietHandler) as httpd: + + def do_GET(self): + if self.path == "/ai/settings": + self._send_json(settings_payload(engine.genome_dir)) + return + super().do_GET() + + def do_POST(self): + if self.path == "/ai/models": + self._handle_models() + return + if self.path == "/ai/chat": + self._handle_chat() + return + self.send_error(404, "Unknown AI endpoint") + + def _handle_models(self): + try: + payload = self._read_json_body() + models = load_models( + engine.genome_dir, + str(payload.get("provider", "")), + _optional_string(payload.get("api_key")), + save_api_key=bool(payload.get("save_api_key")), + ) + self._send_json({"models": models}) + except AIChatError as exc: + self._send_json({"error": str(exc)}, status=400) + except Exception as exc: # noqa: BLE001 - keep live server responsive + self._send_json({"error": f"AI model loading failed: {exc}"}, status=500) + + def _handle_chat(self): + try: + payload = self._read_json_body() + answer = chat_completion( + engine.genome_dir, + engine.graph_json_path, + str(payload.get("provider", "")), + str(payload.get("model", "")), + payload.get("messages", []), + _optional_string(payload.get("api_key")), + _optional_string(payload.get("selected_node_id")), + _optional_string(payload.get("context_size")), + save_api_key=bool(payload.get("save_api_key")), + ) + self._send_json({"message": answer}) + except AIChatError as exc: + self._send_json({"error": str(exc)}, status=400) + except Exception as exc: # noqa: BLE001 - keep live server responsive + self._send_json({"error": f"AI chat failed: {exc}"}, status=500) + + def _read_json_body(self): + length = int(self.headers.get("Content-Length", "0") or "0") + raw = self.rfile.read(length) if length else b"{}" + return json.loads(raw.decode("utf-8")) + + def _send_json(self, payload, status=200): + body = json.dumps(payload).encode("utf-8") + self.send_response(status) + self.send_header("Content-Type", "application/json") + self.send_header("Content-Length", str(len(body))) + self.send_header("Cache-Control", "no-store") + self.end_headers() + self.wfile.write(body) + + def _optional_string(value): + if value is None: + return None + text = str(value).strip() + return text or None + + with ThreadingTCPServer((bind_host if lan else "", http_port), QuietHandler) as httpd: httpd.serve_forever() - + server_thread = threading.Thread(target=serve_forever, daemon=True) server_thread.start() - - url = "http://localhost:8000/graph.html?live=1" - click.echo(f"HTTP Server started. Opening live graph UI at {url}...") - webbrowser.open(url) + + live_query = "?live=1" + local_url = f"http://localhost:{http_port}/graph.html{live_query}" + if lan: + lan_url = f"http://{lan_ip}:{http_port}/graph.html{live_query}" + click.echo(f"HTTP server listening on http://0.0.0.0:{http_port}") + click.echo(f" Open locally: {local_url}") + click.echo(f" Share on LAN: {lan_url}") + else: + click.echo(f"HTTP Server started. Opening live graph UI at {local_url}...") + webbrowser.open(local_url) click.echo("Watching for .py file changes (Press Ctrl+C to stop)...") observer = Observer() @@ -203,7 +331,6 @@ def rules(client: tuple[str], port: int, dry_run: bool, path: str): path (str): The workspace directory path. """ from codegenome.rules import generate_rules - import os workspace = Path(path).resolve() diff --git a/src/codegenome/gitignore.py b/src/codegenome/gitignore.py new file mode 100644 index 0000000..abdd621 --- /dev/null +++ b/src/codegenome/gitignore.py @@ -0,0 +1,150 @@ +"""Git-aware ignore matching with nested .gitignore and .genomeignore support.""" + +from __future__ import annotations + +from pathlib import Path + +from pathspec import GitIgnoreSpec + +IGNORE_FILENAMES = (".gitignore", ".genomeignore") + +DEFAULT_IGNORE_PATTERNS = [ + ".git/", + ".venv/", + "node_modules/", + "__pycache__/", + "*.pyc", + ".genome/", + ".genomeignore", +] + + +def _parse_ignore_lines(text: str) -> list[str]: + lines: list[str] = [] + for line in text.splitlines(): + stripped = line.strip() + if stripped and not stripped.startswith("#"): + lines.append(stripped) + return lines + + +def _rewrite_pattern(base_dir: str, pattern: str) -> str: + """Rewrite a nested ignore pattern so it applies from the workspace root.""" + if not base_dir: + return pattern + + negated = pattern.startswith("!") + body = pattern[1:] if negated else pattern + if body.startswith("/"): + rewritten = f"{base_dir}/{body[1:]}" + elif "/" in body: + rewritten = f"{base_dir}/{body}" + else: + rewritten = f"{base_dir}/**/{body}" + + return f"!{rewritten}" if negated else rewritten + + +class IgnoreMatcher: + """Match paths using gitignore semantics, including nested ignore files.""" + + def __init__( + self, + root: Path | None = None, + extra_patterns: list[str] | None = None, + *, + load_workspace_ignores: bool = True, + ) -> None: + self.root = root.resolve() if root is not None else None + self._extra_patterns = list(extra_patterns or []) + self._load_workspace_ignores = load_workspace_ignores + self._dir_lines: dict[str, list[str]] = {} + self._spec_cache: dict[tuple[tuple[str, ...], bool], GitIgnoreSpec] = {} + + @classmethod + def from_file(cls, root: Path, filename: str = ".genomeignore") -> IgnoreMatcher: + ignore_path = root / filename + extra: list[str] = [] + if ignore_path.is_file(): + extra = _parse_ignore_lines( + ignore_path.read_text(encoding="utf-8", errors="replace") + ) + return cls( + root=root, + extra_patterns=extra, + load_workspace_ignores=False, + ) + + @classmethod + def for_workspace(cls, root: Path) -> IgnoreMatcher: + return cls(root=root, load_workspace_ignores=True) + + def add_pattern(self, pattern: str) -> None: + self._extra_patterns.append(pattern) + self._spec_cache.clear() + + def _ignore_lines_for_dir(self, rel_dir: str) -> list[str]: + if rel_dir in self._dir_lines: + return self._dir_lines[rel_dir] + + if self.root is None or not self._load_workspace_ignores: + self._dir_lines[rel_dir] = [] + return [] + + abs_dir = self.root / rel_dir if rel_dir else self.root + lines: list[str] = [] + for name in IGNORE_FILENAMES: + ignore_path = abs_dir / name + if ignore_path.is_file(): + lines.extend( + _parse_ignore_lines( + ignore_path.read_text(encoding="utf-8", errors="replace") + ) + ) + self._dir_lines[rel_dir] = lines + return lines + + @staticmethod + def _ancestor_dirs(rel_path: str, is_dir: bool) -> tuple[str, ...]: + normalized = rel_path.replace("\\", "/").strip("/") + if not normalized: + return ("",) + + parts = normalized.rstrip("/").split("/") + if is_dir: + dir_parts = parts + else: + dir_parts = parts[:-1] if len(parts) > 1 else [] + + ancestors = [""] + for index in range(len(dir_parts)): + ancestors.append("/".join(dir_parts[: index + 1])) + return tuple(ancestors) + + def _spec_for_ancestors(self, ancestors: tuple[str, ...]) -> GitIgnoreSpec: + merged: list[str] = list(DEFAULT_IGNORE_PATTERNS) + merged.extend(self._extra_patterns) + for base_dir in ancestors: + for line in self._ignore_lines_for_dir(base_dir): + merged.append(_rewrite_pattern(base_dir, line)) + return GitIgnoreSpec.from_lines(merged) + + def _get_spec(self, rel_path: str, is_dir: bool) -> GitIgnoreSpec: + normalized = rel_path.replace("\\", "/").strip("/") + if is_dir and normalized: + normalized = f"{normalized}/" + ancestors = self._ancestor_dirs(normalized, is_dir) + cache_key = (ancestors, is_dir) + spec = self._spec_cache.get(cache_key) + if spec is None: + spec = self._spec_for_ancestors(ancestors) + self._spec_cache[cache_key] = spec + return spec + + def is_ignored(self, rel_path: str, is_dir: bool = False) -> bool: + normalized = rel_path.replace("\\", "/").strip("/") + if not normalized and not is_dir: + return False + + check_path = f"{normalized}/" if is_dir and normalized else normalized + return self._get_spec(check_path, is_dir).match_file(check_path) diff --git a/src/codegenome/graph_api.py b/src/codegenome/graph_api.py index d108538..c800cc5 100644 --- a/src/codegenome/graph_api.py +++ b/src/codegenome/graph_api.py @@ -2,7 +2,6 @@ from __future__ import annotations -import json from typing import Any, Iterable, Iterator, Tuple import igraph as ig diff --git a/src/codegenome/graph_store.py b/src/codegenome/graph_store.py index 480ac48..cfbd9a5 100644 --- a/src/codegenome/graph_store.py +++ b/src/codegenome/graph_store.py @@ -28,10 +28,12 @@ class GraphSummary: empty (bool): Indicates whether the snapshot contains any nodes. """ snapshot_id: int | None + latest_snapshot_id: int | None node_count: int edge_count: int label: str | None empty: bool + current: bool class GraphStore: @@ -101,6 +103,40 @@ def open(self) -> None: self._snapshot_label = latest.label self._intelligence = GraphIntelligence(self._graph) + def refresh_latest(self) -> bool: + """Load the newest timeline snapshot if it changed after startup. + + Returns: + bool: True when a newer snapshot was loaded. + """ + if self._timeline is None: + raise GraphStoreError("Timeline database is not open") + + snapshots = self._timeline.list_snapshots() + if not snapshots: + changed = self._snapshot_id is not None or not self.is_empty + self._graph = create_graph("igraph") + self._snapshot_id = None + self._snapshot_label = None + self._intelligence = GraphIntelligence(self._graph) + return changed + + latest = snapshots[-1] + if latest.snapshot_id == self._snapshot_id: + return False + + try: + self._graph = self._timeline.load_snapshot(latest.snapshot_id) + except sqlite3.Error as exc: + raise GraphStoreError( + f"Failed to load snapshot {latest.snapshot_id}: {exc}" + ) from exc + + self._snapshot_id = latest.snapshot_id + self._snapshot_label = latest.label + self._intelligence = GraphIntelligence(self._graph) + return True + def close(self) -> None: """Closes the connection to the timeline database.""" if self._timeline is not None: @@ -113,12 +149,15 @@ def summary(self) -> GraphSummary: Returns: GraphSummary: High-level metrics for the current graph state. """ + latest_snapshot_id = self._latest_snapshot_id() return GraphSummary( snapshot_id=self._snapshot_id, + latest_snapshot_id=latest_snapshot_id, node_count=self._graph.number_of_nodes(), edge_count=self._graph.number_of_edges(), label=self._snapshot_label, empty=self.is_empty, + current=self._snapshot_id == latest_snapshot_id, ) def get_graph( @@ -141,6 +180,8 @@ def get_graph( summary = self.summary() payload: dict[str, Any] = { "snapshot_id": summary.snapshot_id, + "latest_snapshot_id": summary.latest_snapshot_id, + "current": summary.current, "label": summary.label, "node_count": summary.node_count, "edge_count": summary.edge_count, @@ -328,13 +369,21 @@ def get_timeline( ] return payload - def get_dead_code(self) -> list[str]: + def get_dead_code( + self, + *, + include_generated: bool = False, + include_public_api: bool = False, + ) -> list[str]: """Detects likely dead code by finding unreferenced symbols. Returns: list[str]: A list of node IDs corresponding to unreferenced symbols. """ - return self._require_intelligence().detect_dead_code() + return self._require_intelligence().detect_dead_code( + include_generated=include_generated, + include_public_api=include_public_api, + ) def get_entry_points(self) -> list[str]: """Detects entry points to the application (e.g., main scripts, public API). @@ -344,7 +393,7 @@ def get_entry_points(self) -> list[str]: """ return self._require_intelligence().detect_entry_points() - def get_god_nodes(self) -> list[dict[str, Any]]: + def get_god_nodes(self, *, include_generated: bool = False) -> list[dict[str, Any]]: """Identifies highly connected or overly complex nodes (God Nodes). Returns: @@ -352,7 +401,9 @@ def get_god_nodes(self) -> list[dict[str, Any]]: """ return [ {"node_id": node_id, "score": score} - for node_id, score in self._require_intelligence().detect_god_nodes() + for node_id, score in self._require_intelligence().detect_god_nodes( + include_generated=include_generated + ) ] def get_circular_deps(self) -> list[list[str]]: @@ -363,7 +414,12 @@ def get_circular_deps(self) -> list[list[str]]: """ return self._require_intelligence().detect_circular_dependencies() - def get_complexity(self, *, limit: int = 25) -> list[dict[str, Any]]: + def get_complexity( + self, + *, + limit: int = 25, + include_generated: bool = False, + ) -> list[dict[str, Any]]: """Ranks nodes by their computed complexity score. Args: @@ -377,7 +433,9 @@ def get_complexity(self, *, limit: int = 25) -> list[dict[str, Any]]: """ if limit <= 0: raise ValueError("limit must be a positive integer") - rankings = self._require_intelligence().complexity_rankings()[:limit] + rankings = self._require_intelligence().complexity_rankings( + include_generated=include_generated + )[:limit] return [{"node_id": node_id, "complexity": score} for node_id, score in rankings] def get_churn( @@ -486,6 +544,12 @@ def _serialize_edges(self, *, limit: int) -> list[dict[str, Any]]: break return edges + def _latest_snapshot_id(self) -> int | None: + if self._timeline is None: + return self._snapshot_id + snapshots = self._timeline.list_snapshots() + return snapshots[-1].snapshot_id if snapshots else None + @staticmethod def _snapshot_info_dict(info: SnapshotInfo) -> dict[str, Any]: return { diff --git a/src/codegenome/installer.py b/src/codegenome/installer.py index 5cfddd9..57466d5 100644 --- a/src/codegenome/installer.py +++ b/src/codegenome/installer.py @@ -10,7 +10,7 @@ from pathlib import Path from typing import Any, Literal -SERVER_NAME = "watcher" +SERVER_NAME = "genome" TransportMode = Literal["stdio", "http"] diff --git a/src/codegenome/intelligence.py b/src/codegenome/intelligence.py index 8b27ee5..583f45a 100644 --- a/src/codegenome/intelligence.py +++ b/src/codegenome/intelligence.py @@ -50,6 +50,33 @@ class GraphIntelligence: ENTRY_FILE_NAMES = frozenset( {"__main__.py", "main.py", "app.py", "index.js", "index.ts", "index.tsx"} ) + GENERATED_PATH_PARTS = frozenset( + { + ".cache", + ".mypy_cache", + ".pytest_cache", + ".ruff_cache", + ".tox", + ".venv", + "build", + "coverage", + "dist", + "node_modules", + "site-packages", + "vendor", + "vendors", + "venv", + } + ) + GENERATED_FILE_SUFFIXES = ( + ".bundle.css", + ".bundle.js", + ".generated.css", + ".generated.js", + ".map", + ".min.css", + ".min.js", + ) def __init__( self, @@ -86,7 +113,12 @@ def analyze(self) -> IntelligenceReport: churn_rankings=self.churn_rankings(), ) - def detect_dead_code(self) -> list[str]: + def detect_dead_code( + self, + *, + include_generated: bool = False, + include_public_api: bool = False, + ) -> list[str]: """Detect functions and methods that are never called. Returns: @@ -100,8 +132,15 @@ def detect_dead_code(self) -> list[str]: for node, attrs in self.graph.iter_nodes(): if attrs.get("node_type") != "symbol": continue + if not include_generated and self._is_generated_or_vendor(attrs): + continue if attrs.get("kind") not in {"function", "method"}: continue + name = str(attrs.get("name", "")) + if self._is_dunder_name(name): + continue + if not include_public_api and self._is_public_api_method(attrs): + continue if node in entry_symbols: continue if any( @@ -142,7 +181,11 @@ def detect_circular_dependencies(self) -> list[list[str]]: cycles.sort(key=lambda cycle: (len(cycle), cycle)) return cycles - def detect_god_nodes(self) -> list[tuple[str, float]]: + def detect_god_nodes( + self, + *, + include_generated: bool = False, + ) -> list[tuple[str, float]]: """Identify nodes with excessively high degrees (god nodes). Returns: @@ -153,6 +196,8 @@ def detect_god_nodes(self) -> list[tuple[str, float]]: for node, attrs in self.graph.iter_nodes(): if attrs.get("node_type") not in {"file", "symbol"}: continue + if not include_generated and self._is_generated_or_vendor(attrs): + continue in_degree = self.graph.in_degree(node) out_degree = self.graph.out_degree(node) @@ -235,7 +280,11 @@ def detect_orphan_modules(self) -> list[str]: orphans.append(path) return sorted(orphans) - def complexity_rankings(self) -> list[tuple[str, int]]: + def complexity_rankings( + self, + *, + include_generated: bool = False, + ) -> list[tuple[str, int]]: """Rank symbols based on their cyclomatic complexity. Returns: @@ -246,6 +295,8 @@ def complexity_rankings(self) -> list[tuple[str, int]]: for node, attrs in self.graph.iter_nodes(): if attrs.get("node_type") != "symbol": continue + if not include_generated and self._is_generated_or_vendor(attrs): + continue complexity = attrs.get("complexity") if complexity is None: continue @@ -431,6 +482,36 @@ def _resolve_module_to_file( return module_index[PathLike(candidate).stem] return None + def _is_generated_or_vendor(self, attrs: dict[str, object]) -> bool: + path = str(attrs.get("file_path") or attrs.get("absolute_path") or "") + if not path: + return False + + normalized = path.replace("\\", "/").casefold() + parts = {part for part in normalized.split("/") if part} + if parts & self.GENERATED_PATH_PARTS: + return True + + name = PathLike(normalized).name + return name.endswith(self.GENERATED_FILE_SUFFIXES) + + @staticmethod + def _is_dunder_name(name: str) -> bool: + return len(name) > 4 and name.startswith("__") and name.endswith("__") + + @staticmethod + def _is_public_api_method(attrs: dict[str, object]) -> bool: + name = str(attrs.get("name", "")) + if not name or name.startswith("_"): + return False + + qname = str(attrs.get("qualified_name") or "") + if "." not in qname: + return False + + owner = qname.rsplit(".", 1)[0].rsplit(".", 1)[-1] + return bool(owner) and owner[:1].isupper() and not owner.startswith("_") + class PathLike: """Minimal path helper to avoid importing pathlib in hot loops. diff --git a/src/codegenome/mcp_server.py b/src/codegenome/mcp_server.py index 129b0e9..5d2dd25 100644 --- a/src/codegenome/mcp_server.py +++ b/src/codegenome/mcp_server.py @@ -62,6 +62,7 @@ class ServerConfig: timeout_seconds: float log_level: str transport: Literal["http", "stdio"] + allow_remote_http: bool = False def configure_logging(level: str) -> None: @@ -146,6 +147,11 @@ def parse_args(argv: list[str] | None = None) -> ServerConfig: default=os.getenv(ENV_TRANSPORT, DEFAULT_TRANSPORT), help="MCP transport protocol", ) + parser.add_argument( + "--allow-remote-http", + action="store_true", + help="Allow HTTP transport to bind non-loopback addresses.", + ) args = parser.parse_args(argv) return ServerConfig( host=args.host, @@ -154,6 +160,7 @@ def parse_args(argv: list[str] | None = None) -> ServerConfig: timeout_seconds=args.timeout, log_level=args.log_level, transport=args.transport, + allow_remote_http=args.allow_remote_http, ) @@ -171,7 +178,9 @@ def validate_config(config: ServerConfig) -> None: except ValueError as exc: raise ValueError(f"Invalid host address: {config.host}") from exc - if not host.is_loopback: + if not host.is_loopback and not ( + config.transport == "http" and config.allow_remote_http + ): raise ValueError( f"CodeGenome MCP server is localhost-only; refusing to bind to {config.host}" ) @@ -229,6 +238,7 @@ def shutdown(self) -> None: def _invoke(self, fn: Callable[..., Any], *args: Any, **kwargs: Any) -> Any: with self._lock: + self._store.refresh_latest() return fn(*args, **kwargs) def run(self, fn: Callable[..., Any], *args: Any, **kwargs: Any) -> Any: @@ -457,13 +467,15 @@ def wrapper(*args: Any, **kwargs: Any) -> dict[str, Any]: @mcp.custom_route("/health", methods=["GET"], include_in_schema=False) async def health(_request: Request) -> JSONResponse: - summary = service.store.summary() + summary = service.run(service.store.summary) payload = { "status": "ok", "service": "watcher-mcp", "version": __version__, "db_path": str(service.config.db_path), "snapshot_id": summary.snapshot_id, + "latest_snapshot_id": summary.latest_snapshot_id, + "current": summary.current, "node_count": summary.node_count, "edge_count": summary.edge_count, "empty": summary.empty, @@ -547,33 +559,45 @@ def get_timeline(node_id: str | None = None) -> dict[str, Any]: @mcp.tool @guarded_tool - def get_dead_code() -> list[str]: + def get_dead_code( + include_generated: bool = False, + include_public_api: bool = False, + ) -> dict[str, Any]: """Detect likely dead code symbols.""" - return service.store.get_dead_code() + return service.store.get_dead_code( + include_generated=include_generated, + include_public_api=include_public_api, + ) @mcp.tool @guarded_tool - def get_entry_points() -> list[str]: + def get_entry_points() -> dict[str, Any]: """Detect graph entry points.""" return service.store.get_entry_points() @mcp.tool @guarded_tool - def get_god_nodes() -> list[dict[str, Any]]: + def get_god_nodes(include_generated: bool = False) -> dict[str, Any]: """Return highly connected god nodes.""" - return service.store.get_god_nodes() + return service.store.get_god_nodes(include_generated=include_generated) @mcp.tool @guarded_tool - def get_circular_deps() -> list[list[str]]: + def get_circular_deps() -> dict[str, Any]: """Return circular file import dependencies.""" return service.store.get_circular_deps() @mcp.tool @guarded_tool - def get_complexity(limit: int = 25) -> list[dict[str, Any]]: + def get_complexity( + limit: int = 25, + include_generated: bool = False, + ) -> dict[str, Any]: """Return top complexity-ranked symbols.""" - return service.store.get_complexity(limit=limit) + return service.store.get_complexity( + limit=limit, + include_generated=include_generated, + ) @mcp.tool @guarded_tool @@ -597,7 +621,7 @@ def search_nodes( query: str, node_type: str | None = None, limit: int = 25, - ) -> list[dict[str, Any]]: + ) -> dict[str, Any]: """Search nodes by id, name, qualified name, or file path.""" return service.store.search_nodes(query, node_type=node_type, limit=limit) diff --git a/src/codegenome/network_utils.py b/src/codegenome/network_utils.py new file mode 100644 index 0000000..0ad23da --- /dev/null +++ b/src/codegenome/network_utils.py @@ -0,0 +1,19 @@ +"""Network helpers for LAN-accessible services.""" + +from __future__ import annotations + +import socket + + +def get_lan_ip() -> str: + """Return the primary LAN IPv4 address for this machine. + + Uses a UDP connect trick to discover the outbound interface IP without + sending traffic. Falls back to ``127.0.0.1`` when detection fails. + """ + try: + with socket.socket(socket.AF_INET, socket.SOCK_DGRAM) as sock: + sock.connect(("8.8.8.8", 80)) + return sock.getsockname()[0] + except OSError: + return "127.0.0.1" diff --git a/src/codegenome/parser.py b/src/codegenome/parser.py index 071d2e5..4223995 100644 --- a/src/codegenome/parser.py +++ b/src/codegenome/parser.py @@ -214,12 +214,22 @@ def _load_languages() -> dict[str, Language]: for key, module_name, attr_name, lang_name in specs: try: module = __import__(module_name) - languages[key] = Language(getattr(module, attr_name)(), lang_name) + languages[key] = _build_language(module, attr_name, lang_name) except Exception as exc: # pragma: no cover - optional grammars logger.warning("Failed to load tree-sitter grammar %s: %s", key, exc) return languages +def _build_language(module: object, attr_name: str, lang_name: str) -> Language: + """Create a Language object across tree-sitter API variants.""" + language_capsule = getattr(module, attr_name)() + try: + return Language(language_capsule, lang_name) + except TypeError: + # Newer tree-sitter releases accept only the grammar capsule. + return Language(language_capsule) + + class SourceParser: """Parse source files and extract symbols, imports, calls, and inheritance. @@ -232,8 +242,11 @@ def __init__(self) -> None: self._languages = _load_languages() self._parsers: dict[str, Parser] = {} for key, language in self._languages.items(): - parser = Parser() - parser.set_language(language) + try: + parser = Parser(language) + except TypeError: + parser = Parser() + parser.set_language(language) self._parsers[key] = parser def detect_language(self, path: Path | str) -> str | None: diff --git a/src/codegenome/rules.py b/src/codegenome/rules.py index 4c2f1af..903b4be 100644 --- a/src/codegenome/rules.py +++ b/src/codegenome/rules.py @@ -2,11 +2,8 @@ from __future__ import annotations -import os -import sys from dataclasses import dataclass from pathlib import Path -from typing import Literal try: from importlib.resources import files diff --git a/src/codegenome/scanner.py b/src/codegenome/scanner.py index b45d213..1b3c4a1 100644 --- a/src/codegenome/scanner.py +++ b/src/codegenome/scanner.py @@ -7,27 +7,23 @@ from __future__ import annotations -import fnmatch import hashlib import os import sqlite3 +from collections.abc import Callable from dataclasses import dataclass, field from pathlib import Path +from codegenome.gitignore import DEFAULT_IGNORE_PATTERNS, IgnoreMatcher -DEFAULT_IGNORE_PATTERNS = [ - ".git", - ".git/**", - ".venv", - ".venv/**", - "node_modules", - "node_modules/**", - "__pycache__", - "__pycache__/**", - "*.pyc", - ".genome", - ".genome/**", - ".genomeignore", +__all__ = [ + "DEFAULT_IGNORE_PATTERNS", + "FileRecord", + "IgnoreMatcher", + "ScanCache", + "ScanResult", + "WorkspaceScanner", + "sha256_file", ] @@ -71,99 +67,6 @@ class ScanResult: unchanged: list[str] = field(default_factory=list) -class IgnoreMatcher: - """Match paths against .genomeignore-style glob patterns. - - This class handles parsing and matching paths against ignore files, - similar to .gitignore. - """ - - def __init__(self, patterns: list[str] | None = None) -> None: - """Initialize the IgnoreMatcher with optional additional patterns. - - Args: - patterns (list[str] | None): Additional glob patterns to ignore. - """ - self._patterns = list(DEFAULT_IGNORE_PATTERNS) - if patterns: - self._patterns.extend(patterns) - - @classmethod - def from_file(cls, root: Path, filename: str = ".genomeignore") -> IgnoreMatcher: - """Create an IgnoreMatcher by reading a specific ignore file. - - Args: - root (Path): The root directory containing the ignore file. - filename (str): The name of the ignore file. Defaults to ".genomeignore". - - Returns: - IgnoreMatcher: An initialized matcher instance. - """ - ignore_path = root / filename - patterns: list[str] = [] - if ignore_path.is_file(): - for line in ignore_path.read_text(encoding="utf-8", errors="replace").splitlines(): - stripped = line.strip() - if not stripped or stripped.startswith("#"): - continue - patterns.append(stripped) - return cls(patterns) - - @classmethod - def for_workspace(cls, root: Path) -> IgnoreMatcher: - """Load default, .gitignore, and .genomeignore patterns for a workspace. - - Args: - root (Path): The root directory of the workspace. - - Returns: - IgnoreMatcher: An initialized matcher instance with workspace patterns. - """ - patterns: list[str] = [] - for filename in (".gitignore", ".genomeignore"): - ignore_path = root / filename - if not ignore_path.is_file(): - continue - for line in ignore_path.read_text(encoding="utf-8", errors="replace").splitlines(): - stripped = line.strip() - if not stripped or stripped.startswith("#"): - continue - patterns.append(stripped) - return cls(patterns) - - def is_ignored(self, rel_path: str, is_dir: bool = False) -> bool: - """Determine if a given relative path should be ignored. - - Args: - rel_path (str): The relative path to check. - is_dir (bool): Whether the path represents a directory. Defaults to False. - - Returns: - bool: True if the path matches an ignore pattern, False otherwise. - """ - normalized = rel_path.replace("\\", "/") - if is_dir and not normalized.endswith("/"): - normalized = f"{normalized}/" - - parts = normalized.split("/") - for index in range(len(parts)): - segment = "/".join(parts[: index + 1]) - if is_dir and not segment.endswith("/"): - segment = f"{segment}/" - for pattern in self._patterns: - if fnmatch.fnmatch(normalized, pattern): - return True - if fnmatch.fnmatch(segment, pattern): - return True - if fnmatch.fnmatch(parts[-1], pattern): - return True - if pattern.endswith("/"): - dir_prefix = pattern.rstrip("/") - if normalized == dir_prefix or normalized.startswith(f"{dir_prefix}/"): - return True - return False - - class ScanCache: """SQLite-backed cache of file fingerprints for incremental scans. @@ -274,7 +177,6 @@ def __init__( self, root: Path | str, cache_db: Path | str | None = None, - ignore_file: str = ".genomeignore", ) -> None: """Initialize the WorkspaceScanner. @@ -282,10 +184,9 @@ def __init__( root (Path | str): The workspace root directory. cache_db (Path | str | None): Path to the SQLite cache DB. If None, defaults to `.genome/scan_cache.db` in the workspace root. - ignore_file (str): The name of the ignore file. Defaults to ".genomeignore". """ self.root = Path(root).resolve() - self.ignore = IgnoreMatcher.from_file(self.root, ignore_file) + self.ignore = IgnoreMatcher.for_workspace(self.root) if cache_db is None: cache_db = self.root / ".genome" / "scan_cache.db" self.cache_path = Path(cache_db).resolve() @@ -297,15 +198,24 @@ def _register_cache_ignore(self) -> None: rel_cache = self.cache_path.relative_to(self.root).as_posix() except ValueError: return - if rel_cache not in self.ignore._patterns: - self.ignore._patterns.append(rel_cache) + if rel_cache: + self.ignore.add_pattern(rel_cache) - def scan(self, incremental: bool = True) -> ScanResult: + def scan( + self, + incremental: bool = True, + *, + on_progress: Callable[[int], None] | None = None, + progress_interval: int = 100, + ) -> ScanResult: """Perform a workspace scan and compare against the cache. Args: incremental (bool): If True, compare against previous cache state. If False, ignore previous state and treat all files as added. + on_progress (Callable[[int], None] | None): Optional callback invoked + periodically with the number of files scanned so far. + progress_interval (int): Minimum file count between progress callbacks. Returns: ScanResult: The result of the scan including added, modified, @@ -314,6 +224,7 @@ def scan(self, incremental: bool = True) -> ScanResult: result = ScanResult(root=str(self.root)) previous = self.cache.load_all() if incremental else {} seen: set[str] = set() + scanned = 0 if not self.root.is_dir(): self.cache.commit() @@ -354,6 +265,11 @@ def scan(self, incremental: bool = True) -> ScanResult: ) result.files.append(record) seen.add(rel_path) + scanned += 1 + if on_progress is not None and ( + scanned == 1 or scanned % progress_interval == 0 + ): + on_progress(scanned) prev = previous.get(rel_path) if prev is None: @@ -369,5 +285,8 @@ def scan(self, incremental: bool = True) -> ScanResult: result.deleted.append(path) self.cache.delete(path) + if on_progress is not None and scanned > 0 and scanned % progress_interval != 0: + on_progress(scanned) + self.cache.commit() return result diff --git a/src/codegenome/templates/graph.html.j2 b/src/codegenome/templates/graph.html.j2 index bb59314..1624aa1 100644 --- a/src/codegenome/templates/graph.html.j2 +++ b/src/codegenome/templates/graph.html.j2 @@ -8,6 +8,7 @@ + @@ -521,10 +845,12 @@ ◀ @@ -580,18 +906,24 @@
-
- - - - - +
+ + + + + + +
+
-
-
Graph Legend
+
+
+
Graph Legend
+ +
File / Module
Symbol (Class/Fn)
Import
@@ -602,6 +934,12 @@
+ + @@ -609,6 +947,85 @@ Center Graph
+ + + +
+
+
+ AI Graph Chat + Ask about the current .genome connectome. +
+
+ + +
+
+
+ +
+
+ + +
+
+ + +
+
+ + +
+
+
+ + +
+
+ + +
+
Open the panel and load models to begin.
+
+
+
+
+ + +
+
diff --git a/src/codegenome/templates/rules/cursor-rules.mdc b/src/codegenome/templates/rules/cursor-rules.mdc index 89198e1..6796262 100644 --- a/src/codegenome/templates/rules/cursor-rules.mdc +++ b/src/codegenome/templates/rules/cursor-rules.mdc @@ -9,10 +9,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists and the MCP server is healthy, you MUST use the CodeGenome MCP server (`watcher` on `http://127.0.0.1:{{MCP_PORT}}/mcp`) for all codebase, architecture, dependency, or symbol queries. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -24,5 +25,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If a tool fails due to connection issues, politely ask the user to start the MCP server: `codegenome mcp-start`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/src/codegenome/templates/rules/markdown-instructions.md b/src/codegenome/templates/rules/markdown-instructions.md index 07c4397..3666328 100644 --- a/src/codegenome/templates/rules/markdown-instructions.md +++ b/src/codegenome/templates/rules/markdown-instructions.md @@ -4,10 +4,11 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Core Directives -1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists and the MCP server is healthy, you MUST use the CodeGenome MCP server (`watcher` on `http://127.0.0.1:{{MCP_PORT}}/mcp`) for all codebase, architecture, dependency, or symbol queries. -2. **Prefer Graph over Grep**: Use the graph tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. -3. **Fallback Gracefully**: If MCP tools return empty data, instruct the user to run `codegenome analyze` before resorting to standard text searches. -4. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. +1. **Mandatory MCP Usage**: When `.genome/watcher.db` exists, you MUST use CodeGenome MCP access for all codebase, architecture, dependency, or symbol queries whenever it is available. +2. **Access Order**: First use native CodeGenome MCP tools exposed in your context. If those tools are missing, you MAY try a local MCP HTTP endpoint such as `http://127.0.0.1:{{MCP_PORT}}/mcp` when the user has started it or configured it. Treat this as MCP transport access, not as an arbitrary application HTTP API. +3. **Prefer Graph over Grep**: Use graph-backed MCP tools instead of raw file searching (`grep`) or reading entire files blindly. The graph provides semantic understanding. +4. **Fallback Gracefully**: If native MCP tools are missing and HTTP MCP access is unavailable, incompatible, or returns empty data, tell the user exactly what failed and what to configure. Then, if needed, read `.genome/graph.json` or `.genome/exports/*.md` before resorting to standard text searches. +5. **Keep Context Fresh**: After modifying code files, remind the user to run `codegenome analyze` or start the live evolution server `codegenome evolve --live` to keep the graph updated. ## Available MCP Capabilities @@ -19,5 +20,5 @@ You are operating within a repository analyzed by CodeGenome, an architectural k ## Constraints & Behaviors -- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if the MCP server is unavailable or fails to surface enough context. -- Verify your MCP usage by monitoring tool call success. If a tool fails due to connection issues, politely ask the user to start the MCP server: `codegenome mcp-start`. +- Only read `.genome/graph.json` or `.genome/exports/*.md` directly if native MCP tools and local HTTP MCP transport are unavailable or fail to surface enough context. +- Verify your MCP usage by monitoring tool call success. If native tools are missing, try the configured local HTTP MCP endpoint when possible. If both native and HTTP MCP access fail, politely ask the user to configure their editor's MCP settings to run `codegenome mcp-start` (stdio) or start the server with `codegenome mcp-start --transport http`. diff --git a/src/codegenome/tui.py b/src/codegenome/tui.py index 0531ca0..48d4b6d 100644 --- a/src/codegenome/tui.py +++ b/src/codegenome/tui.py @@ -1,198 +1,986 @@ """Textual TUI for CodeGenome.""" +from __future__ import annotations + import asyncio -import os import sys +from contextlib import suppress +from dataclasses import dataclass from pathlib import Path +from typing import Literal +from textual import events +from textual.actions import SkipAction from textual.app import App, ComposeResult from textual.containers import Container, Horizontal, Vertical -from textual.widgets import Button, Footer, Header, Input, Label, RichLog -from textual.worker import Worker, get_current_worker +from textual.selection import Selection +from textual.widgets import ( + Button, + ContentSwitcher, + Footer, + Header, + Input, + Label, + RichLog, + Static, + TabbedContent, + TabPane, +) +from textual.worker import Worker, WorkerState, get_current_worker + +from codegenome.workspace_info import ( + WorkspaceInfo, + collect_workspace_info, + format_gitignore_files_panel, + format_tracked_extensions_panel, + format_tracked_folders_panel, + format_workspace_summary, +) + +LogChannel = Literal["analyze", "mcp", "evolve", "general"] + +PAGE_SET = "page-set-workspace" +PAGE_INFO = "page-workspace-info" +PAGE_MAIN = "page-main" + + +@dataclass +class ActiveProcess: + """Track a background subprocess and its log destination.""" + + process: asyncio.subprocess.Process + channel: LogChannel + + +class ReadOnlyRichLog(RichLog): + """Console log output: selectable/copyable, not keyboard-editable.""" + + ALLOW_SELECT = True + + def get_selection(self, selection: Selection) -> tuple[str, str] | None: + """Return plain text for the selected region.""" + if not self.lines: + return None + text = "\n".join(line.text for line in self.lines) + extracted = selection.extract(text) + if not extracted: + return None + return extracted, "\n" + + def selection_updated(self, selection: Selection | None) -> None: + self._line_cache.clear() + self.refresh() + + def on_key(self, event: events.Key) -> None: + """Ignore printable keys so log panes cannot be edited.""" + if event.character and event.character.isprintable(): + event.prevent_default() + event.stop() + class CodeGenomeTUI(App): """A Textual app for managing CodeGenome.""" - + + def __init__(self, *args, **kwargs) -> None: + super().__init__(*args, **kwargs) + self._subprocesses: set[asyncio.subprocess.Process] = set() + self.active_processes: list[ActiveProcess] = [] + + BINDINGS = [ + ("ctrl+q", "quit_app", "Quit"), + ("ctrl+c", "copy_log_text", "Copy"), + ] + CSS = """ Screen { layout: vertical; } - - #workspace-container { + + ContentSwitcher { + height: 1fr; + } + + .page { + height: 1fr; + layout: vertical; + } + + #page-set-workspace { + align: center middle; + padding: 2 4; + } + + .set-workspace-panel { + width: 60; + max-width: 100%; + height: auto; + padding: 2 3; + border: solid green; + } + + .set-workspace-panel Label { + margin-bottom: 1; + } + + .set-workspace-panel Input { + margin-bottom: 1; + } + + .page-actions { height: auto; + layout: horizontal; + align: center middle; + margin-top: 1; + } + + #page-workspace-info { padding: 1 2; + } + + #workspace-scan-status { + height: auto; + margin-bottom: 1; + } + + #workspace-info-panels { + height: 1fr; + layout: horizontal; + } + + .info-panel { + width: 1fr; + height: 1fr; + layout: vertical; + border: solid $surface-lighten-1; + margin: 0 1; + padding: 1; + } + + .info-panel Label { + height: auto; + margin-bottom: 1; + } + + .info-panel ReadOnlyRichLog { + height: 1fr; + min-height: 6; + } + + #workspace-summary-bar { + height: auto; + padding: 0 2; + margin: 1 1 0 1; border: solid green; - margin: 1; } - + #commands-container { height: auto; padding: 1 2; border: solid blue; margin: 1 1 0 1; + layout: vertical; + } + + .command-row { + height: auto; layout: horizontal; align: center middle; + margin: 0 0 1 0; + } + + .command-row:last-child { + margin-bottom: 0; } - + Button { margin: 0 1; } - + #log-container { height: 1fr; - padding: 1 2; - border: solid white; - margin: 1; + padding: 0 1 1 1; + margin: 0 1 1 1; + } + + TabbedContent { + height: 1fr; } - - RichLog { + + TabPane { + padding: 0 1; + } + + .log-pane { + height: 1fr; + layout: vertical; + } + + .log-pane ReadOnlyRichLog { height: 1fr; width: 1fr; + border: solid $surface-lighten-1; + } + + #tab-analyze ReadOnlyRichLog { + border: solid cyan; + } + + #tab-mcp ReadOnlyRichLog { + border: solid green; + } + + #tab-evolve ReadOnlyRichLog { + border: solid magenta; + } + + #tab-general ReadOnlyRichLog { + border: solid white; + } + + .panel-header { + height: 1; + layout: horizontal; + align: left middle; + margin-bottom: 1; + } + + .panel-header Label { + width: 1fr; + margin: 0; + padding: 0; + height: auto; + } + + .copy-btn { + height: 1; + min-width: 8; + border: none; + padding: 0 1; + margin: 0; + background: $surface-lighten-1; + color: $text; + text-style: bold; + } + + .copy-btn:hover { + background: $primary; + color: $text; } """ - def compose(self) -> ComposeResult: - """Create child widgets for the app. + LOG_IDS: dict[LogChannel, str] = { + "analyze": "log-analyze", + "mcp": "log-mcp", + "evolve": "log-evolve", + "general": "log-general", + } + + TAB_IDS: dict[LogChannel, str] = { + "analyze": "tab-analyze", + "mcp": "tab-mcp", + "evolve": "tab-evolve", + "general": "tab-general", + } - Returns: - ComposeResult: An iterable of widgets to compose the UI. - """ + COMMAND_BUTTON_IDS: tuple[str, ...] = ( + "btn-analyze", + "btn-export", + "btn-rules", + "btn-mcp-local", + "btn-mcp-lan", + "btn-evolve-local", + "btn-evolve-lan", + "btn-stop-mcp", + "btn-stop-evolve", + ) + + def compose(self) -> ComposeResult: + """Create child widgets for the app.""" yield Header() - - with Container(id="workspace-container"): - yield Label("Workspace Root:") - yield Input(value=".", id="workspace-input", placeholder="Enter path to workspace...") - - with Horizontal(id="commands-container"): - yield Button("Analyze", id="btn-analyze", variant="primary") - yield Button("Export", id="btn-export", variant="primary") - yield Button("Generate AI Rules", id="btn-rules", variant="primary") - yield Button("Start MCP", id="btn-mcp", variant="success") - yield Button("Live Evolve", id="btn-evolve", variant="success") - yield Button("Stop Active Processes", id="btn-stop", variant="error") - - with Container(id="log-container"): - yield Label("Console Log:") - yield RichLog(id="console-log", markup=True, highlight=True) - + + with ContentSwitcher(initial=PAGE_SET): + with Container(id=PAGE_SET, classes="page"): + with Vertical(classes="set-workspace-panel"): + yield Label("[bold]Set Workspace[/bold]") + yield Label("Enter the path to your project root:") + yield Input( + value=".", id="workspace-input", placeholder="Enter path to workspace..." + ) + with Horizontal(classes="page-actions"): + yield Button("Set", id="btn-set-workspace", variant="primary") + yield Button("Quit", id="btn-quit", variant="default") + + with Container(id=PAGE_INFO, classes="page"): + yield Label("[bold]Workspace Scan Results[/bold]") + yield Static(id="workspace-scan-status", markup=True) + with Horizontal(id="workspace-info-panels"): + with Vertical(classes="info-panel"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan]Tracked Folders[/bold cyan]") + yield Button( + "Copy", id="btn-copy-folders", variant="default", classes="copy-btn" + ) + yield ReadOnlyRichLog( + id="info-folders", markup=True, highlight=False, wrap=True + ) + with Vertical(classes="info-panel"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan]File Extensions[/bold cyan]") + yield Button( + "Copy", + id="btn-copy-extensions", + variant="default", + classes="copy-btn", + ) + yield ReadOnlyRichLog( + id="info-extensions", markup=True, highlight=False, wrap=True + ) + with Vertical(classes="info-panel"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan].gitignore Files[/bold cyan]") + yield Button( + "Copy", + id="btn-copy-gitignore", + variant="default", + classes="copy-btn", + ) + yield ReadOnlyRichLog( + id="info-gitignore", markup=True, highlight=False, wrap=True + ) + with Horizontal(classes="page-actions"): + yield Button("Back", id="btn-back-to-set", variant="default") + yield Button("Continue", id="btn-continue", variant="primary", disabled=True) + + with Container(id=PAGE_MAIN, classes="page"): + with Horizontal(id="workspace-summary-bar"): + yield Static(id="workspace-summary", markup=True) + yield Button("Change Workspace", id="btn-change-workspace", variant="default") + + with Container(id="commands-container"): + with Horizontal(classes="command-row"): + yield Button("Analyze", id="btn-analyze", variant="primary") + yield Button("Export", id="btn-export", variant="primary") + yield Button("Generate AI Rules", id="btn-rules", variant="primary") + yield Button( + "Start MCP HTTP (Local)", id="btn-mcp-local", variant="success" + ) + yield Button("Start MCP HTTP (LAN)", id="btn-mcp-lan", variant="warning") + with Horizontal(classes="command-row"): + yield Button( + "Live Evolve (Local)", id="btn-evolve-local", variant="success" + ) + yield Button("Live Evolve (LAN)", id="btn-evolve-lan", variant="success") + + with Container(id="log-container"): + with TabbedContent(initial="tab-analyze"): + with TabPane("Analyze", id="tab-analyze"): + with Vertical(classes="log-pane"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan]Analyze Log[/bold cyan]") + yield Button( + "Copy", + id="btn-copy-analyze", + variant="default", + classes="copy-btn", + ) + yield ReadOnlyRichLog(id="log-analyze", markup=True, highlight=True) + with TabPane("MCP Server", id="tab-mcp"): + with Vertical(classes="log-pane"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan]MCP Server Log[/bold cyan]") + yield Button( + "Copy", + id="btn-copy-mcp", + variant="default", + classes="copy-btn", + ) + yield ReadOnlyRichLog(id="log-mcp", markup=True, highlight=True) + with TabPane("Live Evolve", id="tab-evolve"): + with Vertical(classes="log-pane"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan]Live Evolve Log[/bold cyan]") + yield Button( + "Copy", + id="btn-copy-evolve", + variant="default", + classes="copy-btn", + ) + yield ReadOnlyRichLog(id="log-evolve", markup=True, highlight=True) + with TabPane("General", id="tab-general"): + with Vertical(classes="log-pane"): + with Horizontal(classes="panel-header"): + yield Label("[bold cyan]General Log[/bold cyan]") + yield Button( + "Copy", + id="btn-copy-general", + variant="default", + classes="copy-btn", + ) + yield ReadOnlyRichLog(id="log-general", markup=True, highlight=True) + + with Horizontal(classes="page-actions"): + yield Button("Stop MCP Server", id="btn-stop-mcp", variant="error") + yield Button("Stop Live Evolve", id="btn-stop-evolve", variant="error") + yield Button("Quit", id="btn-quit-main", variant="default") + yield Footer() def on_mount(self) -> None: """Called when app starts. Initializes widgets and state.""" - self.log_widget = self.query_one(RichLog) + self._workspace_poll_timer = None + self.pages = self.query_one(ContentSwitcher) self.workspace_input = self.query_one("#workspace-input", Input) - self.active_processes = [] - self.log_widget.write("[bold green]CodeGenome TUI Initialized.[/bold green]") - self.log_widget.write("Enter a workspace path and click a command to begin.") + self.workspace_scan_status = self.query_one("#workspace-scan-status", Static) + self.info_folders_log = self.query_one("#info-folders", ReadOnlyRichLog) + self.info_extensions_log = self.query_one("#info-extensions", ReadOnlyRichLog) + self.info_gitignore_log = self.query_one("#info-gitignore", ReadOnlyRichLog) + self.workspace_summary = self.query_one("#workspace-summary", Static) + self.continue_button = self.query_one("#btn-continue", Button) + self.set_workspace_button = self.query_one("#btn-set-workspace", Button) + self.log_tabs = self.query_one(TabbedContent) + self.log_widgets: dict[LogChannel, ReadOnlyRichLog] = { + channel: self.query_one(f"#{log_id}", ReadOnlyRichLog) + for channel, log_id in self.LOG_IDS.items() + } + self.command_buttons: dict[str, Button] = { + button_id: self.query_one(f"#{button_id}", Button) + for button_id in self.COMMAND_BUTTON_IDS + } + self._workspace_path: str | None = None + self._pending_workspace_info: WorkspaceInfo | None = None + self._main_initialized = False + + self.set_commands_enabled(False) + + def show_page(self, page_id: str) -> None: + """Switch to the given page.""" + self.pages.current = page_id def get_workspace_path(self) -> str: - """Get the current workspace path from input. + """Return the active workspace path.""" + if self._workspace_path is not None: + return self._workspace_path + return self.workspace_input.value.strip() or "." - Returns: - str: The workspace path entered by the user. - """ - return self.workspace_input.value + def set_commands_enabled(self, enabled: bool) -> None: + """Enable or disable command buttons while a workspace scan runs.""" + for button in self.command_buttons.values(): + button.disabled = not enabled - def on_button_pressed(self, event: Button.Pressed) -> None: - """Event handler called when a button is pressed. + def set_workspace_flow_enabled(self, enabled: bool) -> None: + """Enable or disable workspace setup controls during a scan.""" + self.set_workspace_button.disabled = not enabled + self.workspace_input.disabled = not enabled + + def clear_workspace_scan_panels(self, message: str = "") -> None: + """Clear the three scan result panels.""" + for panel in (self.info_folders_log, self.info_extensions_log, self.info_gitignore_log): + panel.clear() + if message: + panel.write(message) + + def update_workspace_scan_panels(self, info: WorkspaceInfo) -> None: + """Populate the three scan result panels from workspace info.""" + if info.error: + self.workspace_scan_status.update( + f"[bold]Root:[/bold] {info.root} [bold red]Error:[/bold red] {info.error}" + ) + else: + dir_count = len(info.tracked_directories) + file_count = len(info.tracked_files) + self.workspace_scan_status.update( + f"[bold]Root:[/bold] {info.root} " + f"[dim]|[/dim] " + f"{file_count} file{'s' if file_count != 1 else ''} in " + f"{dir_count} director{'ies' if dir_count != 1 else 'y'}" + ) + + self.info_folders_log.clear() + self.info_folders_log.write(format_tracked_folders_panel(info)) + + self.info_extensions_log.clear() + self.info_extensions_log.write(format_tracked_extensions_panel(info)) + + self.info_gitignore_log.clear() + self.info_gitignore_log.write(format_gitignore_files_panel(info)) + + def refresh_workspace_info(self, *, on_page: str = PAGE_INFO) -> None: + """Load ignore rules and tracked paths for the current workspace input.""" + path = self.workspace_input.value.strip() or "." + self.set_workspace_flow_enabled(False) + self.continue_button.disabled = True + self.workspace_scan_status.update("[dim]Scanning workspace...[/dim]") + self.clear_workspace_scan_panels("[dim]Scanning...[/dim]") + self.show_page(on_page) + self.run_worker( + self._load_workspace_info(path), + exclusive=True, + group="workspace-info", + ) + + async def _load_workspace_info(self, path: str) -> None: + """Collect workspace info off the UI thread and update the panel.""" + worker = get_current_worker() + if worker.is_cancelled: + return + + info = await asyncio.to_thread(collect_workspace_info, Path(path)) + if worker.is_cancelled: + return + + self._pending_workspace_info = info + self.update_workspace_scan_panels(info) + + def background_refresh_workspace_info(self) -> None: + """Periodically refresh workspace counts in the background.""" + if ( + getattr(self, "_workspace_path", None) + and getattr(self, "pages", None) + and self.pages.current == PAGE_MAIN + ): + self.run_worker( + self._do_background_refresh(self._workspace_path), + exclusive=True, + group="workspace-info-bg", + ) + + async def _do_background_refresh(self, path: str) -> None: + """Fetch updated info without blocking or changing UI state heavily.""" + worker = get_current_worker() + info = await asyncio.to_thread(collect_workspace_info, Path(path)) + if worker.is_cancelled: + return - Args: - event (Button.Pressed): The button press event. - """ + # Only update the summary bar to avoid flashing the UI + self.workspace_summary.update(format_workspace_summary(info)) + + def on_worker_state_changed(self, event: Worker.StateChanged) -> None: + """Re-enable controls and surface workspace scan failures.""" + if event.worker.group != "workspace-info": + return + + self.set_workspace_flow_enabled(True) + + if event.state == WorkerState.SUCCESS: + info = self._pending_workspace_info + self.continue_button.disabled = info is None or info.error is not None + return + + if event.state == WorkerState.ERROR: + self.continue_button.disabled = True + self.workspace_scan_status.update( + f"[bold red]Failed to scan workspace:[/bold red] {event.worker.error}" + ) + self.clear_workspace_scan_panels("[bold red]Scan failed[/bold red]") + + def enter_main_dashboard(self) -> None: + """Show the main dashboard after workspace confirmation.""" + info = self._pending_workspace_info + if info is None or info.error is not None: + return + + self._workspace_path = info.root + self.workspace_summary.update(format_workspace_summary(info)) + self.show_page(PAGE_MAIN) + + if getattr(self, "_workspace_poll_timer", None) is None: + self._workspace_poll_timer = self.set_interval( + 5.0, self.background_refresh_workspace_info + ) + + if not self._main_initialized: + self._main_initialized = True + self.write_log("general", "[bold green]CodeGenome TUI initialized.[/bold green]") + self.write_log("general", "Use Analyze, MCP, or Live Evolve from the command buttons.") + self.write_log("analyze", "[dim]Analyze output appears here.[/dim]") + self.write_log("mcp", "[dim]MCP server output appears here.[/dim]") + self.write_log("evolve", "[dim]Live Evolve output appears here.[/dim]") + + self.set_commands_enabled(True) + + def write_log(self, channel: LogChannel, message: str) -> None: + """Append a line to the log panel for the given channel.""" + self.log_widgets[channel].write(message) + + def focus_log_tab(self, channel: LogChannel) -> None: + """Switch the visible tab to the given log channel.""" + self.log_tabs.active = self.TAB_IDS[channel] + + def copy_panel_output(self, log_widget: ReadOnlyRichLog, panel_name: str) -> None: + """Get the text from a ReadOnlyRichLog and copy it to clipboard.""" + text = "\n".join(line.text for line in log_widget.lines) + if not text: + self.notify(f"No content to copy in {panel_name}.", severity="warning") + return + self.copy_to_clipboard(text) + self.notify(f"Copied {panel_name} output to clipboard!") + + def on_button_pressed(self, event: Button.Pressed) -> None: + """Handle command button presses.""" button_id = event.button.id + if button_id in self.COMMAND_BUTTON_IDS and event.button.disabled: + return + + if button_id == "btn-copy-folders": + self.copy_panel_output(self.info_folders_log, "Tracked Folders") + return + elif button_id == "btn-copy-extensions": + self.copy_panel_output(self.info_extensions_log, "File Extensions") + return + elif button_id == "btn-copy-gitignore": + self.copy_panel_output(self.info_gitignore_log, ".gitignore Files") + return + elif button_id == "btn-copy-analyze": + self.copy_panel_output(self.log_widgets["analyze"], "Analyze Log") + return + elif button_id == "btn-copy-mcp": + self.copy_panel_output(self.log_widgets["mcp"], "MCP Server Log") + return + elif button_id == "btn-copy-evolve": + self.copy_panel_output(self.log_widgets["evolve"], "Live Evolve Log") + return + elif button_id == "btn-copy-general": + self.copy_panel_output(self.log_widgets["general"], "General Log") + return + + if button_id == "btn-set-workspace": + self.refresh_workspace_info() + return + + if button_id == "btn-back-to-set": + self.show_page(PAGE_SET) + return + + if button_id == "btn-continue": + self.enter_main_dashboard() + return + + if button_id == "btn-change-workspace": + self.show_page(PAGE_SET) + return + workspace = self.get_workspace_path() - + if button_id == "btn-analyze": - self.run_command(["codegenome", "analyze", workspace]) + self.run_command( + ["codegenome", "analyze", workspace], + channel="analyze", + ) elif button_id == "btn-export": - self.run_command(["codegenome", "export", "--format", "json", "--path", workspace]) + self.run_command( + ["codegenome", "export", "--format", "json", "--path", workspace], + channel="general", + ) elif button_id == "btn-rules": - self.run_command(["codegenome", "rules", "--client", "all", workspace]) - elif button_id == "btn-mcp": - self.run_command(["codegenome", "mcp-start", "--path", workspace], is_background=True) - elif button_id == "btn-evolve": - self.run_command(["codegenome", "evolve", "--live", workspace], is_background=True) - elif button_id == "btn-stop": - self.stop_all_processes() - - def run_command(self, cmd: list[str], is_background: bool = False) -> None: - """Run a CLI command in a worker. - - Args: - cmd (list[str]): The command list to execute. - is_background (bool, optional): Whether to run the process in the background. Defaults to False. - """ + self.run_command( + ["codegenome", "rules", "--client", "all", workspace], + channel="general", + ) + elif button_id == "btn-mcp-local": + self.run_command( + [ + "codegenome", + "mcp-start", + "--path", + workspace, + "--transport", + "http", + "--port", + "7331", + ], + channel="mcp", + is_background=True, + ) + elif button_id == "btn-mcp-lan": + self.run_command( + [ + "codegenome", + "mcp-start", + "--path", + workspace, + "--transport", + "http", + "--port", + "7331", + "--lan", + ], + channel="mcp", + is_background=True, + ) + elif button_id == "btn-evolve-local": + self.run_command( + ["codegenome", "evolve", "--live", workspace], + channel="evolve", + is_background=True, + ) + elif button_id == "btn-evolve-lan": + self.run_command( + ["codegenome", "evolve", "--live", "--lan", workspace], + channel="evolve", + is_background=True, + ) + elif button_id == "btn-stop-mcp": + self.stop_processes_for_channel("mcp", "MCP server") + elif button_id == "btn-stop-evolve": + self.stop_processes_for_channel("evolve", "Live Evolve") + elif button_id in ("btn-quit", "btn-quit-main"): + self.quit_app() + + def run_command( + self, + cmd: list[str], + *, + channel: LogChannel, + is_background: bool = False, + ) -> None: + """Run a CLI command and stream output to the matching log panel.""" command_str = " ".join(cmd) - self.log_widget.write(f"\n[bold blue]> Running:[/bold blue] {command_str}") - self.run_worker(self._execute_process(cmd, is_background), exclusive=False) + self.focus_log_tab(channel) + self.write_log(channel, f"\n[bold blue]> Running:[/bold blue] {command_str}") + self.run_worker( + self._execute_process(cmd, channel=channel, is_background=is_background), + exclusive=False, + exit_on_error=False, + group="command", + ) + + def _track_subprocess(self, process: asyncio.subprocess.Process) -> None: + """Register a subprocess so shutdown can close its pipes.""" + self._subprocesses.add(process) + + def _untrack_subprocess(self, process: asyncio.subprocess.Process) -> None: + """Remove a subprocess after its pipes are closed.""" + self._subprocesses.discard(process) + + async def _close_subprocess(self, process: asyncio.subprocess.Process) -> None: + """Terminate a subprocess and close pipes (avoids Windows Proactor warnings).""" + if process.returncode is None: + process.terminate() + with suppress(asyncio.TimeoutError, ProcessLookupError): + await asyncio.wait_for(process.wait(), timeout=5.0) + if process.returncode is None: + with suppress(ProcessLookupError): + process.kill() + with suppress(asyncio.TimeoutError, ProcessLookupError): + await asyncio.wait_for(process.wait(), timeout=5.0) + + self._close_process_pipes(process) + + def _close_process_pipes(self, process: asyncio.subprocess.Process) -> None: + """Close subprocess pipe transports without using StreamReader.wait_closed().""" + transport = process._transport + if transport is None: + return + + for stream in (process.stdout, process.stderr): + if stream is not None: + with suppress(Exception): + if not stream.at_eof(): + stream.feed_eof() + + for fd in (1, 2): + with suppress(Exception): + pipe_transport = transport.get_pipe_transport(fd) + if pipe_transport is not None and not pipe_transport.is_closing(): + pipe_transport.close() + + if process.stdin is not None: + with suppress(Exception): + process.stdin.close() - async def _execute_process(self, cmd: list[str], is_background: bool) -> None: - """Execute subprocess asynchronously. + with suppress(Exception): + if not transport.is_closing(): + transport.close() - Args: - cmd (list[str]): The command list to execute. - is_background (bool): Whether the process should run in the background. - """ + def _remove_active_process(self, process: asyncio.subprocess.Process) -> LogChannel | None: + """Remove a process from the active list and return its log channel.""" + for index, active in enumerate(self.active_processes): + if active.process is process: + self.active_processes.pop(index) + return active.channel + return None + + async def _execute_process( + self, + cmd: list[str], + *, + channel: LogChannel, + is_background: bool, + ) -> None: + """Execute subprocess asynchronously and route output to the log panel.""" worker = get_current_worker() - + process: asyncio.subprocess.Process | None = None + cancelled = False + try: - # We use sys.executable to ensure we run in the same python env if cmd[0] == "codegenome": cmd = [sys.executable, "-m", "codegenome.cli"] + cmd[1:] - + process = await asyncio.create_subprocess_exec( *cmd, - stdin=asyncio.subprocess.PIPE, + stdin=asyncio.subprocess.DEVNULL, stdout=asyncio.subprocess.PIPE, stderr=asyncio.subprocess.STDOUT, ) - + self._track_subprocess(process) + if is_background: - self.active_processes.append(process) - self.log_widget.write(f"[italic]Started background process (PID: {process.pid})[/italic]") - + self.active_processes.append(ActiveProcess(process=process, channel=channel)) + self.write_log( + channel, + f"[italic]Started background process (PID: {process.pid})[/italic]", + ) + while True: if worker.is_cancelled: - process.terminate() + cancelled = True + break + + if process.stdout is None: break - + line = await process.stdout.readline() if not line: break - - text = line.decode().rstrip() - # Run the log write directly since async workers run in the main asyncio loop - self.log_widget.write(text) - - await process.wait() - - if is_background and process in self.active_processes: - self.active_processes.remove(process) - - status_color = "green" if process.returncode == 0 else "red" - self.log_widget.write(f"[[bold {status_color}]Process exited with code {process.returncode}[/bold {status_color}]]") - - except Exception as e: - self.log_widget.write(f"[bold red]Error:[/bold red] {e}") + + text = line.decode(errors="replace").rstrip() + self.write_log(channel, text) + + except asyncio.CancelledError: + cancelled = True + raise + except Exception as exc: + self.write_log(channel, f"[bold red]Error:[/bold red] {exc}") + if process is not None: + removed_channel = self._remove_active_process(process) + if removed_channel is not None: + self.write_log( + removed_channel, + f"[bold red]Process failed:[/bold red] {exc}", + ) + else: + removed_channel = self._remove_active_process(process) + if removed_channel is not None: + channel = removed_channel + + if process is not None and not cancelled: + status_color = "green" if process.returncode == 0 else "red" + self.write_log( + channel, + f"[[bold {status_color}]Process exited with code {process.returncode}[/bold {status_color}]]", + ) + finally: + if process is not None: + self._untrack_subprocess(process) + self._remove_active_process(process) + await asyncio.shield(self._close_subprocess(process)) def stop_all_processes(self) -> None: """Stop all active background processes.""" if not self.active_processes: - self.log_widget.write("[yellow]No active background processes to stop.[/yellow]") + self.write_log("general", "[yellow]No active background processes to stop.[/yellow]") + self.focus_log_tab("general") + return + + self.run_worker( + self._stop_processes( + list(self.active_processes), + completion_message="[yellow]All background processes stopped.[/yellow]", + ), + exclusive=False, + ) + + def stop_processes_for_channel(self, channel: LogChannel, label: str) -> None: + """Stop active background processes for a specific log channel.""" + matching = [active for active in self.active_processes if active.channel == channel] + if not matching: + self.write_log(channel, f"[yellow]No active {label} process to stop.[/yellow]") + self.focus_log_tab(channel) return - - for p in self.active_processes: + + self.run_worker( + self._stop_processes( + matching, + completion_message=f"[yellow]{label} processes stopped.[/yellow]", + ), + exclusive=False, + ) + + async def _stop_processes( + self, + processes: list[ActiveProcess], + *, + completion_message: str, + ) -> None: + """Async cleanup for background subprocesses.""" + for active in processes: try: - p.terminate() - self.log_widget.write(f"[yellow]Terminated process (PID: {p.pid})[/yellow]") - except Exception as e: - self.log_widget.write(f"[red]Failed to terminate PID {p.pid}: {e}[/red]") - self.active_processes.clear() + await self._close_subprocess(active.process) + self._untrack_subprocess(active.process) + self._remove_active_process(active.process) + self.write_log( + active.channel, + f"[yellow]Terminated process (PID: {active.process.pid})[/yellow]", + ) + except Exception as exc: + self.write_log( + active.channel, + f"[red]Failed to terminate PID {active.process.pid}: {exc}[/red]", + ) + self.write_log("general", completion_message) + self.focus_log_tab("general") + + async def _cleanup_subprocesses(self) -> None: + """Close every tracked subprocess and its pipes.""" + if hasattr(self, "_subprocesses"): + for process in list(self._subprocesses): + with suppress(Exception): + await asyncio.shield(self._close_subprocess(process)) + self._subprocesses.clear() + if hasattr(self, "active_processes"): + self.active_processes.clear() + + def action_copy_log_text(self) -> None: + """Copy selected log text to the clipboard.""" + try: + self.screen.action_copy_text() + except SkipAction: + self.notify( + "Select text in a log panel first, then press Ctrl+C.", + severity="warning", + ) + + def action_quit_app(self) -> None: + """Handle quit action from bindings.""" + self.quit_app() -def main(): + def quit_app(self) -> None: + """Stop running subprocesses and exit the TUI.""" + self.run_worker( + self._shutdown_and_exit(), + exclusive=True, + group="shutdown", + exit_on_error=False, + ) + + async def _shutdown_and_exit(self) -> None: + """Terminate subprocesses, close pipes, then exit cleanly.""" + if getattr(self, "_subprocesses", None): + self.write_log("general", "[yellow]Stopping running commands...[/yellow]") + + await self._cleanup_subprocesses() + self.exit() + + async def on_unmount(self) -> None: + """Ensure subprocess pipes are closed when the app exits.""" + await self._cleanup_subprocesses() + + +def main() -> None: """Entry point for the CodeGenome TUI.""" app = CodeGenomeTUI() app.run() + if __name__ == "__main__": main() diff --git a/src/codegenome/version.py b/src/codegenome/version.py index 831c8ac..e47e837 100644 --- a/src/codegenome/version.py +++ b/src/codegenome/version.py @@ -1,3 +1,3 @@ """Version information for the CodeGenome package.""" -__version__ = "0.1.0" +__version__ = "0.1.4" diff --git a/src/codegenome/watcher.py b/src/codegenome/watcher.py index bf1851e..07d0c3e 100644 --- a/src/codegenome/watcher.py +++ b/src/codegenome/watcher.py @@ -10,7 +10,7 @@ import time from dataclasses import dataclass, field from pathlib import Path -from typing import Iterable +from typing import Callable, Iterable import networkx as nx from watchdog.events import FileSystemEvent, FileSystemEventHandler @@ -30,6 +30,9 @@ DEFAULT_EXPORT_FORMATS = ("json", "html", "markdown") +ProgressCallback = Callable[[str], None] +PARSE_PROGRESS_INTERVAL = 50 + @dataclass class WatcherConfig: @@ -201,23 +204,51 @@ def __init__(self, config: WatcherConfig) -> None: self._mcp_process: subprocess.Popen[str] | None = None self._loaded_existing_graph = self._load_existing_graph() - def build(self, *, full: bool = False) -> BuildResult: + def build( + self, + *, + full: bool = False, + on_progress: ProgressCallback | None = None, + ) -> BuildResult: """Build or rebuild the graph from source files. Args: full (bool, optional): Force a full rebuild instead of incremental. Defaults to False. + on_progress (ProgressCallback | None, optional): Optional callback for + human-readable progress messages during long-running phases. Returns: BuildResult: The result of the build process. """ + def emit(message: str) -> None: + if on_progress is not None: + on_progress(message) + incremental = not full and self._loaded_existing_graph - scan = self.scanner.scan(incremental=incremental) - parses = self._parse_scan(scan) + emit("Scanning workspace...") + scan = self.scanner.scan( + incremental=incremental, + on_progress=lambda count: emit(f"Scanning... {count:,} files"), + ) + file_count = len(scan.files) + change_parts: list[str] = [] + if scan.added: + change_parts.append(f"{len(scan.added):,} added") + if scan.modified: + change_parts.append(f"{len(scan.modified):,} modified") + if scan.deleted: + change_parts.append(f"{len(scan.deleted):,} deleted") + change_summary = f" ({', '.join(change_parts)})" if change_parts else "" + emit(f"Scan complete: {file_count:,} files{change_summary}") + + parses = self._parse_scan(scan, on_progress=on_progress) if incremental and self.builder.graph.number_of_nodes() > 0: + emit("Updating graph...") graph, provides, consumes = self.builder.update(scan, parses) label = "incremental" else: + emit("Building graph...") graph, provides, consumes = self.builder.build(scan, parses) label = "full" @@ -233,12 +264,14 @@ def build(self, *, full: bool = False) -> BuildResult: self._flag_broken_proxy(graph, dep_path, fqn) self.clusterer.annotate(graph) + emit("Analyzing dependencies...") intelligence = GraphIntelligence(graph, registry=self.registry) - report = intelligence.analyze() + intel_report = intelligence.analyze() + emit("Exporting graph...") exporter = GraphExporter( graph, - report=report, + report=intel_report, workspace_name=self.workspace.name, ) @@ -248,7 +281,7 @@ def build(self, *, full: bool = False) -> BuildResult: return BuildResult( graph=graph, - report=report, + report=intel_report, snapshot_id=snapshot_id, export_paths=export_paths, ) @@ -509,15 +542,30 @@ def _load_existing_graph(self) -> bool: self.builder.graph = self.timeline.load_snapshot(latest.snapshot_id) return self.builder.graph.number_of_nodes() > 0 - def _parse_scan(self, scan: ScanResult) -> dict: + def _parse_scan( + self, + scan: ScanResult, + *, + on_progress: ProgressCallback | None = None, + ) -> dict: parses = {} - for record in scan.files: + total = len(scan.files) + if on_progress is not None: + on_progress(f"Parsing 0 / {total:,} files...") + + for index, record in enumerate(scan.files, start=1): rel_path = record.path if scan.deleted and rel_path in scan.deleted: continue parsed = self.parser.parse_file(record.absolute_path) if parsed is not None: parses[rel_path] = parsed + if on_progress is not None and ( + index == 1 + or index == total + or index % PARSE_PROGRESS_INTERVAL == 0 + ): + on_progress(f"Parsing {index:,} / {total:,} files...") return parses def _run_exports( diff --git a/src/codegenome/workspace_info.py b/src/codegenome/workspace_info.py new file mode 100644 index 0000000..a848e1e --- /dev/null +++ b/src/codegenome/workspace_info.py @@ -0,0 +1,292 @@ +"""Collect workspace ignore rules and tracked paths for UI display.""" + +from __future__ import annotations + +import os +from dataclasses import dataclass, field +from pathlib import Path + +from codegenome.gitignore import DEFAULT_IGNORE_PATTERNS, IGNORE_FILENAMES, IgnoreMatcher + + +@dataclass(frozen=True) +class IgnoreFileInfo: + """An ignore file discovered under the workspace root.""" + + relative_path: str + filename: str + patterns: tuple[str, ...] + + +@dataclass(frozen=True) +class WorkspaceInfo: + """Snapshot of ignore configuration and tracked paths for one workspace.""" + + root: str + exists: bool + is_directory: bool + error: str | None = None + default_patterns: tuple[str, ...] = field(default_factory=lambda: tuple(DEFAULT_IGNORE_PATTERNS)) + ignore_files: tuple[IgnoreFileInfo, ...] = () + tracked_directories: tuple[str, ...] = () + tracked_files: tuple[str, ...] = () + + +def collect_workspace_info(root: Path | str) -> WorkspaceInfo: + """Walk a workspace and collect ignore files plus tracked paths.""" + resolved = Path(root).expanduser() + try: + resolved = resolved.resolve() + except OSError as exc: + return WorkspaceInfo( + root=str(root), + exists=False, + is_directory=False, + error=str(exc), + ) + + if not resolved.exists(): + return WorkspaceInfo( + root=str(resolved), + exists=False, + is_directory=False, + error="Path does not exist", + ) + + if not resolved.is_dir(): + return WorkspaceInfo( + root=str(resolved), + exists=True, + is_directory=False, + error="Path is not a directory", + ) + + ignore = IgnoreMatcher.for_workspace(resolved) + ignore_files = _discover_ignore_files(resolved, ignore) + tracked_directories, tracked_files = _collect_tracked_paths(resolved, ignore) + + return WorkspaceInfo( + root=str(resolved), + exists=True, + is_directory=True, + ignore_files=tuple(ignore_files), + tracked_directories=tuple(tracked_directories), + tracked_files=tuple(tracked_files), + ) + + +def _discover_ignore_files(root: Path, ignore: IgnoreMatcher) -> list[IgnoreFileInfo]: + """Collect ignore files from directories visited by the same walk as scanning.""" + found: list[IgnoreFileInfo] = [] + + for dirpath, dirnames, _ in os.walk(root): + current = Path(dirpath) + rel_dir = current.relative_to(root).as_posix() + if rel_dir == ".": + rel_dir = "" + + dirnames[:] = [ + name + for name in dirnames + if not ignore.is_ignored(f"{rel_dir}/{name}".strip("/"), is_dir=True) + ] + + for filename in IGNORE_FILENAMES: + ignore_path = current / filename + if not ignore_path.is_file(): + continue + patterns = _read_ignore_patterns(ignore_path) + found.append( + IgnoreFileInfo( + relative_path=ignore_path.relative_to(root).as_posix(), + filename=filename, + patterns=tuple(patterns), + ) + ) + + return sorted(found, key=lambda item: item.relative_path) + + +def _collect_tracked_paths( + root: Path, + ignore: IgnoreMatcher, +) -> tuple[list[str], list[str]]: + """Return tracked directory and file paths relative to the workspace root.""" + tracked_directories: list[str] = [] + tracked_files: list[str] = [] + + for dirpath, dirnames, filenames in os.walk(root): + current = Path(dirpath) + rel_dir = current.relative_to(root).as_posix() + if rel_dir == ".": + rel_dir = "" + + dirnames[:] = [ + name + for name in dirnames + if not ignore.is_ignored(f"{rel_dir}/{name}".strip("/"), is_dir=True) + ] + + if rel_dir not in tracked_directories: + tracked_directories.append(rel_dir) + + for filename in sorted(filenames): + rel_path = f"{rel_dir}/{filename}".strip("/") if rel_dir else filename + if ignore.is_ignored(rel_path): + continue + tracked_files.append(rel_path) + + return tracked_directories, tracked_files + + +def _read_ignore_patterns(path: Path) -> list[str]: + text = path.read_text(encoding="utf-8", errors="replace") + patterns: list[str] = [] + for line in text.splitlines(): + stripped = line.strip() + if stripped and not stripped.startswith("#"): + patterns.append(stripped) + return patterns + + +def format_workspace_info(info: WorkspaceInfo) -> str: + """Render workspace info as Rich markup for the TUI.""" + lines: list[str] = [] + + lines.append(f"[bold]Resolved root:[/bold] {info.root}") + + if info.error: + lines.append(f"[bold red]Status:[/bold red] {info.error}") + return "\n".join(lines) + + dir_count = len(info.tracked_directories) + file_count = len(info.tracked_files) + lines.append( + f"[bold green]Status:[/bold green] tracking " + f"{file_count} file{'s' if file_count != 1 else ''} in " + f"{dir_count} director{'ies' if dir_count != 1 else 'y'}" + ) + + lines.append("") + lines.append("[bold cyan]Built-in ignore patterns[/bold cyan]") + for pattern in info.default_patterns: + lines.append(f" [dim]•[/dim] {pattern}") + + lines.append("") + lines.append("[bold cyan]Ignore files in use[/bold cyan]") + if not info.ignore_files: + lines.append(" [dim](none — only built-in patterns apply)[/dim]") + else: + for ignore_file in info.ignore_files: + pattern_count = len(ignore_file.patterns) + lines.append( + f" [bold]{ignore_file.relative_path}[/bold] " + f"[dim]({ignore_file.filename}, {pattern_count} pattern" + f"{'s' if pattern_count != 1 else ''})[/dim]" + ) + for pattern in ignore_file.patterns: + lines.append(f" [dim]•[/dim] {pattern}") + + lines.append("") + lines.append("[bold cyan]Tracked directories[/bold cyan]") + if not info.tracked_directories: + lines.append(" [dim](none)[/dim]") + else: + for directory in info.tracked_directories: + label = "." if directory == "" else directory + lines.append(f" [dim]•[/dim] {label}/") + + lines.append("") + lines.append("[bold cyan]Tracked files[/bold cyan]") + if not info.tracked_files: + lines.append(" [dim](none)[/dim]") + else: + for rel_path in info.tracked_files: + lines.append(f" [dim]•[/dim] {rel_path}") + + return "\n".join(lines) + + +def format_workspace_summary(info: WorkspaceInfo) -> str: + """Render a compact one-line workspace summary for the main dashboard.""" + if info.error: + return f"[bold red]{info.root}[/bold red] — {info.error}" + + dir_count = len(info.tracked_directories) + file_count = len(info.tracked_files) + return ( + f"[bold]Workspace:[/bold] {info.root} " + f"[dim]|[/dim] " + f"⏳ [bold cyan]Live Tracking:[/bold cyan] {file_count} file{'s' if file_count != 1 else ''} in " + f"{dir_count} director{'ies' if dir_count != 1 else 'y'}" + ) + + +def _folder_label(directory: str) -> str: + return "(root)" if directory == "" else directory + + +def _tracked_extension_counts(info: WorkspaceInfo) -> tuple[tuple[str, int], ...]: + counts: dict[str, int] = {} + for rel_path in info.tracked_files: + suffix = Path(rel_path).suffix.lower() + label = suffix if suffix else "(no extension)" + counts[label] = counts.get(label, 0) + 1 + return tuple(sorted(counts.items(), key=lambda item: (-item[1], item[0]))) + + +def format_tracked_folders_panel(info: WorkspaceInfo) -> str: + """Render tracked folder names for the scan results panel.""" + if info.error: + return f"[bold red]{info.error}[/bold red]" + + if not info.tracked_directories: + return "[dim](none)[/dim]" + + lines: list[str] = [] + for directory in info.tracked_directories: + label = _folder_label(directory) + lines.append(f"[dim]•[/dim] {label}/") + return "\n".join(lines) + + +def format_tracked_extensions_panel(info: WorkspaceInfo) -> str: + """Render tracked file extensions for the scan results panel.""" + if info.error: + return "[dim]—[/dim]" + + extensions = _tracked_extension_counts(info) + if not extensions: + return "[dim](none)[/dim]" + + lines: list[str] = [] + for extension, count in extensions: + lines.append( + f"[dim]•[/dim] {extension} " + f"[dim]({count} file{'s' if count != 1 else ''})[/dim]" + ) + return "\n".join(lines) + + +def format_gitignore_files_panel(info: WorkspaceInfo) -> str: + """Render discovered .gitignore files for the scan results panel.""" + if info.error: + return "[dim]—[/dim]" + + gitignore_files = tuple( + ignore_file for ignore_file in info.ignore_files if ignore_file.filename == ".gitignore" + ) + if not gitignore_files: + return "[dim](none found)[/dim]" + + lines: list[str] = [] + for ignore_file in gitignore_files: + pattern_count = len(ignore_file.patterns) + lines.append(f"[bold]{ignore_file.relative_path}[/bold]") + lines.append( + f" [dim]{pattern_count} pattern{'s' if pattern_count != 1 else ''}[/dim]" + ) + for pattern in ignore_file.patterns: + lines.append(f" [dim]•[/dim] {pattern}") + lines.append("") + return "\n".join(lines).rstrip() diff --git a/tests/test_ai_chat.py b/tests/test_ai_chat.py new file mode 100644 index 0000000..ac0ff8d --- /dev/null +++ b/tests/test_ai_chat.py @@ -0,0 +1,344 @@ +import json +from pathlib import Path + +from codegenome import ai_chat +from codegenome.ai_chat import build_graph_context, save_provider_key, settings_payload + + +def test_settings_payload_reports_saved_keys_without_exposing_values(tmp_path: Path) -> None: + genome_dir = tmp_path / ".genome" + save_provider_key(genome_dir, "openai", "sk-test") + + payload = settings_payload(genome_dir) + + assert payload["saved"]["openai"] is True + assert "sk-test" not in json.dumps(payload) + + +def test_settings_payload_includes_new_chat_providers(tmp_path: Path) -> None: + payload = settings_payload(tmp_path / ".genome") + + providers = {provider["id"]: provider for provider in payload["providers"]} + + assert list(providers) == ["openai", "google", "groq", "ollama", "ollama_cloud"] + assert providers["openai"]["requires_api_key"] is True + assert providers["google"]["requires_api_key"] is True + assert providers["groq"]["requires_api_key"] is True + assert providers["ollama"]["requires_api_key"] is False + assert providers["ollama_cloud"]["requires_api_key"] is True + assert "default_base_url" not in providers["ollama"] + + +def test_build_graph_context_includes_selected_node_neighborhood(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "metadata": {"statistics": {"node_count": 2, "edge_count": 1}}, + "nodes": [ + {"id": "a.py", "node_type": "file", "name": "a.py", "is_bridge": True}, + {"id": "b.py", "node_type": "file", "name": "b.py"}, + ], + "edges": [{"source": "a.py", "target": "b.py", "edge_type": "imports"}], + } + ), + encoding="utf-8", + ) + + context = build_graph_context(graph_path, selected_node_id="a.py") + + assert "Selected node:" in context + assert '"id": "a.py"' in context + assert '"direction": "outgoing"' in context + + +def test_build_graph_context_caps_large_payloads(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "nodes": [ + { + "id": f"file_{index}.py", + "node_type": "file", + "name": f"file_{index}.py", + "file_path": "src/" + ("very_long_path/" * 40) + f"file_{index}.py", + "qualified_name": "module." + ("very_long_symbol." * 40) + str(index), + "source": "x" * 5000, + } + for index in range(200) + ], + "edges": [ + { + "source": f"file_{index}.py", + "target": f"file_{index + 1}.py", + "edge_type": "imports", + } + for index in range(199) + ], + } + ), + encoding="utf-8", + ) + + context = build_graph_context(graph_path, selected_node_id="file_0.py") + + assert len(context) <= ai_chat.MAX_CONTEXT_CHARS + 80 + assert "Import edges:" in context + assert "...[truncated]" in context + + +def test_build_graph_context_profiles_change_budget(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "nodes": [ + { + "id": f"file_{index}.py", + "node_type": "file", + "name": f"file_{index}.py", + "file_path": f"src/package/file_{index}.py", + } + for index in range(50) + ], + "edges": [ + { + "source": f"file_{index}.py", + "target": f"file_{index + 1}.py", + "edge_type": "imports", + } + for index in range(49) + ], + } + ), + encoding="utf-8", + ) + + minimal = build_graph_context(graph_path, context_size="minimal") + full = build_graph_context(graph_path, context_size="full") + + assert "- context profile: minimal" in minimal + assert "- context profile: full" in full + assert len(full) > len(minimal) + + +def test_build_graph_context_max_profile_includes_more_import_edges(tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text( + json.dumps( + { + "nodes": [ + {"id": f"file_{index}.py", "node_type": "file", "name": f"file_{index}.py"} + for index in range(30) + ], + "edges": [ + { + "source": f"file_{index}.py", + "target": f"import:file_{index}.py:1:dep_{index}", + "edge_type": "imports", + } + for index in range(30) + ], + } + ), + encoding="utf-8", + ) + + minimal = build_graph_context(graph_path, context_size="minimal") + max_context = build_graph_context(graph_path, context_size="max") + + assert "- context profile: max" in max_context + assert "Import edges:" in max_context + assert max_context.count('"edge_type": "imports"') > minimal.count('"edge_type": "imports"') + + +def test_load_models_supports_keyless_ollama(monkeypatch, tmp_path: Path) -> None: + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"models": [{"name": "llama3.2:latest"}, {"model": "codellama:latest"}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + models = ai_chat.load_models(tmp_path / ".genome", "ollama") + + assert calls[0][0] == "http://127.0.0.1:11434/api/tags" + assert models == [ + {"id": "codellama:latest", "label": "codellama:latest"}, + {"id": "llama3.2:latest", "label": "llama3.2:latest"}, + ] + + +def test_load_models_supports_ollama_cloud(monkeypatch, tmp_path: Path) -> None: + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"models": [{"model": "gpt-oss:120b"}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + models = ai_chat.load_models(tmp_path / ".genome", "ollama_cloud", "ollama-key") + + assert calls[0][0] == "https://ollama.com/api/tags" + assert calls[0][1]["headers"]["Authorization"] == "Bearer ollama-key" + assert models == [{"id": "gpt-oss:120b", "label": "gpt-oss:120b"}] + + +def test_load_models_supports_groq(monkeypatch, tmp_path: Path) -> None: + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"data": [{"id": "llama-3.3-70b-versatile"}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + models = ai_chat.load_models(tmp_path / ".genome", "groq", "gsk-test") + + assert calls[0][0] == "https://api.groq.com/openai/v1/models" + assert calls[0][1]["headers"]["Authorization"] == "Bearer gsk-test" + assert models == [ + {"id": "llama-3.3-70b-versatile", "label": "llama-3.3-70b-versatile"} + ] + + +def test_request_json_adds_provider_friendly_headers(monkeypatch) -> None: + captured = {} + + class FakeResponse: + def __enter__(self): + return self + + def __exit__(self, exc_type, exc, traceback): + return False + + def read(self): + return b"{}" + + def fake_urlopen(request, timeout): + captured["headers"] = dict(request.header_items()) + captured["timeout"] = timeout + return FakeResponse() + + monkeypatch.setattr(ai_chat.urllib.request, "urlopen", fake_urlopen) + + ai_chat._request_json( + "https://api.groq.com/openai/v1/models", + headers={"Authorization": "Bearer gsk-test"}, + ) + + assert captured["headers"]["User-agent"].startswith("CodeGenome/") + assert captured["headers"]["Accept"] == "application/json" + assert captured["headers"]["Authorization"] == "Bearer gsk-test" + + +def test_chat_completion_supports_ollama_payload(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"message": {"content": "Local answer"}} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + answer = ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "ollama", + "llama3.2:latest", + [{"role": "user", "content": "What changed?"}], + ) + + assert answer == "Local answer" + assert calls[0][0] == "http://127.0.0.1:11434/api/chat" + assert calls[0][1]["payload"]["stream"] is False + assert calls[0][1]["payload"]["options"]["num_predict"] == ai_chat.MAX_RESPONSE_TOKENS + + +def test_chat_completion_supports_ollama_cloud_auth(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"message": {"content": "Cloud answer"}} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + answer = ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "ollama_cloud", + "gpt-oss:120b", + [{"role": "user", "content": "What changed?"}], + "ollama-key", + ) + + assert answer == "Cloud answer" + assert calls[0][0] == "https://ollama.com/api/chat" + assert calls[0][1]["headers"]["Authorization"] == "Bearer ollama-key" + assert calls[0][1]["payload"]["stream"] is False + + +def test_chat_completion_caps_openai_compatible_output(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"choices": [{"message": {"content": "Answer"}}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + answer = ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "groq", + "llama-3.3-70b-versatile", + [{"role": "user", "content": "Which files should split?"}], + "gsk-test", + ) + + assert answer == "Answer" + assert calls[0][1]["payload"]["max_tokens"] == ai_chat.MAX_RESPONSE_TOKENS + assert "- context profile: small" in calls[0][1]["payload"]["messages"][1]["content"] + + +def test_chat_completion_uses_requested_context_profile(monkeypatch, tmp_path: Path) -> None: + graph_path = tmp_path / ".genome" / "graph.json" + graph_path.parent.mkdir() + graph_path.write_text(json.dumps({"nodes": [], "edges": []}), encoding="utf-8") + calls = [] + + def fake_request_json(url, **kwargs): + calls.append((url, kwargs)) + return {"choices": [{"message": {"content": "Answer"}}]} + + monkeypatch.setattr(ai_chat, "_request_json", fake_request_json) + + ai_chat.chat_completion( + tmp_path / ".genome", + graph_path, + "openai", + "gpt-4o-mini", + [{"role": "user", "content": "Use more context"}], + "sk-test", + context_size="full", + ) + + context = calls[0][1]["payload"]["messages"][1]["content"] + assert "- context profile: full" in context diff --git a/tests/test_clusterer.py b/tests/test_clusterer.py index 369925a..7e07129 100644 --- a/tests/test_clusterer.py +++ b/tests/test_clusterer.py @@ -5,6 +5,7 @@ from codegenome.builder import GraphBuilder, file_node_id from codegenome.clusterer import GraphClusterer from codegenome.graph_api import Graph +from codegenome.graph_api import create_graph from codegenome.parser import ParseResult, ParsedCall, ParsedImport, ParsedSymbol from codegenome.scanner import FileRecord, ScanResult @@ -25,8 +26,6 @@ def _build_graph(files: dict[str, ParseResult]) -> Graph: return graph -from codegenome.graph_api import create_graph - def test_clusterer_empty_graph() -> None: result = GraphClusterer().cluster(create_graph("igraph")) diff --git a/tests/test_gitignore_semantics.py b/tests/test_gitignore_semantics.py new file mode 100644 index 0000000..611c58f --- /dev/null +++ b/tests/test_gitignore_semantics.py @@ -0,0 +1,97 @@ +"""Tests for full gitignore semantics and nested ignore files.""" + +from __future__ import annotations + +from pathlib import Path + +from codegenome.gitignore import IgnoreMatcher +from codegenome.scanner import WorkspaceScanner + + +def test_nested_gitignore_in_subdirectory(tmp_path: Path) -> None: + root = tmp_path / "project" + pkg = root / "packages" / "app" + pkg.mkdir(parents=True) + (root / "main.py").write_text("x\n", encoding="utf-8") + (pkg / "main.py").write_text("y\n", encoding="utf-8") + (pkg / "dist.py").write_text("z\n", encoding="utf-8") + (pkg / ".gitignore").write_text("dist.py\n", encoding="utf-8") + + matcher = IgnoreMatcher.for_workspace(root) + assert not matcher.is_ignored("main.py") + assert not matcher.is_ignored("packages/app/main.py") + assert matcher.is_ignored("packages/app/dist.py") + + +def test_nested_gitignore_directory_pattern(tmp_path: Path) -> None: + root = tmp_path / "project" + lib = root / "packages" / "lib" + dist = lib / "dist" + dist.mkdir(parents=True) + (dist / "bundle.js").write_text("js\n", encoding="utf-8") + (lib / "index.js").write_text("js\n", encoding="utf-8") + (lib / ".gitignore").write_text("dist/\n", encoding="utf-8") + + matcher = IgnoreMatcher.for_workspace(root) + assert not matcher.is_ignored("packages/lib/index.js") + assert matcher.is_ignored("packages/lib/dist/bundle.js") + assert matcher.is_ignored("packages/lib/dist", is_dir=True) + + +def test_gitignore_negation(tmp_path: Path) -> None: + root = tmp_path / "project" + root.mkdir() + (root / ".gitignore").write_text("*.log\n!important.log\n", encoding="utf-8") + + matcher = IgnoreMatcher.for_workspace(root) + assert matcher.is_ignored("debug.log") + assert not matcher.is_ignored("important.log") + assert matcher.is_ignored("nested/debug.log") + assert not matcher.is_ignored("nested/important.log") + + +def test_nested_gitignore_negation_overrides_parent(tmp_path: Path) -> None: + root = tmp_path / "project" + pkg = root / "packages" / "app" + pkg.mkdir(parents=True) + (root / ".gitignore").write_text("*.log\n", encoding="utf-8") + (pkg / ".gitignore").write_text("!keep.log\n", encoding="utf-8") + + matcher = IgnoreMatcher.for_workspace(root) + assert matcher.is_ignored("other.log") + assert matcher.is_ignored("packages/app/other.log") + assert not matcher.is_ignored("packages/app/keep.log") + + +def test_anchored_pattern_only_matches_in_ignore_directory(tmp_path: Path) -> None: + root = tmp_path / "project" + pkg = root / "packages" / "app" + nested = root / "packages" / "other" + pkg.mkdir(parents=True) + nested.mkdir() + (pkg / "target").write_text("x\n", encoding="utf-8") + (nested / "target").write_text("y\n", encoding="utf-8") + (pkg / ".gitignore").write_text("/target\n", encoding="utf-8") + + matcher = IgnoreMatcher.for_workspace(root) + assert matcher.is_ignored("packages/app/target") + assert not matcher.is_ignored("packages/other/target") + + +def test_scanner_skips_nested_gitignored_files(tmp_path: Path) -> None: + root = tmp_path / "project" + pkg = root / "packages" / "app" + pkg.mkdir(parents=True) + (root / "main.py").write_text("x\n", encoding="utf-8") + (pkg / "keep.py").write_text("y\n", encoding="utf-8") + (pkg / "skip.py").write_text("z\n", encoding="utf-8") + (pkg / ".gitignore").write_text("skip.py\n", encoding="utf-8") + + scanner = WorkspaceScanner(root, cache_db=root / ".genome" / "cache.db") + result = scanner.scan(incremental=False) + paths = {record.path for record in result.files} + + assert "main.py" in paths + assert "packages/app/keep.py" in paths + assert "packages/app/skip.py" not in paths + scanner.cache.close() diff --git a/tests/test_graph_api.py b/tests/test_graph_api.py index 75d1cea..1414256 100644 --- a/tests/test_graph_api.py +++ b/tests/test_graph_api.py @@ -1,7 +1,6 @@ """Tests for the Graph API abstraction.""" import networkx as nx -import pytest from codegenome.graph_api import IGraphGraph, NetworkXGraph, create_graph @@ -23,8 +22,9 @@ def test_graph_api_parity(): assert nx_graph.number_of_nodes() == ig_graph.number_of_nodes() == 3 assert nx_graph.number_of_edges() == ig_graph.number_of_edges() == 3 - assert nx_graph.has_node("A") == ig_graph.has_node("A") == True - assert nx_graph.has_node("D") == ig_graph.has_node("D") == False + assert nx_graph.has_node("A") == ig_graph.has_node("A") + assert not nx_graph.has_node("D") + assert not ig_graph.has_node("D") assert nx_graph.get_node("A") == ig_graph.get_node("A") == {"type": "file"} assert nx_graph.get_edge("A", "B") == ig_graph.get_edge("A", "B") == {"weight": 1.5} @@ -58,7 +58,8 @@ def test_graph_api_parity(): assert nx_graph.number_of_nodes() == ig_graph.number_of_nodes() == 2 assert nx_graph.number_of_edges() == ig_graph.number_of_edges() == 2 - assert nx_graph.has_node("C") == ig_graph.has_node("C") == False + assert not nx_graph.has_node("C") + assert not ig_graph.has_node("C") # Test attribute setting nx_graph.set_node_attr("A", "seen", True) diff --git a/tests/test_imports.py b/tests/test_imports.py index 874b7ee..d1bc574 100644 --- a/tests/test_imports.py +++ b/tests/test_imports.py @@ -6,7 +6,6 @@ "tree_sitter", "watchdog", "fastmcp", - "radon", "leidenalg", "igraph", "jinja2", @@ -21,4 +20,4 @@ def test_third_party_import(pkg: str) -> None: def test_codegenome_import() -> None: import codegenome - assert codegenome.__version__ == "0.1.0" + assert codegenome.__version__ == "0.1.4" diff --git a/tests/test_intelligence.py b/tests/test_intelligence.py index bbb700f..937ff0a 100644 --- a/tests/test_intelligence.py +++ b/tests/test_intelligence.py @@ -158,6 +158,67 @@ def test_intelligence_rankings() -> None: assert churn[0] == (file_node_id("rank.py"), 3) +def test_intelligence_filters_generated_complexity_by_default() -> None: + graph = create_graph("igraph") + graph.add_node( + "symbol:src/app.py:hard", + node_type="symbol", + file_path="src/app.py", + name="hard", + qualified_name="hard", + kind="function", + complexity=5, + ) + graph.add_node( + "symbol:src/assets/vendor.min.js:a", + node_type="symbol", + file_path="src/assets/vendor.min.js", + name="a", + qualified_name="a", + kind="function", + complexity=99, + ) + + intelligence = GraphIntelligence(graph) + + assert intelligence.complexity_rankings()[0] == ("symbol:src/app.py:hard", 5) + assert intelligence.complexity_rankings(include_generated=True)[0] == ( + "symbol:src/assets/vendor.min.js:a", + 99, + ) + + +def test_intelligence_filters_public_api_methods_from_dead_code_by_default() -> None: + graph = create_graph("igraph") + graph.add_node( + "symbol:src/codegenome/graph_api.py:Graph.add_node", + node_type="symbol", + file_path="src/codegenome/graph_api.py", + name="add_node", + qualified_name="Graph.add_node", + kind="method", + complexity=1, + ) + graph.add_node( + "symbol:src/codegenome/graph_api.py:Graph._unused_helper", + node_type="symbol", + file_path="src/codegenome/graph_api.py", + name="_unused_helper", + qualified_name="Graph._unused_helper", + kind="method", + complexity=1, + ) + + intelligence = GraphIntelligence(graph) + + assert intelligence.detect_dead_code() == [ + "symbol:src/codegenome/graph_api.py:Graph._unused_helper" + ] + assert "symbol:src/codegenome/graph_api.py:Graph.add_node" in ( + intelligence.detect_dead_code(include_public_api=True) + ) + + def test_intelligence_detects_entry_points() -> None: alpha = ParseResult(path="alpha.py", language="python") alpha.symbols = [ diff --git a/tests/test_mcp_server.py b/tests/test_mcp_server.py index 467e0de..ff48133 100644 --- a/tests/test_mcp_server.py +++ b/tests/test_mcp_server.py @@ -68,6 +68,33 @@ def test_validate_config_rejects_non_localhost() -> None: validate_config(config) +def test_validate_config_allows_remote_http_with_opt_in() -> None: + config = ServerConfig( + host="0.0.0.0", + port=7331, + db_path=Path("test.db"), + timeout_seconds=30.0, + log_level="INFO", + transport="http", + allow_remote_http=True, + ) + validate_config(config) + + +def test_validate_config_rejects_remote_stdio_even_with_opt_in() -> None: + config = ServerConfig( + host="0.0.0.0", + port=7331, + db_path=Path("test.db"), + timeout_seconds=30.0, + log_level="INFO", + transport="stdio", + allow_remote_http=True, + ) + with pytest.raises(ValueError, match="localhost-only"): + validate_config(config) + + def test_graph_store_empty_db(tmp_path: Path) -> None: db_path = tmp_path / "empty.db" store = GraphStore(db_path) @@ -137,6 +164,49 @@ def test_graph_service_get_timeline_from_worker_thread(sample_db: Path) -> None: service.shutdown() +def test_graph_service_refreshes_latest_snapshot_before_tool_reads(sample_db: Path) -> None: + config = ServerConfig( + host="127.0.0.1", + port=7331, + db_path=sample_db, + timeout_seconds=5.0, + log_level="INFO", + transport="http", + ) + service = GraphService(config) + service.startup() + try: + updated_graph = create_graph("igraph") + updated_graph.add_node( + "file:alpha.py", + node_type="file", + file_path="alpha.py", + churn=2, + complexity=1, + ) + updated_graph.add_node( + "file:beta.py", + node_type="file", + file_path="beta.py", + churn=1, + complexity=1, + ) + timeline = GraphTimeline(sample_db) + try: + latest_snapshot_id = timeline.record_snapshot(updated_graph, label="updated") + finally: + timeline.close() + + graph = service.run(service.store.get_graph) + + assert graph["snapshot_id"] == latest_snapshot_id + assert graph["latest_snapshot_id"] == latest_snapshot_id + assert graph["current"] is True + assert graph["node_count"] == 2 + finally: + service.shutdown() + + def test_create_server_registers_tools(sample_db: Path) -> None: config = ServerConfig( host="127.0.0.1", @@ -177,6 +247,26 @@ def test_parse_args_defaults() -> None: assert config.transport == "http" +def test_parse_args_remote_http_opt_in() -> None: + config = parse_args( + [ + "--db-path", + "test.db", + "--transport", + "http", + "--host", + "0.0.0.0", + "--allow-remote-http", + "--port", + "8123", + ] + ) + assert config.transport == "http" + assert config.host == "0.0.0.0" + assert config.allow_remote_http is True + assert config.port == 8123 + + def test_invalid_request_returns_error_envelope(sample_db: Path) -> None: config = ServerConfig( host="127.0.0.1", diff --git a/tests/test_mcp_server_load.py b/tests/test_mcp_server_load.py new file mode 100644 index 0000000..8b4d95b --- /dev/null +++ b/tests/test_mcp_server_load.py @@ -0,0 +1,70 @@ +"""Load-oriented tests for MCP server tool handlers.""" + +from __future__ import annotations + +import asyncio +import time +from pathlib import Path + +import pytest + +from codegenome.graph_api import create_graph +from codegenome.mcp_server import GraphService, ServerConfig, create_server +from codegenome.timeline import GraphTimeline + + +@pytest.fixture +def sample_db_for_load(tmp_path: Path) -> Path: + graph = create_graph("igraph") + for idx in range(40): + file_id = f"file:mod_{idx}.py" + symbol_id = f"symbol:mod_{idx}.py:fn_{idx}" + graph.add_node(file_id, node_type="file", file_path=f"mod_{idx}.py") + graph.add_node( + symbol_id, + node_type="symbol", + file_path=f"mod_{idx}.py", + name=f"fn_{idx}", + qualified_name=f"fn_{idx}", + kind="function", + ) + graph.add_edge(file_id, symbol_id, edge_type="contains") + + db_path = tmp_path / "load.db" + timeline = GraphTimeline(db_path) + timeline.record_snapshot(graph, label="baseline") + timeline.close() + return db_path + + +def test_search_nodes_tool_sustains_repeated_calls(sample_db_for_load: Path) -> None: + config = ServerConfig( + host="127.0.0.1", + port=7331, + db_path=sample_db_for_load, + timeout_seconds=5.0, + log_level="INFO", + transport="http", + ) + service = GraphService(config) + service.startup() + try: + server = create_server(service) + tools = asyncio.run(server.list_tools()) + search_nodes = next(item for item in tools if item.name == "search_nodes") + + iterations = 300 + started = time.perf_counter() + ok_count = 0 + for _ in range(iterations): + result = search_nodes.fn(query="mod_", node_type=None, limit=25) + assert result["status"] == "ok" + assert result["data"] + ok_count += 1 + elapsed = time.perf_counter() - started + + assert ok_count == iterations + # Broad threshold to catch severe regressions while staying CI-friendly. + assert elapsed < 20.0 + finally: + service.shutdown() diff --git a/tests/test_network_utils.py b/tests/test_network_utils.py new file mode 100644 index 0000000..6cb99a2 --- /dev/null +++ b/tests/test_network_utils.py @@ -0,0 +1,29 @@ +"""Tests for network utility helpers.""" + +from __future__ import annotations + +from unittest.mock import MagicMock, patch + +from codegenome.network_utils import get_lan_ip + + +def test_get_lan_ip_returns_detected_address() -> None: + mock_socket = MagicMock() + mock_socket.__enter__.return_value = mock_socket + mock_socket.__exit__.return_value = False + mock_socket.getsockname.return_value = ("192.168.1.50", 54321) + + with patch("codegenome.network_utils.socket.socket", return_value=mock_socket): + assert get_lan_ip() == "192.168.1.50" + + mock_socket.connect.assert_called_once_with(("8.8.8.8", 80)) + + +def test_get_lan_ip_falls_back_to_loopback() -> None: + mock_socket = MagicMock() + mock_socket.__enter__.return_value = mock_socket + mock_socket.__exit__.return_value = False + mock_socket.connect.side_effect = OSError("no route") + + with patch("codegenome.network_utils.socket.socket", return_value=mock_socket): + assert get_lan_ip() == "127.0.0.1" diff --git a/tests/test_parser.py b/tests/test_parser.py index ce32782..9ee060f 100644 --- a/tests/test_parser.py +++ b/tests/test_parser.py @@ -3,9 +3,11 @@ from __future__ import annotations from pathlib import Path +from types import SimpleNamespace import pytest +from codegenome import parser as parser_module from codegenome.parser import SourceParser @@ -129,3 +131,33 @@ def test_parser_read_failure_is_graceful(parser: SourceParser, tmp_path: Path) - result = parser.parse_file(path) assert result is not None assert result.errors + + +def test_build_language_supports_legacy_signature(monkeypatch: pytest.MonkeyPatch) -> None: + capsule = object() + + class LegacyLanguage: + def __init__(self, received_capsule: object, name: str) -> None: + self.received_capsule = received_capsule + self.name = name + + module = SimpleNamespace(language=lambda: capsule) + monkeypatch.setattr(parser_module, "Language", LegacyLanguage) + + language = parser_module._build_language(module, "language", "python") + assert language.received_capsule is capsule + assert language.name == "python" + + +def test_build_language_supports_modern_signature(monkeypatch: pytest.MonkeyPatch) -> None: + capsule = object() + + class ModernLanguage: + def __init__(self, received_capsule: object) -> None: + self.received_capsule = received_capsule + + module = SimpleNamespace(language=lambda: capsule) + monkeypatch.setattr(parser_module, "Language", ModernLanguage) + + language = parser_module._build_language(module, "language", "python") + assert language.received_capsule is capsule diff --git a/tests/test_scanner_gitignore.py b/tests/test_scanner_gitignore.py index fe1965d..570b025 100644 --- a/tests/test_scanner_gitignore.py +++ b/tests/test_scanner_gitignore.py @@ -1,13 +1,35 @@ +from pathlib import Path -def test_ignore_matcher_for_workspace_loads_gitignore(tmp_path): +from codegenome.scanner import IgnoreMatcher, WorkspaceScanner + + +def test_ignore_matcher_for_workspace_loads_gitignore(tmp_path: Path) -> None: root = tmp_path / "project" root.mkdir() (root / ".gitignore").write_text("ignored.txt\n", encoding="utf-8") (root / ".genomeignore").write_text("local.txt\n", encoding="utf-8") - from codegenome.scanner import IgnoreMatcher - matcher = IgnoreMatcher.for_workspace(root) assert matcher.is_ignored("ignored.txt") assert matcher.is_ignored("local.txt") assert not matcher.is_ignored("main.py") + + +def test_scanner_respects_gitignore(tmp_path: Path) -> None: + root = tmp_path / "project" + root.mkdir() + (root / "main.py").write_text("print('hello')\n", encoding="utf-8") + (root / "ignored.txt").write_text("skip me\n", encoding="utf-8") + (root / ".gitignore").write_text("ignored.txt\nbuild/\n", encoding="utf-8") + build_dir = root / "build" + build_dir.mkdir() + (build_dir / "artifact.txt").write_text("ignored by gitignore\n", encoding="utf-8") + + scanner = WorkspaceScanner(root, cache_db=root / ".genome" / "cache.db") + result = scanner.scan(incremental=False) + + paths = {record.path for record in result.files} + assert "main.py" in paths + assert "ignored.txt" not in paths + assert "build/artifact.txt" not in paths + scanner.cache.close() diff --git a/tests/test_timeline.py b/tests/test_timeline.py index 8da1ec5..aaa8379 100644 --- a/tests/test_timeline.py +++ b/tests/test_timeline.py @@ -74,7 +74,7 @@ def test_timeline_node_history_and_churn_rate(tmp_path: Path, sample_graph: Grap timeline = GraphTimeline(tmp_path / "timeline.db") node_id = file_node_id("alpha.py") - first_id = timeline.record_snapshot(sample_graph, label="v1", created_at=1.0) + timeline.record_snapshot(sample_graph, label="v1", created_at=1.0) changed = sample_graph.copy() changed.set_node_attr(node_id, "churn", 1) timeline.record_snapshot(changed, label="v2", created_at=2.0) diff --git a/tests/test_tui.py b/tests/test_tui.py new file mode 100644 index 0000000..30c7e65 --- /dev/null +++ b/tests/test_tui.py @@ -0,0 +1,148 @@ +"""Unit tests for CodeGenome TUI command wiring.""" + +from __future__ import annotations + +import asyncio + +from rich.segment import Segment + +from textual import events +from textual.geometry import Offset +from textual.selection import Selection +from textual.strip import Strip + +from codegenome.tui import ActiveProcess, CodeGenomeTUI, ReadOnlyRichLog + + +def test_bindings_use_ctrl_c_for_copy_not_quit() -> None: + binding_map = {key: action for key, action, _description in CodeGenomeTUI.BINDINGS} + assert binding_map["ctrl+c"] == "copy_log_text" + assert binding_map["ctrl+q"] == "quit_app" + + +def test_read_only_rich_log_get_selection_returns_plain_text() -> None: + log = ReadOnlyRichLog() + log.lines = [ + Strip([Segment("alpha")], 5), + Strip([Segment("beta")], 4), + ] + selection = Selection(Offset(0, 0), Offset(4, 1)) + result = log.get_selection(selection) + assert result is not None + text, ending = result + assert text == "alpha\nbeta" + assert ending == "\n" + + +def test_read_only_rich_log_blocks_printable_keys() -> None: + log = ReadOnlyRichLog() + event = events.Key(key="x", character="x") + log.on_key(event) + assert event._stop_propagation is True + + +def test_command_button_ids_include_channel_specific_stop_buttons() -> None: + assert "btn-stop-mcp" in CodeGenomeTUI.COMMAND_BUTTON_IDS + assert "btn-stop-evolve" in CodeGenomeTUI.COMMAND_BUTTON_IDS + assert "btn-stop" not in CodeGenomeTUI.COMMAND_BUTTON_IDS + + +def test_stop_processes_for_channel_schedules_only_matching_processes() -> None: + app = CodeGenomeTUI() + app.active_processes = [ + ActiveProcess(process=object(), channel="mcp"), + ActiveProcess(process=object(), channel="evolve"), + ] + + captured: dict[str, object] = {} + + async def fake_stop_processes(processes, *, completion_message: str): # type: ignore[no-untyped-def] + captured["processes"] = processes + captured["message"] = completion_message + + def fake_run_worker(coro, *, exclusive: bool): # type: ignore[no-untyped-def] + captured["exclusive"] = exclusive + asyncio.run(coro) + + app._stop_processes = fake_stop_processes # type: ignore[method-assign] + app.run_worker = fake_run_worker # type: ignore[method-assign] + + app.stop_processes_for_channel("mcp", "MCP server") + + matching = captured["processes"] + assert isinstance(matching, list) + assert len(matching) == 1 + assert matching[0].channel == "mcp" + assert captured["message"] == "[yellow]MCP server processes stopped.[/yellow]" + assert captured["exclusive"] is False + + +def test_stop_processes_for_channel_logs_when_no_matching_processes() -> None: + app = CodeGenomeTUI() + app.active_processes = [ActiveProcess(process=object(), channel="evolve")] + + logs: list[tuple[str, str]] = [] + focused: list[str] = [] + + def fake_write_log(channel: str, message: str) -> None: + logs.append((channel, message)) + + def fake_focus(channel: str) -> None: + focused.append(channel) + + app.write_log = fake_write_log # type: ignore[method-assign] + app.focus_log_tab = fake_focus # type: ignore[method-assign] + + app.stop_processes_for_channel("mcp", "MCP server") + + assert logs == [("mcp", "[yellow]No active MCP server process to stop.[/yellow]")] + assert focused == ["mcp"] + + +def test_copy_panel_output_copies_text_to_clipboard() -> None: + app = CodeGenomeTUI() + log = ReadOnlyRichLog() + log.lines = [ + Strip([Segment("line 1")], 6), + Strip([Segment("line 2")], 6), + ] + + copied: list[str] = [] + notifications: list[str] = [] + + def fake_copy_to_clipboard(text: str) -> None: + copied.append(text) + + def fake_notify(message: str, *, severity: str = "information") -> None: + notifications.append(message) + + app.copy_to_clipboard = fake_copy_to_clipboard # type: ignore[method-assign] + app.notify = fake_notify # type: ignore[method-assign] + + app.copy_panel_output(log, "Test Panel") + + assert copied == ["line 1\nline 2"] + assert notifications == ["Copied Test Panel output to clipboard!"] + + +def test_copy_panel_output_notifies_if_empty() -> None: + app = CodeGenomeTUI() + log = ReadOnlyRichLog() + log.lines = [] + + copied: list[str] = [] + notifications: list[str] = [] + + def fake_copy_to_clipboard(text: str) -> None: + copied.append(text) + + def fake_notify(message: str, *, severity: str = "information") -> None: + notifications.append(message) + + app.copy_to_clipboard = fake_copy_to_clipboard # type: ignore[method-assign] + app.notify = fake_notify # type: ignore[method-assign] + + app.copy_panel_output(log, "Test Panel") + + assert not copied + assert notifications == ["No content to copy in Test Panel."] diff --git a/tests/test_workspace_info.py b/tests/test_workspace_info.py new file mode 100644 index 0000000..e91443f --- /dev/null +++ b/tests/test_workspace_info.py @@ -0,0 +1,87 @@ +"""Tests for workspace info collection and formatting.""" + +from __future__ import annotations + +from pathlib import Path + +import pytest + +from codegenome.workspace_info import ( + collect_workspace_info, + format_gitignore_files_panel, + format_tracked_extensions_panel, + format_tracked_folders_panel, + format_workspace_info, +) + + +@pytest.fixture +def workspace(tmp_path: Path) -> Path: + root = tmp_path / "project" + root.mkdir() + (root / "main.py").write_text("print('hello')\n", encoding="utf-8") + (root / "ignored.txt").write_text("skip me\n", encoding="utf-8") + (root / ".gitignore").write_text("ignored.txt\nbuild/\n", encoding="utf-8") + build_dir = root / "build" + build_dir.mkdir() + (build_dir / "artifact.txt").write_text("ignored\n", encoding="utf-8") + pkg_dir = root / "pkg" + pkg_dir.mkdir() + (pkg_dir / "module.py").write_text("x = 1\n", encoding="utf-8") + (pkg_dir / ".genomeignore").write_text("module.py\n", encoding="utf-8") + return root + + +def test_collect_workspace_info_lists_ignore_files_and_tracked_paths(workspace: Path) -> None: + info = collect_workspace_info(workspace) + + assert info.exists + assert info.is_directory + assert info.error is None + assert len(info.ignore_files) == 2 + assert info.ignore_files[0].relative_path == ".gitignore" + assert info.ignore_files[0].patterns == ("ignored.txt", "build/") + assert any(item.relative_path == "pkg/.genomeignore" for item in info.ignore_files) + assert "main.py" in info.tracked_files + assert "pkg/module.py" not in info.tracked_files + assert "ignored.txt" not in info.tracked_files + assert "" in info.tracked_directories + assert "pkg" in info.tracked_directories + assert "build" not in info.tracked_directories + + +def test_collect_workspace_info_invalid_path(tmp_path: Path) -> None: + missing = tmp_path / "missing" + info = collect_workspace_info(missing) + + assert not info.exists + assert info.error == "Path does not exist" + + +def test_format_workspace_info_includes_sections(workspace: Path) -> None: + info = collect_workspace_info(workspace) + rendered = format_workspace_info(info) + + assert "Built-in ignore patterns" in rendered + assert "Ignore files in use" in rendered + assert ".gitignore" in rendered + assert "Tracked directories" in rendered + assert "Tracked files" in rendered + assert "main.py" in rendered + + +def test_scan_result_panels_show_folders_extensions_and_gitignore(workspace: Path) -> None: + info = collect_workspace_info(workspace) + + folders = format_tracked_folders_panel(info) + extensions = format_tracked_extensions_panel(info) + gitignore = format_gitignore_files_panel(info) + + assert "(root)/" in folders + assert "pkg/" in folders + assert "build/" not in folders + assert ".py" in extensions + assert "main.py" not in extensions + assert ".gitignore" in gitignore + assert "ignored.txt" in gitignore + assert ".genomeignore" not in gitignore