diff --git a/README.md b/README.md
index 5452378..5d4c510 100644
--- a/README.md
+++ b/README.md
@@ -26,6 +26,8 @@ All four covers are **AI-generated editorial illustrations**, not footage, measu
## Latest studies
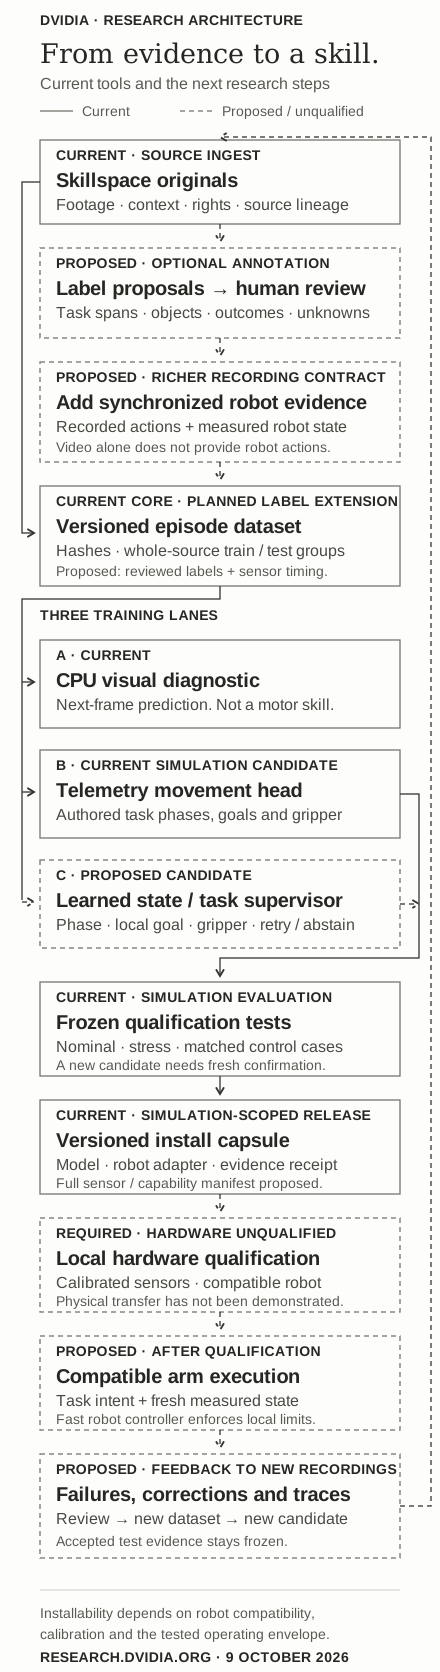
+[Robotics research pipeline](reports/Robotics%20research%20pipeline.md) maps the path from Skillspace originals and synchronized robot measurements to reviewed episodes, local training, frozen simulation evaluation and compatible skill installation. The diagram distinguishes implemented simulation components from proposed automatic labeling and a learned task supervisor. A new annotation-labor pilot and feedback-supervisor experiment are specified; neither has been run, and physical robot qualification remains open. [Read the public architecture](https://research.dvidia.org/papers/robotics-research-pipeline/).
+
[Skillspace footage training pipeline](reports/Skillspace%20footage%20training%20pipeline.md) introduces the standalone [DVIDIA Training repository](https://github.com/Dvidia-Inference/dvidia-training): audit actual footage, freeze connected source groups, fit visual weights locally and export inspectable results. Its optional movement branch requires aligned numerical actions and a supported simulation adapter. The separate [frozen sample-count benchmark](https://github.com/Dvidia-Inference/dvidia-training/blob/main/benchmarks/sample-count-19047/README.md) compares two, four and seven training groups on the same twelve layouts: nominal completion is 8/8, 7/8 and 8/8; actuator-stress completion is 3/4 for each, and all 36 matched open-jaw controls fail. This single composition-order pilot establishes no sufficient video count, human-video action bridge or hardware skill. [Inspect the protocol, outcomes and recorded evidence release](https://github.com/Dvidia-Inference/dvidia-training/releases/tag/benchmark-2026-10-08).
[Installing a Skillspace on a simulated arm](reports/Installing%20a%20Skillspace%20on%20a%20simulated%20arm.md) publishes the first public-link-to-execution product path. A local installer binds DVIDIA task metadata to one authored native-contact placement controller. The same controller completes six changed scenes; no-motion and identical arm commands with open jaws each complete 0/6. [Run the local lab, inspect the source or replay the arm](topics/physical-grounding/runs/2026-10-07-skillspace-arm/PRODUCT.md). This virtual box/arm profile has no learned video policy or physical qualification.
diff --git a/docs/assets/robotics-pipeline.svg b/docs/assets/robotics-pipeline.svg
new file mode 100644
index 0000000..869cdfb
--- /dev/null
+++ b/docs/assets/robotics-pipeline.svg
@@ -0,0 +1,117 @@
+
diff --git a/docs/downloads/reports/Robotics research pipeline.md b/docs/downloads/reports/Robotics research pipeline.md
new file mode 100644
index 0000000..411da62
--- /dev/null
+++ b/docs/downloads/reports/Robotics research pipeline.md
@@ -0,0 +1,76 @@
+# Robotics research pipeline
+
+DVIDIA's product goal is a local training environment that converts Skillspace evidence into a versioned skill a compatible robot can install, test and execute with feedback. The next architectural step couples reviewed task descriptions to **measured robot state**, allowing a skill to decide whether a grasp worked, whether progress stopped and whether to retry or abstain. This paper specifies that pipeline and its validation gates. It adds no trained supervisor, human-video action bridge or hardware qualification. The implemented foundation remains a CPU research alpha with bounded simulation evidence. ([Public training package](https://github.com/Dvidia-Inference/dvidia-training), [Published measurements](https://research.dvidia.org/papers/skillspace-footage-training/))
+
+## Pipeline at a glance
+
+
+
+**Figure 1.** Solid elements represent implemented components within the bounded simulation pipeline; dashed elements represent proposed integrations. Physical robot execution remains unqualified. A visual model, reviewed label and executable motor policy have different evidence requirements. The diagram describes a target architecture, not a newly completed end-to-end system.
+
+The intended flow is **original recordings → label proposals and synchronized telemetry → reviewed episodes → frozen grouped datasets → appropriate learners → frozen simulation evaluation → versioned skill → compatibility checks and local qualification → feedback execution**. Today, media intake, grouping, visual diagnostics, numerical movement fitting and simulation capsule qualification exist. Automatic task labeling and learned task supervision require new contracts and experiments.
+
+| Component | Implemented evidence | Next addition |
+|---|---|---|
+| Intake and provenance | Local media audit, hashes and connected source groups | Immutable annotation revisions and richer synchronized telemetry |
+| Learning | RGB next-frame diagnostic; numerical six-joint movement head | Reviewed task/outcome consumer and state supervisor |
+| Task decisions | Authored phases, goals, gripper, completion and recovery | Learned bounded decisions using observation history |
+| Evaluation and installation | Frozen simulation trials; runtime-bound capsule and exact-scene gate | Fresh supervisor confirmation and qualified embodiment adapters |
+| Physical execution | No qualified hardware skill | Calibrated sensing, dynamics and independent arm tests |
+
+## 1. Preserve originals; propose labels separately
+
+Skillspace should evolve from a media folder into an evidence container. Preserve original bytes, source/session identifiers, camera identity, task declarations and redistribution rights. Existing connected-group checks keep declared related recordings and duplicate media together before train/development/test assignment. Twelve cuts from one long recording remain one dependent source group; a “complete” flag does not prove task completion. ([Current format](https://github.com/Dvidia-Inference/dvidia-training/blob/2f372698e941bbcdd9342499592cc6baf9227d8d/docs/skillspace-format.md))
+
+An optional detector, tracker and vision-language model can propose intervals, objects, relations and observed outcomes. Grounded SAM 2 demonstrates detection, tracking and JSON export, but these outputs still need event and identity review. Distinguish reaching, attempting grasp, closing jaws, visibly holding, lifting, placing, releasing and observed completion. Preserve retries, drops, occlusion and unknown outcomes instead of turning every attempt into success. ([Grounded SAM 2](https://github.com/IDEA-Research/Grounded-SAM-2))
+
+The proposed annotation sidecar stores original presentation timestamps, clip mappings, track identities, box conventions, visibility, model/prompt revisions, evidence frames, raw scores and reviewer edits. Revision states distinguish proposed, accepted, corrected, rejected and unknown. Detector scores are not calibrated accuracy, and hashes bind an artifact without certifying its truth. Current Training does not consume segment/box annotations; this must be a separate versioned addition, not an annotation file renamed as numerical actions.
+
+## 2. Synchronize measured state and action intent
+
+Teleoperation and simulator recordings can provide aligned numerical actions. Egocentric human video can provide task semantics while lacking robot actions, metric geometry and contact measurements. Reviewed captions cannot manufacture those channels. DIAL supports language augmentation of existing robot demonstrations using a human-labeled seed and fine-tuned CLIP; it does not establish arbitrary human-video conversion into controls. ([DIAL](https://instructionaugmentation.github.io/))
+
+The richer telemetry contract should retain the distinction between what the controller requested and what the robot did:
+
+| Channel | Required interpretation |
+|---|---|
+| Joint and tool state | Measured position/velocity, units, frame and acquisition time |
+| Gripper state | Actual aperture and available effort/contact observations |
+| Commands | Requested targets, issue time and application time |
+| Camera and objects | Presentation times, visibility, identity and calibration |
+| Synchronization | Clock mapping, resampling method, sensor age and uncertainty |
+| Missing data | Explicit unavailable/stale flags; unknown is not zero |
+
+“Close jaws” records intent. Holding requires supporting aperture, contact, effort or object-motion evidence. The current simulator exposes joints, velocities, jaw gap, actuator forces and pad contacts separately from commands; the strict movement sidecar retains only its narrower timestamp/context/error/joint-delta features. Exporting the richer tape therefore needs a new schema and alignment checks. LeRobot's separate video, state, action and task channels offer an interoperability target through an explicit adapter. ([Environment observations](https://github.com/Dvidia-Inference/dvidia-training/blob/2f372698e941bbcdd9342499592cc6baf9227d8d/src/dvidia_training/arm_env.py#L244), [Recorder](https://github.com/Dvidia-Inference/dvidia-training/blob/2f372698e941bbcdd9342499592cc6baf9227d8d/src/dvidia_training/footage_example.py#L71), [LeRobot v3](https://huggingface.co/docs/lerobot/en/lerobot-dataset-v3))
+
+The original spatial-prior thesis remains useful: shoes often lie low and tables near the torso, conditional on viewpoint, posture and scene. Such expectations can prioritize search while preserving exceptions. A pixel box is not robot-base XYZ, orientation or a grasp point. Metric targets require calibration, depth or geometric constraints and frame transforms; semantic labels cannot supply friction or deformability. ([OpenCV calibration](https://docs.opencv.org/4.x/d9/d0c/group__calib3d.html))
+
+## 3. Train distinct models for distinct claims
+
+The current visual learner measures next-frame prediction on small synthetic RGB samples. It does not control the arm. The current movement learner consumes privileged simulator context and an authored Cartesian goal to predict six joint increments, replacing a differential inverse-kinematics calculation. Phases, targets, gripper decisions, completion and recovery remain authored. These boundaries explain what today's successful placement trials establish. ([Movement learner](https://github.com/Dvidia-Inference/dvidia-training/blob/2f372698e941bbcdd9342499592cc6baf9227d8d/src/dvidia_training/arm_distill.py), [Authored supervisor](https://github.com/Dvidia-Inference/dvidia-training/blob/2f372698e941bbcdd9342499592cc6baf9227d8d/src/dvidia_training/arm_policy.py))
+
+The next learner should be a compact local supervisor over recent measured-state history. It proposes a bounded phase, local goal and gripper intent, together with progress, recovery or abstention. State estimation establishes what observations support; supervision chooses what to attempt; the motor policy produces bounded targets; the fast controller tracks accepted targets and enforces limits. Teacher phases may label training examples but must not appear as deployment inputs.
+
+ACT demonstrates observation-conditioned action chunks; SayCan combines instruction usefulness with skill feasibility in the current state; FoAR combines visual and force/torque inputs with reactive contact refinement. These mechanisms motivate the design without validating DVIDIA's exact architecture or arbitrary-arm installation. Start with the CPU specialist and measure complete inference cost before selecting larger models. ([ACT](https://tonyzhaozh.github.io/aloha/), [SayCan](https://say-can.github.io/), [FoAR](https://tonyfang.net/FoAR/))
+
+## 4. Validate curation and decisions independently
+
+The proposed annotation pilot uses twenty independent source sessions: ten teleoperation and ten egocentric, reported separately. Reserve four development and six untouched test sessions per domain. Two reference annotators, blinded to model suggestions, adjudicate events and outcomes. Separate operators compare manual, VLM-assisted and detector-plus-VLM-assisted labeling with balanced assignments, without showing the same operator the same source in multiple conditions.
+
+Measure correction plus audit time at matched quality, boundary errors, missed/extra events, object/target errors, tracking identity errors, false completion and abstention. Include inference, storage, retries and setup in cost per approved episode. The proposed go/no-go target is 30% less reviewer labor without an observed increase in serious errors and with reliable provenance-preserving exports. This companion triage pilot targets annotation labor and retrieval; the earlier forty-episode graduation proposal remains separate and unrun. Neither establishes production reliability; policy benefits require a compatible consumer and separate learning evaluation. ([Earlier graduation protocol](https://research.dvidia.org/downloads/topics/evaluation-provenance/experiments/0002-skill-graduation.md))
+
+For the supervisor, keep the movement head, physics, servos, limits and success predicate fixed against authored supervision. Add empty grasps, slips, response delay and lost observations to training/intervention recordings. Successful demonstrations alone cannot establish recovery. Use the known twelve benchmark layouts for regression, then freeze model, thresholds and protocol before a fresh confirmation suite with nominal, recoverable, impossible and sensor-fault cases. Preserve whole connected groups and matched open-jaw controls. ([Existing frozen protocol](https://github.com/Dvidia-Inference/dvidia-training/blob/2f372698e941bbcdd9342499592cc6baf9227d8d/benchmarks/sample-count-19047/protocol.json))
+
+Report all attempted episodes: completion, false success, drops, recovery success/time, interventions, unnecessary aborts and abstention coverage. Record latency distributions, sensor-to-command age and deadline misses. Ablate measured sensors versus command history, contact/force, temporal history and object context. Test task conditioning with distinct intentions; one placement task cannot establish multi-task arbitration. Adoption requires preserved nominal performance and a preregistered improvement in recovery or intervention burden, beyond lower imitation loss.
+
+## 5. Qualify physics and performance before expanding coverage
+
+Simulation practice must preserve task-relevant geometry, contact, friction, compliance, actuator response and sensor behavior. Stable trajectories alone do not establish physical accuracy. Our earlier fixture study found endpoint agreement insufficient to establish contact transients, with coarse timesteps missing collisions. Calibration against measurements, timestep checks and explicit parameter uncertainty remain required before physical-transfer claims. ([Simulation study](https://research.dvidia.org/papers/fast-accurate-robot-training-simulation/), [MuJoCo contact modeling](https://mujoco.readthedocs.io/en/stable/modeling.html))
+
+The current base trainer runs locally on CPU; arm simulation adds MuJoCo. Offline execution follows dependency/data installation. Keep future annotation models optional, cache decoded evidence by source/model/recipe hashes and refine uncertain intervals. Measure cold/warm latency, total wall time, memory and quality together. Published hardware guidance is provisional; small CPU measurements do not establish universal minima, GPU scaling or faster production annotation. Audit exact model licenses before redistribution. ([Installation](https://github.com/Dvidia-Inference/dvidia-training/blob/main/docs/installation.md), [Hardware guidance](https://github.com/Dvidia-Inference/dvidia-training/blob/main/docs/hardware.md))
+
+## 6. Release a skill with its operating contract
+
+The target bundle contains weights, observation/action semantics, units, timing and missingness rules, required sensors, calibrated frames, robot/gripper adapter, tested support envelope, bounded recovery and qualification receipts. Compatibility includes joint ordering, limits, kinematics, gripper geometry and sensing; degree-of-freedom count alone is insufficient. One click should automate inspection, adapter checks and local qualification. An incompatible or failed qualification remains a failed installation gate.
+
+The existing runtime-bound simulation capsule provides a starting point. Execution must retain feedback and scene-specific qualification rather than treat an installed file as competence. New failures return to immutable recordings and reviewed future datasets without changing frozen tests. Public [source](https://github.com/Dvidia-Inference/dvidia-training), [dataset](https://huggingface.co/datasets/Dvidia/dvidia-training-examples), [pilot models](https://huggingface.co/Dvidia/dvidia-training-pilot) and [recorded evidence Space](https://huggingface.co/spaces/Dvidia/dvidia-training) make the present baseline inspectable. Physical arm execution, shoe organization and sufficient human-video counts remain open research questions. This architecture makes the next product milestone measurable: an installed skill uses measured feedback to make better decisions within a declared operating envelope.
diff --git a/docs/downloads/reports/Skillspace footage training pipeline.md b/docs/downloads/reports/Skillspace footage training pipeline.md
index 540c835..f8433f2 100644
--- a/docs/downloads/reports/Skillspace footage training pipeline.md
+++ b/docs/downloads/reports/Skillspace footage training pipeline.md
@@ -1,5 +1,7 @@
# Skillspace footage training pipeline
+**Research pipeline evolution — 9 October 2026.** The [Robotics research pipeline](https://research.dvidia.org/papers/robotics-research-pipeline/) adds the proposed annotation-review and measured-state task-supervisor layers around this implemented training path. It includes an architecture diagram, data contracts and separate validation gates. Those additions are proposals; the recorded pilots and frozen sample-count results below retain their original scope.
+
The public, standalone [DVIDIA training repository](https://github.com/Dvidia-Inference/dvidia-training) provides a local CPU pipeline that turns actual Skillspace media into a fitted visual model and, when aligned numeric actions are supplied, a learned movement head. The useful advance is a reproducible path from source files through provenance checks, grouped splits, measured fitting and portable artifacts. **Video prediction and robot movement remain separate claims.** Ten synthetic six-second clips demonstrate visual fitting; simulator telemetry supplies the movement pilot's action labels. Its exported capsule installs and passes native qualification in one exact scene, while identical joint targets with open jaws fail. Neither experiment learns shoe organization or reconstructs robot actions from human footage. This report documents the implemented path and its limited measured evidence, rather than establishing a sufficient demonstration count or hardware competence. ([Standalone source archive](https://research.dvidia.org/downloads/topics/physical-grounding/runs/2026-10-08-footage-pipeline-v1/release/dvidia-training-v0.1.zip), [Qualification receipt](https://research.dvidia.org/downloads/topics/physical-grounding/runs/2026-10-08-footage-pipeline-v1/qualification/qualification.json))
## Published artifacts on Hugging Face
diff --git a/docs/downloads/topics/physical-grounding/README.md b/docs/downloads/topics/physical-grounding/README.md
index b350701..46ba01e 100644
--- a/docs/downloads/topics/physical-grounding/README.md
+++ b/docs/downloads/topics/physical-grounding/README.md
@@ -1,5 +1,9 @@
# Physical grounding
+## Robotics research pipeline — 9 October 2026
+
+[Robotics research pipeline](../../reports/Robotics%20research%20pipeline.md) connects footage review, synchronized measured state, separate visual and movement training, frozen simulation evaluation and versioned skill installation. Its diagram identifies current simulation components, proposed automatic labeling and learned task decisions, and the outstanding physical qualification gate. The proposed supervisor consumes recent joint, gripper and contact evidence; it does not equate a close command with a successful grasp. The new annotation-labor pilot is a companion to the existing graduation proposal. Both new experiments are **not run**. Existing recorded benchmarks retain their original protocols and claims.
+
[Skillspace footage training pipeline](../../reports/Skillspace%20footage%20training%20pipeline.md)
introduces the separate public [DVIDIA Training](https://github.com/Dvidia-Inference/dvidia-training)
repository: CPU footage intake, connected source groups, measured visual fitting,
diff --git a/docs/feed.xml b/docs/feed.xml
index c93da9c..d6d6a3f 100644
--- a/docs/feed.xml
+++ b/docs/feed.xml
@@ -1,2 +1,2 @@
-DVIDIA Researchhttps://research.dvidia.org/Research footprints on demonstrations, calibrated simulation and robot skills.enSkillspace footage training pipelinehttps://research.dvidia.org/papers/skillspace-footage-training/https://research.dvidia.org/papers/skillspace-footage-training/Thu, 08 Oct 2026 12:00:00 GMTPublic CPU package · one native scene qualified · simulation-only. The public Dvidia-Inference/dvidia-training repository provides a standalone CPU pipeline that audits Skillspace media, freezes grouped splits and exports inspectable artifacts. Ten synthetic six-second clips train a visual predictor with a 0.5106-second median pipeline time across three repeats on one macOS host. Aligned native simulator telemetry supplies 4,029 training labels for a learned joint-delta head, evaluated on one held-out recording. Its capsule passes native placement qualification in that recording's exact scene; identical joint targets with open jaws fail. Installation and hardware guides accompany the package. Human-video action recovery, shoe organization, demonstration sufficiency, independent scene generalization and physical robot competence remain unestablished.Skill capsule acquisition and optimizationhttps://research.dvidia.org/papers/skill-capsule-acquisition/https://research.dvidia.org/papers/skill-capsule-acquisition/Wed, 07 Oct 2026 12:00:00 GMTSimulation-only · teacher/student 7/8 · no overall speedup. A compact learned CPU movement head replaces joint-target computation inside an authored placement supervisor. Teacher and student both pass 7/8 in a new frozen evaluation, while episode wall time increases from 6.273 to 6.360 seconds. A 39,845-byte JSON capsule imports into the local lab, checks its exact runtime and qualifies the current scene through native placement and a recorded-arm/open-jaw control. Scene changes require a fresh test. One known scene and repeat pass native network denial; perception, complete task learning, other embodiments and hardware remain unqualified.Skillspace arm benchmarks and evolutionhttps://research.dvidia.org/papers/skillspace-arm-benchmarks/https://research.dvidia.org/papers/skillspace-arm-benchmarks/Wed, 07 Oct 2026 12:00:00 GMTMixed held-out result · 30/32 baseline, 29/32 updated. Two controller revisions improve development completion from 14/20 to 17/20, but the frozen paired test declines from 30/32 to 29/32: both pass all 24 normal-strength cases while actuator-stress completion falls from 6/8 to 5/8. Instrumented CPU throughput also declines. We publish the regression, unchanged contact and success rules, exact controller snapshots, richer physical inputs, runtime-bound installation and a proposed staged Skillspace contract. Contact forces and penetration remain uncalibrated; learned perception and physical qualification are open.Installing a Skillspace on a simulated armhttps://research.dvidia.org/papers/skillspace-arm-installation/https://research.dvidia.org/papers/skillspace-arm-installation/Wed, 07 Oct 2026 12:00:00 GMTPublic skill link to authored adapter · 6/6 scene placements. The first link-to-arm product path installs an existing DVIDIA placement envelope, binds a local authored controller to one simulated arm, and reuses it in independently grounded scenes. Native jaw contacts carry a free box; six layouts complete, while no-motion and identical joint commands with open jaws each complete zero of six. Installed execution passes process-level offline checks. Task metadata contains no learned policy; perception, cup geometry, full arm collisions and physical qualification remain open.Offline cable training environmenthttps://research.dvidia.org/papers/offline-cable-training-environment/https://research.dvidia.org/papers/offline-cable-training-environment/Wed, 07 Oct 2026 12:00:00 GMTCPU simulation-only · Controller search and frozen evaluation executed. The first runnable product loop combines an anchored cable environment, local controller-parameter search, frozen evaluation, offline replay and a manifest-backed skill pack. The selected controller and a fixed feedback baseline both completed 10/10 held-out simulated episodes; zero-force and release controls completed 0/10. A native macOS network-denial run completed 3/3 additional episodes. Ideal endpoint attachment and privileged state bound the result; physical rope calibration, gripping, sensors and GPU throughput remain untested.Fast accurate robot training simulationhttps://research.dvidia.org/papers/fast-accurate-robot-training-simulation/https://research.dvidia.org/papers/fast-accurate-robot-training-simulation/Wed, 07 Oct 2026 12:00:00 GMT54 CPU fixture trials · GPU and physical transfer untested. A design for an offline, self-hosted training environment that turns demonstrations into calibrated practice and qualified robot skills. We examine contact, deformation, sensor feedback and the performance–accuracy tradeoff, then report 54 deterministic native MuJoCo CPU fixture trials. Fine endpoint agreement did not establish accurate contact transients, and coarse timesteps missed collisions. Minimum GPU memory, rope accuracy and physical transfer remain unmeasured.Grok robotics research on Xhttps://research.dvidia.org/papers/grok-robotics-research-on-x/https://research.dvidia.org/papers/grok-robotics-research-on-x/Wed, 07 Oct 2026 12:00:00 GMTPrimary sources checked · Experiments proposed. Three Grok 4.7 research passes surface observation-to-action, synthetic-practice and reusable-repair ideas. Independent primary-source checks compare those findings with our thesis: observation supplies goals and state, language retrieves a skill, spatial expectations guide attention, and executable feedback with evaluation establishes competence. X posts remain discovery leads. No universal demonstration count or arbitrary-robot transfer follows from the reviewed results.Spatially grounded downloadable robot skillshttps://research.dvidia.org/papers/spatially-grounded-downloadable-robot-skills/https://research.dvidia.org/papers/spatially-grounded-downloadable-robot-skills/Wed, 07 Oct 2026 12:00:00 GMTSource review · DVIDIA experiments not run. A synthesis of learning from human demonstrations, language-conditioned spatial attention, simulation expansion and robot-specific skill delivery. Spatial priors can accelerate inspection but do not determine contact state or control. The proposed downloadable skill packages a controller, initiation and termination conditions, compatible sensing and hardware, recovery behavior and measured evidence. Separate experiments would test attention, data coverage, feedback and transfer.Clef and grounded video observationshttps://research.dvidia.org/papers/clef-and-grounded-video-observations/https://research.dvidia.org/papers/clef-and-grounded-video-observations/Tue, 06 Oct 2026 12:00:00 GMTFive licensed excerpts · Accuracy evaluation outstanding. A preregistered image-API feasibility run processed five licensed three-second POV excerpts using four timestamped frames, a Gemma caption and a Clef-flash check. All five completed at a price-derived inference estimate of $0.00140634. Post-run inspection found an object error accepted by the checker and omitted state changes. API and schema compatibility were demonstrated; annotation accuracy and whole-task success were not.From Skillspace to robot skillhttps://research.dvidia.org/papers/from-skillspace-to-robot-skill/https://research.dvidia.org/papers/from-skillspace-to-robot-skill/Tue, 06 Oct 2026 12:00:00 GMTGraduation and robot training not run. An Argus review and a proposal to connect original recordings, reviewed episodes, immutable datasets, training runs, held-out evaluation and robot-tested releases. The review separates video annotation from action supervision and defines compatibility beyond a robot’s degree-of-freedom count. A proposed 40-episode annotation pilot and evidence-based graduation criteria remain unrun.Turn physical footage into testable evidencehttps://research.dvidia.org/papers/physical-skill-research-agenda/https://research.dvidia.org/papers/physical-skill-research-agenda/Tue, 06 Oct 2026 12:00:00 GMTFour baseline protocols proposed. A research agenda covering visible capture evidence, relations over time, evaluation provenance and physical grounding. Each question has a bounded protocol and a failure condition. The aim is to measure whether structure and physical signals improve a defined task before scaling collection. Strategic opinions, author-reported results and our untested proposals are kept distinct.
+DVIDIA Researchhttps://research.dvidia.org/Research footprints on demonstrations, calibrated simulation and robot skills.enRobotics research pipelinehttps://research.dvidia.org/papers/robotics-research-pipeline/https://research.dvidia.org/papers/robotics-research-pipeline/Fri, 09 Oct 2026 12:00:00 GMTArchitecture proposal · current simulation alpha · hardware unqualified. An updated architecture connects immutable Skillspace recordings, reviewed task-label proposals and synchronized measured telemetry to grouped datasets, separate visual and motor learners, and a proposed local state supervisor. The implemented CPU baseline retains authored phases, gripper decisions and recovery around its learned joint-delta head. New annotation and supervisor pilots, fresh frozen confirmation, physics calibration and compatible skill-installation gates define the next milestones. Automatic labeling, learned supervision, human-video action recovery and physical arm qualification remain unestablished; this publication adds no new training or hardware result.Skillspace footage training pipelinehttps://research.dvidia.org/papers/skillspace-footage-training/https://research.dvidia.org/papers/skillspace-footage-training/Thu, 08 Oct 2026 12:00:00 GMTPublic CPU package · one native scene qualified · simulation-only. The public Dvidia-Inference/dvidia-training repository provides a standalone CPU pipeline that audits Skillspace media, freezes grouped splits and exports inspectable artifacts. Ten synthetic six-second clips train a visual predictor with a 0.5106-second median pipeline time across three repeats on one macOS host. Aligned native simulator telemetry supplies 4,029 training labels for a learned joint-delta head, evaluated on one held-out recording. Its capsule passes native placement qualification in that recording's exact scene; identical joint targets with open jaws fail. Installation and hardware guides accompany the package. Human-video action recovery, shoe organization, demonstration sufficiency, independent scene generalization and physical robot competence remain unestablished.Skill capsule acquisition and optimizationhttps://research.dvidia.org/papers/skill-capsule-acquisition/https://research.dvidia.org/papers/skill-capsule-acquisition/Wed, 07 Oct 2026 12:00:00 GMTSimulation-only · teacher/student 7/8 · no overall speedup. A compact learned CPU movement head replaces joint-target computation inside an authored placement supervisor. Teacher and student both pass 7/8 in a new frozen evaluation, while episode wall time increases from 6.273 to 6.360 seconds. A 39,845-byte JSON capsule imports into the local lab, checks its exact runtime and qualifies the current scene through native placement and a recorded-arm/open-jaw control. Scene changes require a fresh test. One known scene and repeat pass native network denial; perception, complete task learning, other embodiments and hardware remain unqualified.Skillspace arm benchmarks and evolutionhttps://research.dvidia.org/papers/skillspace-arm-benchmarks/https://research.dvidia.org/papers/skillspace-arm-benchmarks/Wed, 07 Oct 2026 12:00:00 GMTMixed held-out result · 30/32 baseline, 29/32 updated. Two controller revisions improve development completion from 14/20 to 17/20, but the frozen paired test declines from 30/32 to 29/32: both pass all 24 normal-strength cases while actuator-stress completion falls from 6/8 to 5/8. Instrumented CPU throughput also declines. We publish the regression, unchanged contact and success rules, exact controller snapshots, richer physical inputs, runtime-bound installation and a proposed staged Skillspace contract. Contact forces and penetration remain uncalibrated; learned perception and physical qualification are open.Installing a Skillspace on a simulated armhttps://research.dvidia.org/papers/skillspace-arm-installation/https://research.dvidia.org/papers/skillspace-arm-installation/Wed, 07 Oct 2026 12:00:00 GMTPublic skill link to authored adapter · 6/6 scene placements. The first link-to-arm product path installs an existing DVIDIA placement envelope, binds a local authored controller to one simulated arm, and reuses it in independently grounded scenes. Native jaw contacts carry a free box; six layouts complete, while no-motion and identical joint commands with open jaws each complete zero of six. Installed execution passes process-level offline checks. Task metadata contains no learned policy; perception, cup geometry, full arm collisions and physical qualification remain open.Offline cable training environmenthttps://research.dvidia.org/papers/offline-cable-training-environment/https://research.dvidia.org/papers/offline-cable-training-environment/Wed, 07 Oct 2026 12:00:00 GMTCPU simulation-only · Controller search and frozen evaluation executed. The first runnable product loop combines an anchored cable environment, local controller-parameter search, frozen evaluation, offline replay and a manifest-backed skill pack. The selected controller and a fixed feedback baseline both completed 10/10 held-out simulated episodes; zero-force and release controls completed 0/10. A native macOS network-denial run completed 3/3 additional episodes. Ideal endpoint attachment and privileged state bound the result; physical rope calibration, gripping, sensors and GPU throughput remain untested.Fast accurate robot training simulationhttps://research.dvidia.org/papers/fast-accurate-robot-training-simulation/https://research.dvidia.org/papers/fast-accurate-robot-training-simulation/Wed, 07 Oct 2026 12:00:00 GMT54 CPU fixture trials · GPU and physical transfer untested. A design for an offline, self-hosted training environment that turns demonstrations into calibrated practice and qualified robot skills. We examine contact, deformation, sensor feedback and the performance–accuracy tradeoff, then report 54 deterministic native MuJoCo CPU fixture trials. Fine endpoint agreement did not establish accurate contact transients, and coarse timesteps missed collisions. Minimum GPU memory, rope accuracy and physical transfer remain unmeasured.Grok robotics research on Xhttps://research.dvidia.org/papers/grok-robotics-research-on-x/https://research.dvidia.org/papers/grok-robotics-research-on-x/Wed, 07 Oct 2026 12:00:00 GMTPrimary sources checked · Experiments proposed. Three Grok 4.7 research passes surface observation-to-action, synthetic-practice and reusable-repair ideas. Independent primary-source checks compare those findings with our thesis: observation supplies goals and state, language retrieves a skill, spatial expectations guide attention, and executable feedback with evaluation establishes competence. X posts remain discovery leads. No universal demonstration count or arbitrary-robot transfer follows from the reviewed results.Spatially grounded downloadable robot skillshttps://research.dvidia.org/papers/spatially-grounded-downloadable-robot-skills/https://research.dvidia.org/papers/spatially-grounded-downloadable-robot-skills/Wed, 07 Oct 2026 12:00:00 GMTSource review · DVIDIA experiments not run. A synthesis of learning from human demonstrations, language-conditioned spatial attention, simulation expansion and robot-specific skill delivery. Spatial priors can accelerate inspection but do not determine contact state or control. The proposed downloadable skill packages a controller, initiation and termination conditions, compatible sensing and hardware, recovery behavior and measured evidence. Separate experiments would test attention, data coverage, feedback and transfer.Clef and grounded video observationshttps://research.dvidia.org/papers/clef-and-grounded-video-observations/https://research.dvidia.org/papers/clef-and-grounded-video-observations/Tue, 06 Oct 2026 12:00:00 GMTFive licensed excerpts · Accuracy evaluation outstanding. A preregistered image-API feasibility run processed five licensed three-second POV excerpts using four timestamped frames, a Gemma caption and a Clef-flash check. All five completed at a price-derived inference estimate of $0.00140634. Post-run inspection found an object error accepted by the checker and omitted state changes. API and schema compatibility were demonstrated; annotation accuracy and whole-task success were not.From Skillspace to robot skillhttps://research.dvidia.org/papers/from-skillspace-to-robot-skill/https://research.dvidia.org/papers/from-skillspace-to-robot-skill/Tue, 06 Oct 2026 12:00:00 GMTGraduation and robot training not run. An Argus review and a proposal to connect original recordings, reviewed episodes, immutable datasets, training runs, held-out evaluation and robot-tested releases. The review separates video annotation from action supervision and defines compatibility beyond a robot’s degree-of-freedom count. A proposed 40-episode annotation pilot and evidence-based graduation criteria remain unrun.Turn physical footage into testable evidencehttps://research.dvidia.org/papers/physical-skill-research-agenda/https://research.dvidia.org/papers/physical-skill-research-agenda/Tue, 06 Oct 2026 12:00:00 GMTFour baseline protocols proposed. A research agenda covering visible capture evidence, relations over time, evaluation provenance and physical grounding. Each question has a bounded protocol and a failure condition. The aim is to measure whether structure and physical signals improve a defined task before scaling collection. Strategic opinions, author-reported results and our untested proposals are kept distinct.
diff --git a/docs/index.html b/docs/index.html
index 93489cc..7fb128f 100644
--- a/docs/index.html
+++ b/docs/index.html
@@ -1,4 +1,4 @@
Research journal · DVIDIA Research
-Skip to content
An open research notebook
From observation to physical skill.
We study how demonstrations become usable evidence, how simulation becomes useful practice, and when a robot skill earns a release.
The public Dvidia-Inference/dvidia-training repository provides a standalone CPU pipeline that audits Skillspace media, freezes grouped splits and exports inspectable artifacts. Ten synthetic six-second clips train a visual predictor with a 0.5106-second median pipeline time across three repeats on one macOS host. Aligned native simulator telemetry supplies 4,029 training labels for a learned joint-delta head, evaluated on one held-out recording. Its capsule passes native placement qualification in that recording's exact scene; identical joint targets with open jaws fail. Installation and hardware guides accompany the package. Human-video action recovery, shoe organization, demonstration sufficiency, independent scene generalization and physical robot competence remain unestablished.
Public CPU package · one native scene qualified · simulation-only
· Learned movement artifact and installation prototype
A compact learned CPU movement head replaces joint-target computation inside an authored placement supervisor. Teacher and student both pass 7/8 in a new frozen evaluation, while episode wall time increases from 6.273 to 6.360 seconds. A 39,845-byte JSON capsule imports into the local lab, checks its exact runtime and qualifies the current scene through native placement and a recorded-arm/open-jaw control. Scene changes require a fresh test. One known scene and repeat pass native network denial; perception, complete task learning, other embodiments and hardware remain unqualified.
Simulation-only · teacher/student 7/8 · no overall speedup
· Paired simulation benchmark and product assessment
Two controller revisions improve development completion from 14/20 to 17/20, but the frozen paired test declines from 30/32 to 29/32: both pass all 24 normal-strength cases while actuator-stress completion falls from 6/8 to 5/8. Instrumented CPU throughput also declines. We publish the regression, unchanged contact and success rules, exact controller snapshots, richer physical inputs, runtime-bound installation and a proposed staged Skillspace contract. Contact forces and penetration remain uncalibrated; learned perception and physical qualification are open.
Mixed held-out result · 30/32 baseline, 29/32 updated
· Product prototype and native contact qualification
The first link-to-arm product path installs an existing DVIDIA placement envelope, binds a local authored controller to one simulated arm, and reuses it in independently grounded scenes. Native jaw contacts carry a free box; six layouts complete, while no-motion and identical joint commands with open jaws each complete zero of six. Installed execution passes process-level offline checks. Task metadata contains no learned policy; perception, cup geometry, full arm collisions and physical qualification remain open.
Public skill link to authored adapter · 6/6 scene placements
The first runnable product loop combines an anchored cable environment, local controller-parameter search, frozen evaluation, offline replay and a manifest-backed skill pack. The selected controller and a fixed feedback baseline both completed 10/10 held-out simulated episodes; zero-force and release controls completed 0/10. A native macOS network-denial run completed 3/3 additional episodes. Ideal endpoint attachment and privileged state bound the result; physical rope calibration, gripping, sensors and GPU throughput remain untested.
CPU simulation-only · Controller search and frozen evaluation executed
A design for an offline, self-hosted training environment that turns demonstrations into calibrated practice and qualified robot skills. We examine contact, deformation, sensor feedback and the performance–accuracy tradeoff, then report 54 deterministic native MuJoCo CPU fixture trials. Fine endpoint agreement did not establish accurate contact transients, and coarse timesteps missed collisions. Minimum GPU memory, rope accuracy and physical transfer remain unmeasured.
54 CPU fixture trials · GPU and physical transfer untested
Three Grok 4.7 research passes surface observation-to-action, synthetic-practice and reusable-repair ideas. Independent primary-source checks compare those findings with our thesis: observation supplies goals and state, language retrieves a skill, spatial expectations guide attention, and executable feedback with evaluation establishes competence. X posts remain discovery leads. No universal demonstration count or arbitrary-robot transfer follows from the reviewed results.
A synthesis of learning from human demonstrations, language-conditioned spatial attention, simulation expansion and robot-specific skill delivery. Spatial priors can accelerate inspection but do not determine contact state or control. The proposed downloadable skill packages a controller, initiation and termination conditions, compatible sensing and hardware, recovery behavior and measured evidence. Separate experiments would test attention, data coverage, feedback and transfer.
A preregistered image-API feasibility run processed five licensed three-second POV excerpts using four timestamped frames, a Gemma caption and a Clef-flash check. All five completed at a price-derived inference estimate of $0.00140634. Post-run inspection found an object error accepted by the checker and omitted state changes. API and schema compatibility were demonstrated; annotation accuracy and whole-task success were not.
Five licensed excerpts · Accuracy evaluation outstanding
An Argus review and a proposal to connect original recordings, reviewed episodes, immutable datasets, training runs, held-out evaluation and robot-tested releases. The review separates video annotation from action supervision and defines compatibility beyond a robot’s degree-of-freedom count. A proposed 40-episode annotation pilot and evidence-based graduation criteria remain unrun.
A research agenda covering visible capture evidence, relations over time, evaluation provenance and physical grounding. Each question has a bounded protocol and a failure condition. The aim is to measure whether structure and physical signals improve a defined task before scaling collection. Strategic opinions, author-reported results and our untested proposals are kept distinct.
Four baseline protocols proposed
No publications match this search.
Research footprints
A public skill link reaches a simulated arm
One-click local installation binds a DVIDIA placement envelope to an authored contact controller. Six scene layouts pass; identical joint commands with open jaws and no-motion controls each pass 0/6. Physical transfer and learned policies remain open.
A local controller-training loop and simulation-only skill pack now run on CPU. Trained and baseline feedback each pass 10/10 simulated seeds; zero force and early release each pass 0/10. Real gripping, calibration and GPU qualification remain open.
54 deterministic CPU fixture trials recorded. Endpoint agreement coexists with unqualified force transients; coarse wall tests expose missed contact. No GPU or physical-transfer claim.
Compare the observation-to-skill thesis with prior work
Spatial attention, demonstration coverage, executable simulation and reusable repairs are reviewed separately. Three parallel Grok 4.7 searches support discovery; primary sources support the claims.
Four baseline protocols and a Skillspace graduation proposal establish the questions to test. A proposed protocol is distinct from an executed experiment.
An updated architecture connects immutable Skillspace recordings, reviewed task-label proposals and synchronized measured telemetry to grouped datasets, separate visual and motor learners, and a proposed local state supervisor. The implemented CPU baseline retains authored phases, gripper decisions and recovery around its learned joint-delta head. New annotation and supervisor pilots, fresh frozen confirmation, physics calibration and compatible skill-installation gates define the next milestones. Automatic labeling, learned supervision, human-video action recovery and physical arm qualification remain unestablished; this publication adds no new training or hardware result.
Architecture proposal · current simulation alpha · hardware unqualified
· Product implementation and measured synthetic pilot
The public Dvidia-Inference/dvidia-training repository provides a standalone CPU pipeline that audits Skillspace media, freezes grouped splits and exports inspectable artifacts. Ten synthetic six-second clips train a visual predictor with a 0.5106-second median pipeline time across three repeats on one macOS host. Aligned native simulator telemetry supplies 4,029 training labels for a learned joint-delta head, evaluated on one held-out recording. Its capsule passes native placement qualification in that recording's exact scene; identical joint targets with open jaws fail. Installation and hardware guides accompany the package. Human-video action recovery, shoe organization, demonstration sufficiency, independent scene generalization and physical robot competence remain unestablished.
Public CPU package · one native scene qualified · simulation-only
· Learned movement artifact and installation prototype
A compact learned CPU movement head replaces joint-target computation inside an authored placement supervisor. Teacher and student both pass 7/8 in a new frozen evaluation, while episode wall time increases from 6.273 to 6.360 seconds. A 39,845-byte JSON capsule imports into the local lab, checks its exact runtime and qualifies the current scene through native placement and a recorded-arm/open-jaw control. Scene changes require a fresh test. One known scene and repeat pass native network denial; perception, complete task learning, other embodiments and hardware remain unqualified.
Simulation-only · teacher/student 7/8 · no overall speedup
· Paired simulation benchmark and product assessment
Two controller revisions improve development completion from 14/20 to 17/20, but the frozen paired test declines from 30/32 to 29/32: both pass all 24 normal-strength cases while actuator-stress completion falls from 6/8 to 5/8. Instrumented CPU throughput also declines. We publish the regression, unchanged contact and success rules, exact controller snapshots, richer physical inputs, runtime-bound installation and a proposed staged Skillspace contract. Contact forces and penetration remain uncalibrated; learned perception and physical qualification are open.
Mixed held-out result · 30/32 baseline, 29/32 updated
· Product prototype and native contact qualification
The first link-to-arm product path installs an existing DVIDIA placement envelope, binds a local authored controller to one simulated arm, and reuses it in independently grounded scenes. Native jaw contacts carry a free box; six layouts complete, while no-motion and identical joint commands with open jaws each complete zero of six. Installed execution passes process-level offline checks. Task metadata contains no learned policy; perception, cup geometry, full arm collisions and physical qualification remain open.
Public skill link to authored adapter · 6/6 scene placements
The first runnable product loop combines an anchored cable environment, local controller-parameter search, frozen evaluation, offline replay and a manifest-backed skill pack. The selected controller and a fixed feedback baseline both completed 10/10 held-out simulated episodes; zero-force and release controls completed 0/10. A native macOS network-denial run completed 3/3 additional episodes. Ideal endpoint attachment and privileged state bound the result; physical rope calibration, gripping, sensors and GPU throughput remain untested.
CPU simulation-only · Controller search and frozen evaluation executed
A design for an offline, self-hosted training environment that turns demonstrations into calibrated practice and qualified robot skills. We examine contact, deformation, sensor feedback and the performance–accuracy tradeoff, then report 54 deterministic native MuJoCo CPU fixture trials. Fine endpoint agreement did not establish accurate contact transients, and coarse timesteps missed collisions. Minimum GPU memory, rope accuracy and physical transfer remain unmeasured.
54 CPU fixture trials · GPU and physical transfer untested
Three Grok 4.7 research passes surface observation-to-action, synthetic-practice and reusable-repair ideas. Independent primary-source checks compare those findings with our thesis: observation supplies goals and state, language retrieves a skill, spatial expectations guide attention, and executable feedback with evaluation establishes competence. X posts remain discovery leads. No universal demonstration count or arbitrary-robot transfer follows from the reviewed results.
A synthesis of learning from human demonstrations, language-conditioned spatial attention, simulation expansion and robot-specific skill delivery. Spatial priors can accelerate inspection but do not determine contact state or control. The proposed downloadable skill packages a controller, initiation and termination conditions, compatible sensing and hardware, recovery behavior and measured evidence. Separate experiments would test attention, data coverage, feedback and transfer.
A preregistered image-API feasibility run processed five licensed three-second POV excerpts using four timestamped frames, a Gemma caption and a Clef-flash check. All five completed at a price-derived inference estimate of $0.00140634. Post-run inspection found an object error accepted by the checker and omitted state changes. API and schema compatibility were demonstrated; annotation accuracy and whole-task success were not.
Five licensed excerpts · Accuracy evaluation outstanding
An Argus review and a proposal to connect original recordings, reviewed episodes, immutable datasets, training runs, held-out evaluation and robot-tested releases. The review separates video annotation from action supervision and defines compatibility beyond a robot’s degree-of-freedom count. A proposed 40-episode annotation pilot and evidence-based graduation criteria remain unrun.
A research agenda covering visible capture evidence, relations over time, evaluation provenance and physical grounding. Each question has a bounded protocol and a failure condition. The aim is to measure whether structure and physical signals improve a defined task before scaling collection. Strategic opinions, author-reported results and our untested proposals are kept distinct.
Four baseline protocols proposed
No publications match this search.
Research footprints
Publish the robotics research pipeline
A diagram connects footage review, measured robot state, local training, frozen simulation evaluation and compatible skill installation. Automatic annotation and a learned task supervisor are proposed; their companion validation studies and physical robot qualification remain unrun.
One-click local installation binds a DVIDIA placement envelope to an authored contact controller. Six scene layouts pass; identical joint commands with open jaws and no-motion controls each pass 0/6. Physical transfer and learned policies remain open.
A local controller-training loop and simulation-only skill pack now run on CPU. Trained and baseline feedback each pass 10/10 simulated seeds; zero force and early release each pass 0/10. Real gripping, calibration and GPU qualification remain open.
54 deterministic CPU fixture trials recorded. Endpoint agreement coexists with unqualified force transients; coarse wall tests expose missed contact. No GPU or physical-transfer claim.
Compare the observation-to-skill thesis with prior work
Spatial attention, demonstration coverage, executable simulation and reusable repairs are reviewed separately. Three parallel Grok 4.7 searches support discovery; primary sources support the claims.
Four baseline protocols and a Skillspace graduation proposal establish the questions to test. A proposed protocol is distinct from an executed experiment.